



Label-free analysis in proteomics usually means label-free quantification (LFQ): relative protein abundance is inferred from mass spectrometry signals on unlabeled digests without isobaric or metabolic tags on the discovery path (Cox et al. 2014). Each sample is typically acquired on its own liquid chromatography-tandem mass spectrometry (LC-MS/MS) injection. Software aligns features across runs, normalizes systematic scale differences, and rolls peptide evidence into protein-level values for a predefined contrast. The guide below defines LFQ in project language, separates chemistry from acquisition and metrics, and links principles to workflow, parameters, limits, and fit. It is not a metabolomics methods page, not a software manual for every platform, and not a disease application catalog.
LFQ intensities support relative change of the same protein across samples in one study. They do not report molar concentration, copy number across proteins, or clinical cutoffs without separate targeted or calibration design (Gerber et al. 2003).
In MtoZ Biolabs offerings, unlabeled discovery is commonly run as DDA LFQ from MS1 peak areas or as unlabeled DIA or SWATH-style extraction when windowed acquisition fits the cohort.
What Label-Free Means Versus Labeling-Based Quantification
Three chemistry labels belong in the project brief.
Label-free discovery keeps digests unlabeled through injection. Quantification compares extracted intensities across separate runs after alignment and normalization.
Metabolic labeling such as stable isotope labeling by amino acids in cell culture (SILAC) encodes culture state before harvest. It fits cultivable systems with defined media, not every tissue or biofluid cohort.
Isobaric tagging such as tandem mass tag (TMT) or isobaric tags for relative and absolute quantitation (iTRAQ) combines labeled digests for reporter readout inside a multiplex. It fits closed sets that can be tagged the same day, not every open enrollment design.
Label-free names the absence of discovery tagging on separate injections, not a single acquisition mode or one software brand.
Route selection across chemistry and acquisition appears in Protein Quantification Method.
Acquisition and Metrics Separate From Label-Free Chemistry
Unlabeled prep can pair with more than one acquisition and metric.
Data-dependent acquisition (DDA) selects precursors in real time for fragmentation. Intensity-based LFQ usually integrates MS1 precursor chromatograms after identification. Stochastic sampling drives missing values at low abundance.
Data-independent acquisition (DIA) fragments precursors in declared m/z windows. Label-free DIA quantifies from extracted fragment traces under false discovery rate (FDR) control (Gillet et al. 2012). SWATH-MS names one common window plan inside DIA.
Spectral counting ranks proteins by assigned MS/MS spectrum counts. It can support rough screening but is weaker for precise fold-change statistics than MS1 peak-area LFQ on the same DDA files.
Targeted parallel reaction monitoring (PRM) or multiple reaction monitoring (MRM) on a closed peptide list is a separate assay scope, not a synonym for LFQ discovery.
DIA depth for unlabeled cohorts compares with Label-Free DIA Quantitative Proteomics. Pretreatment before windowed runs compares with SWATH-MS Label-Free Protein Quantification Technology Analysis.
How LFQ Turns MS Signal Into Relative Protein Values
The working assumption is narrow. Under comparable LC-MS conditions, recorded signal for a given peptide tracks relative amount of that peptide in that run, subject to loading, ionization, and interference.
Identification assigns peptide sequences from fragment evidence searched against a declared database. Quantification extracts precursor or fragment chromatograms and integrates intensity for aligned features.
Normalization corrects global loading and instrument response drift. MaxLFQ-style approaches use peptide ratio relationships after delayed normalization (Cox et al. 2014). Normalization does not fix confounded run order or mixed processing pipelines.
Protein rollup applies a declared rule to combine peptides. Shared peptides, filtering, and missing observations change reported protein values.
Missing values are common in unlabeled DDA and still appear in DIA matrices. Policy for dropout and imputation must be declared before contrast testing (Lazar et al. 2016).
Normalization choices compare with How to Normalize Data in Label-Free Quantitative Proteomics?. Within-sample abundance proxies such as iBAQ answer a different question than cross-run LFQ (What Is the Difference between LFQ and iBAQ?).
Label-Free Principle Linked Workflow Spine
A practical label-free discovery spine usually runs as follows.
- Confirm matrix, contrast, relative claim, and acquisition route.
- Prepare matched digests with shared lysis, digestion, and cleanup.
- Desalt to injection-ready loads without discovery tags.
- Acquire separate LC-MS/MS runs with interleaved order when cohort size allows.
- Identify peptides; extract MS1 areas or DIA fragment groups under FDR control.
- Align features across runs; normalize; document missing-value handling.
- Roll up proteins; test predefined contrast only.
- Optional PRM, stable isotope-labeled internal standard (SIS), or independent cohort for confirmation.
Steps 1 through 3 are chemistry and prep. Steps 4 through 5 are acquisition and feature extraction. Steps 6 through 7 are the quantitative claim layer.
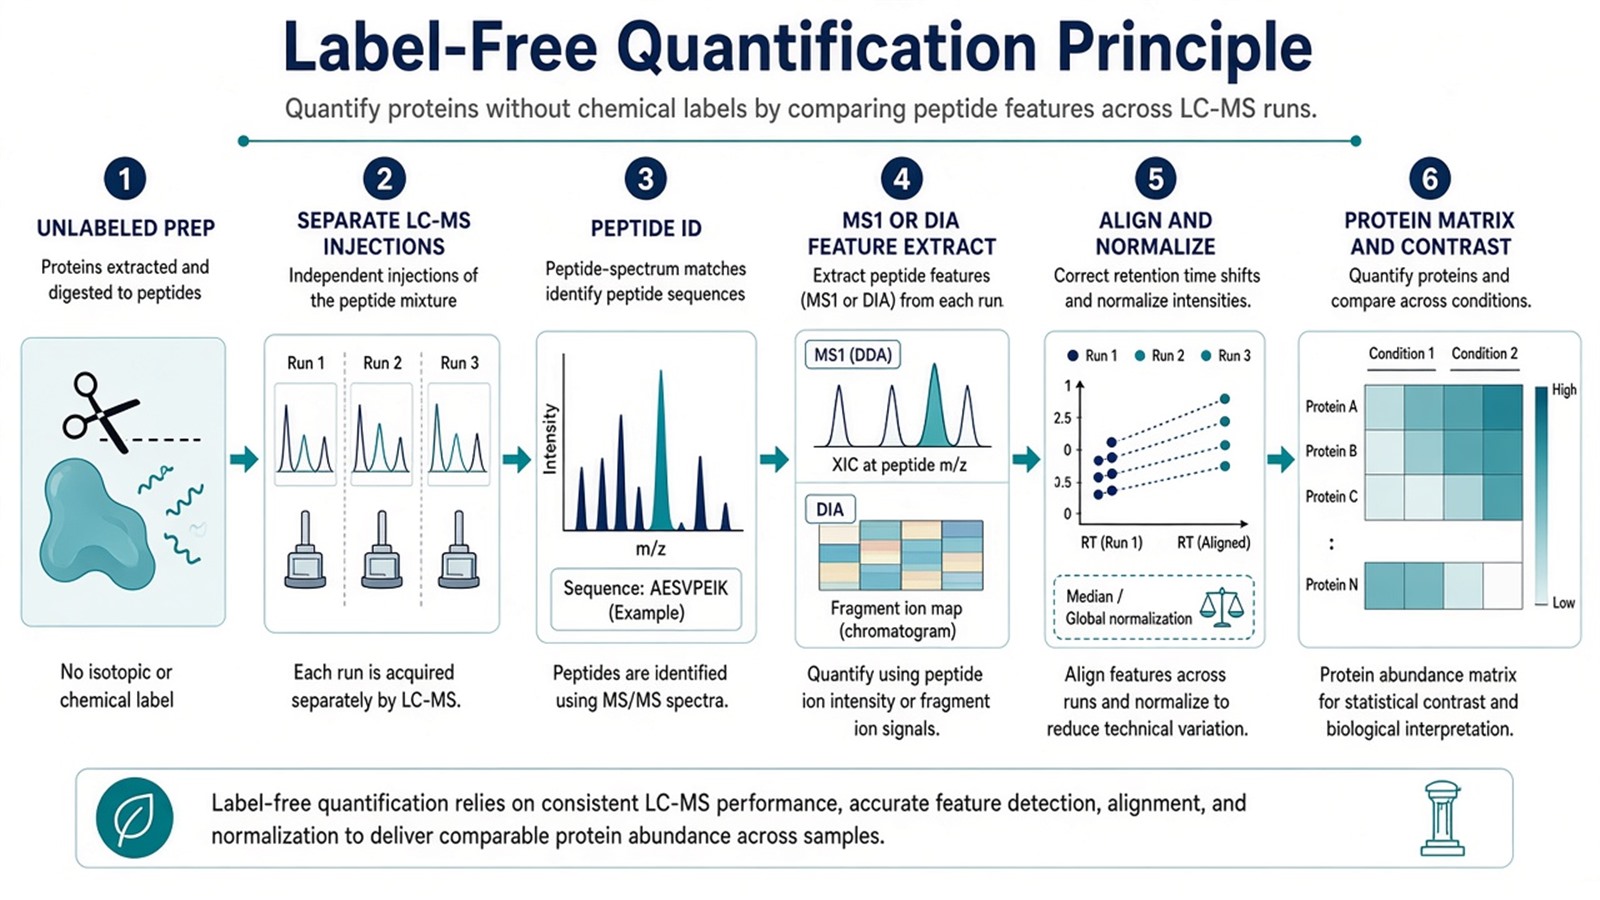
Figure 1. Label-free quantification compares the same protein across independently acquired runs after alignment and normalization, not across proteins as molar ranks.
General prep spine appears in Quantitative Protein Analysis. End-to-end framing appears in A Guide to Label-Free Quantitative Proteomics: From Experiment to Data Analysis.
Parameters and Limits in Label-Free Quantification
Layer |
Parameter that must be declared |
Limit if mis-set |
|---|---|---|
Chemistry |
Unlabeled separate injections |
Tagged and untagged files merged |
Prep |
Matched across contrast arms |
Load bias mimics biology |
Acquisition |
DDA versus DIA locked |
Mixed modes in one matrix |
Metric |
MS1 area versus DIA extraction |
Spectral counts treated as precise LFQ |
Alignment |
One pipeline version |
Incomparable feature maps |
Normalization |
Method and scope |
Global drift as biology |
Missing values |
Documented policy |
Imputed gaps without rules |
Contrast |
Frozen before threshold tuning |
Post hoc relabeling |
Claim |
Relative discovery default |
Open LFQ as absolute amount |
Limits follow the same table. Label-free analysis does not remove batch effects by itself. Instrument drift, column aging, and harvest batch confounding need design and QC, not only software defaults. Throughput flexibility does not replace replicate design or frozen contrasts.
Enrollment and pilot checks appear in Exploring Quantitative Analysis in Proteomics.
How to Choose Label-Free Analysis for the Next Project
Use enrollment, contrast type, and follow-up unit together.
Project need |
Label-free plan that often fits |
Recheck before committing |
|---|---|---|
Open cohort, staggered samples |
Unlabeled DDA LFQ or unlabeled DIA |
Same-day TMT assumption |
Many files, windowed acquisition fit |
Label-free DIA or SWATH-style |
DDA when DIA pilots show gain |
Closed multi-arm set, one labeling day |
TMT or iTRAQ multiplex |
Forced LFQ when mixing is required |
Cultured cells with SILAC media |
SILAC relative comparison |
SILAC on tissue without plan |
Closed peptide monitoring list |
PRM or MRM |
Full LFQ when names fixed |
Amount on named peptides |
SIS targeted assay |
Discovery LFQ as concentration |
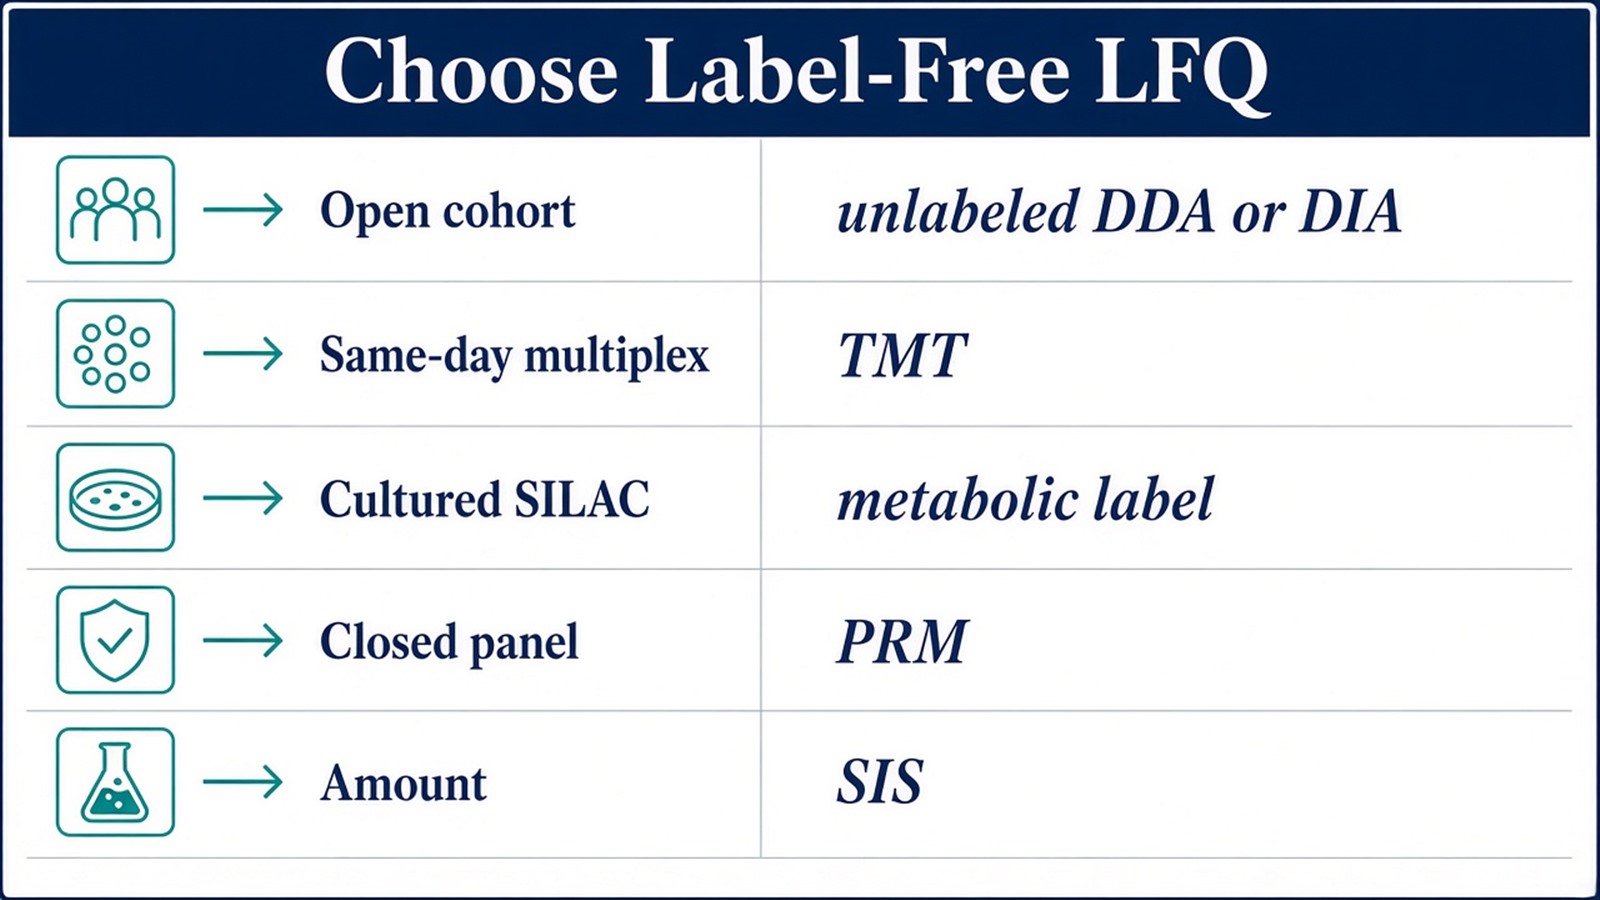
Figure 2. Choose label-free LFQ when unlabeled separate injections and a relative contrast fit; tagging, targeted assays, or SIS fit other claim units.
Teams with matrix, contrast design, and acquisition intent can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for label-free planning alignment.
Frequently Asked Questions
1. Is label-free analysis the same as label-free metabolomics?
No. This guide focuses on proteomics LFQ. Metabolomics uses different feature classes and calibration logic.
2. Can LFQ report absolute protein concentration?
Not from open discovery intensities alone. SIS peptides or external calibration on named targets support amount claims in targeted designs.
3. Does label-free mean DIA?
No. Label-free names chemistry. DIA names acquisition. Unlabeled digests can run as DDA or DIA.
4. How should extensive missing data be handled?
Declare detection limits, imputation rules, and how missingness relates to abundance before testing the contrast. Imputation changes statistics and must stay transparent.
5. How is batch variation controlled in LFQ?
Match prep, interleave groups across run order, use normalization with documented scope, and avoid relabeling arms after acquisition.
MtoZ Biolabs can discuss label-free quantification principles in project planning when contrast design, matrix pilots, and acquisition route are documented.
If further evaluation of DDA versus DIA fit, normalization choice, or discovery-to-targeted staging is needed, project details can be submitted for a feasibility review.
Reference
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, H. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
