



Data-independent acquisition (DIA) is a mass spectrometry strategy that fragments precursors in scheduled m/z windows and recovers peptide quantities from extracted fragment-ion chromatograms, rather than relying only on intensity-triggered precursor picks used in data-dependent acquisition (DDA). SWATH-MS (sequential window acquisition of all theoretical fragment ion spectra) is one influential DIA implementation: it cycles through consecutive precursor windows and typically quantifies peptides by targeted extraction against a spectral library (Gillet et al. 2012). DIA is the acquisition class; SWATH is a sequential-window member of that class. Both answer relative discovery across independently injected samples. They are not a labeling chemistry and do not report absolute protein concentration by default.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Deep DIA Proteomics Service for project-specific feasibility and analysis planning.
What DIA Means in Practice
In DDA, the instrument selects intense precursors in real time for fragmentation. That stochastic sampling often leaves missing values in unlabeled discovery matrices. In DIA, the precursor range is divided into isolation windows that are fragmented on a fixed schedule. Fragment evidence is recorded across the window set in every cycle, so later analysis can extract peptide transitions even when a precursor was never chosen as a top peak.
The quantitative object in many DIA workflows is a fragment-ion chromatogram. Window width, cycle time, and chromatography set the interference-versus-coverage trade-off. Narrower windows can reduce chimeric spectra but need higher MS/MS speed. Wider windows increase multiplexing and can raise fragment overlap. Those settings belong in the methods record with the protein table.
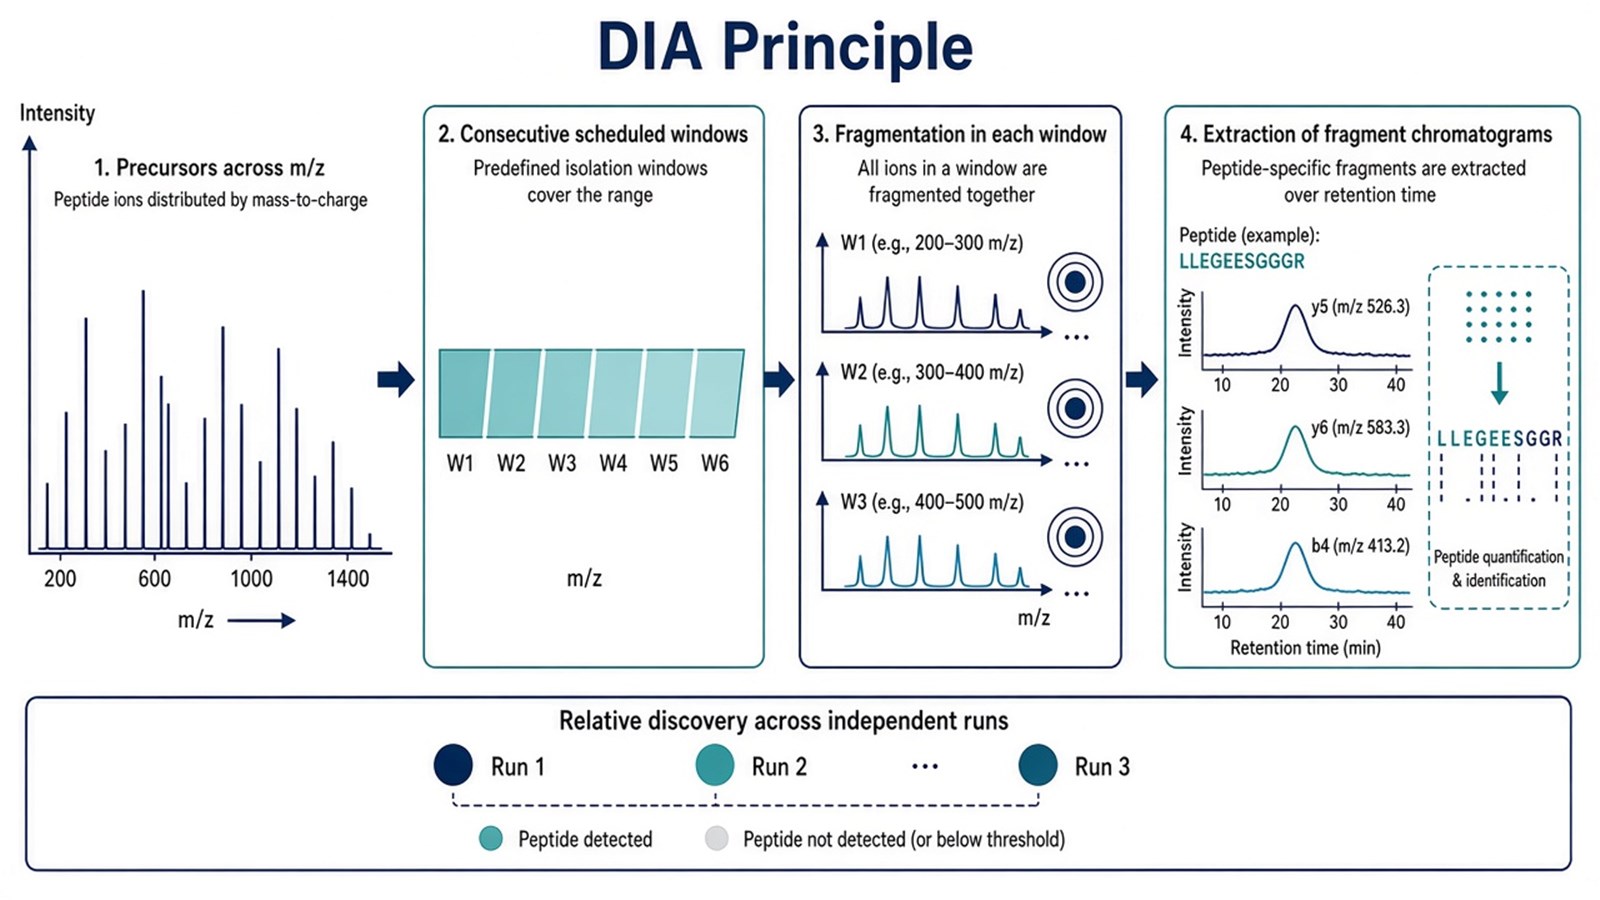
Figure 1. DIA fragments scheduled m/z windows and extracts fragment chromatograms for relative discovery across independent runs.
DIA names how fragmentation is scheduled. It does not mean labels were unused, and it does not mean every peptide is interference-free.
What SWATH Means Relative to DIA
SWATH-MS applies the DIA principle as sequential precursor isolation windows and recovers peptide quantities by matching extracted transitions to a spectral library that stores peptide identity, fragment ions, and retention-time information (Gillet et al. 2012). The library often comes from prior DDA of matched or related samples, although public or project libraries may be used when provenance is documented.
SWATH should be read as a member of the DIA family, not as a separate omics category and not as a synonym for every modern library-free DIA search. Direct DIA or library-free routes still use scheduled-window acquisition; they change extraction strategy, not the definition of DIA. Naming SWATH does not specify instrument vendor, exact window scheme, gradient, or whether the digest was labeled.
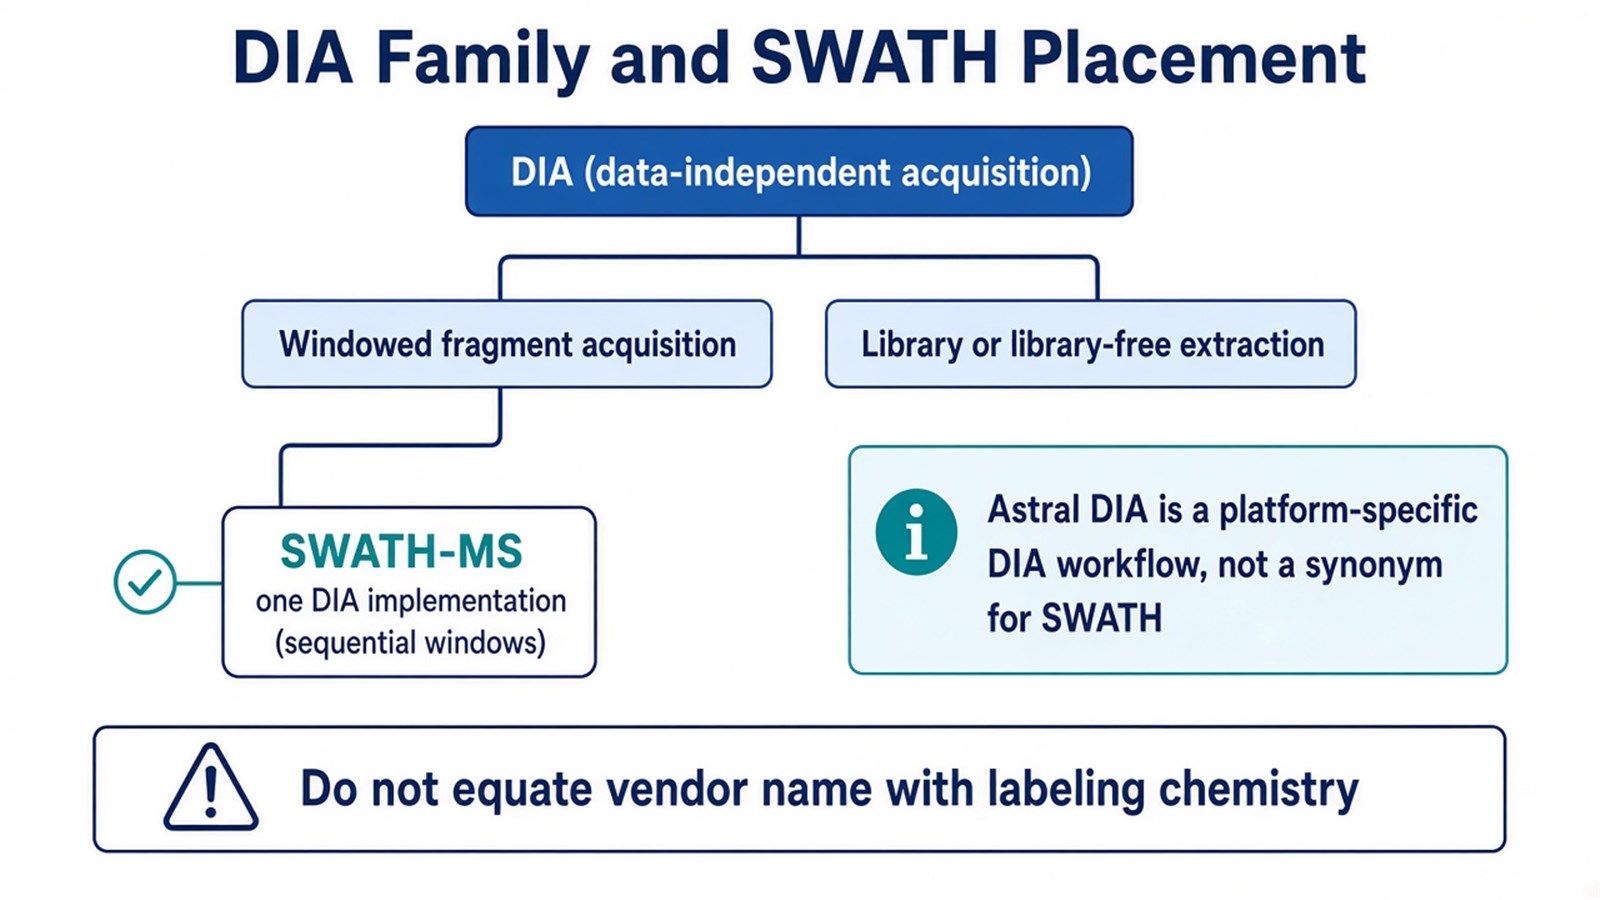
Figure 2. DIA is the acquisition class; SWATH-MS is one sequential-window implementation, commonly paired with library-based extraction.
For SWATH-centered workflow and library detail beyond this definition page, researchers can refer to What Is SWATH Mass Spectrometry. For library-free extraction, see Direct DIA: High-Efficiency Proteomics without a Spectral Library.
Judgment Criteria: When DIA or SWATH Fits
Study need |
DIA / SWATH-style often fits |
Reassess before committing |
|---|---|---|
Discovery claim |
Relative protein change across independent unlabeled runs |
Absolute concentration or calibrated amount |
Missing-value concern |
Scheduled-window completeness preferred over stochastic DDA picks |
Simple matrix where DDA depth is already enough |
Library logistics |
Empirical library available, or library-free DIA planned |
Library unmatched to matrix and no library-free path |
Panel status |
Open discovery inventory still needed |
Closed peptide list ready for PRM or MRM |
Cohort design |
Chromatography and processing can stay coherent across runs |
Many disconnected instrument blocks without bridging |
Prefer DIA when relative unlabeled discovery needs more consistent fragment coverage than stochastic DDA sampling provides. Prefer a SWATH-style library workflow when an appropriate spectral library is part of the analysis plan. Prefer Direct DIA when library construction is the bottleneck. Prefer DDA-LFQ when identification-centric DDA files and MaxLFQ are the planned path. Prefer PRM or MRM when targets are already closed.
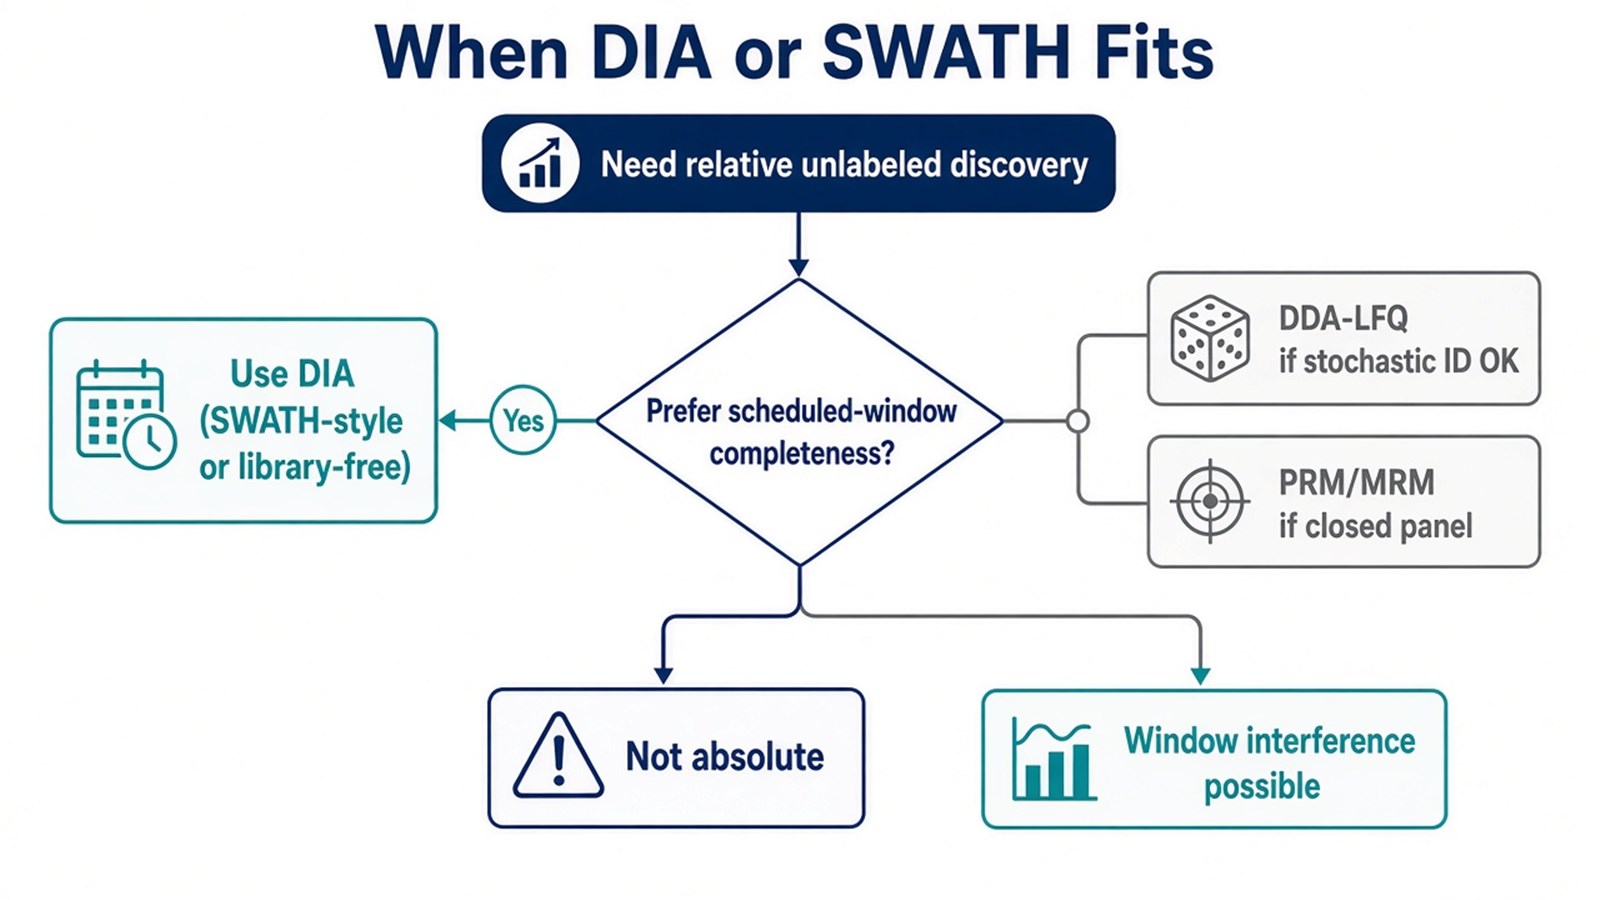
Figure 3. Use DIA or SWATH-style methods for relative scheduled-window discovery; keep DDA-LFQ or targeted assays when the claim or panel status differs.
Limits and Application Boundaries
Window interference can still mix fragment signals. Library gaps transfer into SWATH-style matrices. Library-free search removes some library logistics but not chromatography drift or batch confounding. Ordinary DIA intensities support relative change of the same protein across comparable runs. Absolute amount needs matched standards and a calibration model. Cross-site alignment is a design and QC problem, not an automatic property of the SWATH name.
Typical applications are treatment or genotype screens, tissue-state comparisons, plasma or other complex-matrix discovery cohorts, and projects that may re-extract stored DIA files under updated libraries or search settings. Pathway enrichment on a DIA candidate list reflects overrepresentation relative to a quantified background. It does not prove pathway activity. Diagnostic cutoffs sit outside ordinary research DIA reporting unless a separately validated assay framework is in place.
Once the acquisition mode, library or library-free route, and relative comparison design are defined, the project can be evaluated as a DIA or SWATH-style study. Researchers can review the MtoZ Biolabs Deep DIA Proteomics Service for sample evaluation, feasibility assessment, and workflow planning. For unlabeled DIA context and analysis tooling, see Label-Free DIA Quantitative Proteomics and Essential Analysis Tools for Label-Free Proteomics: A Comprehensive Review of MaxQuant and DIA-NN.
Frequently Asked Questions
1. Are DIA and SWATH the same thing?
No. DIA is the acquisition class based on scheduled-window fragmentation. SWATH-MS is one sequential-window DIA implementation, often analyzed with a spectral library.
2. Is DIA the same as label-free quantification?
No. DIA names acquisition. Label-free names the absence of isotopic or isobaric tags. Unlabeled samples are often acquired as DIA, but the two decisions remain separate.
3. Can DIA or SWATH report absolute protein concentration?
Not from ordinary intensities. Absolute amount requires matched standards and a calibration model.
4. Does SWATH guarantee better results than every other DIA method?
No. Performance depends on window design, chromatography, library quality or library-free settings, and QC. SWATH is a specific implementation tradition, not a universal ranking.
5. When is PRM better than continuing with DIA?
When a closed peptide shortlist needs fragment-level confirmation or a tighter targeted claim than the discovery matrix can defend.
Reference
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
