



Label-free peptide quantification uses software pipelines to turn unlabeled liquid chromatography-tandem mass spectrometry (LC-MS/MS) files into relative protein matrices. Tools sit in linked layers: identification, feature extraction, alignment, normalization, and contrast statistics (Cox et al. 2014). The layer set depends on acquisition. Data-dependent acquisition (DDA) LFQ usually integrates MS1 precursor areas after search. Unlabeled data-independent acquisition (DIA) extracts fragment chromatograms under false discovery rate (FDR) control (Gillet et al. 2012; Demichev et al. 2020). The guide below maps those tool layers in project language and ties them to workflow, parameters, limits, and fit. It is not a software version catalog, not a benchmark contest, and not a pathway enrichment manual.
Tool choice cannot repair confounded run order or unequal prep. Pipeline version and parameter locks belong in the same record as the contrast (Lazar et al. 2016).
In MtoZ Biolabs offerings, unlabeled discovery reporting is commonly tied to one declared search, extraction, normalization, and statistics stack per cohort block.
Principle language appears in What Is Label-Free Analysis?. Quality integration appears in How to Improve Data Quality and Reproducibility in Label-Free Proteomics?.
Tool Layers in Label-Free Peptide Quantification Projects
Project records should name five layers, not a single program brand.
Raw conversion and peak picking prepare vendor formats for downstream search or extraction.
Peptide identification assigns sequences with declared database, enzyme rules, modifications, and FDR thresholds.
Quantitative feature extraction turns identifications into peptide intensities. MS1 peak integration supports DDA LFQ. Fragment trace extraction supports unlabeled DIA.
Alignment and normalization make separate injections comparable. Retention time alignment and scale correction are tool-dependent but design-dependent first.
Protein rollup and contrast statistics apply missing-value rules and test the predefined contrast only.
Spectral counting tools count peptide-spectrum matches. They can rank detectability but are a weak primary metric for group fold changes when MS1 areas exist on the same DDA files.
LFQ tools implement a declared pipeline; they do not define the biological contrast or claim unit.
Method survey context appears in Mass Spectrometry-Based Quantitative Proteomics: Labeled and Label-Free Quantification Strategies.
DDA LFQ Tool Chain From Search to Protein Matrix
Common DDA LFQ stacks combine database search with MS1 quantification modules.
Search engines score fragment spectra against a protein database. Parameters must stay fixed across the cohort block.
MaxLFQ-style algorithms use delayed normalization and peptide ratio relationships to estimate protein-level profiles from MS1 features (Cox et al. 2014). Match-between-runs options fill some missing features; they must be documented because they change dropout interpretation.
Alignment-first platforms emphasize chromatographic warping before intensity extraction. They still need frozen search rules and replicate design.
R-based statistical packages such as MSstats accept peptide-level tables from multiple search outputs and apply mixed models, imputation options, and contrast tests when the input format is declared.
Normalization detail appears in How to Normalize Data in Label-Free Quantitative Proteomics?.
Unlabeled DIA Tool Chain and Library Decisions
DIA tools extract from windowed MS/MS, not from MS1 picking alone.
Library-based extraction uses prior fragment evidence matched to study matrix. Library-free engines identify and quantify from DIA maps with interference modeling (Demichev et al. 2020).
Extractors must match the locked window plan and instrument generation used at acquisition.
OpenSWATH-style targeted extraction workflows document library provenance and FDR control for scheduled-window data (Quantitative Analysis of SWATH Proteomics Using OpenSWATH: A Complete Workflow Overview).
Broader extraction conventions appear in DIA Data Analysis Methods in Proteomics. Label-free DIA project framing appears in Label-Free DIA Quantitative Proteomics.
Parameters That Must Be Locked Across Tool Versions
Layer |
Parameter that must be declared |
Failure mode if ignored |
|---|---|---|
Search |
Database, enzyme, modifications, FDR |
Mixed search spaces |
Extraction |
MS1 versus DIA fragment route |
Incomparable features |
Alignment |
Algorithm version and anchors |
False correspondence |
Normalization |
Method and scope |
Global drift as biology |
Missing values |
Detection and imputation rules |
Hidden model bias |
Rollup |
Protein inference rule |
Shared peptide ambiguity |
Statistics |
Contrast frozen before tuning |
Post hoc relabeling |
Pipeline |
One version per cohort block |
Mid-cohort tool swaps |
Limits follow the same table. Switching search or extraction versions mid cohort splits the matrix. GUI convenience does not replace interleaved run order or matched prep. Statistical packages cannot fix arms that were merged after acquisition.
Integrated Workflow Where Tools Hand Off
A practical label-free tool spine usually runs as follows.
- Confirm contrast, acquisition route, and pipeline scope.
- Convert raw files with shared settings.
- Identify peptides under locked search or DIA rules.
- Extract peptide intensities to a table with provenance metadata.
- Align and normalize across runs.
- Roll up to proteins with a declared rule.
- Apply missing-value policy; run matrix QC plots.
- Test predefined contrast only; archive software versions with outputs.
Steps 3 through 6 are where tool layers chain. Step 8 keeps statistics separate from exploratory parameter tuning on the full cohort.
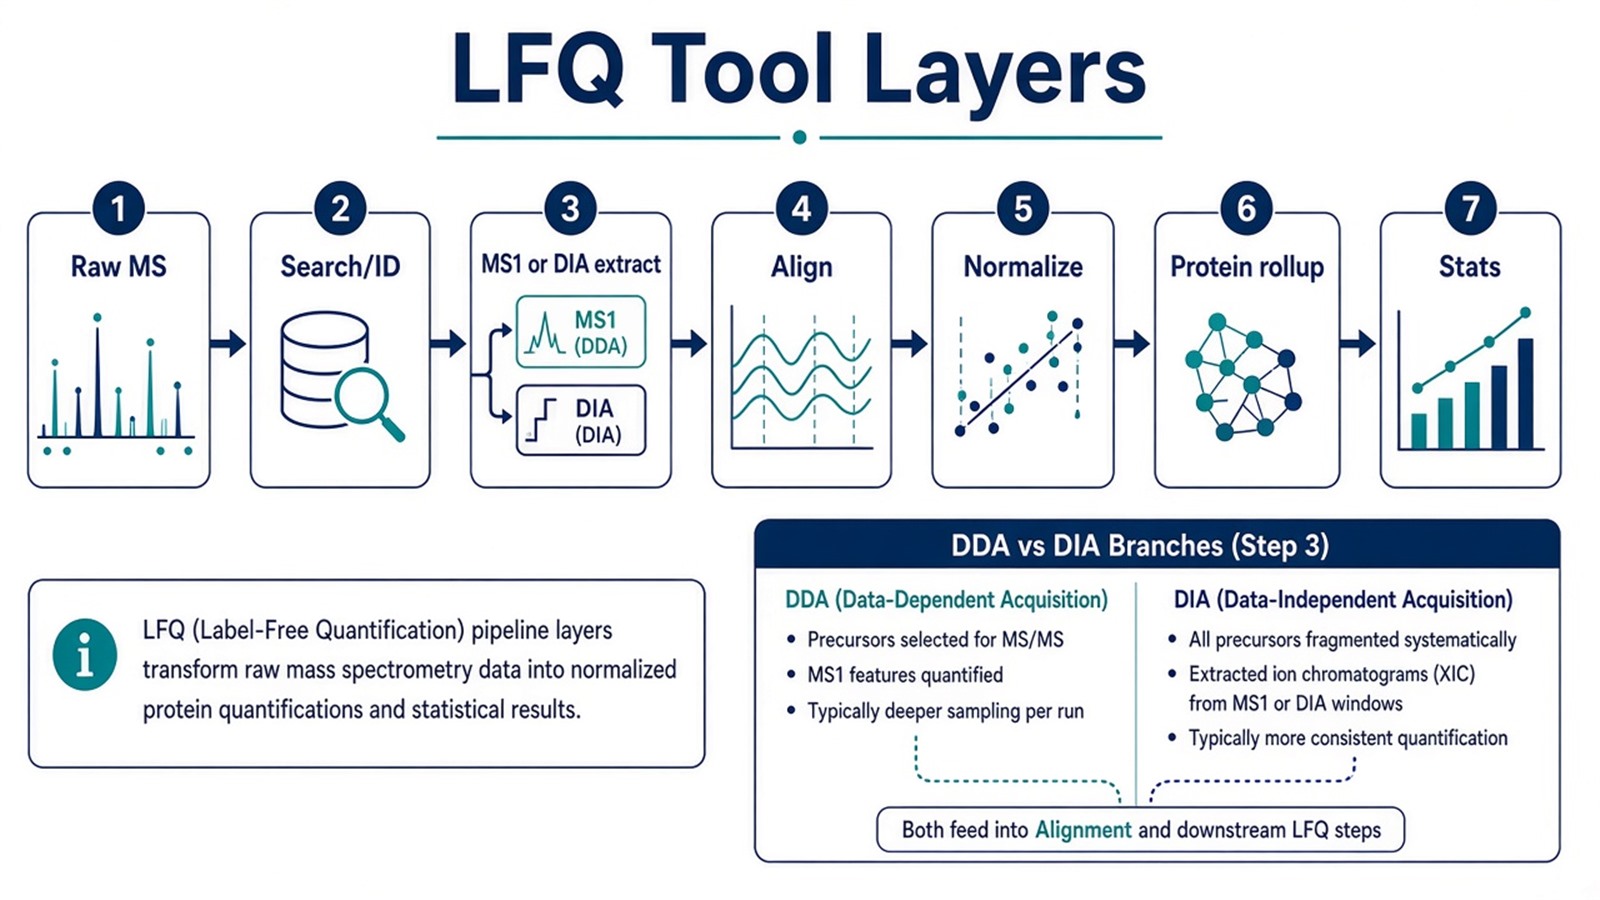
Figure 1. LFQ tools chain identification, extraction, alignment, and statistics; acquisition route sets which extraction layer applies.
Experiment framing appears in A Guide to Label-Free Quantitative Proteomics: From Experiment to Data Analysis. Prep before tools run appears in Quantitative Protein Analysis.
How to Choose Tool Scope for the Next LFQ Project
Use acquisition route, cohort size, and follow-up goal together.
Project need |
Tool scope that often fits |
Recheck before committing |
|---|---|---|
DDA LFQ, standard discovery |
Search plus MS1 quant module plus stats |
DIA extractor on DDA files |
Large DIA cohort |
Library or library-free DIA extractor plus stats |
DDA search-only without DIA quant |
Multi-site files |
Harmonized pipeline version and parameters |
Mixed tool versions |
Clinical-style replicates |
Mixed-model stats on peptide table |
Underpowered replicate count |
Open list then targeted panel |
Discovery pipeline then separate PRM tools |
One model for discovery and SIS amount |
Spectral count screening only |
Count-based ranking |
Counts as precise LFQ fold change |
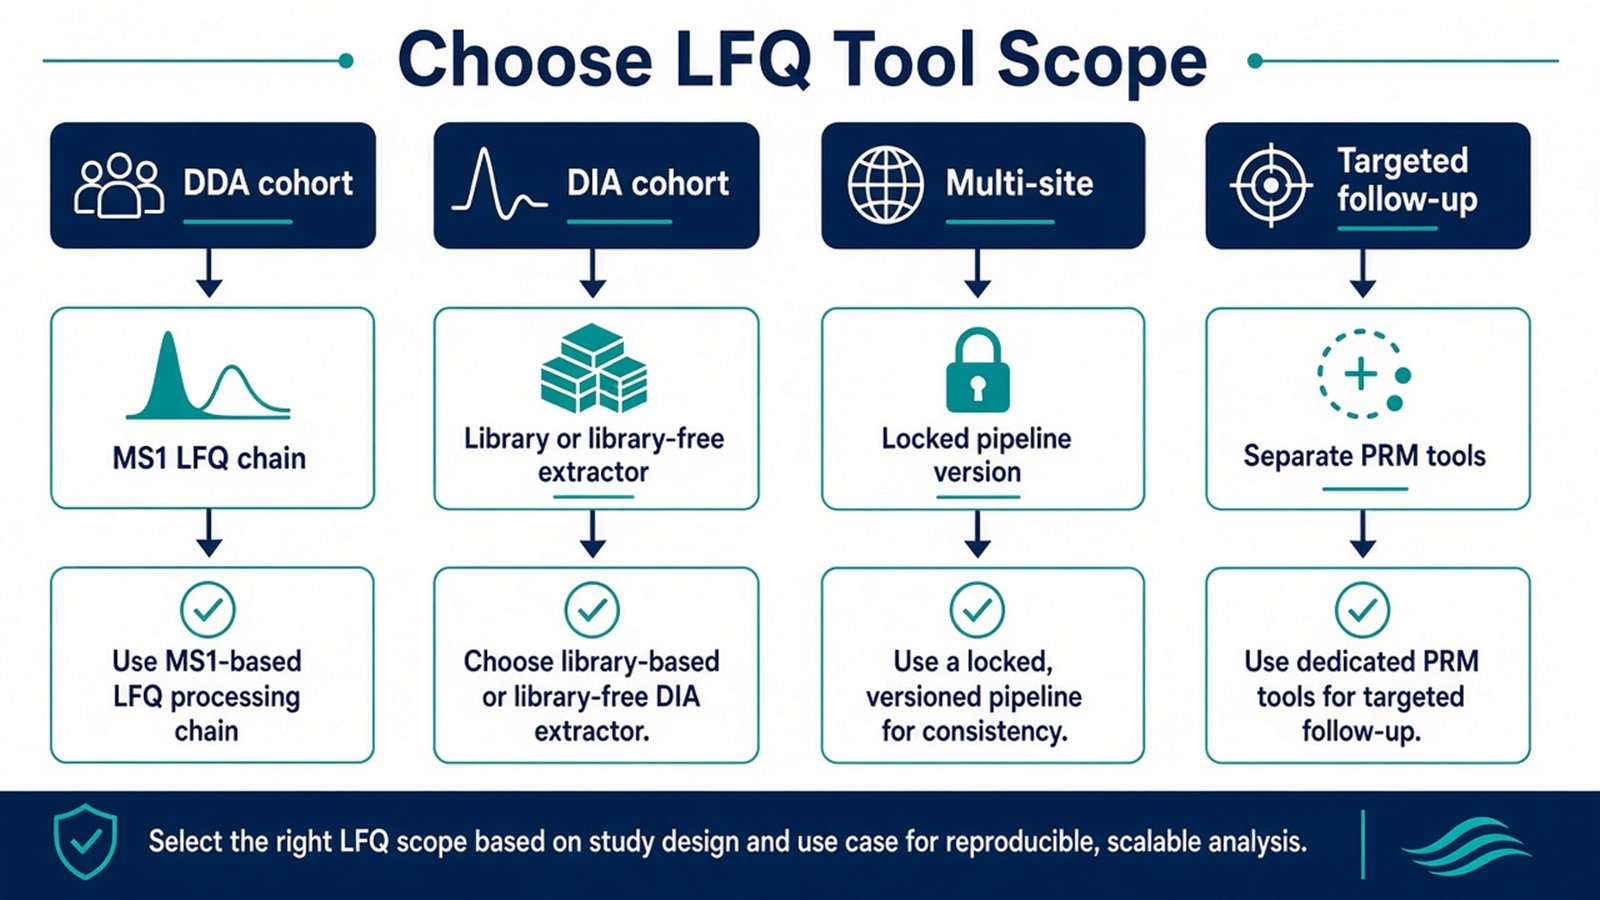
Figure 2. Choose DDA MS1 LFQ tools or DIA extraction stacks after acquisition route is fixed; targeted assays use separate tool chains.
Route selection appears in Protein Quantification Method. Enrollment checks appear in Exploring Quantitative Analysis in Proteomics.
Teams with acquisition route, cohort block plan, and contrast design can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for pipeline alignment.
Frequently Asked Questions
1. Is one software package enough for all LFQ projects?
No. Packages differ by DDA versus DIA support, statistical models, and export formats. The cohort block still needs one locked chain.
2. Does DIA-NN replace MaxLFQ-style workflows?
Not directly. DIA-NN targets unlabeled DIA extraction. DDA MS1 LFQ uses a different feature layer.
3. Can MSstats run on any search output?
Only when peptide tables meet the documented input requirements and contrast design is frozen.
4. Should Match Between Runs always be on?
It is a declared choice. Gap filling affects missing-value meaning and must appear in methods text.
5. Do enrichment tools fix poor LFQ matrices?
No. Pathway tools interpret tested lists. They do not replace alignment, normalization, or contrast QC.
MtoZ Biolabs can discuss label-free quantification tool planning when acquisition route, pipeline version, and contrast design are documented.
If further evaluation of DDA versus DIA extractor fit or discovery-to-targeted tool staging is needed, project details can be submitted for a feasibility review.
Reference
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, H. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- V. Demichev, C. Messner, S. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- M. Choi, C. Chang, N. Clough, D. Broudy, T. Killeen, B. MacLean, M. Vitek (2014). MSstats: an R package for statistical analysis of quantitative mass spectrometry-based proteomic experiments. Bioinformatics, 30, 2524-2526. https://doi.org/10.1093/bioinformatics/btu305
