



Sequential window acquisition of all theoretical fragment ion spectra (SWATH-MS) is a data-independent acquisition (DIA) schedule applied to unlabeled digests that stay on separate liquid chromatography-tandem mass spectrometry (LC-MS/MS) injections (Gillet et al. 2012). Label-free names the chemistry. SWATH names the window plan. Quantification still depends on matched sample pretreatment before those injections, then on library or library-free extraction after acquisition. The guide below focuses on sample handling and pretreatment for label-free SWATH work. It is not a spectral-library software manual, not a disease-application catalog, and not a DDA versus DIA theory page.
Unlabeled SWATH projects keep each digest on its own injection path. That design fits open cohorts that may still add samples. It also makes cross-run alignment and missing-value rules part of the downstream claim, not optional extras. In MtoZ Biolabs offerings, unlabeled digests are commonly acquired as DIA or SWATH-style windowed schedules, with extraction and statistics documented after the prep and acquisition record is fixed.
Sample Types Used for Label-Free SWATH-MS Quantification
Common label-free SWATH inputs include cultured cells, tissues, plasma or serum, and other biofluids. Each matrix changes lysis strength, depletion or fractionation needs, and how much material is required for a matched digest.
Cells often accept detergent or urea lysis with controlled reduction and alkylation. Tissues need disruption plus debris removal before digestion. Plasma and serum often require abundant-protein depletion or fractionation applied equally across groups when deep discovery is planned. Biofluids that cannot be relabeled later still fit unlabeled separate injections when enrollment stays open.
Sample type sets the first SWATH prep bound: matched extraction across groups matters more than a SWATH keyword in the project title.
Bulk Bradford, bicinchoninic acid (BCA), Lowry, and 280 nm assays help match total protein input. They do not replace peptide-level SWATH extraction after acquisition.
Pretreatment Steps That Keep SWATH Digests Comparable
Label-free SWATH comparability depends on matched prep, not on window width alone.
Lysis and digestion. Groups should share buffer family, enzyme-to-substrate ratio, and digestion time. Filter-aided or solid-phase cleanup helps remove detergents and chaotropes that suppress LC and fragment extraction (Wisniewski et al. 2009).
Cleanup and recovery. Peptide yield must stay comparable after StageTip-style or cartridge cleanup (Rappsilber et al. 2007). Group-specific losses create missing values that track treatment, not biology.
Desalting and injection load. SWATH acquisition needs stable chromatography across the cohort. Unequal dry-down recovery or mismatched peptide loads per injection distort extracted fragment traces before the window scheme is even tested.
No isobaric tagging step appears in label-free SWATH prep. Digests proceed directly to LC when cleanup is complete. Stable isotope-labeled internal standard (SIS) peptides, when used later on named targets, are a targeted follow-up claim, not part of ordinary open SWATH discovery prep.
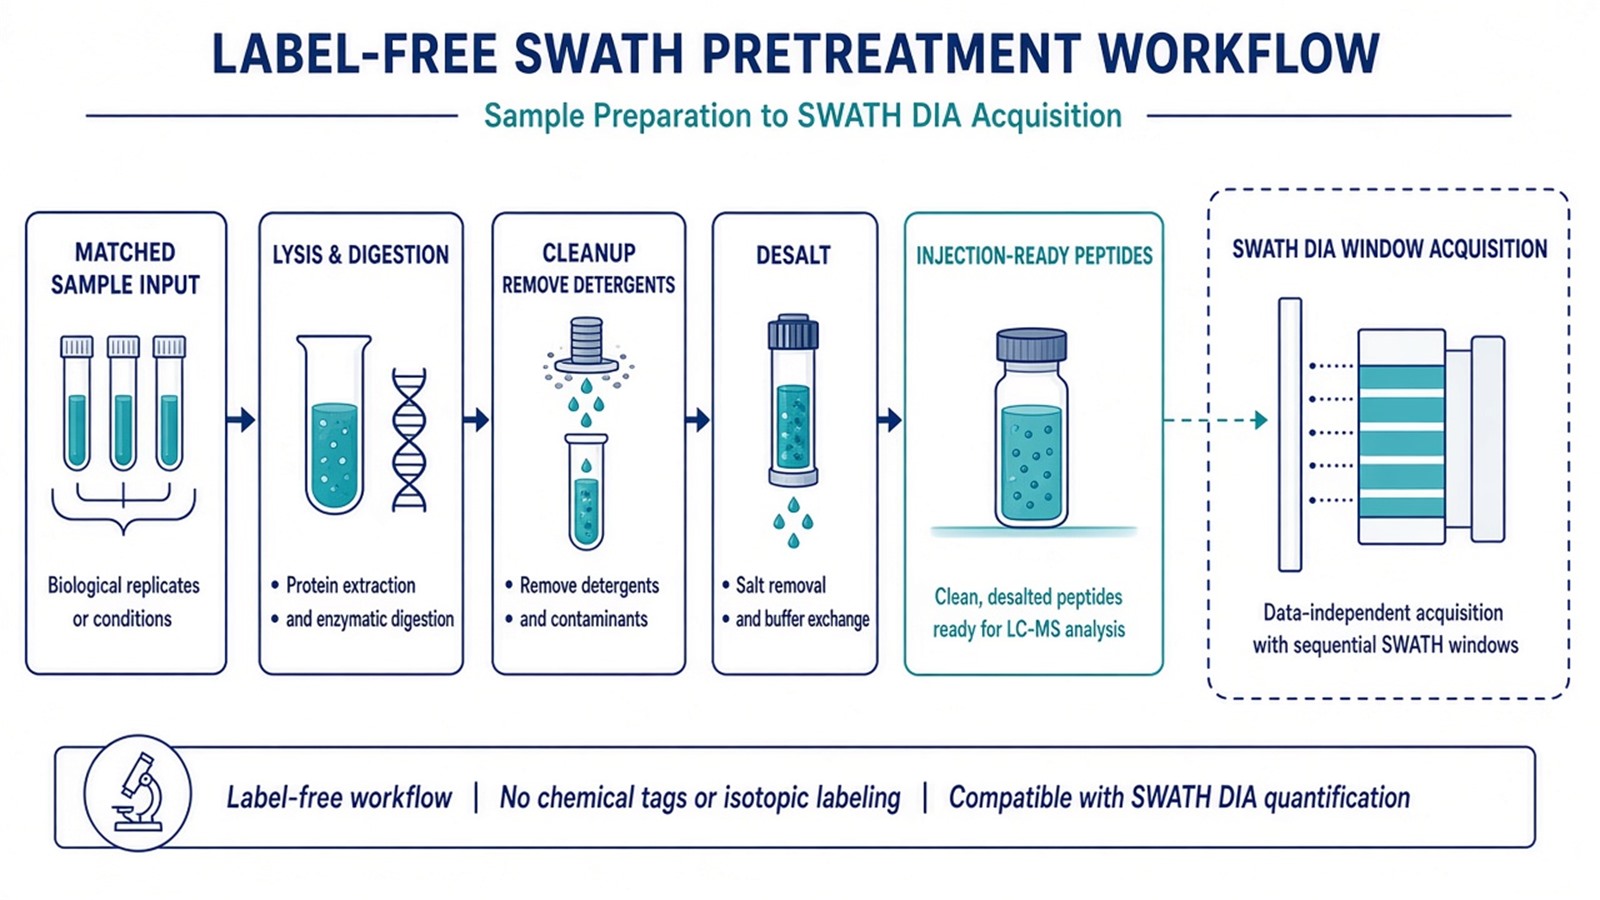
Figure 1. Label-free SWATH quantification starts with matched pretreatment and injection-ready digests before windowed acquisition and extraction.
Researchers who need the general lysis-to-digest spine can refer to Quantitative Protein Analysis. For enrollment and pilot checks before large SWATH batches, see Exploring Quantitative Analysis in Proteomics.
Shared Workflow From Sample Receipt to SWATH-Ready Injection
A practical label-free SWATH prep spine usually runs as follows.
- Confirm matrix, contrast, and relative claim across separate injections.
- Aliquot matched input after a load assay; record freeze-thaw history.
- Lyse, reduce, alkylate, and digest under shared rules.
- Clean peptides to LC-compatible purity and recovery.
- Desalt and resuspend at a declared load; run a pilot injection when the recipe is new.
- Acquire SWATH windows under a locked plan, then hand files to extraction.
Steps 1 through 5 belong to pretreatment. Step 6 crosses into acquisition. Extraction, FDR control, interference filters, and contrast testing belong with DIA Data Analysis Methods in Proteomics. Mixing prep batches with treatment labels breaks SWATH comparability even when the window scheme is unchanged.
Order errors show up as alignment failure or abundance-dependent missingness (Lazar et al. 2016). Pathway enrichment after search cannot repair unequal cleanup or confounded injection order.
Parameters and Limits in Label-Free SWATH Sample Prep
Parameter |
Why it matters for SWATH prep |
Failure mode if ignored |
|---|---|---|
Matched input and lysis |
Keeps peptide yield comparable |
Apparent fold changes from load bias |
Equal cleanup recovery |
Limits group-specific dropout |
Missingness that tracks treatment |
Detergent and salt removal |
Protects LC and extraction |
Weak or unstable fragment traces |
Injection load per run |
Stabilizes peak groups |
Saturation or weak alignment |
Pilot before cohort |
Catches bad loads early |
Full batch repeat digestion |
Run-order plan |
Separates biology from batch |
Treatment tracks injection day |
Limits follow the same table. SWATH prep does not label channels. Late samples cannot join prior injections as hidden replicates. SWATH does not report absolute concentration from open discovery intensities without SIS on named peptides. Plasma depletion applied to only one arm is not enrichment. Identification depth after extraction is not a prep success metric by itself.
Window width and library strategy are acquisition and analysis parameters. They must be declared with the matrix, but they do not replace matched pretreatment. Researchers who need analysis-side limits can refer to A Guide to Label-Free Quantitative Proteomics: From Experiment to Data Analysis after SWATH-ready injections exist.
How to Choose Pretreatment for the Next SWATH-MS Project
Use matrix, enrollment flexibility, and claim unit together.
Project need |
Pretreatment plan that often fits |
Recheck before committing |
|---|---|---|
Open cohort, cells or tissue |
Matched unlabeled prep, separate SWATH injections |
Run order identical to treatment |
Plasma or serum SWATH discovery |
Equal depletion plus matched digest |
Depletion on only one group |
Flexible time-course harvests |
Interleaved prep and injection order |
All late time points in one prep batch |
Freezable set that must share one LC day |
Matched loads; consider TMT instead |
Forced SWATH when mixing is required |
Named peptides after SWATH discovery |
Same cleanup rules, then targeted panel |
Open SWATH stats as confirmation |
Amount on selected peptides |
Targeted SIS assay, not open SWATH table |
Discovery peaks read as concentration |
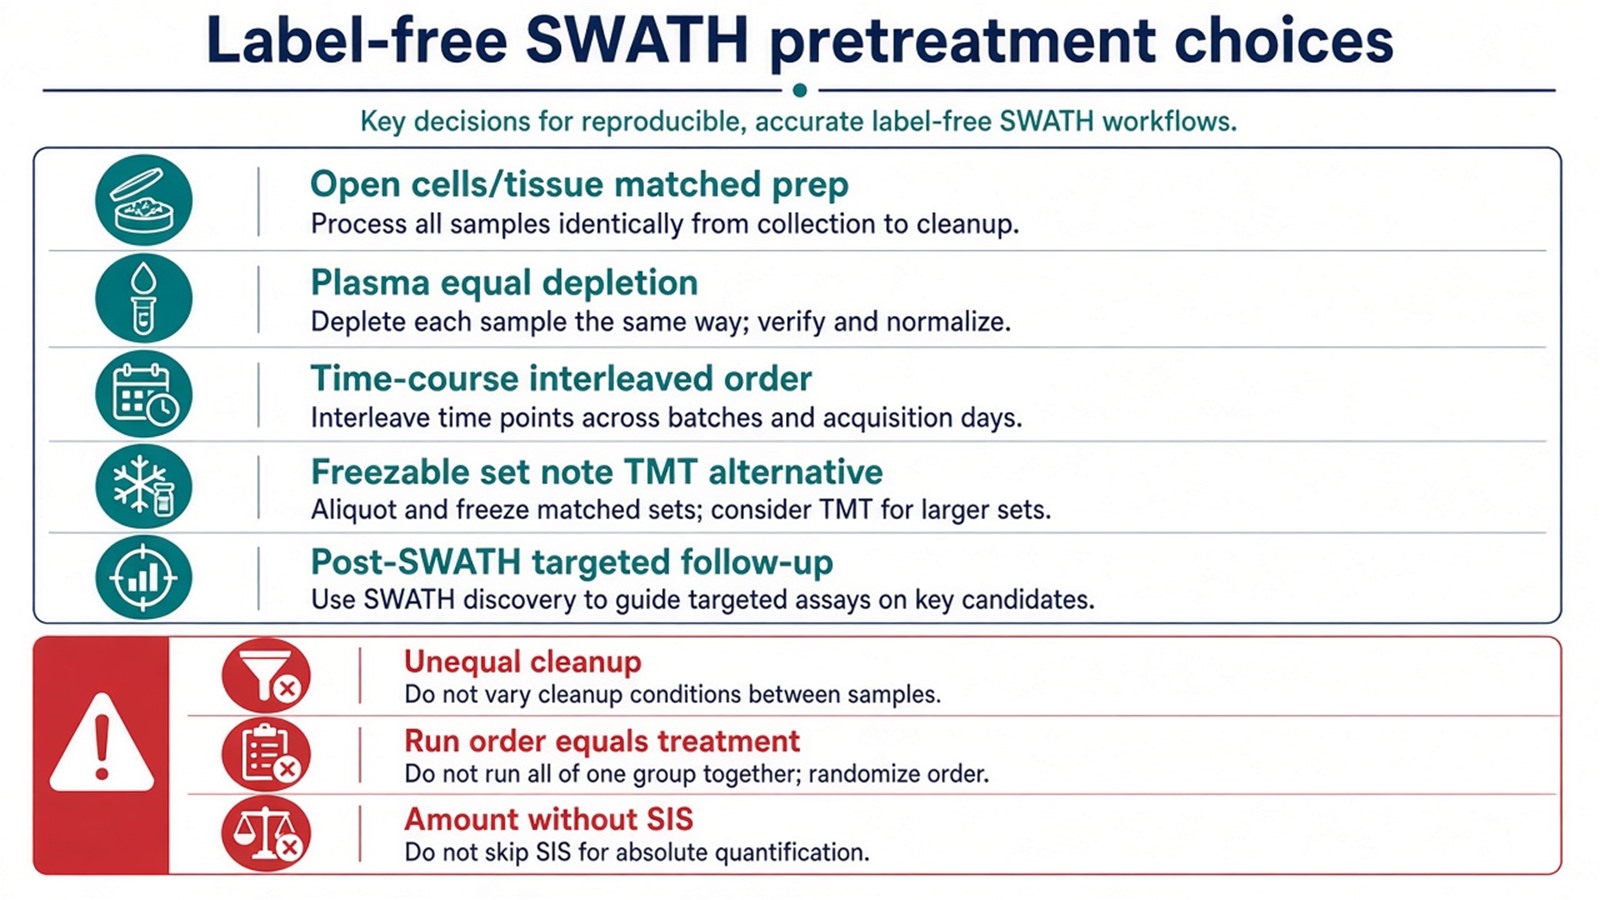
Figure 2. Choose SWATH prep from matrix and enrollment; unequal cleanup, confounded run order, and amount-without-SIS requests need repair first.
Unlabeled SWATH pretreatment more often fits open enrollment with separate injections. TMT prep more often fits a freezable multi-group set that must share one mixed LC path. Targeted confirmation more often fits after names freeze from the same digest material. Exceptions exist when a short closed cohort must limit run-order drift through tight injection scheduling, not through skipped prep QC.
Teams that already have matrix, contrast, and a requested relative claim can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for project-specific SWATH pretreatment and acquisition planning. For route selection against TMT or DDA LFQ, see Protein Quantification Method.
Frequently Asked Questions
1. Is SWATH-MS a different labeling method from label-free quantification?
No. Label-free names the chemistry. SWATH names a DIA window acquisition schedule on unlabeled digests.
2. Must every SWATH project build a DDA library first?
No. Library-free extraction routes exist. Prep quality rules stay the same regardless of library strategy.
3. Can SWATH prep differ by treatment group?
Only when prep is an explicit experimental factor. Otherwise matched lysis and cleanup are required across groups.
4. Does SWATH prep require isobaric tags?
No. Isobaric tagging is a separate route. SWATH label-free work keeps digests unlabeled through injection.
5. Is a successful SWATH search proof that pretreatment was matched?
No. Search can return IDs from uneven prep. Matrix QC and contrast design still decide whether ratios are trustworthy.
MtoZ Biolabs can support label-free SWATH pretreatment and acquisition planning when sample type, study design, and the intended relative claim are available.
If further evaluation of matrix-matched lysis, depletion strategy, injection loads, or SWATH versus TMT enrollment is needed, project details can be submitted for a feasibility review.
Reference
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- J. Rappsilber, M. Mann, Y. Ishihama (2007). Protocol for micro-purification, enrichment, pre-fractionation and storage of peptides for proteomics using StageTips. Nat. Protoc., 2, 1896-1906. https://doi.org/10.1038/nprot.2007.261
- J.R. Wisniewski, A. Zougman, N. Nagaraj, M. Mann (2009). Universal sample preparation method for proteome analysis. Nat. Methods, 6, 359-362. https://doi.org/10.1038/nmeth.1322
- G. Rosenberger, S. Liu, J. Röst, H.L. Ludwig, C. Buil, B. Borchers, R. Aebersold, L. Collins (2017). Statistical control of peptide and protein error rates in large-scale targeted data-independent acquisition analyses. Nat. Commun., 8, 14224. https://doi.org/10.1038/ncomms14224
