



When SWATH-MS results look inconsistent, troubleshoot analysis choices before relabeling biology: confirm the files are scheduled-window DIA, check whether the spectral library or library-free route matches the cohort matrix and gradient, verify that peptide and protein FDR rules were locked to the window plan, inspect retention-time alignment and peak-group interference, and separate prep or injection batch effects from normalization choices (Gillet et al. 2012; Rosenberger et al. 2017). Prefer fixing library mismatch, extractor version changes, and alignment QC when missing values or ratio compression track processing; keep acquisition changes only after analysis rules are stable; split cohorts if mixed window tables or processing versions were merged (Demichev et al. 2020). Analysis cannot repair unmatched prep or undefined contrasts.
Researchers who already have SWATH or DIA raw files, defined groups, and a requested contrast can also review the MtoZ Biolabs Deep DIA Proteomics Service, Label-Free DIA Quantitative Proteomics, and DIA based Protein Quantitative Service for project-specific extraction planning.
Troubleshooting Map: Symptom to Analysis Cause
SWATH-MS is sequential-window DIA analyzed by fragment peak-group extraction. Most pitfalls are mismatches between acquisition metadata, library provenance, and declared contrasts.
Observed problem |
Likely analysis-related cause |
First check |
|---|---|---|
Global protein loss vs expectation |
Wrong extractor for vendor or window table |
Window scheme and software route |
Inflated peptide counts |
Weak FDR or interference filters |
Peptide and protein FDR audit |
Missing values track sample order |
Failed RT alignment or iRT drift |
Alignment QC and reference peptides |
False biology after merging studies |
Different window plans or library versions |
Split by processing version |
Noisy ratios in dense regions |
Co-fragmentation in wide windows |
Window design and peak-group QC |
DDA-style search on SWATH files |
Acquisition class mismatch |
Re-run with DIA extractor |
Apparent batch fix after stats only |
Prep or run order confounded with groups |
Design record before imputation |
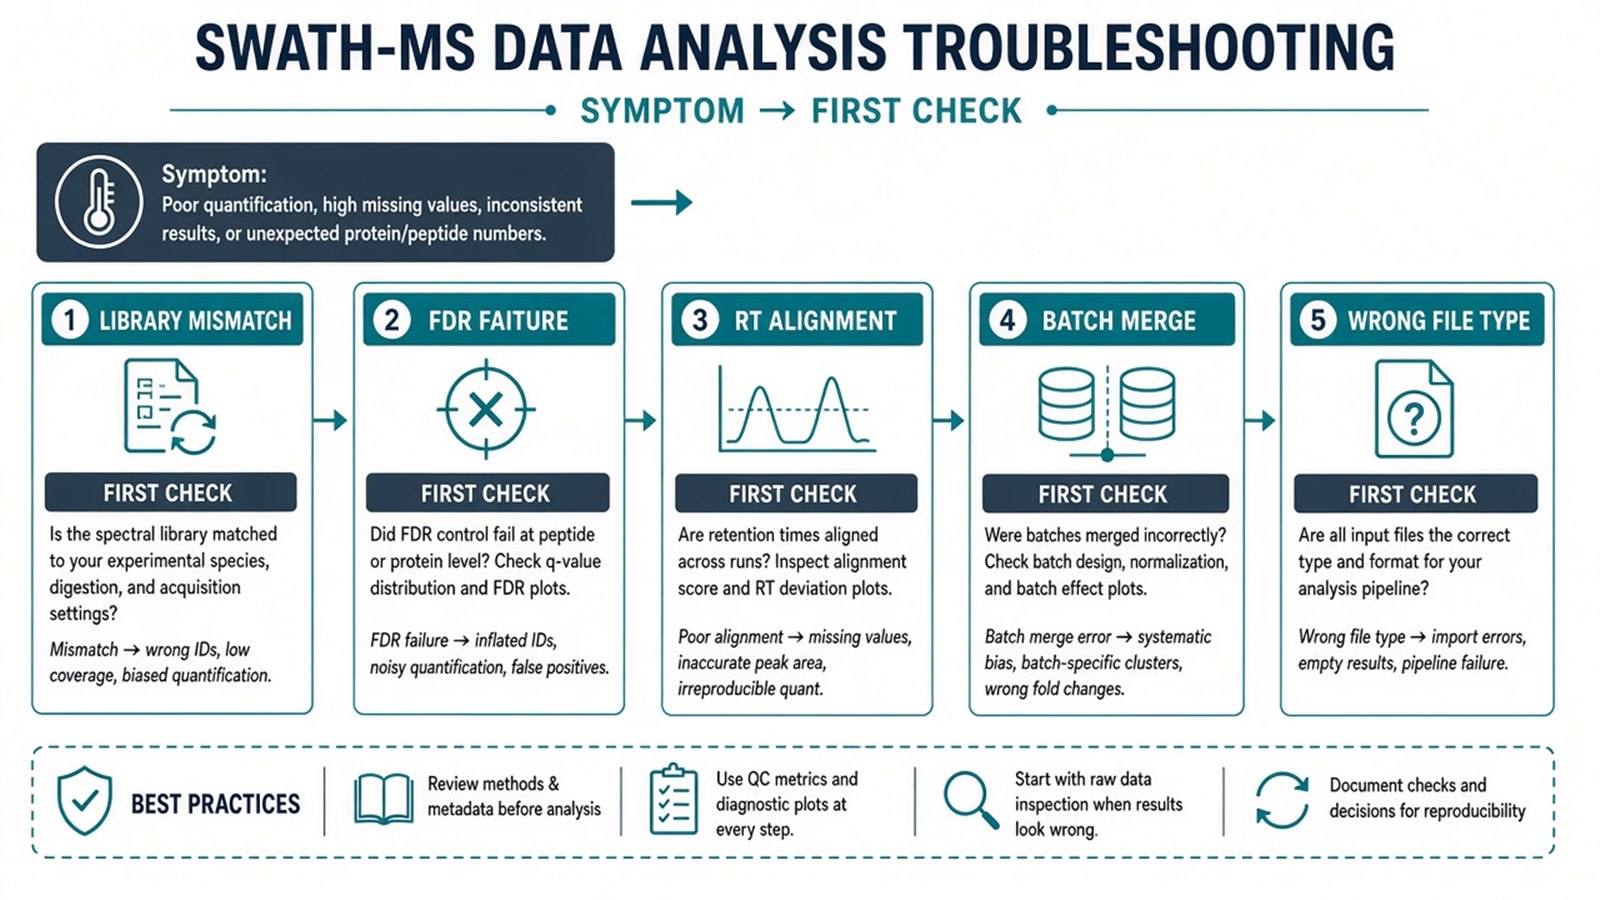
Figure 1. SWATH-MS troubleshooting starts at analysis metadata and extraction rules, not at differential test choice alone.
Imputing missing peptides before documenting why traces failed often freezes processing errors into the final matrix.
Standard SWATH-MS Analysis Workflow (With Pitfall Checkpoints)
- Import windowed raw files with documented conversion settings (centroid versus profile affects downstream peak picking).
- Lock the isolation-window table and chromatographic gradient reference used at acquisition.
- Choose library-based targeted extraction or a defended library-free route; do not switch mid cohort without versioning.
- Control peptide and protein FDR with decoy-aware scoring suited to the extractor (Rosenberger et al. 2017).
- Align retention times across runs; use indexed retention standards when the platform supports them.
- Filter interfered or weak peak groups before protein roll-up.
- Normalize only after QC maps; declare missing-value policy before group tests.
- Test predefined contrasts; treat pathway enrichment as secondary to matrix QC.
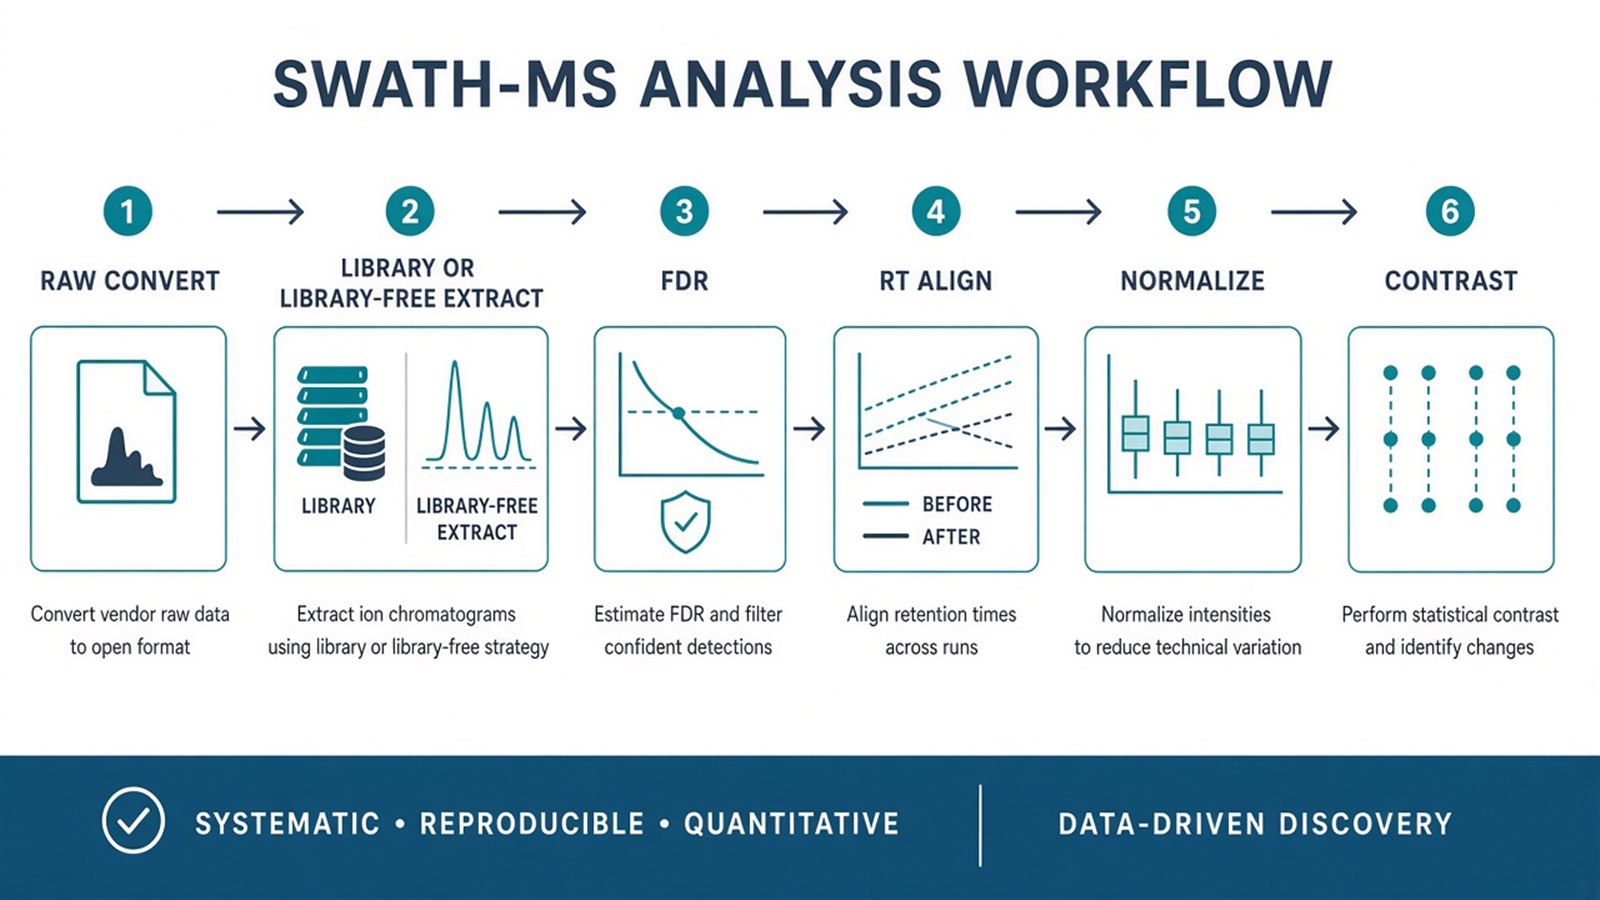
Figure 2. Each SWATH analysis step carries pitfall risk when window plans, libraries, or versions drift across samples.
For general DIA analysis framing, see DIA Data Analysis Methods in Proteomics and Principles and Applications of Proteomics Data-Independent Acquisition (DIA) Technology. For OpenSWATH-oriented workflow context, see Quantitative Analysis of SWATH Proteomics Using OpenSWATH: A Complete Workflow Overview. For library-free options, see Direct DIA: High-Efficiency Proteomics Without a Spectral Library.
Judgment Criteria: When SWATH-MS Analysis Fits the Question
Study state |
SWATH-style analysis fits |
Reassess |
|---|---|---|
Raw files |
Scheduled-window DIA or SWATH acquisitions |
DDA MS1-only label-free files |
Contrast |
Groups and replicates frozen before tuning |
Open-ended fishing without design |
Library |
Matrix-matched or defended library-free path |
Transferred library from unlike matrix |
Claim |
Relative same-protein discovery |
Absolute concentration without standards |
Follow-up |
Shortlist may move to PRM or AQUA |
Diagnostic cutoff from discovery matrix |
Prefer SWATH-style extraction when windowed files, library or library-free capacity, and relative contrasts align. Prefer DDA-LFQ pipelines when acquisitions were not windowed DIA. Prefer TMT when a frozen multiplex plex fits better than reprocessing mixed window cohorts. Prefer PRM or AQUA when a closed panel needs confirmation or amount units.
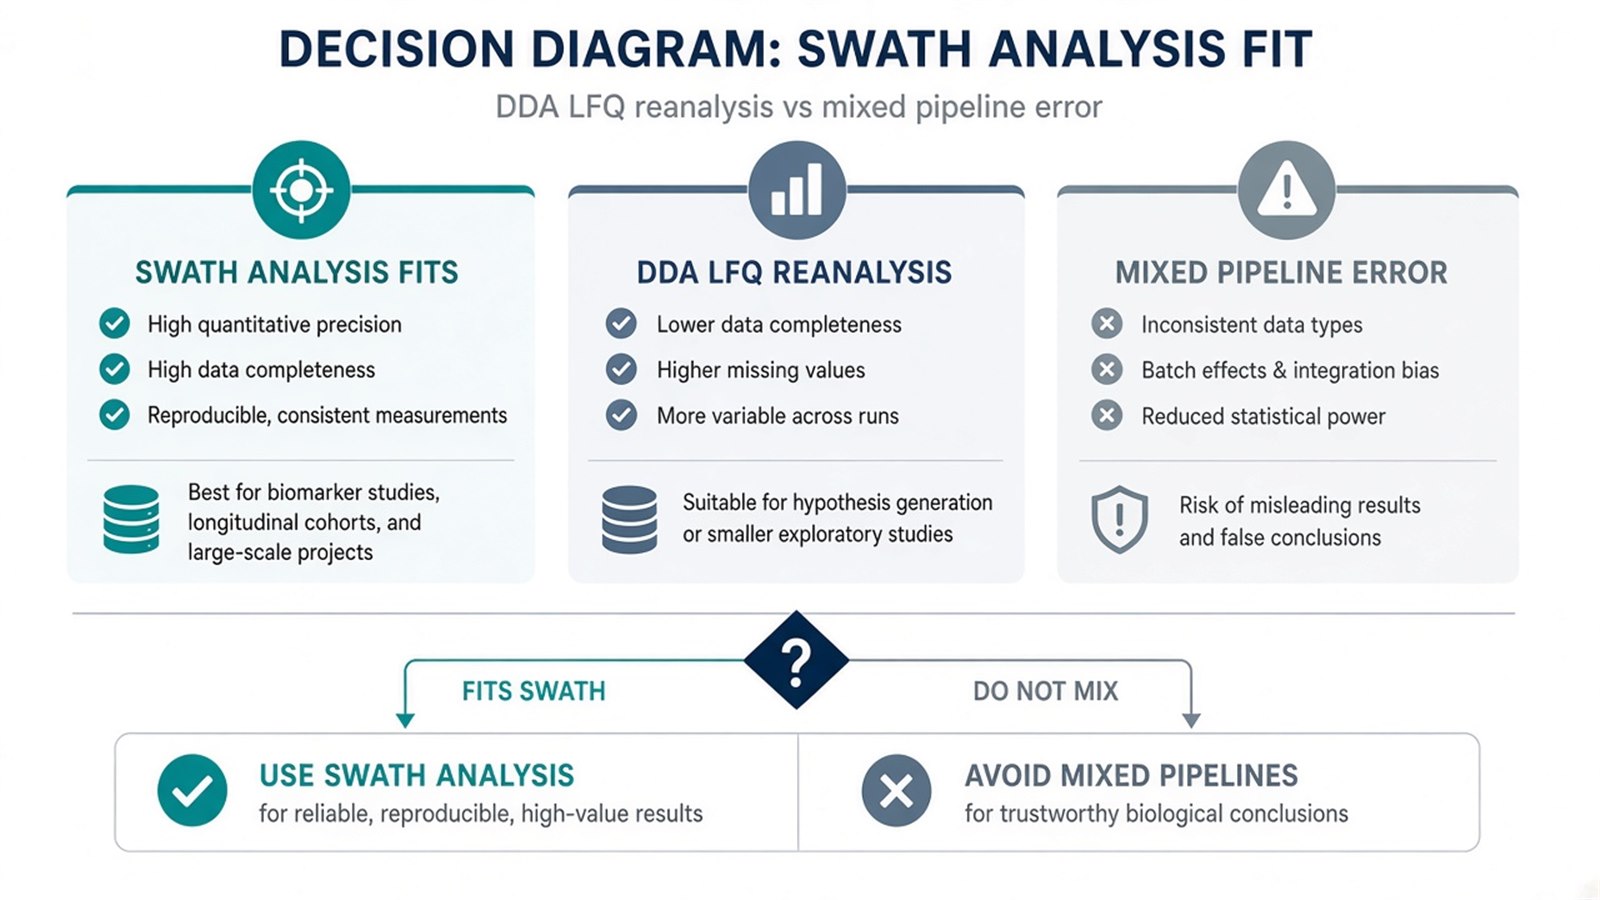
Figure 3. Use SWATH analysis workflows only when files and processing versions belong to windowed DIA; otherwise change route.
For method trade-offs, see Advantages and Disadvantages of SWATH-MS and Advantages and Disadvantages of DIA in Protein Quantification. For acquisition choice, see SWATH-MS vs DDA-MS: Which Technique Is Suitable for Your Research? and DDA vs. DIA vs. TMT in LC-MS/MS Proteomics: How to Choose the Right Strategy. For prep confounding, see The Impact of Sample Preparation on Quantitative Results in Quantitative Proteomics.
Limits and Application Boundaries
SWATH analysis does not create peptides absent from extractable fragment evidence. Completeness is not accuracy. Library transfer across dissimilar matrices can invent plausible peak groups. Reprocessing old cohorts with a new extractor version should be reported as a new matrix, not a silent update. Ordinary intensities remain relative unless matched standards and calibration are added. Pathway enrichment shows overrepresentation relative to the quantified background; it does not prove pathway activity. Diagnostic cutoffs sit outside ordinary research SWATH reporting unless a separately validated assay framework is in place.
Typical applications after a defended SWATH workflow:
- Cohort relative discovery when windowed acquisitions and extraction QC are documented.
- Biomarker-candidate nomination with plans for PRM or MRM confirmation.
- Biofluid or tissue screens where DDA missingness would dominate.
- Retrospective peptide trace review under FDR when raw window data are stored.
- Bridging run batches with QC pools when design supports anchor normalization.
Once window plan, extractor version, FDR rules, and contrast definitions are locked, the project can deliver a traceable SWATH quantitative matrix. Researchers can review the MtoZ Biolabs Deep DIA Proteomics Service for raw-file intake and analysis planning.
Frequently Asked Questions
1. What is the first troubleshooting step for bad SWATH results?
Verify acquisition class, window table, and that the same extractor version and library route were used across the contrast arms.
2. Is a spectral library always required for SWATH analysis?
Classical SWATH workflows often use one. Library-free or predicted-library DIA routes can work but still need FDR and interference QC.
3. Can I merge SWATH cohorts processed with different window plans?
Treat unlike window tables as incompatible for one naive merge. Reprocess under one plan or analyze contrasts within each acquisition block.
4. Does global normalization fix batch effects from prep?
Not reliably. Normalization adjusts intensities; it cannot undo group-confounded prep or run order without a designed bridge.
5. When should SWATH discovery move to PRM?
When a closed shortlist needs tighter fragment evidence or amount units. Discovery matrices alone do not replace targeted validation design.
Reference
- L.C. Gillet, P. Navarro, S. Tate, et al. (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.M111.016717
- G. Rosenberger, S. Liu, J. Röst, et al. (2017). Statistical control of peptide and protein error rates in large-scale targeted data-independent acquisition analyses. Nat. Commun., 8, 14224. https://doi.org/10.1038/ncomms14224
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
