



OpenSWATH is an open-source pipeline for targeted extraction and quantification of peptides from sequential window acquisition of all theoretical fragment ion spectra (SWATH-MS) files after data-independent acquisition (DIA) (Rost et al. 2014). It aligns windowed MS/MS traces to a spectral library, scores peak groups, and exports intensity matrices for contrast testing. The guide below maps that workflow for project planning from file prep through false discovery rate (FDR) control. It is not a command-line manual for every flag, not a vendor instrument tutorial, and not a repeat of label-free pretreatment chemistry.
SWATH acquisition and OpenSWATH extraction are linked but separate commitments. Matched digests and a locked window plan must exist before library-based extraction starts (Gillet et al. 2012). In MtoZ Biolabs offerings, unlabeled cohorts are often acquired as DIA or SWATH-style schedules, with extraction documented after prep and acquisition records are fixed.
Project Contexts Where an OpenSWATH Workflow Fits
Three project patterns commonly lead teams to library-based OpenSWATH extraction.
Cohort studies with a provenance-matched spectral library. Same species, digestion, gradient family, and instrument class as the library source fit targeted extraction when the library was built or imported with those fields documented.
Multi-file relative contrasts with unified FDR. Case-control, treatment, or time-point sets that need one scoring model across runs fit pyProphet-style FDR control after OpenSWATH peak picking (Rosenberger et al. 2017).
Teams that standardize on OpenMS-compatible formats. mzML conversion, TraML or transition lists, and indexed retention time (iRT) calibration are acceptable operational costs when the library path is already chosen.
OpenSWATH fits when a library-backed SWATH matrix is the declared extractor, not when the project still lacks matched prep or a locked contrast.
Label-free pretreatment before acquisition is covered in SWATH-MS Label-Free Protein Quantification Technology Analysis. Broader extractor comparison and matrix statistics appear in DIA Data Analysis Methods in Proteomics.
Prerequisites Before the OpenSWATH Spine Starts
Operational gates appear before the first OpenSwathWorkflow run.
Raw to mzML conversion. Vendor formats convert to mzML with consistent peak picking so chromatograms stay comparable across the cohort (Chambers et al. 2012).
Spectral library provenance. Libraries from data-dependent acquisition (DDA), public atlases, or project-specific builds must match species, digestion, and chromatography expectations. Format should be OpenSWATH-compatible, commonly transition tables or TraML.
iRT or retention-time normalization plan. Batch shifts need a declared calibration strategy, often spiked iRT peptides or RTNormalizer outputs, before peak groups are scored across files.
Contrast and replicate map frozen. OpenSWATH outputs intensities. Differential claims still require predefined groups and replicate structure agreed before FDR thresholds are tuned.
Skipping pretreatment alignment or mixing library species with sample species produces empty or misleading matrices even when the workflow completes.
End-to-End OpenSWATH Workflow Stages
A practical OpenSWATH spine usually runs as follows.
- Convert raw SWATH files to mzML with shared conversion settings.
- Acquire or build the spectral library; document source runs and digestion.
- Calibrate retention time with iRT standards or project-specific anchors.
- Run OpenSwathWorkflow on each mzML against the library; generate extracted ion chromatograms (XICs) and preliminary scores.
- Apply pyProphet or equivalent FDR modeling across runs for peptide-level control.
- Align runs and handle missing values with TRIC or a declared imputation policy before protein rollup.
- Roll up to protein groups with a documented rule; export the quantitative matrix.
- Test only the predefined biological contrast with statistics agreed upfront.
Steps 1 through 3 are file and library prep. Steps 4 through 6 define reproducibility across operators. Step 8 is where application claims live; enrichment alone does not replace contrast design.
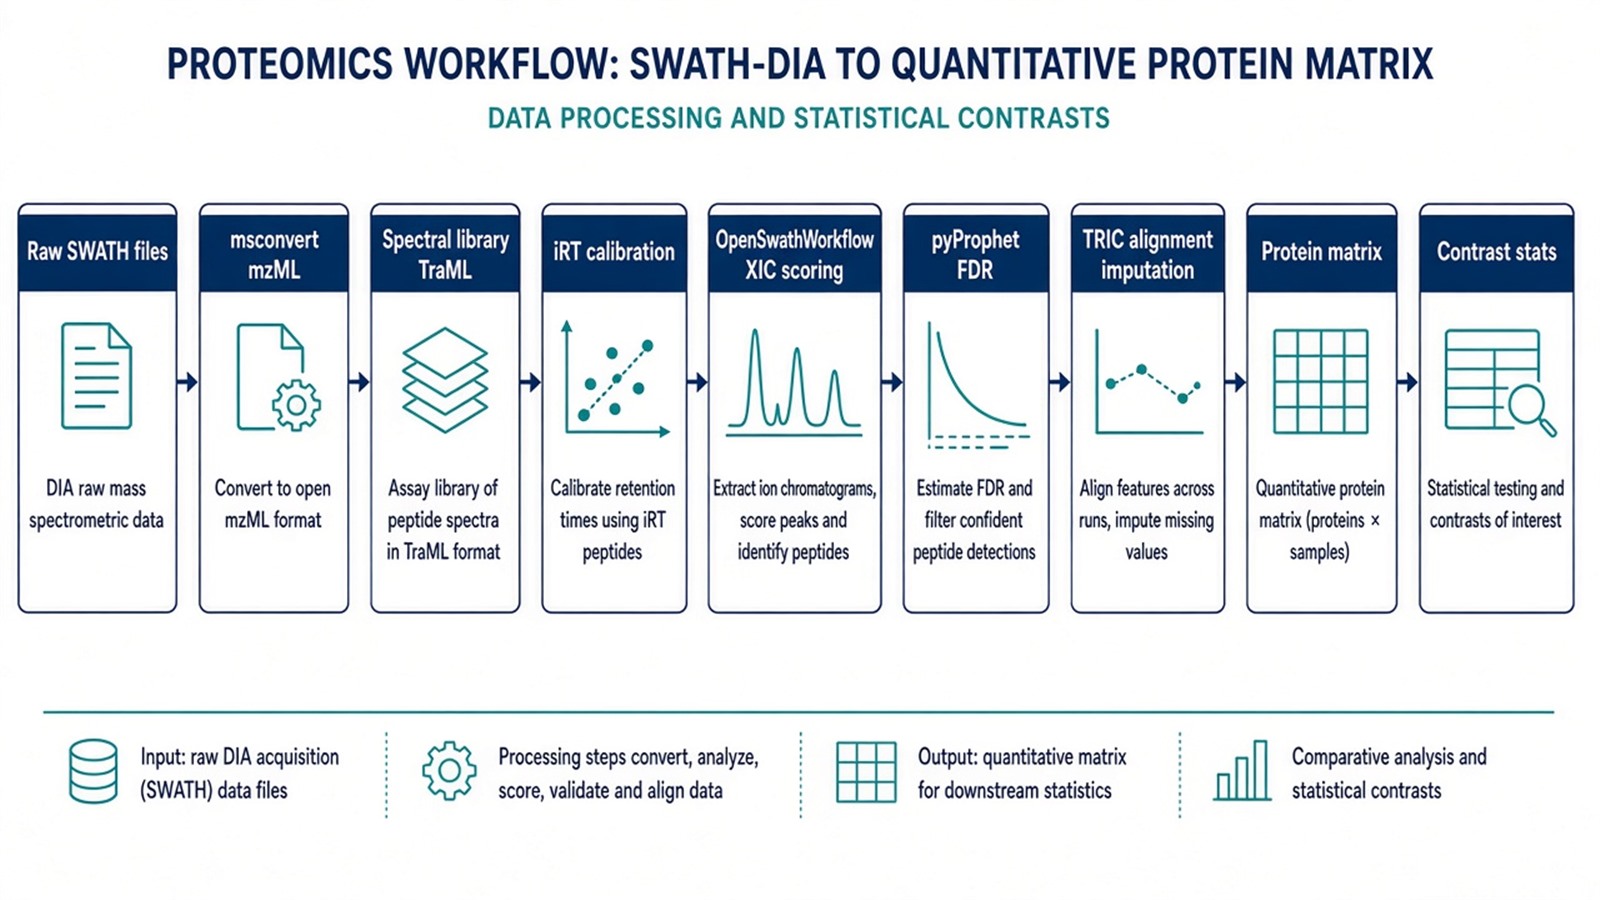
Figure 1. OpenSWATH operational flow moves from standardized mzML inputs and library provenance to FDR-controlled peak groups and a matrix for predefined contrasts.
High-throughput cohort applications that use the same matrix discipline are described in High-throughput SWATH-MS Quantitative Proteomics for Biomarker Discovery.
Key Parameters and QC Checkpoints
Stage |
Parameter or checkpoint |
Why it matters |
Typical failure signal |
|---|---|---|---|
Conversion |
Shared msconvert settings |
Keeps peak density comparable |
Drifting ID counts by file order |
Library |
Species and digestion match |
Bounds extractable peptides |
Systematic missing targets |
iRT |
Calibration coverage |
Aligns RT across batches |
Misassigned peak groups |
OpenSwathWorkflow |
Score and width settings |
Balances sensitivity and specificity |
Noise peaks or empty XICs |
FDR |
Unified model across runs |
Controls peptide error rate |
Per-run thresholds that drift |
Alignment |
TRIC or declared alternative |
Reduces RT misalignment |
Fragment traces that split by batch |
Missing values |
Imputation rule documented |
Stabilizes downstream stats |
Treatment-linked dropout ignored |
Protein rollup |
Shared aggregation rule |
Keeps contrasts reproducible |
Protein counts that change by script version |
QC should be recorded, not assumed. Pilot mzML subsets from the same prep batch expose library mismatch before full cohort compute is spent. Library-free direct DIA tools are an alternative when no provenance-matched library exists (Demichev et al. 2020). Switching extractors mid cohort breaks comparability even when raw files are unchanged.
Limits and Operational Constraints
OpenSWATH does not repair unequal sample prep, confounded run order, or undefined contrasts. It extracts what the library encodes; proteins absent from the library stay absent regardless of window width.
Compute and storage scale with file count, window count, and library size. Large agricultural or clinical cohorts need batch plans and shared configuration files so operators do not fork parameters silently.
Public libraries speed startup but rarely match every matrix. Custom DDA library builds add lead time yet often reduce missing targets when species or digestion differ from atlas defaults.
Pathway, gene ontology, or clustering after the matrix is interpretation. Mechanism and biomarker deployment claims need orthogonal validation and often targeted follow-up.
How to Choose OpenSWATH for the Next SWATH Project
Use library status, cohort size, and extractor policy together.
Project need |
OpenSWATH-oriented plan that often fits |
Recheck before committing |
|---|---|---|
Matched library from same project DDA |
OpenSWATH plus unified FDR |
Library built in different digestion |
Public atlas, model species |
Import library plus iRT pilot |
Atlas species mismatch |
Large multi-file contrast |
pyProphet across all mzML inputs |
Per-file manual cutoffs |
No usable library yet |
Library build or library-free route |
Forcing atlas on non-model matrix |
Open discovery then short list |
OpenSWATH matrix, then PRM panel |
Discovery p-values as final assay |
Mixed instrument generations |
Separate extractor configs per batch |
Merged matrix without batch covariate |
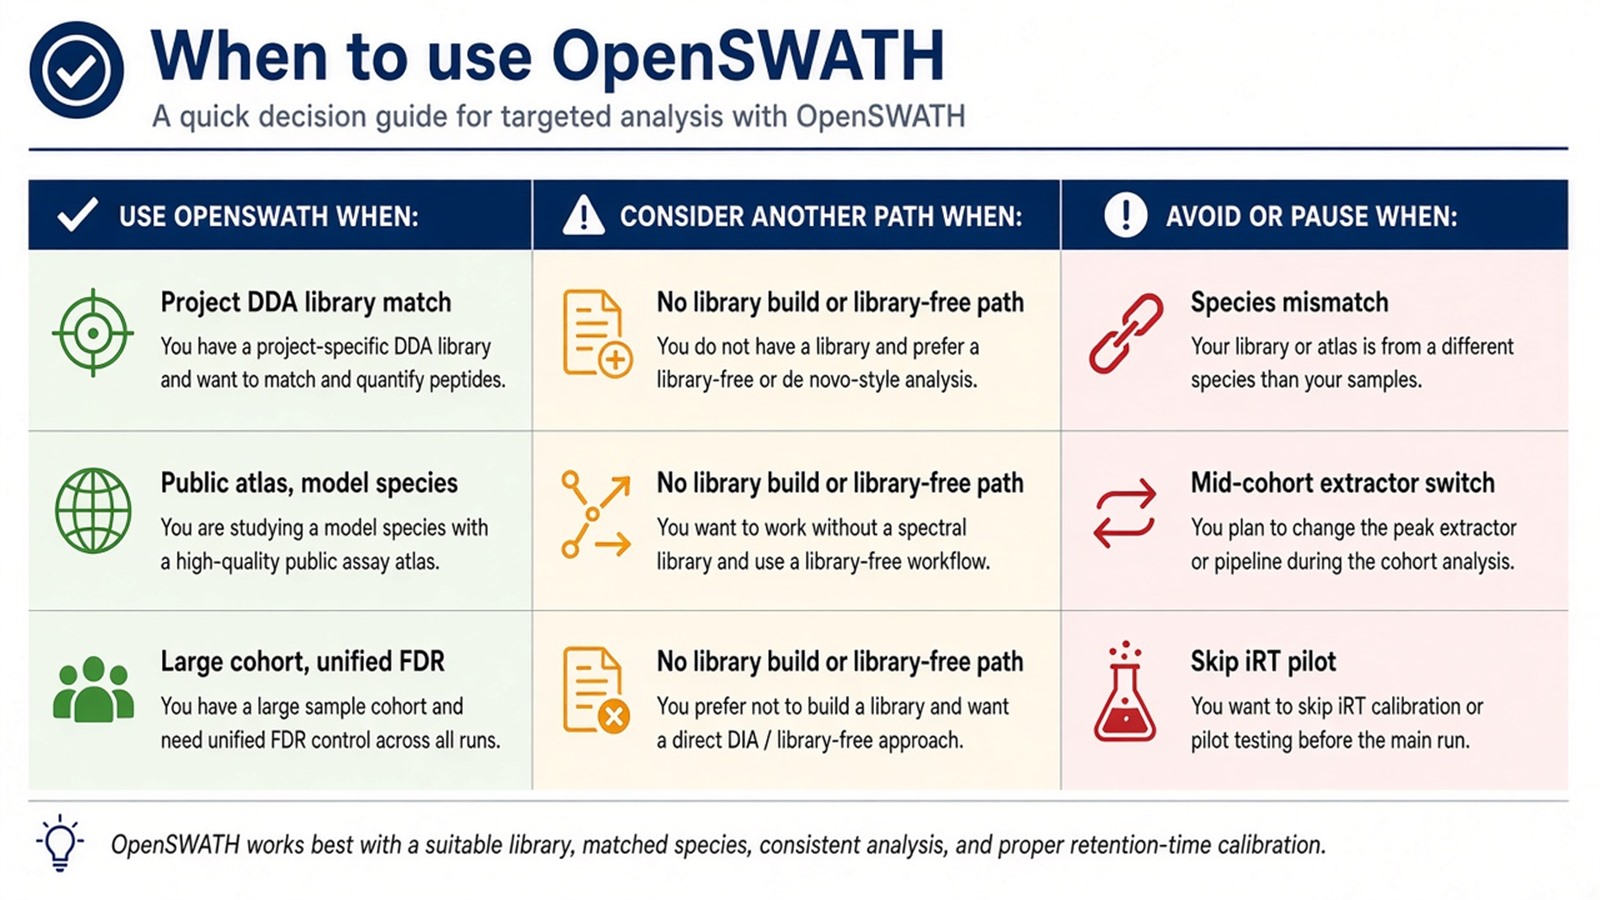
Figure 2. Commit to OpenSWATH when a library-backed SWATH extractor and locked FDR policy fit; library mismatch and mid-study extractor changes need explicit replanning.
Researchers who need route selection across labeling and acquisition can refer to Protein Quantification Method.
Teams with frozen mzML sets, library provenance, and a declared contrast can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for SWATH extraction planning alongside acquisition.
Frequently Asked Questions
1. Is OpenSWATH required for every SWATH-MS project?
No. Library-free DIA extractors and vendor workflows are valid when documented. OpenSWATH fits library-based targeted extraction on mzML inputs.
2. Can OpenSWATH run without a spectral library?
No. Targeted extraction needs transition evidence from a library or equivalent transition list prepared for OpenSWATH formats.
3. Does pyProphet replace biological replicates?
No. FDR controls peptide identification error. Replicate design and contrast testing remain separate.
4. Should missing values always be imputed?
No. Imputation is a declared policy choice. Some contrasts use complete-case rules or report missingness explicitly.
5. Can one OpenSWATH matrix certify a diagnostic panel?
No. The matrix supports predefined relative contrasts. Panel certification needs confirmation designs outside discovery extraction alone.
MtoZ Biolabs can support SWATH projects when sample prep, acquisition plan, library provenance, and intended contrast are documented before extraction starts.
If further evaluation of library build timing, iRT calibration, FDR thresholds, or handoff to targeted confirmation is needed, project details can be submitted for a feasibility review.
Reference
- M.C. Chambers, B. Fischer, J. Burke, D. Agar, D. Mallick, M. Kertesz, S. Tam, D. Niu, J. MacLean, B. Neumann, S. Morris, B. Bieszki, L. Malmstrom, F. Bruderer, R. Aebersold (2012). A cross-platform toolkit for mass spectrometry and proteomics. Nat. Biotechnol., 30, 918-924. https://doi.org/10.1038/nbt.2377
- V. Demichev, C. Messner, S. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- G. Rosenberger, S. Liu, J. Röst, H.L. Ludwig, C. Buil, B. Borchers, R. Aebersold, L. Collins (2017). Statistical control of peptide and protein error rates in large-scale targeted data-independent acquisition analyses. Nat. Commun., 8, 14224. https://doi.org/10.1038/ncomms14224
- H.L. Rost, G. Rosenberger, P. Navarro, L. Gillet, S.M. Miladinovic, O.T. Schubert, W. Wolski, H.L. Collins, B. Malmstrom, L. Malmstrom, R. Aebersold (2014). OpenSWATH enables automated, targeted analysis of data-independent acquisition MS data. Nat. Biotechnol., 32, 219-223. https://doi.org/10.1038/nbt.2841
