



A PRM proteomics data processing workflow turns scheduled high-resolution MS2 files into a peptide or protein matrix for a closed target list. Typical operations are import vendor raw files, load or build precursors and expected fragments, extract fragment chromatograms (XICs), review peak boundaries and interference, select quantifier ions with spectral consistency checks, apply relative normalization or stable isotope ratio calibration when SIS is in scope, track QC injections across batches, then export a matrix for predefined contrasts only (Peterson et al. 2012; MacLean et al. 2010). Processing does not reopen an undefined discovery inventory. Lock document version, mass accuracy windows, and integration rules before group statistics. Prefer manual peak review when matrices are complex; automate only after pilot QC passes.
Researchers who already have PRM raw files, a closed peptide panel, and defined groups can also review the MtoZ Biolabs Parallel Reaction Monitoring (PRM) Service and Targeted Proteomics Service for project-specific processing and assay planning.
End-to-End PRM Data Processing Steps
PRM acquisition already fixed the inclusion list. Processing must stay aligned with that schedule and the declared relative or absolute claim.
Step |
Operation |
Output to document |
|---|---|---|
1 |
Import raw PRM files and run metadata |
File list tied to sample IDs |
2 |
Load closed target list (sequences, charges, modifications) |
Panel version frozen |
3 |
Map retention times and isolation windows from acquisition |
Schedule audit trail |
4 |
Extract fragment XICs from stored HR MS2 |
Peptide-level traces |
5 |
Review peaks; adjust integration when interference appears |
Manual or ruled boundaries |
6 |
Score spectral consistency (for example dot product vs reference) |
Pass or fail per peptide |
7 |
Summarize quantifier fragments to peptide abundance |
Relative areas or SIS ratios |
8 |
Normalize across runs; apply QC pool or bridge rules |
Comparable matrix |
9 |
Roll up to proteins if surrogates are declared |
Protein-level table |
10 |
Export matrix; test only predefined contrasts |
Analysis-ready file |
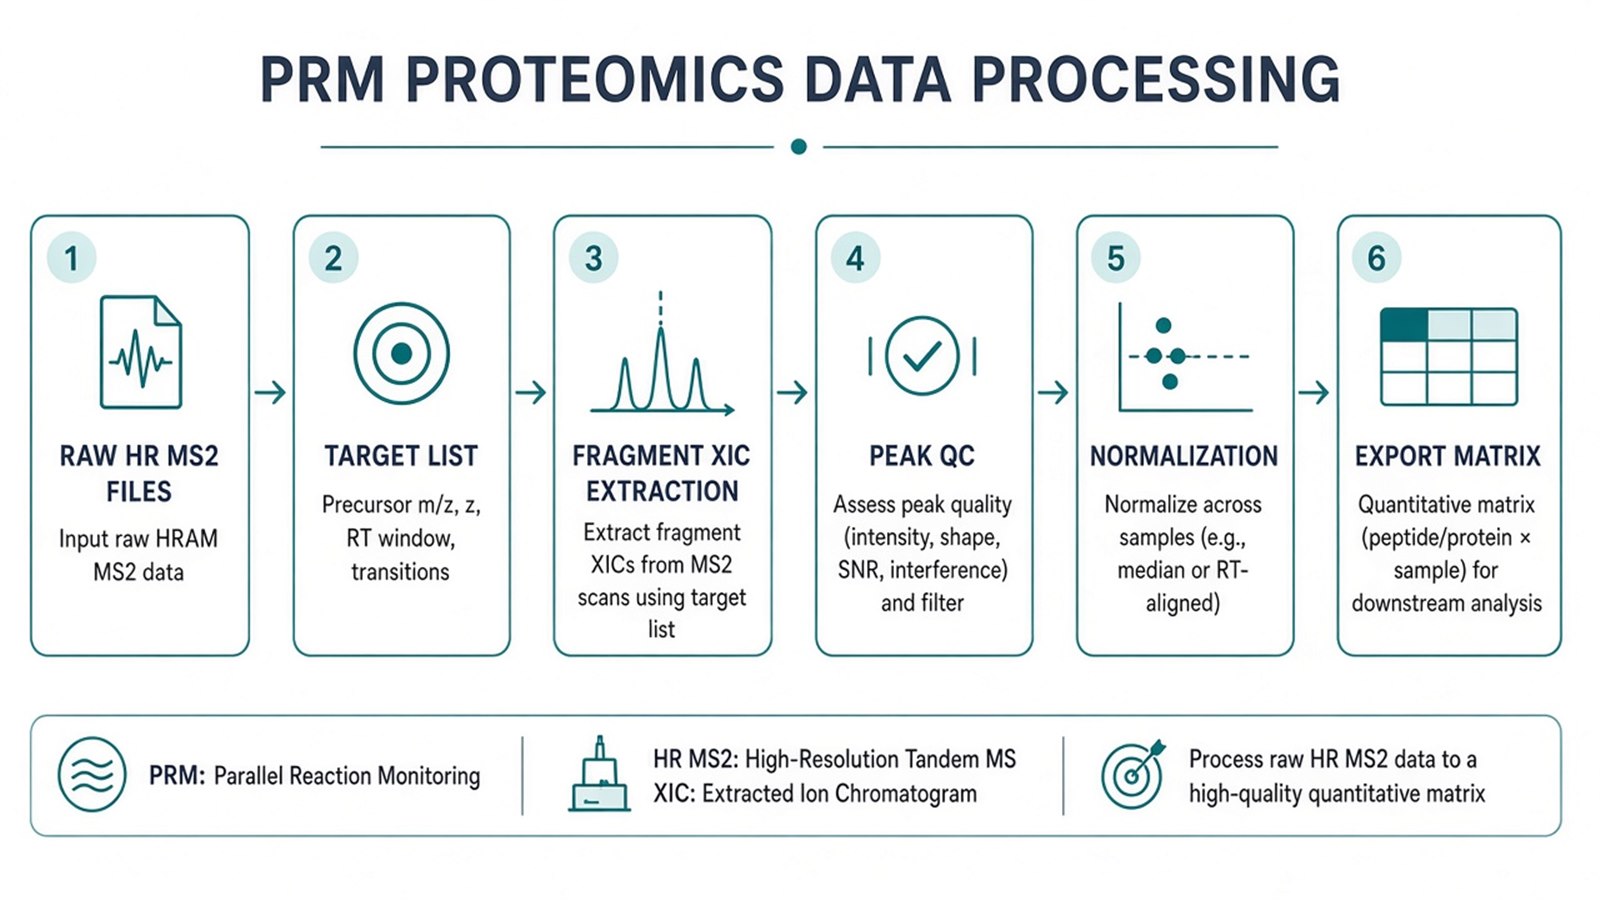
Figure 1. PRM data processing is a closed-panel pipeline: each step should be traceable before group comparisons are interpreted.
Changing integration rules mid cohort splits the matrix; treat that as a new processing version, not a silent rerun.
For acquisition-side workflow, see Parallel Reaction Monitoring (PRM): Principles, Workflow, and Applications. For validation study design, see How to Plan a Targeted Proteomics Validation Study. For generic proteomics statistics after the matrix exists, see How to Analyze Quantitative Proteomics Data.
Software Operations and QC Checkpoints
Open tools such as Skyline are widely used to visualize PRM chromatograms, manage target lists, and export batch tables, but the scientific requirements are tool-agnostic (MacLean et al. 2010). QC should be declared per project rather than copied as universal cutoffs.
QC topic |
What to verify during processing |
Common misread |
|---|---|---|
Peak shape |
Co-elution and tailing near the scheduled RT |
Assuming every integrated peak is on-target |
Spectral match |
Fragment pattern consistency with reference MS2 |
Quantifying with interfered traces |
Replicate spread |
Technical replicate CV on QC pools |
Treating single injections as validation |
SIS behavior |
Stable heavy-to-light ratios when absolute design is active |
Using SIS only for naming, not calibration |
Batch bridges |
Anchor peptides or QC pools across run days |
Normalizing away biological signal by mistake |
Missing traces |
Peptides that fail scheduling or fall below LOD |
Imputing absent peptides as low abundance |
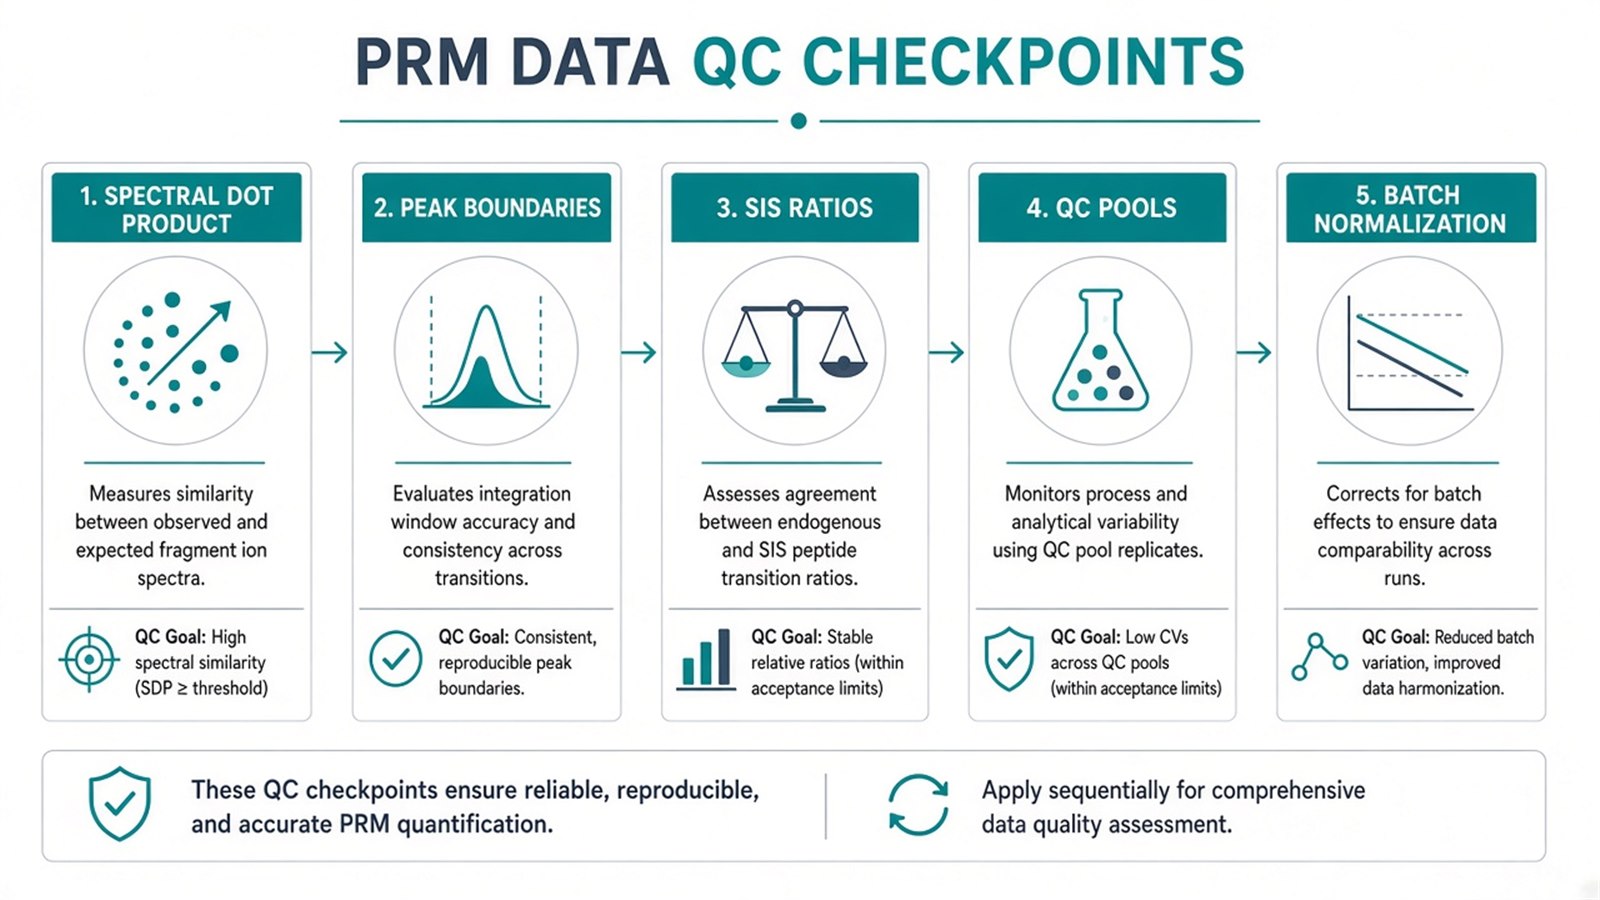
Figure 2. PRM processing QC links chromatographic evidence to the declared quantitative claim before statistics run.
For absolute calibration steps, see Absolute Quantification in Targeted Proteomics and AQUA Proteomics. For detection-oriented context, see Detection of Proteins Using Parallel Reaction Monitoring.
Judgment Criteria: When This PRM Processing Workflow Fits
Situation |
PRM processing workflow fits |
Reassess |
|---|---|---|
Input files |
Scheduled HR MS2 PRM raw data exist |
Files are DDA discovery or DIA windows only |
Target list |
Peptides and charges are closed |
Inventory still expanding weekly |
Claim |
Relative confirmation or SIS-backed amount on the panel |
Whole-proteome rediscovery from PRM files |
QC capacity |
Time for peak review or validated automation rules |
Full automation without pilot review |
Follow-up intent |
Matrix feeds predefined group contrasts |
Exploratory protein listing without design |
Prefer PRM processing when discovery already nominated peptides and high-resolution confirmation traces are required. Prefer MRM pipelines when mature triple-quadrupole transitions are locked and HR MS2 review is not the bottleneck. Prefer DIA or LFQ reanalysis when the question remains open discovery. Prefer AQUA-style designs when concentration units need matrix-matched curves, not only light-to-heavy ratios.
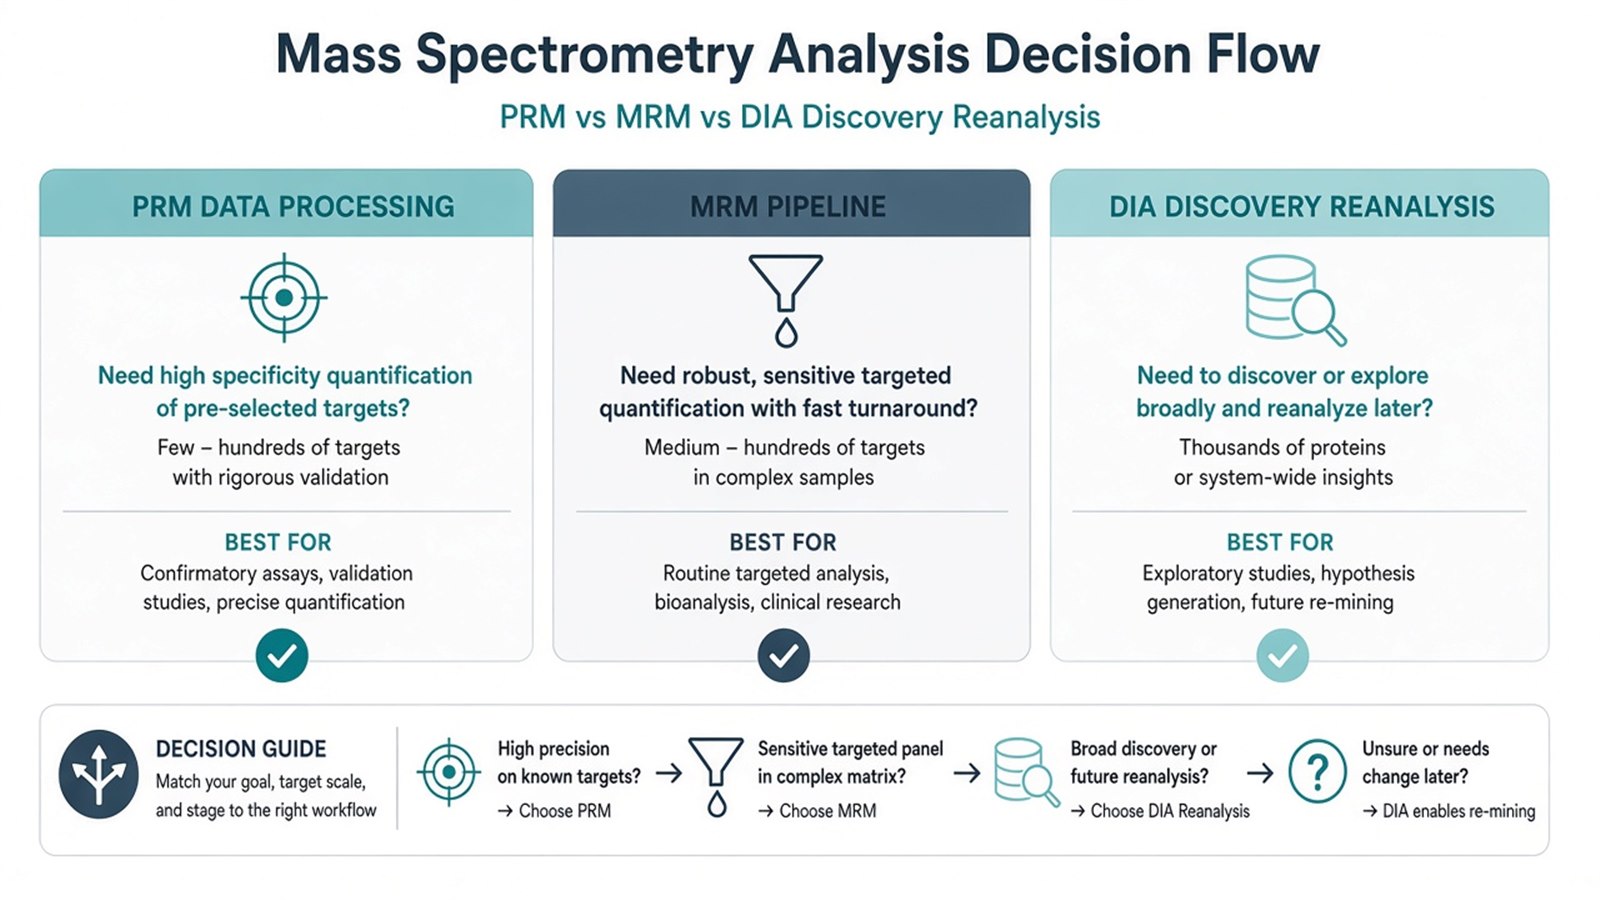
Figure 3. Use PRM data processing for closed-panel HR MS2 files; switch routes when files or claims belong to discovery or mature MRM panels.
For PRM versus MRM processing differences, see PRM vs MRM: Comparative Analysis in Quantitative Proteomics and PRM and MRM in Targeted Proteomics: Advantages and Limitations. For advantages at method level, see Advantages and Disadvantages of Parallel Reaction Monitoring. For DIA-to-PRM handoff, see Application of DIA-PRM Proteomics.
Limits and Application Boundaries
Processing cannot recover peptides that were never scheduled or that failed acquisition QC. Full MS2 storage does not remove co-isolation interference when boundaries are set incorrectly. Relative peak areas are not molar concentrations without declared SIS and calibration logic. Protein roll-up inherits surrogate peptide behavior; inconsistent digestion still breaks inference. Pathway or mechanism language based on a short panel reflects that panel, not whole-proteome proof. Diagnostic cutoffs sit outside ordinary research PRM reporting unless a separately validated assay framework is in place.
Typical applications after a defended processing workflow:
- Biomarker-candidate confirmation matrices from discovery shortlists.
- Pharmacodynamic panels compared across treatment arms on fixed peptides.
- Biopharmaceutical peptide monitoring with documented integration rules.
- Cross-batch bridging studies when QC pools and anchor peptides are planned.
- Absolute peptide amount readouts when SIS and curve QC are part of the same pipeline.
Once target list version, processing rules, and contrast definitions are locked, the project can deliver a traceable PRM quantitative matrix. Researchers can review the MtoZ Biolabs Parallel Reaction Monitoring (PRM) Service for raw-file intake and analysis planning.
Frequently Asked Questions
1. What is the first step in PRM data processing?
Confirm that raw files are scheduled PRM HR MS2 data and that the closed target list matches the acquisition inclusion list before extracting XICs.
2. Is manual peak review always required?
Complex matrices often need review or validated automation rules piloted on QC samples. Blind automation without QC can propagate interference.
3. Can PRM processing software replace study design?
No. Software exports tables. Contrast arms, replicates, and claim type must be fixed before interpreting group differences.
4. How does absolute quantification enter the workflow?
Add SIS peptides, ratio or curve logic, and documented calibration QC. Otherwise the default output remains relative.
5. Should DIA raw files be processed with a PRM pipeline?
Only when the study used a defined targeted extraction on compatible data. Open DIA discovery usually needs DIA extractors first, then PRM confirmation on a shortlist.
Reference
- A.C. Peterson, J.D. Russell, D.J. Bailey, M.S. Westphall, J.J. Coon (2012). Parallel reaction monitoring for high resolution and high mass accuracy quantitative, targeted proteomics. Mol. Cell. Proteomics, 11, 1475-1488. https://doi.org/10.1074/mcp.O112.020131
- B. MacLean, D.M. Tomazela, N. Shulman, et al. (2010). Skyline: an open source document editor for creating and analyzing targeted proteomics experiments. Bioinformatics, 26, 966-968. https://doi.org/10.1093/bioinformatics/btq054
