



Label-free quantification (LFQ) estimates relative protein abundance from independent LC-MS/MS runs without isotopic or chemical tags. Shared advantages are simpler sample chemistry, flexible enrollment, and compatibility with matrices that resist clean labeling. Shared disadvantages are chromatographic drift, missing values under DDA, dependence on alignment and normalization, and relative-only intensities unless matched standards are added (Cox et al. 2014). Tools such as MaxQuant for DDA peak-area LFQ and DIA-NN for unlabeled DIA extract those relative matrices under FDR and QC control (Demichev et al. 2020). Prefer LFQ for open-enrollment discovery; keep TMT when a frozen plex fits; keep PRM or AQUA when a closed amount panel is required.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service and Deep DIA Proteomics Service for project-specific feasibility and analysis planning.
Advantages and Disadvantages at a Glance
Topic |
Advantage when controls hold |
Matching disadvantage |
|---|---|---|
Chemistry |
No isotopic or isobaric labeling step |
No same-run multiplex damper on injection drift |
Cohort design |
Flexible independent enrollment |
Every added run carries chromatography risk |
Sample types |
Broad matrix compatibility when prep is matched |
Detergent and digestion drift still bias results |
Throughput planning |
Not capped by a fixed TMT channel count |
Instrument time scales with sample number |
Data reuse |
Independent runs can be reprocessed under new filters |
Batch structure remains if prep or columns change |
Quantitative claim |
Relative same-protein discovery at scale |
Not absolute concentration without standards |
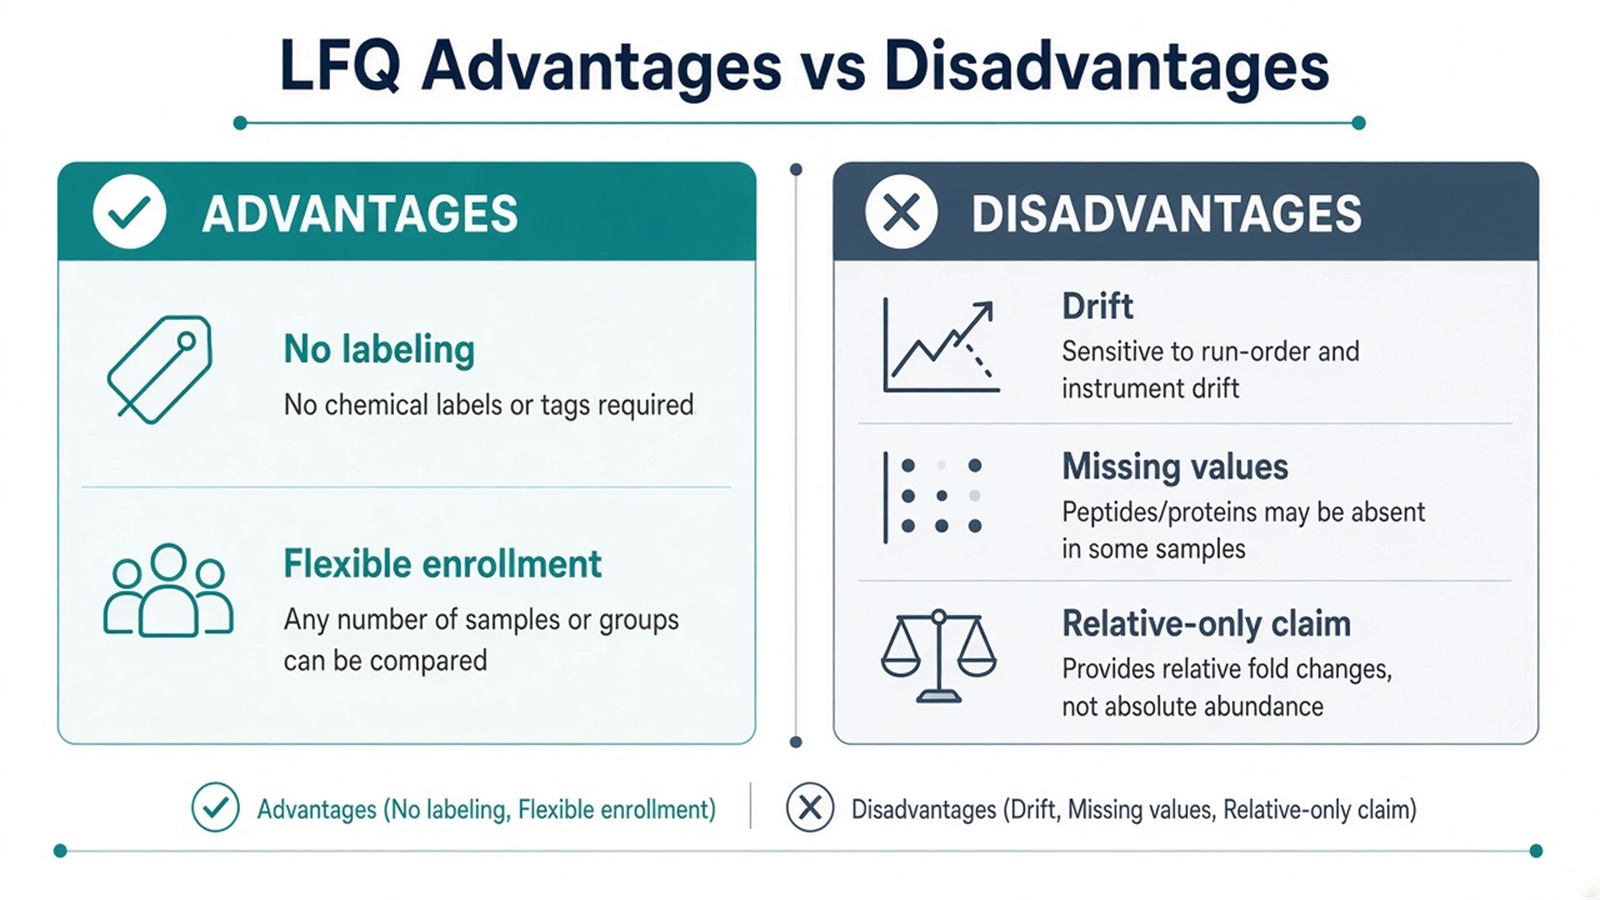
Figure 1. LFQ advantages and disadvantages arise together: unlabeled flexibility raises batch and missing-value risk that tools can only partly control.
Calling LFQ unlimited or highly accurate without stating acquisition mode, run order, and the relative claim overstates method class alone.
Within LFQ, MS1 peak-area methods such as MaxLFQ, spectral counting, and unlabeled DIA fragment quantification trade precision and completeness differently. For variant-level advantage lists, see Label-Free Protein Quantification Methods: Advantages and Limitations. For strategy mapping, see Label-Free Quantification Methods: Mass Spectrometry-Based Protein Quantification Strategies.
Applications That Match These Trade-Offs
Application |
Why LFQ often fits |
Limit to keep visible |
|---|---|---|
Disease or treatment screens |
Independent samples; enrollment may expand |
Relative candidates are not diagnostic cutoffs |
Drug-response proteomes |
Flexible multi-arm unlabeled injections |
Prep must stay matched across arms |
Clinical or preclinical biofluids |
Late arrivals do not need a frozen plex |
Chromatography QC becomes part of the method |
Non-model or hard-to-label matrices |
No commercial label dependence |
Database and digestion quality still limit depth |
Discovery before targeting |
Open inventory for later PRM or AQUA |
Absolute amount needs a separate standard design |
For biomedical LFQ use maps, see A Complete Guide to Label-Free Quantitative Proteomics (LFQ) in Biomedical Research and Applications of LC-MS/MS in Label-Free Quantitative Proteomics.
Tools for Label-Free Quantification
Tools sit downstream of prep and acquisition. They summarize relative matrices; they do not repair unmatched digests.
Tool or class |
Typical LFQ role |
Main limit |
|---|---|---|
MaxQuant (MaxLFQ) |
DDA peak-area LFQ after peptide identification |
Stochastic missingness across runs |
Proteome Discoverer LFQ modules |
Vendor-centered DDA LFQ processing |
Still inherits run-order and prep batch effects |
DIA-NN / Spectronaut |
Unlabeled DIA fragment quantification with FDR control |
Window interference and library or library-free burden |
MSstats and related stats layers |
Normalization and differential testing on exported matrices |
Cannot invent peptides absent from the search |
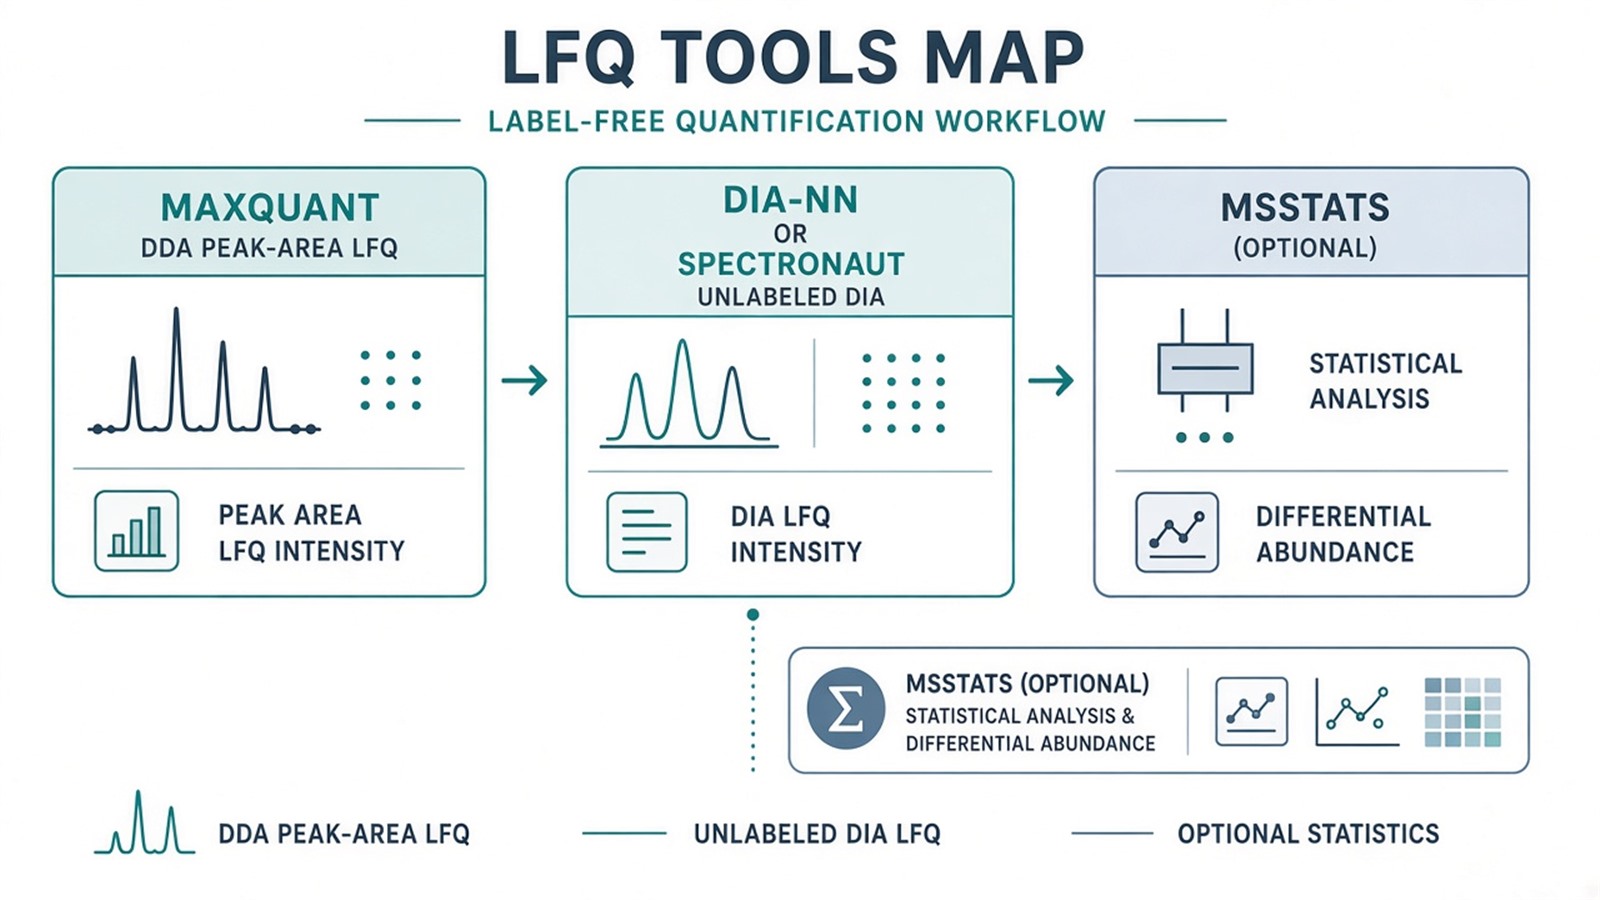
Figure 2. Choose LFQ tools from the acquisition class: MaxQuant-centered DDA peak areas versus DIA-NN-centered fragment chromatograms.
For tool pairing detail, see Essential Analysis Tools for Label-Free Proteomics: A Comprehensive Review of MaxQuant and DIA-NN. For DDA versus DIA inside LFQ, see DIA vs. DDA in Label-Free Quantitative Proteomics: A Comparative Analysis. For normalization, see How to Normalize Data in Label-Free Quantitative Proteomics?.
Judgment Criteria: When LFQ Advantages Hold
Study need |
LFQ often fits |
Reassess before committing |
|---|---|---|
Claim |
Relative same-protein discovery |
Absolute concentration or diagnostic cutoff |
Enrollment |
Independent injections; samples may arrive later |
All contrasts must share one TMT plex |
Chemistry |
Labeling impractical, costly, or risky |
Clean amine labeling and closed plex preferred |
Tooling |
MaxQuant or DIA-NN path matches acquisition |
Acquisition undecided; software chosen first |
Follow-up |
Discovery list may later move to PRM or AQUA |
Closed shortlist already needs amount units now |
Prefer MaxQuant-centered DDA-LFQ when identification-centric peak areas fit. Prefer DIA-NN when unlabeled DIA completeness is the priority. Prefer TMT when same-run multiplex ratios fit a frozen kit. Prefer PRM, MRM, or AQUA when targets are closed or amount units are required.
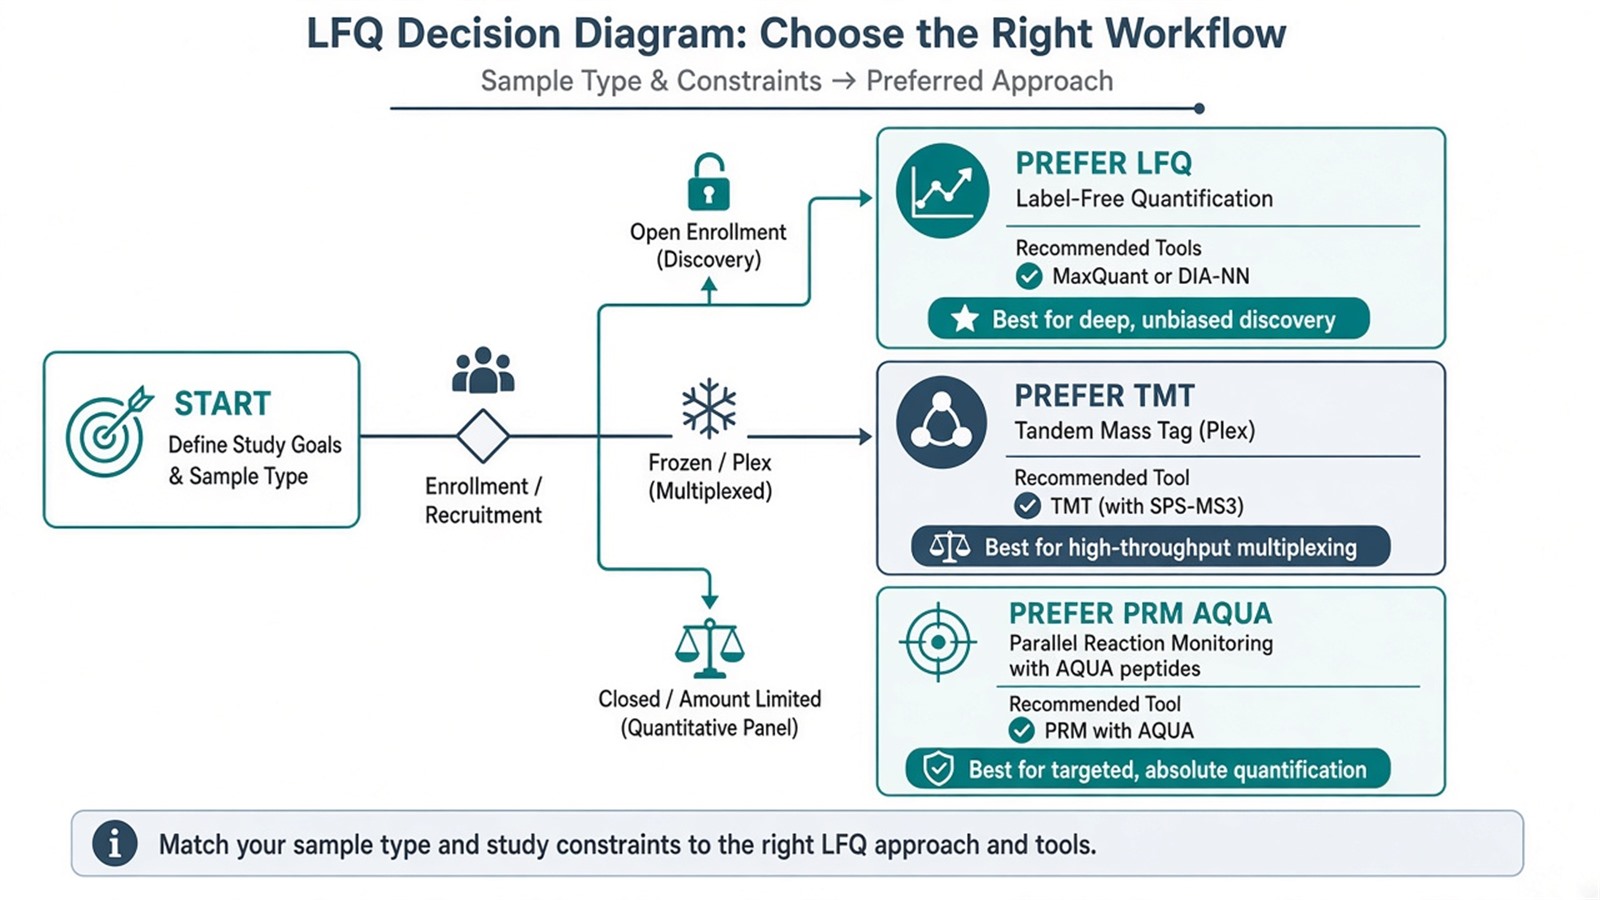
Figure 3. Use LFQ when unlabeled relative discovery and matching tools fit; change family when plex labeling or absolute panels dominate.
For labeling versus unlabeled selection, see TMT vs Label Free Quantitative Proteomics and Comparing LFQ and Isobaric Labeling Strategies in Proteomics Quantification. For operational workflow, see What Is Label-Free Analysis? LFQ Principles, Workflow, Advantages, and Limitations.
Limits and Application Boundaries
No LFQ advantage removes batch effects without design. Tool speed or neural-network scoring does not override poor digestion or confounded run order. Spectral counting is not interchangeable with MaxLFQ for subtle fold changes. Ordinary intensities remain relative unless matched standards and calibration are added. Pathway enrichment shows overrepresentation relative to the quantified background; it does not prove pathway activity. Diagnostic cutoffs sit outside ordinary research LFQ reporting unless a separately validated assay framework is in place.
Once advantages, application scope, and tool path are aligned, the project can be scoped as an LFQ or unlabeled DIA study. Researchers can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for sample evaluation and workflow planning.
Frequently Asked Questions
1. What are the main advantages of LFQ?
No labeling chemistry, flexible enrollment across independent runs, and broad matrix compatibility when prep is matched.
2. What are the main disadvantages?
Run-to-run drift, missing values especially in DDA, dependence on alignment and normalization, and relative-only claims by default.
3. Which tools should I use?
Match the tool to acquisition: MaxQuant for many DDA peak-area LFQ plans; DIA-NN or Spectronaut for unlabeled DIA; statistics packages only after a coherent matrix exists.
4. Is LFQ better than TMT for every cohort?
No. LFQ fits open enrollment. TMT fits frozen multiplex comparison when amine chemistry holds.
5. Can LFQ tools report absolute protein concentration?
Not by themselves. Absolute amount needs matched standards and calibration on a closed panel.
Reference
- J. Cox, M.Y. Hein, C.A. Luber, et al. (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031591
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
