



Label-free quantification (LFQ) in mass spectrometry compares peptide signals across independently acquired liquid chromatography-tandem mass spectrometry (LC-MS/MS) runs. The comparison is reconstructed after acquisition by alignment, normalization, and protein summarization. Practical failures follow from that design. Chromatographic drift and ion suppression change peak intensity without a chemical code that would cancel the change. Stochastic identification leaves missing values that are often intensity-dependent. Run order can become indistinguishable from the biological contrast. Resolutions are experimental and processing controls that keep one coherent analytical plan, not a claim that unlabeled analysis is inherently more accurate than labeling. Ordinary LFQ intensities remain relative values of the same protein inside that plan. They are not molar concentrations.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for project-specific feasibility and analysis planning.
Why Independent LC-MS Runs Create Quantitative Problems
LFQ does not pool chemically coded samples into one injection. Each digest carries its own loading, retention-time, and instrument-response history. Software can align features and correct global scale. It cannot invent a shared chemical reference that was never added.
The working assumption is narrow. Under comparable LC-MS conditions, the recorded signal of a given peptide tracks the relative amount of that same peptide. Sample complexity, ionization competition, and column aging violate comparability even when peptide identity is correct. A title such as label-free quantification mass spectrometry names that unlabeled comparison. It does not name a more accurate detector, an absolute assay, or a method that is immune to run-to-run change.
Researchers can refer to What Is Label-Free Quantification in Proteomics for how precursor peak area becomes a protein-level matrix when the analytical plan stays coherent.
LFQ comparability is created after acquisition; it is not built into a pooled mixture.
Intensity Drift, Ion Suppression, and Chromatographic Instability
Peak area is the usual discovery metric for unlabeled data-dependent acquisition (DDA). Intensity records the ion current that arrived, subject to spray stability, loading, co-eluting peptides, and drift across a sequence. A globally stronger chromatogram can make many proteins appear increased. Abundant co-eluters can suppress a lower-intensity peptide in some samples and not in others. The scientific problem is using that ion current as if it were a sample-coded abundance.
Standardizing extraction, digestion, reconstitution, and on-column load reduces a major source of scale difference. Colorimetric total-protein assays remain useful for load matching. They do not identify which proteins changed. One chromatographic regime should be kept for the contrast: the same column family, gradient, and mobile-phase system. Quality-control (QC) injections can monitor drift. They cannot rescue a design in which all controls were acquired before all treated samples.
Normalization addresses systematic differences such as sample loading or overall analytical response (Cox et al. 2014). Delayed normalization and peptide-ratio summarization can stabilize protein profiles when the same peptides are observed across runs. Normalization does not repair a confounded run order. It does not merge files acquired after a column change or on a different instrument into the original comparison.
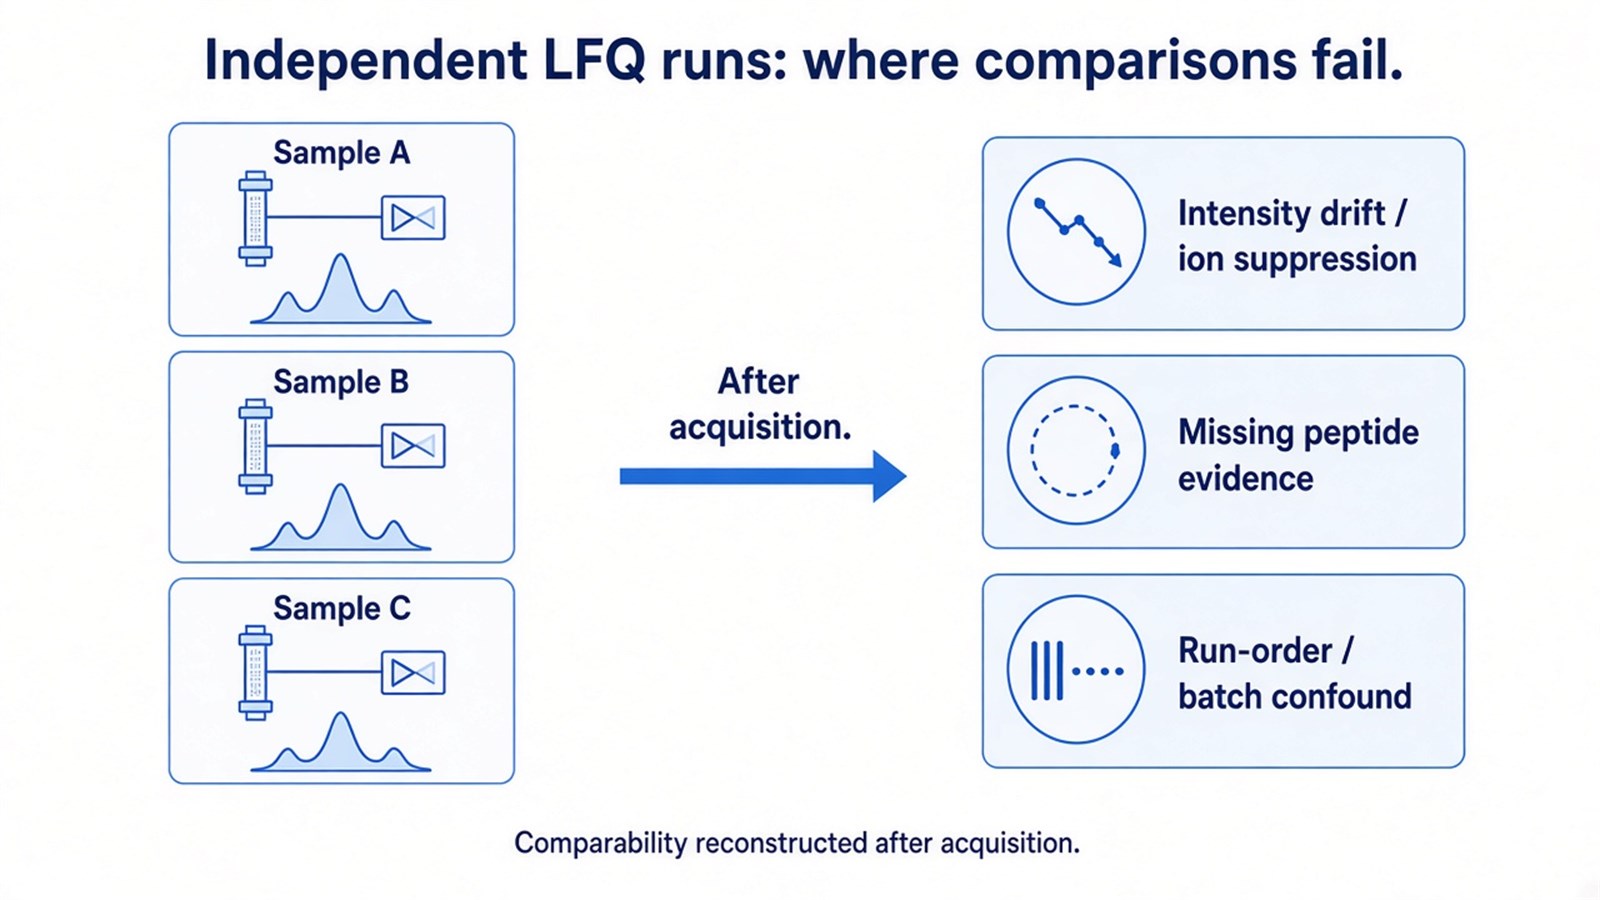
Figure 1. Unlabeled samples remain separate LC-MS runs; intensity drift, missing peptide evidence, and run-order confounding appear before software reconstructs a protein matrix.
Missing Values and Incomplete Peptide Evidence
In unlabeled DDA, the instrument selects precursors in real time. A low-intensity peptide may be identified in one run and missed in another. Missingness then often correlates with abundance, a missing-not-at-random pattern rather than a random gap (Lazar et al. 2016). Treating every gap as protein absence overstates biology. Alignment and match-between-runs transfer can close some gaps when mass and aligned retention time match. Transfer is not the same evidence as a local identification in that file.
Imputation fills a matrix so that a statistical model can run. A left-censored model may be a better match for low-abundance gaps than an assumption of random missingness. Imputation does not recover a peptide that never ionized. The method and its effect on group differences should be disclosed. Filling values across incompatible analytical blocks creates a complete table that is no longer one experiment.
Increasing on-column load or adding fractionation can raise identification counts. Those steps also change the analytical regime and can create a new comparison problem if only some samples receive them. Unlabeled data-independent acquisition (DIA) can improve completeness because fragmentation is scheduled rather than chosen in real time (Gillet et al. 2012). DIA is an acquisition choice, not proof that labels were unused, and fragment interference remains a separate review.
In MtoZ unlabeled discovery offerings, DDA-LFQ is typically reported from MS1 peak-area workflows rather than from spectral counts. Switching the same unlabeled digest to DIA is a separate acquisition decision when completeness, not labeling chemistry, is the limiting failure.
Batch Structure and Run Order
Large unlabeled projects are acquired over hours or days. If all controls occupy the first block and all treated samples occupy the later block, column aging, spray change, and the biological factor occupy the same axis. Batch-correction software cannot recover a fully confounded design. Randomizing group labels across injection order keeps condition and acquisition time from becoming the same variable. Bridging QC samples can show whether a sequence stayed inside one response regime.
A column replacement, instrument change, or long interruption is a new analytical block. Additional unlabeled samples can still be injected when the regime remains compatible. Ordinary normalization does not insert a later digest, acquired after that break, into the original protein matrix. Cross-project tables that were processed months apart should not be presented as one LFQ study after a generic batch adjustment.
Failure mode |
Typical source |
Control that can help |
Control that does not |
|---|---|---|---|
Independent-run intensity shift |
Loading, spray, co-elution, column drift |
Load matching, one LC plan, QC injections |
Reading a globally brighter run as biology |
Missing peptide evidence |
Stochastic DDA sampling at low intensity |
Disclose match-between-runs; review completeness |
Treating every gap as protein absence |
Run-order or batch confound |
Grouped injection order or split processing days |
Randomize groups; use bridging QC |
Merging a new instrument by ordinary normalization |
Identification-quantification split |
IDs and intensities from unlinked tools |
Keep one processing trail |
Using a pathway map as a technical repair |
Identification, Quantification, and Over-read Interpretation
Protein identification, peak integration, and statistical testing should stay in one processing trail: the same database search, the same feature map, and the same protein roll-up. Exporting identifications from one tool and intensities from another, without a shared peptide-to-run map, breaks the link between a spectrum and a reported ratio.
Fragmented software is a traceability problem. It is not solved by an interactive network view. Pathway enrichment, disease-association tables, and multi-omics overlays interpret a differential list. They do not correct ion suppression, missingness, or a confounded run order. A noisy LFQ matrix still yields a pathway figure.
After alignment, normalization, and protein summarization, an LFQ intensity can support a relative statement: protein A is higher or lower in group 1 than in group 2 inside this study. Peptide support, replicate agreement, missingness, and the stated normalization belong next to that statement. Ordinary LFQ intensities should not rank different proteins by copy number, infer a diagnostic cutoff, or transfer a ratio from one instrument to another study as a calibrated quantity.
A corrected LFQ table still supports relative change of one protein inside one study, not a diagnostic cutoff.
When the Resolution Is a Different Quantitative Route
Design controls should be tried first when the endpoint is still relative discovery on independently injected samples. Reassess unlabeled discovery when the cohort cannot stay under one chromatographic plan, when near-complete values for low-abundance proteins are required, or when the claim is an amount rather than a ratio.
Isobaric labeling, such as tandem mass tags (TMT), trades labeling chemistry and channel structure for a same-run comparison. Targeted monitoring follows a short candidate list; it is not a competing discovery scan. Spectral counting can still help with rough ranking of identification-centric DDA files. Protein-level fold changes for downstream statistics should use peak-area LFQ.
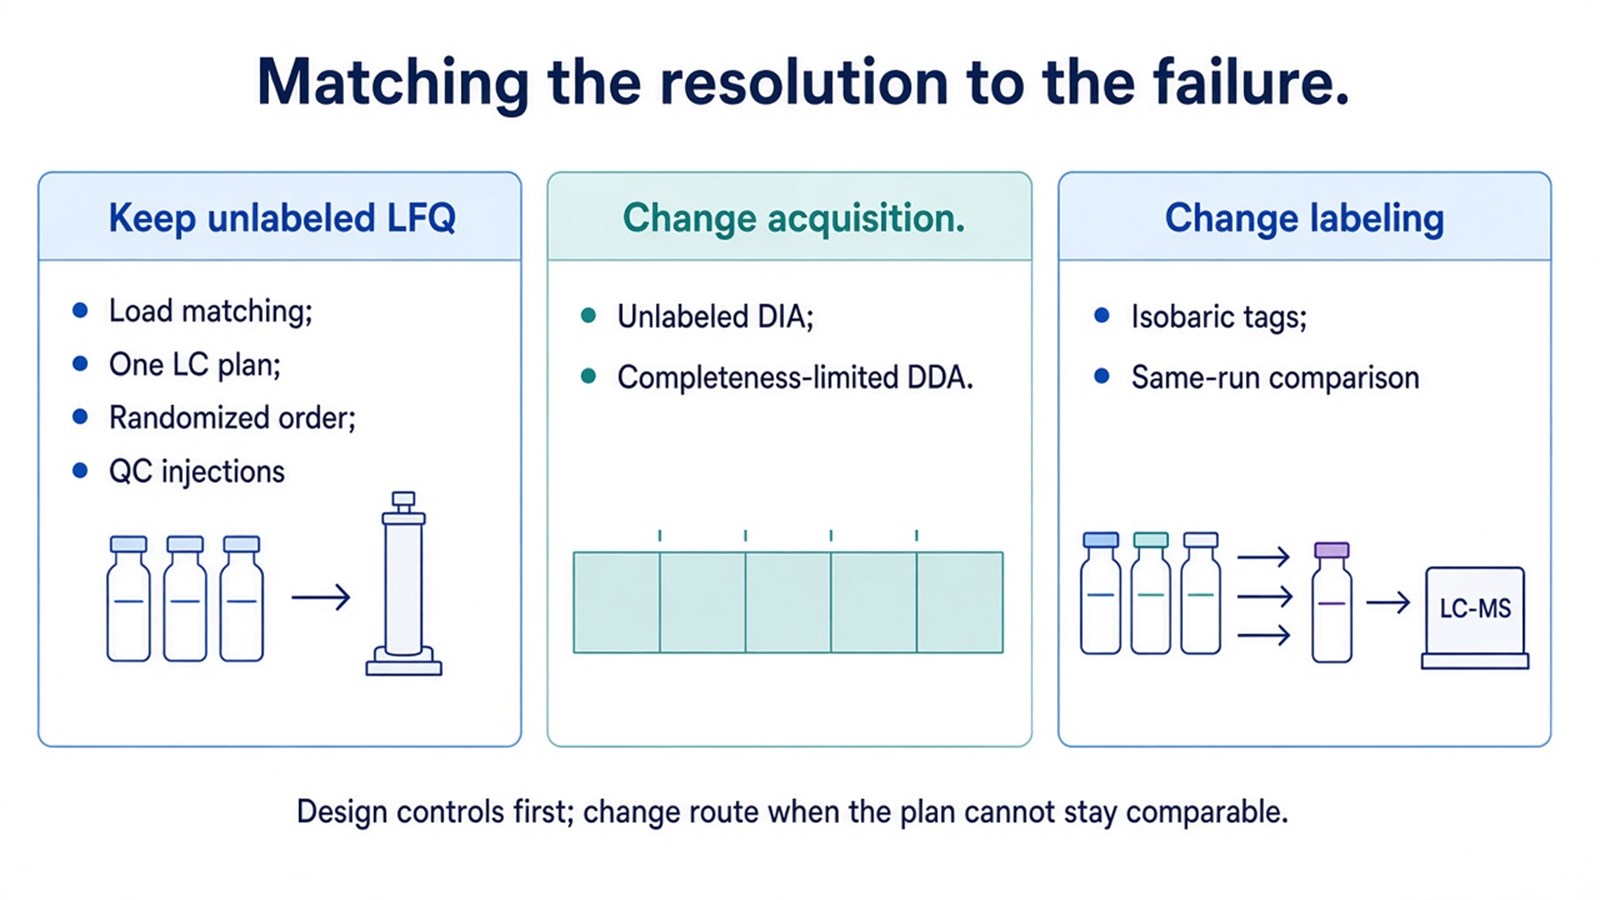
Figure 2. Intensity drift and run-order problems are first addressed inside one unlabeled plan; incomplete DDA matrices and a need for pooled comparison point to different routes.
When sample number, multiplexing, or acquisition strategy makes the choice less straightforward, researchers can refer to Comparing LFQ and Isobaric Labeling Strategies in Proteomics Quantification for a more detailed strategy-selection framework.
Frequently Asked Questions
1. Do missing values mean the protein is absent?
No. In unlabeled DDA, a peptide can fall below the identification threshold in one run and still be present. Match-between-runs and imputation are processing choices. They should be reported. They do not convert a gap into proof of absence or presence.
2. Can batch correction merge two instruments into one LFQ study?
Not as a default. Different instruments, columns, or long interruptions create a new analytical block. Randomization and bridging QC protect a sequence that was planned as one block. They do not license a retrospective merge of unrelated acquisitions.
3. Does higher-resolution mass spectrometry remove ion suppression?
No. Higher resolution can separate close precursors and improve identification. Co-eluting peptides can still compete for charge in electrospray. Chromatography, load, and sample complexity remain part of the intensity problem.
4. Can optimized software turn LFQ intensities into absolute protein amounts?
No. Normalization and peak integration improve the relative comparison inside one plan. Absolute or copy-number claims need spike-in standards, a calibration model, or a targeted quantitative assay. Mass spectrometry-based label-free quantitative proteomics, as used in ordinary discovery, remains a relative method.
Once the comparison design, unlabeled sample set, and expected protein-level readout are defined, residual LFQ risks can be reviewed as part of project planning. Researchers can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for project-specific sample evaluation, feasibility assessment, and workflow planning.
