



To perform label-free quantitative proteomics by mass spectrometry, freeze contrast arms and the relative claim, match lysis digestion and protein load across samples, inject each digest as an independent LC-MS/MS run, then branch acquisition to DDA for MS1 peak-area LFQ (for example MaxLFQ) or to windowed DIA for fragment peak-group quantification under FDR control (Cox et al. 2014; Demichev et al. 2020). Identify peptides from fragment evidence, extract intensities with one declared software route, align retention times, normalize across runs with QC pools, declare missing-value rules, and test only predefined group contrasts. Do not mix DDA-LFQ tables with DIA fragment tables without a bridging design. Reserve aliquots for PRM or AQUA if confirmation is planned.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service and Deep DIA Proteomics Service for project-specific feasibility and workflow planning.
Step-by-Step LFQ Workflow on Mass Spectrometry
Step |
Operation |
Record in methods |
|---|---|---|
1 |
Define groups, replicates, and relative claim |
Contrast table frozen |
2 |
Extract and digest with matched recipe across arms |
Lysis and enzyme protocol |
3 |
Assay protein and load by mass into digestion |
Load QC values |
4 |
Clean peptides for LC (for example SPE) |
Detergent and salt control |
5 |
Lock LC gradient and injection amount |
Gradient ID per cohort |
6 |
Acquire DDA or DIA on each sample separately |
Acquisition mode declared |
7 |
Search or extract peptides under FDR control |
Software version locked |
8 |
Summarize intensities to protein level |
MaxLFQ, area, or DIA roll-up |
9 |
Normalize and map missing values |
QC pool or bridge rules |
10 |
Test predefined contrasts only |
Stats on exported matrix |
- Design the study before scaling injections. Label-free runs inherit batch structure; ad hoc group changes mid project break comparability.
- Prepare samples with the same extraction and digestion rules for every contrast arm (Wisniewski et al. 2009).
- Run LC-MS/MS with interleaved QC and balanced run order when possible.
- Process data with one toolchain matched to acquisition: MaxQuant-centered paths for typical DDA-LFQ; DIA-NN or equivalent for unlabeled DIA.
- Export a protein-by-sample matrix, review missingness maps, then apply statistics.
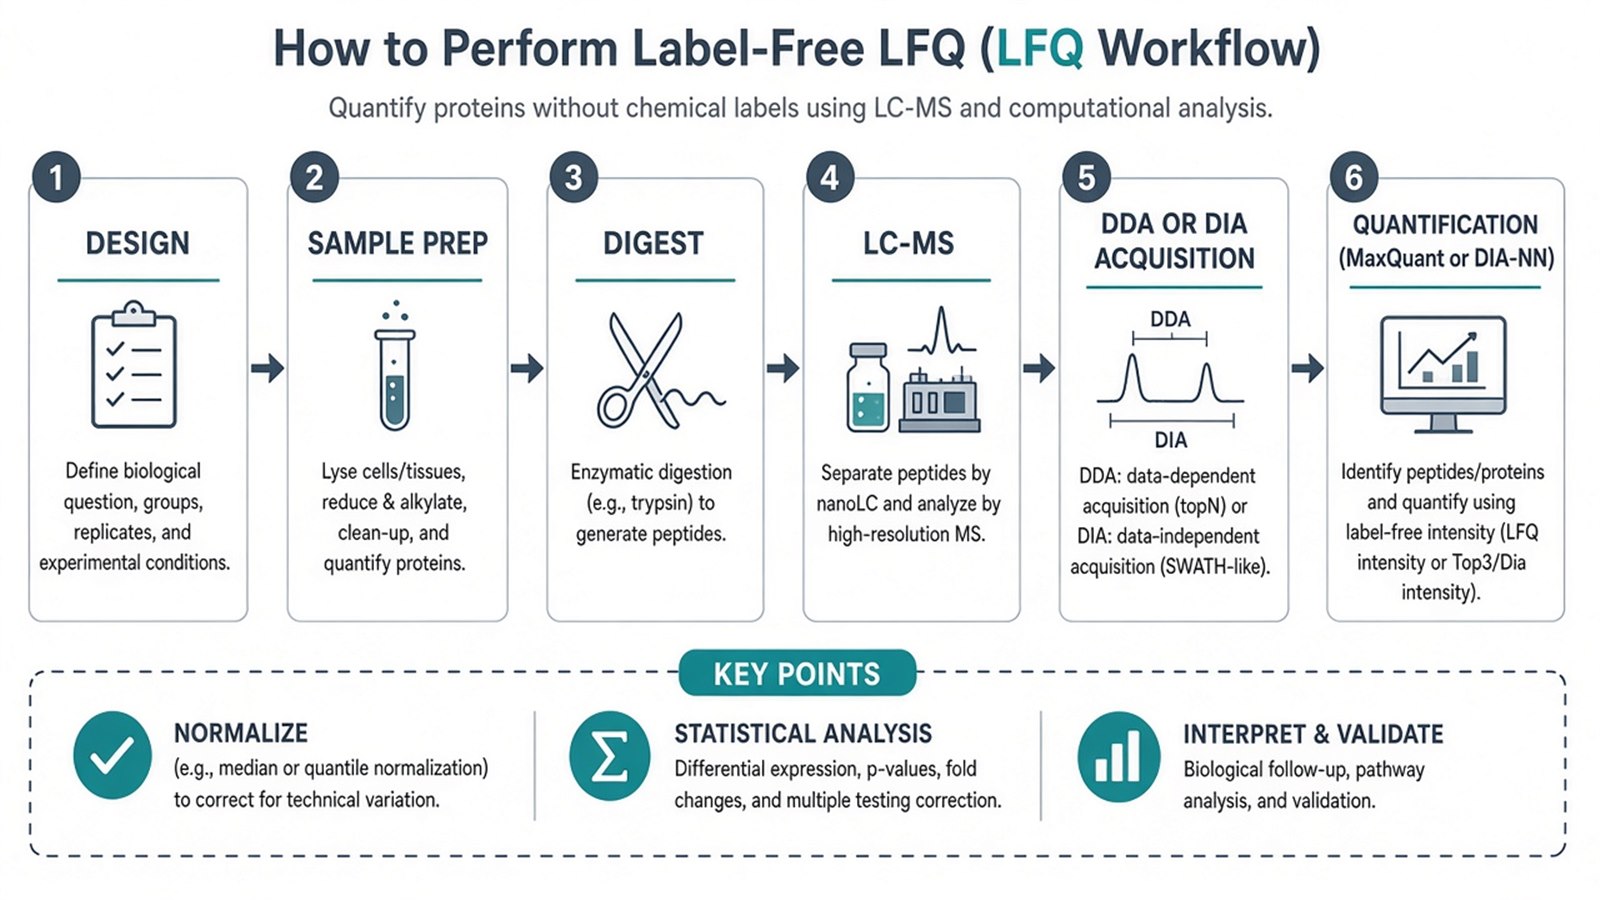
Figure 1. Label-free LFQ on mass spectrometry is independent injections plus aligned quantification, not a single pooled labeled run.
Spectral counting alone is a weak default for subtle fold changes; MS1 peak-area LFQ or DIA fragment quantification is usually preferred when instrument stability allows.
For extended workflow commentary, see What Is Label-Free Analysis? LFQ Principles, Workflow, Advantages, and Limitations. For prep gates, see Precise Quantitative: Label-free Protein Analysis.
DDA-LFQ Versus Unlabeled DIA in the Same Project
Both routes omit chemical tags. The operational fork is acquisition and software, not sample labeling.
Element |
DDA-LFQ (typical) |
Unlabeled DIA / SWATH-style |
|---|---|---|
MS trigger |
Stochastic MS2 on top precursors |
Scheduled windows |
Quant signal |
MS1 peak areas (MaxLFQ) |
Fragment peak groups |
Missingness |
Stochastic across runs |
Often lower for scheduled peptides |
Software examples |
MaxQuant, Proteome Discoverer LFQ |
DIA-NN, Spectronaut |
Main risk |
Run-order drift |
Library or extractor mismatch |
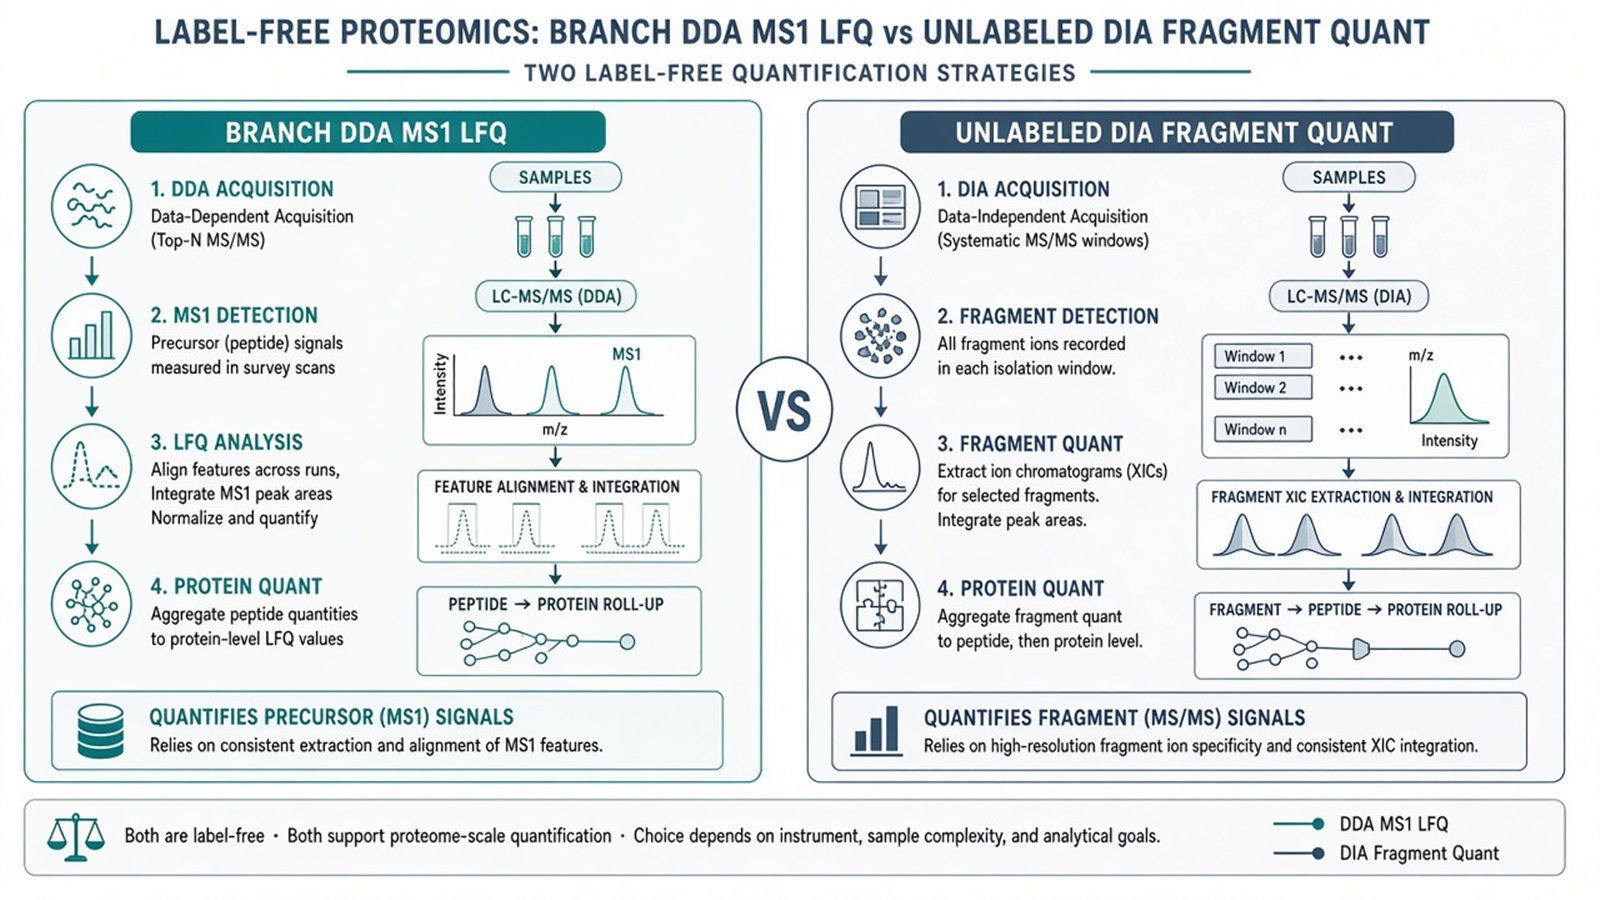
Figure 2. Choose DDA-LFQ or unlabeled DIA before scaling the cohort; switching mid study splits the matrix.
For comparative detail, see DIA vs. DDA in Label-Free Quantitative Proteomics: A Comparative Analysis. For tools, see Essential Analysis Tools for Label-Free Proteomics: A Comprehensive Review of MaxQuant and DIA-NN. For normalization, see How to Normalize Data in Label-Free Quantitative Proteomics?.
Judgment Criteria: When Label-Free MS Quantification Fits
Study need |
Label-free LFQ or DIA often fits |
Reassess |
|---|---|---|
Claim |
Relative same-protein discovery |
Absolute concentration or diagnostic cutoff |
Enrollment |
Independent samples may arrive over time |
All arms must share one TMT plex |
Chemistry |
Labeling impractical |
Clean isobaric tagging preferred |
Acquisition |
DDA-LFQ or unlabeled DIA declared |
Mode undecided while batches accumulate |
Follow-up |
Open list for later PRM or AQUA |
Closed panel needs amount units now |
Prefer DDA-LFQ when MS1 peak-area workflows and MaxQuant-style processing fit matched prep. Prefer unlabeled DIA when windowed completeness and extractor QC match the cohort. Prefer TMT when same-run multiplex ratios fit a frozen kit. Prefer PRM, MRM, or AQUA when targets are closed or amount units are required.
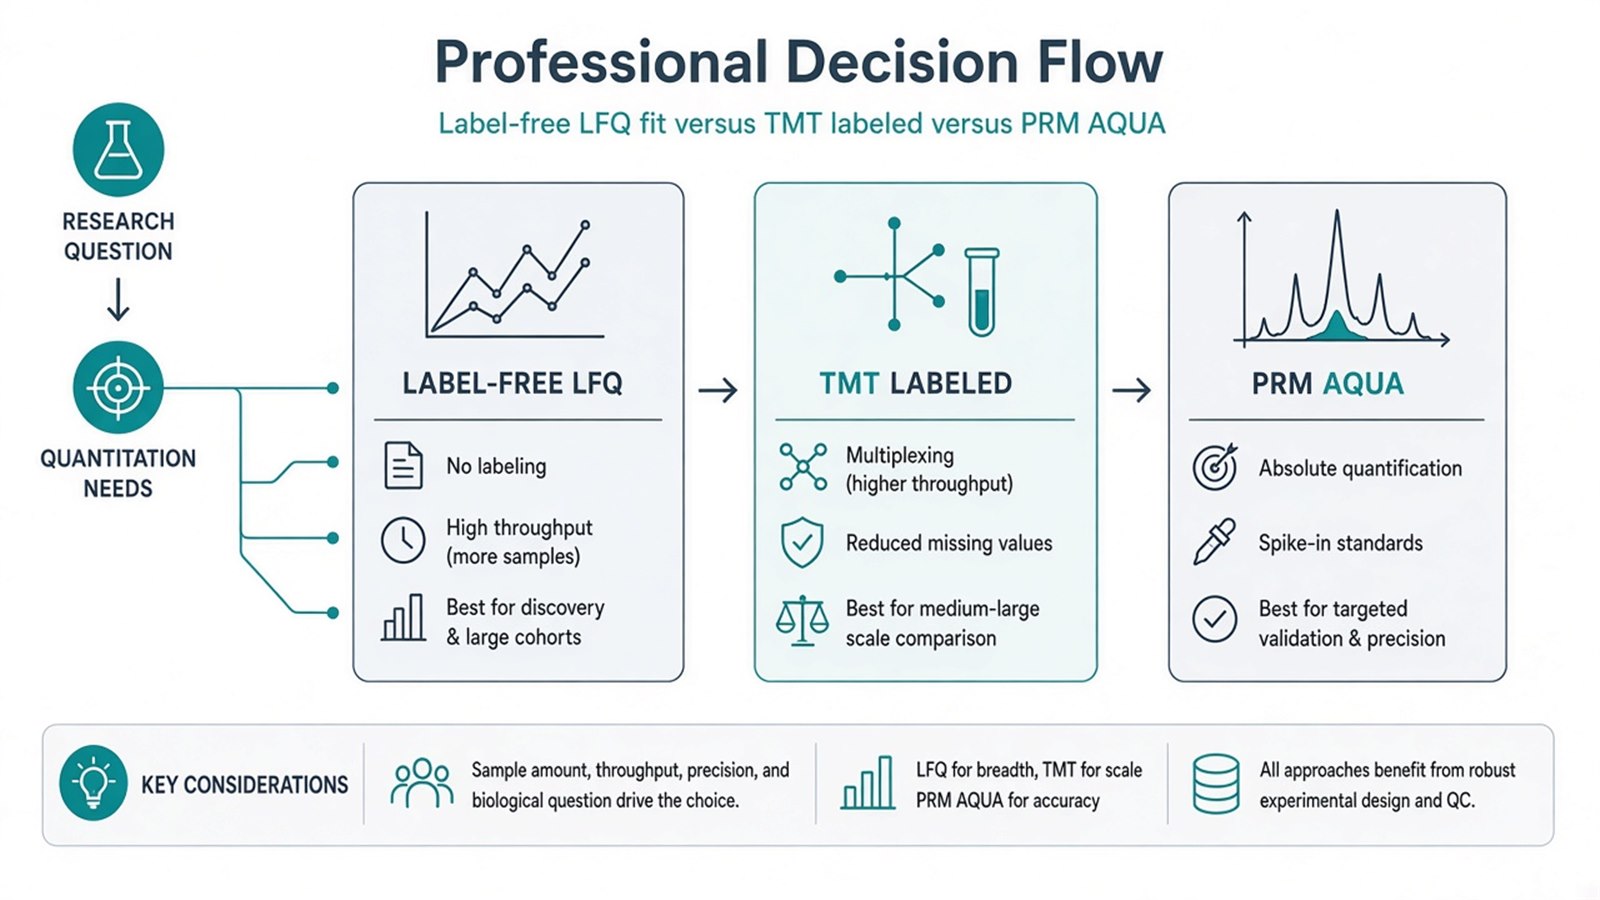
Figure 3. Perform label-free MS quantification when unlabeled relative discovery fits; change family when multiplex labeling or absolute panels dominate.
For strategy maps, see Label-Free Quantification Methods: Mass Spectrometry-Based Protein Quantification Strategies and Differences of Labeled and Label-free Quantitative Proteomics. For advantage trade-offs, see Label-Free Quantification: Advantages, Applications, and Tools.
Limits and Application Boundaries
Label-free mass spectrometry quantification does not remove batch effects without design. Instrument stability helps but does not replace matched prep. Missing values remain common in DDA-LFQ. DIA completeness is not accuracy. Ordinary intensities stay relative unless matched standards and calibration are added. Pathway enrichment shows overrepresentation relative to the quantified background; it does not prove pathway activity. Diagnostic cutoffs sit outside ordinary research LFQ reporting unless separately validated.
Typical applications when the workflow is defended:
- Treatment or disease screens with flexible unlabeled enrollment.
- Biofluid or tissue cohorts where labeling is costly or risky.
- Discovery lists nominated for later PRM or MRM confirmation.
- Multi-batch studies with QC pools and documented normalization.
- Hard-to-label matrices after consistent extraction and digestion rules.
Once acquisition mode, software version, and contrast definitions are locked, the project can be scoped as label-free quantitative proteomics. Researchers can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for sample evaluation and workflow planning.
Frequently Asked Questions
1. How many LC-MS/MS runs does label-free LFQ need?
At least biological replicates per group, plus QC injections. Every sample is usually a separate unlabeled run.
2. Can I compare MaxQuant LFQ with DIA-NN tables directly?
Only with an explicit bridging design. DDA MS1 and DIA fragment matrices are not interchangeable by default.
3. Is label-free quantification the same as spectral counting?
Spectral counting is one legacy approach. MS1 peak-area LFQ or DIA fragment quantification is usually preferred for relative fold changes.
4. When should I switch from LFQ to TMT mid project?
Avoid switching mid contrast. If multiplex labeling fits better, plan a new cohort with frozen plex design rather than mixing labeled and unlabeled arms naively.
5. Can this workflow report absolute protein amount?
Not by default. Add targeted SIS assays and calibration on a closed panel for amount units.
Reference
- J. Cox, M.Y. Hein, C.A. Luber, et al. (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031591
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
- J.R. Wisniewski, A. Zougman, N. Nagaraj, M. Mann (2009). Universal sample preparation method for proteome analysis. Nat. Methods, 6, 359-362. https://doi.org/10.1038/nmeth.1322
