



Label-free quantification (LFQ) reproducibility problems usually appear as unstable peptide evidence for the same predefined contrast, not as identical raw intensities on every protein across separate injections (Cox et al. 2014). Unlabeled cohorts carry independent chromatography and instrument history, so batch structure, prep drift, and pipeline changes can mimic biology when contrasts are not frozen. The guide below maps common failure signatures to likely layers, response actions, and project fit. It is not a repeat of full LFQ definitions, not a software tutorial, and not a promise that every low-abundance protein will replicate in every run.
Technical replicates and pooled QC samples answer different questions. QC monitors system drift. Biological replicates test the contrast. Mixing those roles in statistics confounds reproducibility review (Lazar et al. 2016).
In MtoZ Biolabs offerings, LFQ reproducibility recovery is commonly planned by tracing batch flags to prep, acquisition, or processing layers before contrasts are retested.
Integrated quality framing appears in How to Improve Data Quality and Reproducibility in Label-Free Proteomics?. Tool layer context appears in Tools for Label-free Peptide Quantification.
Where Reproducibility Breaks in Label-Free Cohorts
Four layers dominate LFQ reproducibility failures.
Design and run order confound treatment with injection day or column batch.
Sample prep splits yield, digestion, or cleanup recovery across arms.
Acquisition drift changes retention time, sensitivity, or data-dependent acquisition (DDA) sampling across the cohort block.
Processing swaps search versions, normalization scope, or missing-value rules mid study.
Reproducibility recovery starts by naming which layer produced the signature, not by retuning statistics on a confounded matrix.
Principle language appears in What Is Label-Free Analysis?.
Failure Signatures and Likely Root Layers
Use QC plots and metadata together.
Principal component separation that tracks run order or prep batch points to design or prep layers, not always to biology.
High technical replicate dispersion with stable QC pools points to sample prep or load mismatch across arms.
Rising missing values on low-abundance proteins late in a sequence often track DDA stochasticity or column aging.
Sudden protein count shifts after a software update point to processing layer changes.
Global intensity shifts without rank changes may be normalization scope problems instead of prep failure.
Document the signature before changing methods. Multiple layers can co-occur.
Design and Run-Order Responses to Batch Confounding
When injection day tracks treatment, reproducibility fixes are design fixes.
Interleave biological groups across the acquisition calendar when cohort size allows.
Record prep batch, operator, and column identity in the project table. Investigate metadata before dropping replicates.
Add pooled QC injections on a schedule separate from biological contrast arms. Use QC to monitor drift, not as substitute biological replicates.
Freeze contrast labels before differential testing. Relabeling arms after acquisition invalidates reproducibility claims.
Enrollment planning appears in Exploring Quantitative Analysis in Proteomics.
Prep and Acquisition Responses to Technical Drift
When prep or instrument layers drive instability, block changes and repeat pilots.
Return to one declared lysis, digestion, and cleanup route across arms. Split prep batches by treatment label only when intentional.
Rematch protein input with bulk assays before digestion when load-driven dispersion appears.
Replace or regenerate LC columns when retention time drift breaks alignment. Continue the cohort only after pilot files realign.
Lock DDA cycle settings or unlabeled data-independent acquisition (DIA) window plans for the remaining block. Treat post-lock changes as a new acquisition segment (Gillet et al. 2012).
Consider unlabeled DIA when DDA pilots show high missingness that tracks sampling, not prep (Label-Free DIA Quantitative Proteomics).
Prep spine detail appears in Quantitative Protein Analysis.
Processing and Normalization Responses
When extraction and statistics layers drive instability, lock the pipeline.
Reprocess the cohort block with one search version, modification rules, and FDR model.
Declare normalization method and whether QC pools were included in scaling (How to Normalize Data in Label-Free Quantitative Proteomics?).
Document match-between-runs or imputation choices because they change missing-value meaning.
Archive software versions with exported tables. Mid-cohort tool swaps require a new analysis record.
Pipeline layers appear in Tools for Label-free Peptide Quantification.
Integrated Remediation Workflow When QC Fails
A practical reproducibility recovery spine usually runs as follows.
- Freeze the current matrix and list QC signatures with run metadata.
- Test whether run order or prep batch explains separation.
- Fix design or prep layers when metadata confounds the contrast.
- Split acquisition records if methods changed mid cohort.
- Reprocess affected blocks under one locked pipeline.
- Re-run matrix QC before contrast testing.
- Retest the predefined contrast only if QC supports comparability.
- Document what changed relative to the first analysis pass.
Steps 1 through 3 diagnose. Steps 4 through 6 repair comparability. Step 7 restores statistical claims.
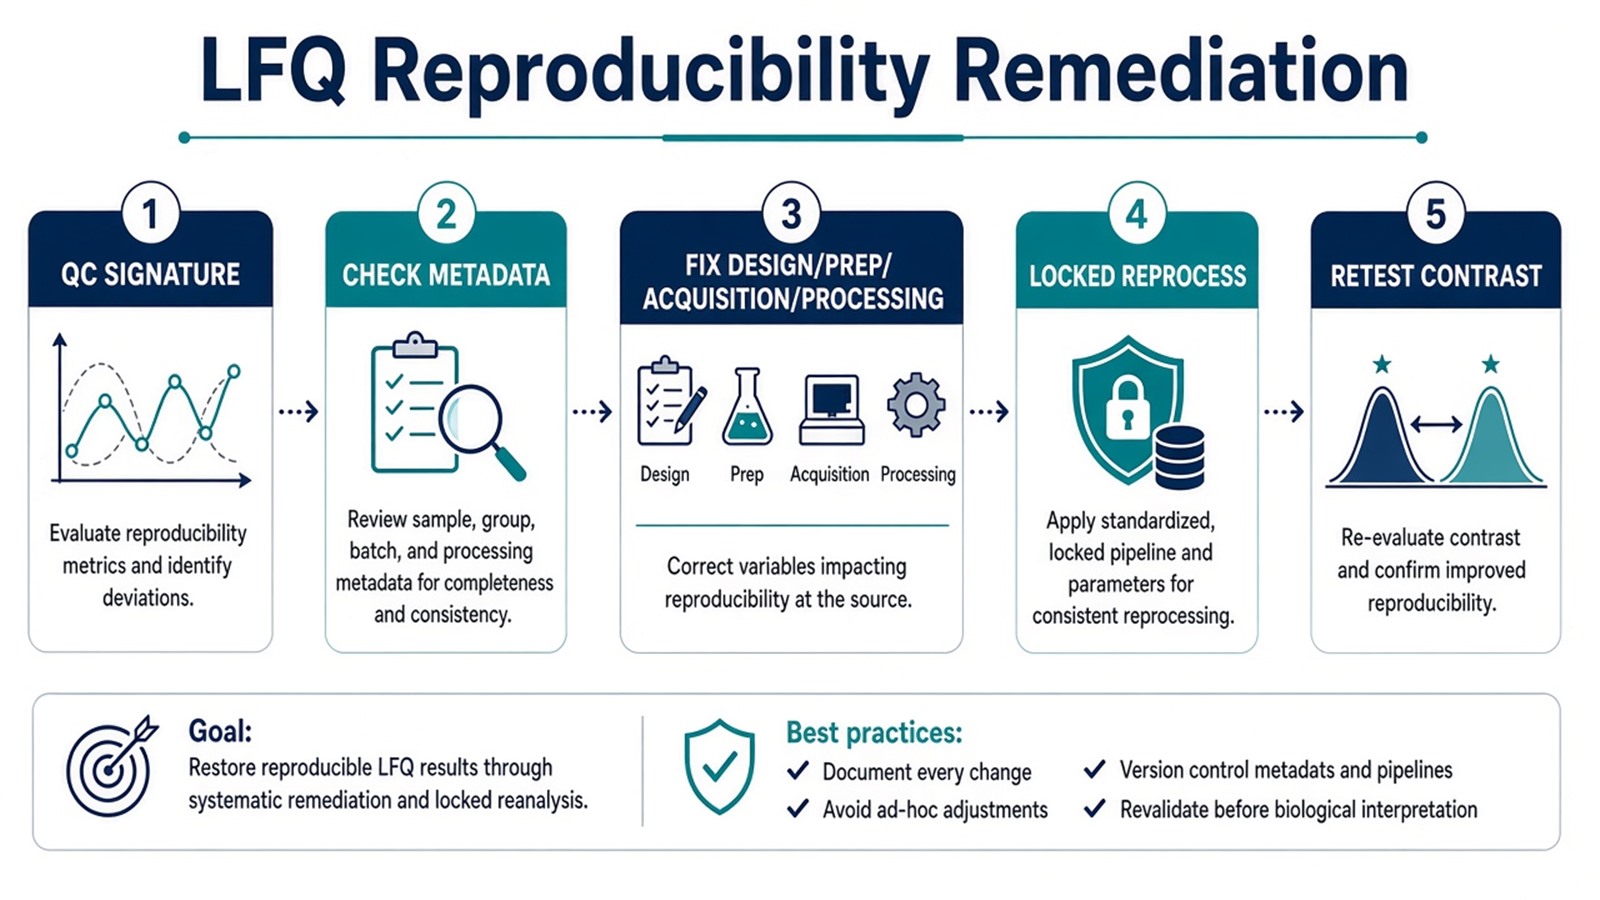
Figure 1. Reproducibility recovery traces QC signatures to design, prep, acquisition, or processing layers before contrasts are retested.
Experiment framing appears in A Guide to Label-Free Quantitative Proteomics: From Experiment to Data Analysis.
Parameters and Limits of Reproducibility Fixes
Issue signature |
Response that often fits |
Limit if misapplied |
|---|---|---|
Run-order confounding |
Interleave and metadata fix |
More statistics without design change |
Prep batch tracks group |
Repeat matched prep block |
Drop replicates without root cause |
Column drift |
Column change plus pilot |
Continue with broken alignment |
DDA missingness |
Unlabeled DIA after pilot lock |
DIA without window lock |
Pipeline version drift |
Reprocess unified block |
Mix versions in one contrast |
Imputation hides dropout |
Declare imputation rule |
Impute before diagnosing batch |
Low replicate count |
Add biological replicates |
Force significance with n equals 2 |
Limits follow the same table. Reproducibility work does not convert discovery LFQ into clinical validation. Normalization does not fix intentional confounding. Switching to isobaric tagging mid open cohort needs a new design, not a post hoc rescue (Mass Spectrometry-Based Quantitative Proteomics: Labeled and Label-Free Quantification Strategies).
How to Choose Recovery Scope for the Next LFQ Cohort
Use failure layer, cohort progress, and follow-up goal together.
Situation |
Recovery plan that often fits |
Recheck before committing |
|---|---|---|
Early pilot, prep dispersion |
Fix prep SOP and repeat pilot |
Full cohort before pilot passes |
Mid cohort column failure |
New column segment plus interleave |
Merge segments without record |
DDA missingness only |
Unlabeled DIA for remaining block |
DIA without library or extractor plan |
Open list, chronic batch noise |
TMT for closed set if enrollment allows |
TMT when samples still arrive weekly |
Names frozen, need remeasure |
PRM panel on stored aliquots |
Re-run full LFQ for three peptides |
QC pool drift only |
Instrument service plus QC schedule |
Drop biological samples |
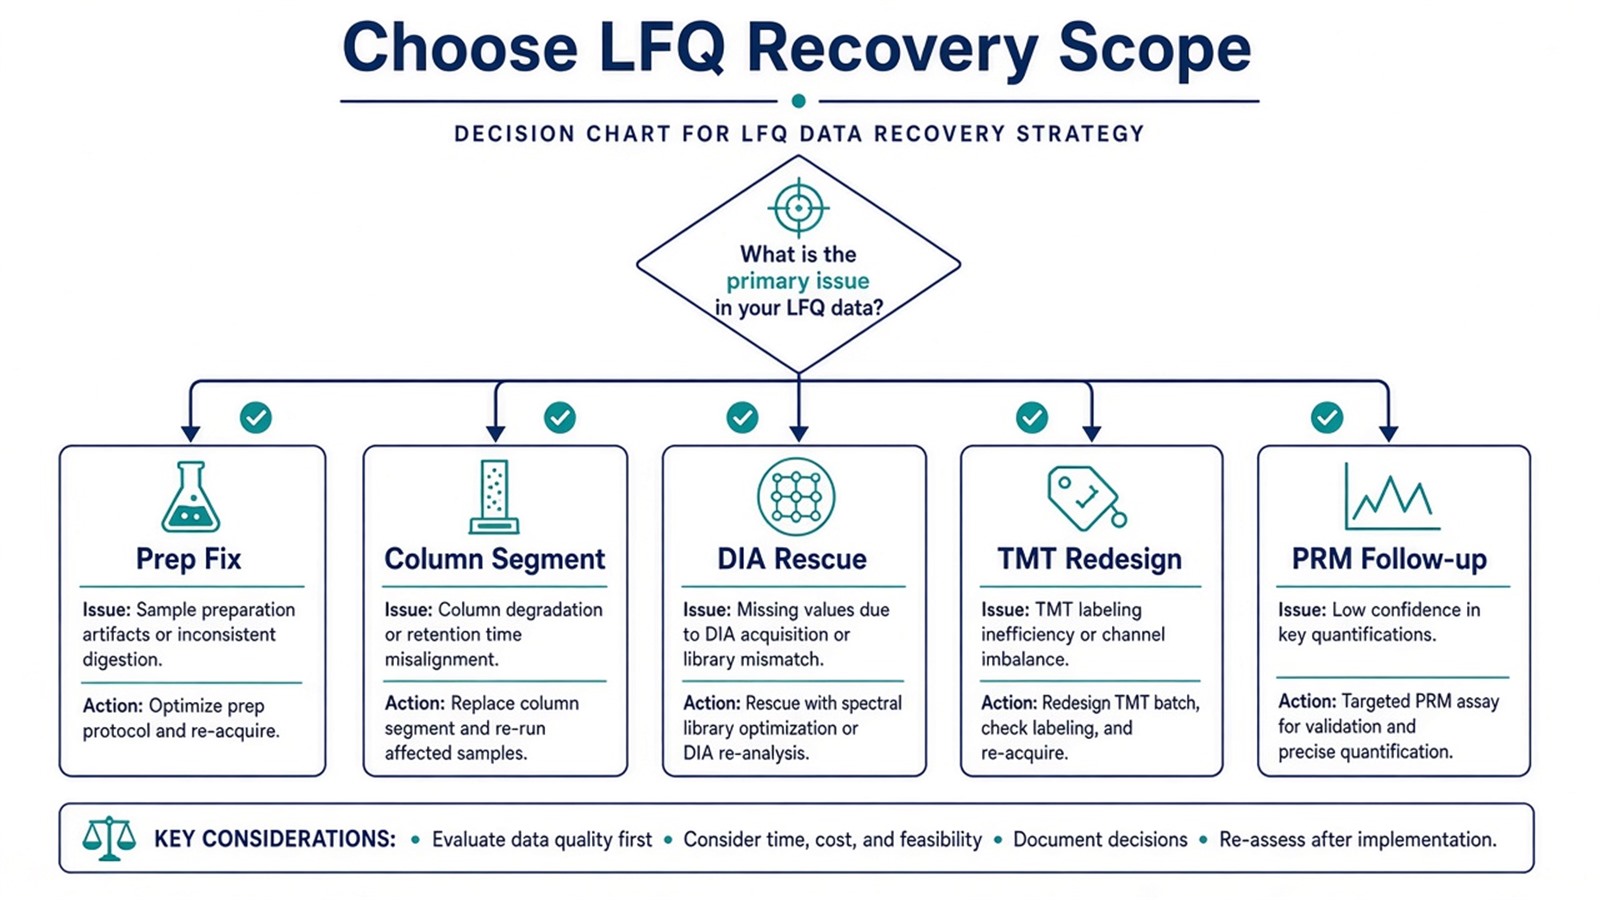
Figure 2. Choose in-block fixes when one layer failed; choose route change when design or acquisition mode cannot support the contrast.
Route selection appears in Protein Quantification Method.
Teams with QC signatures, metadata tables, and cohort block status can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for reproducibility recovery planning.
Frequently Asked Questions
1. Are technical replicates enough to prove biological reproducibility?
No. Technical replicates test instrument and prep repeatability. Biological replicates test the contrast.
2. Should outlier samples be removed when PCA separates one run?
Only after metadata review. Runs that track failed prep or wrong labels differ from biological outliers.
3. Does batch correction software fix confounded run order?
It adjusts scale and systematic effects. It does not replace interleaved design when day tracks treatment.
4. Is low overlap of identified proteins between replicates always failure?
Not always in DDA LFQ. Missingness patterns and contrast stability matter more than identical ID lists.
5. When should a cohort switch from LFQ to targeted assays?
When names are frozen and decisions need remeasurement or stable isotope-labeled internal standard amount, not when discovery lists are still open.
MtoZ Biolabs can discuss LFQ reproducibility recovery when QC outputs, metadata, and contrast design are documented.
If further evaluation of block reprocessing, DDA versus unlabeled DIA rescue, or discovery-to-targeted staging is needed, project details can be submitted for a feasibility review.
Reference
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, H. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- M. Choi, C. Chang, N. Clough, D. Broudy, T. Killeen, B. MacLean, M. Vitek (2014). MSstats: an R package for statistical analysis of quantitative mass spectrometry-based proteomic experiments. Bioinformatics, 30, 2524-2526. https://doi.org/10.1093/bioinformatics/btu305
