



Label-free quantification (LFQ) quality in proteomics projects means a relative protein matrix defends the predefined contrast after documented prep, acquisition, and processing rules (Cox et al. 2014). Reproducibility means biological replicates and technical controls show stable peptide evidence for the same contrast, not identical raw intensities on every protein. Separate unlabeled injections carry their own chromatography and instrument history, so quality work spans design, matched pretreatment, run order, and one declared analysis pipeline. The guide below integrates those layers for LFQ cohorts and ties them to workflow, parameters, limits, and fit. It is not a vendor maintenance manual, not a software click path for one platform, and not a repeat of full LFQ definition theory.
LFQ does not remove batch effects by default. Missing values, alignment drift, and confounded run order can mimic biology when contrasts are not frozen (Lazar et al. 2016).
In MtoZ Biolabs offerings, unlabeled discovery quality is commonly planned across matched prep, interleaved acquisition, unified search and normalization settings, and contrast-tested reporting.
Principle language appears in What Is Label-Free Analysis?. Method survey context appears in Mass Spectrometry-Based Quantitative Proteomics: Labeled and Label-Free Quantification Strategies.
What Quality and Reproducibility Mean for LFQ Matrices
Project records should separate three quality ideas.
Contrast integrity means arms were defined before threshold tuning and were not relabeled after acquisition.
Technical comparability means prep, injection load, column state, and processing version stay matched enough for cross-run alignment.
Biological reproducibility means independent replicates support group differences beyond run-order confounding.
LFQ quality is contrast-ready relative matrices with documented QC, not maximum protein count alone.
Enrollment checks before scaling appear in Exploring Quantitative Analysis in Proteomics.
Experimental Design Gates Before LFQ Acquisition
Quality starts before the first injection.
Freeze contrast labels and replicate structure. Post hoc arm merges invalidate LFQ statistics.
Plan interleaved run order when cohort size grows. Injection day should not track treatment unless that confound is intentional.
Declare acquisition route: data-dependent acquisition (DDA) MS1 LFQ versus unlabeled data-independent acquisition (DIA) when pilots support windowed extraction (Gillet et al. 2012).
Reserve aliquots when targeted follow-up may follow discovery.
Pilot new matrices before full cohort scale. Prep yield and chromatography stability belong in the pilot record.
Sample Preparation QC Checkpoints
Matched prep protects LFQ more than extra search sensitivity.
Use one declared lysis and digestion route across contrast arms. Mixed buffer families between groups create peptide yield bias.
Match total protein input with bulk assays such as bicinchoninic acid (BCA) before digestion when load normalization depends on input.
Control digestion time, enzyme ratio, and cleanup recovery equally across arms. Unequal desalting recovery creates missing values that track treatment.
Limit keratin and plastic binder contamination with gloves, dedicated labware, and clean benches.
General prep spine appears in Quantitative Protein Analysis. LC load discipline appears in Quantitative Analysis of Proteins by Liquid Chromatography. Windowed prep context appears in SWATH-MS Label-Free Protein Quantification Technology Analysis.
LC-MS Acquisition Stability for Separate Injections
Each LFQ file depends on stable chromatography and documented instrument state.
Track column age, gradient performance, and retention time drift across the cohort. Large drift breaks feature alignment.
Maintain ion source cleanliness and calibration on a declared schedule. Suppression and sensitivity shifts affect low-abundance peptides first.
Lock DDA cycle settings or DIA window plans for the cohort block. Mid-study method changes split comparability.
Use pooled QC or reference peptide spikes when the project record includes them for system monitoring. QC interpretation stays separate from biological contrast arms.
DDA stochasticity increases missing values at low abundance. Unlabeled DIA may change completeness but still needs locked windows and extraction rules (Label-Free DIA Quantitative Proteomics).
Data Processing and Matrix QC for Label-Free Cohorts
Processing consistency defines whether intensities are comparable.
Apply one search engine version, modification rules, and false discovery rate (FDR) model across files.
Extract MS1 areas or DIA fragments with declared algorithms. Mixing DDA MS1 tables with DIA fragment tables in one model without documentation breaks contrasts.
Normalize with a declared method and scope (How to Normalize Data in Label-Free Quantitative Proteomics?).
Document missing-value detection limits and imputation before contrast testing.
Review matrix QC plots such as principal component views and replicate dispersion to flag batch structure that tracks run order instead of biology. QC plots inform investigation; they do not replace frozen contrasts.
Extraction conventions for DIA appear in DIA Data Analysis Methods in Proteomics.
Integrated End-to-End LFQ Quality Workflow
A practical quality spine usually runs as follows.
- Lock contrast, replicates, and acquisition route.
- Execute matched prep with batch metadata recorded.
- Run pilot injections; accept or adjust load and gradient.
- Acquire cohort with interleaving and QC inserts as agreed.
- Process under one pipeline version with locked parameters.
- Normalize and apply missing-value policy.
- Run matrix QC; investigate batch flags before contrast testing.
- Test predefined contrast only; report QC layers with results.
Steps 1 through 4 are acquisition-side quality. Steps 5 through 8 are matrix-side quality.
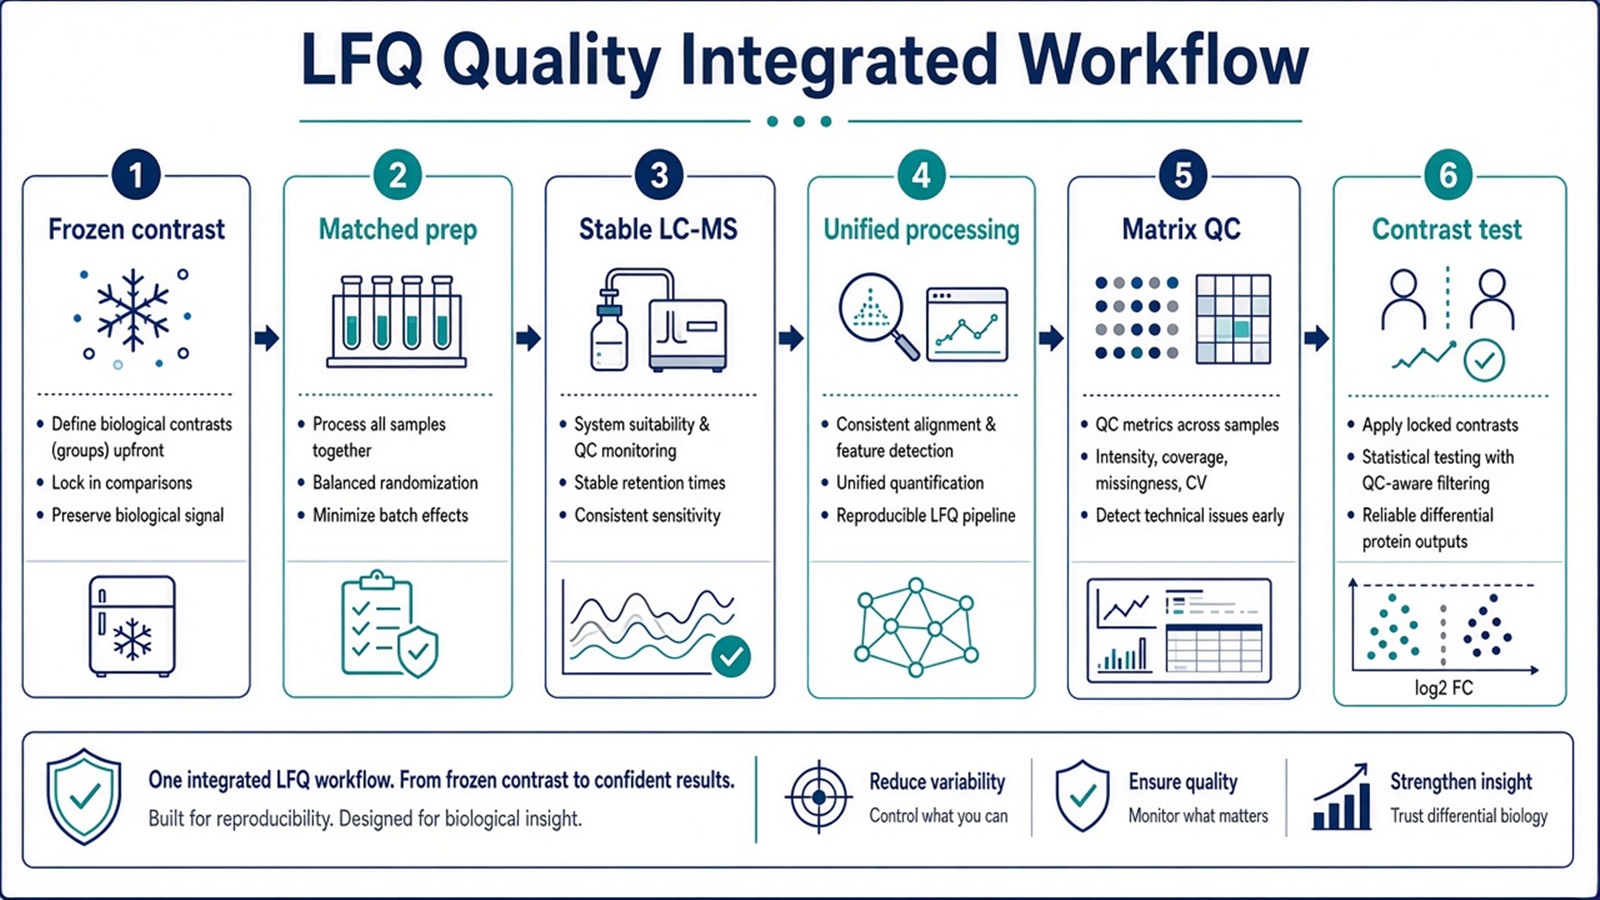
Figure 1. LFQ quality spans design, prep parity, acquisition stability, and one processing record before contrast claims.
End-to-end experiment framing appears in A Guide to Label-Free Quantitative Proteomics: From Experiment to Data Analysis.
Parameters and Limits When Quality Targets Conflict
Layer |
Parameter that must be declared |
Failure mode if ignored |
|---|---|---|
Design |
Frozen contrast and replicates |
Post hoc arm merges |
Prep |
Matched routes across arms |
Load bias mimics biology |
Run order |
Interleaving across groups |
Batch tracks treatment |
Acquisition |
Locked DDA or DIA block |
Split incompatible files |
Processing |
One pipeline version |
Mixed search spaces |
Normalization |
Method and scope |
Global drift as regulation |
Missing values |
Policy before statistics |
Imputed gaps without rules |
QC interpretation |
QC separate from biology arms |
QC pools treated as groups |
Limits follow the same table. LFQ quality work does not certify diagnostic assays or fixed coefficient-of-variation promises on every protein. Match-between-runs and imputation can fill gaps but do not prove absence. Forced DIA when DDA pilots already meet contrast needs may add cost without quality gain.
How to Choose LFQ Quality Scope for the Next Project
Use matrix risk, cohort size, and follow-up goal together.
Project need |
Quality plan that often fits |
Recheck before committing |
|---|---|---|
Small pilot, new matrix |
Prep pilot plus replicate injections |
Full cohort without pilot QC |
Large open cohort |
Interleaved DDA LFQ or unlabeled DIA |
Run order identical to group |
High missingness in DDA pilot |
Unlabeled DIA after window lock |
DDA when DIA adds little |
Strict amount on finalists |
Targeted SIS after LFQ discovery |
Discovery intensities as amount |
Multi-site files |
Harmonized prep SOP and pipeline version |
Mixed processing versions |
Time-course contrast |
Frozen time bins before acquisition |
Relabel time after acquisition |
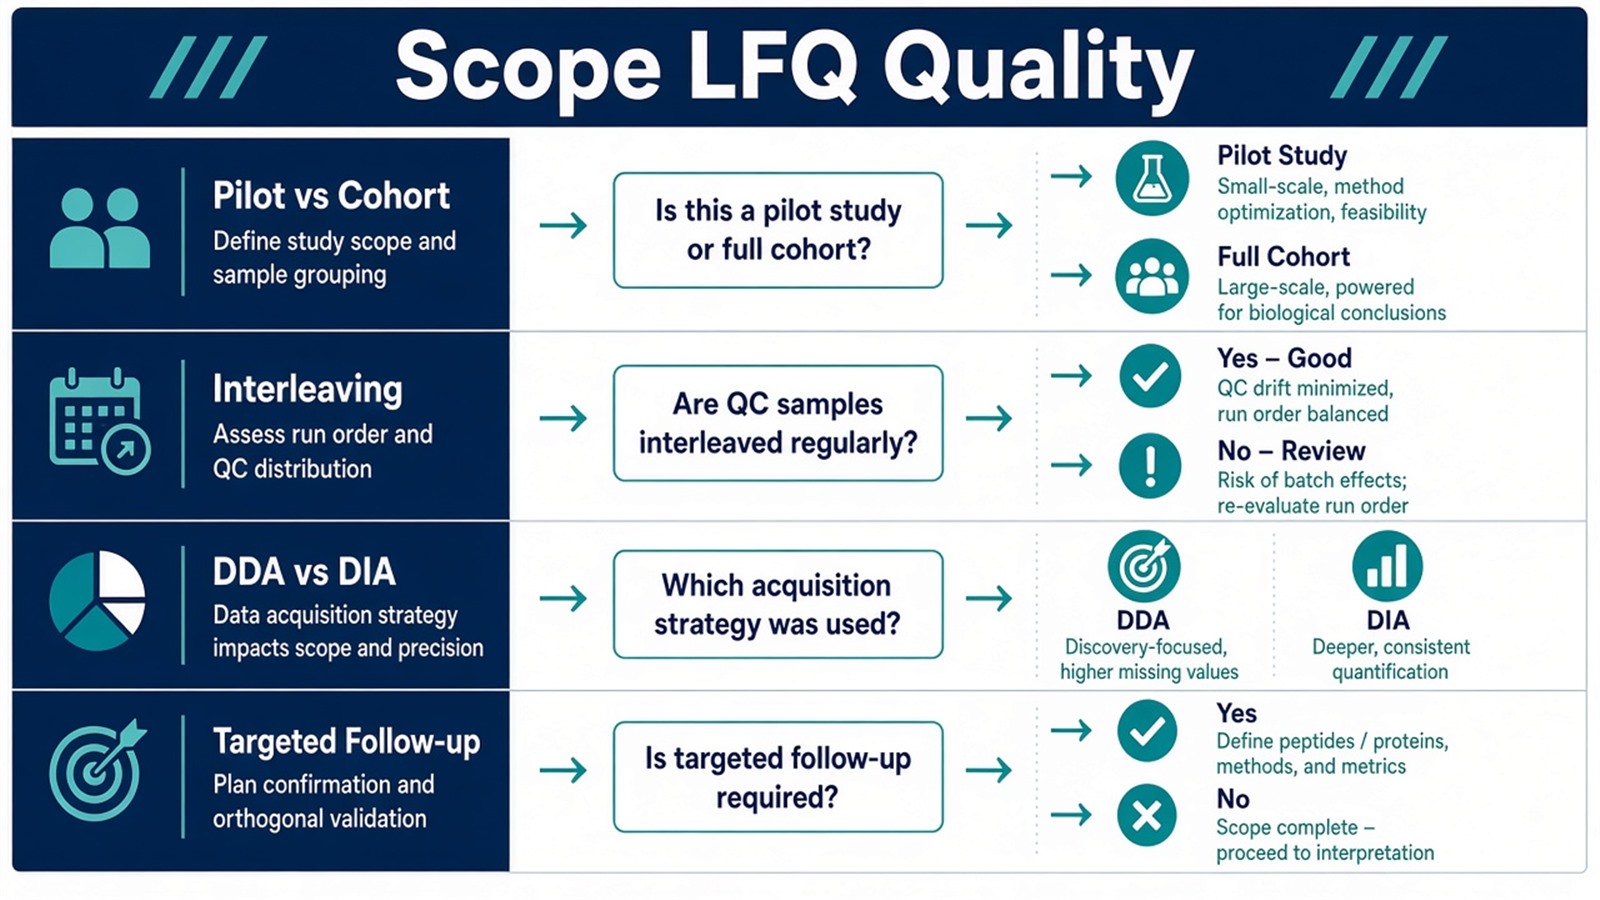
Figure 2. Scope LFQ quality around prep parity and locked processing; DIA or targeted routes fit when pilots show missingness or claim unit demands it.
Route selection appears in Protein Quantification Method.
Teams with contrast design, matrix documentation, and cohort size can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for LFQ quality planning alignment.
Frequently Asked Questions
1. Does a higher protein identification count alone indicate adequate LFQ quality?
No. Identification depth does not replace contrast integrity, prep parity, or processing consistency.
2. Can normalization alone fix confounded run order?
No. Normalization adjusts scale. It does not remove treatment confounded with injection day without design changes.
3. Should Match Between Runs always be enabled?
It is a project decision. Gap filling can help alignment but must be documented because it affects missing-value interpretation.
4. Is instrument brand the main reproducibility factor?
No. Prep matching, run order, locked methods, and replicate design usually dominate cohort comparability.
5. When should LFQ shift to unlabeled DIA for quality reasons?
When pilots show high missingness or unstable DDA sampling and windowed extraction improves completeness under locked rules.
MtoZ Biolabs can discuss LFQ quality planning when contrast design, prep records, and acquisition scope are documented.
If further evaluation of pilot QC, normalization choice, or DDA versus unlabeled DIA staging is needed, project details can be submitted for a feasibility review.
Reference
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, H. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- J.R. Wisniewski, A. Zougman, N. Nagaraj, M. Mann (2009). Universal sample preparation method for proteome analysis. Nat. Methods, 6, 359-362. https://doi.org/10.1038/nmeth.1322
