



Machine learning in label-free quantification (LFQ) data analysis usually means algorithmic steps inside declared pipelines, not a separate product layer that replaces study design. Neural networks and related models can score spectra, correct interference in data-independent acquisition (DIA) maps, align features, impute missing values, or fit complex variance models when inputs and contrasts are frozen (Demichev et al. 2020; Cox et al. 2014). The guide below maps where those steps sit in LFQ analysis, what must be locked in the project record, and where machine learning cannot fix prep or batch confounding. It is not an artificial intelligence trends essay, not a deep learning peak-picking sales page, and not a substitute for documented normalization and contrast testing.
Model-assisted imputation and classification change p-values and missing-value meaning. Methods text must name the model class, training scope, and whether imputation ran before or after quality review (Lazar et al. 2016).
In MtoZ Biolabs offerings, unlabeled analysis records commonly separate core search and quantification steps from optional model-assisted imputation or DIA extractors when those tools are in scope for the cohort block.
Tool layer context appears in Tools for Label-free Peptide Quantification. Quality integration appears in How to Improve Data Quality and Reproducibility in Label-Free Proteomics?.
What Machine Learning Means in LFQ Analysis Records
Project language should separate four uses.
Spectral scoring and peptide identification in DIA or enhanced search uses learned scores to control error rates under declared FDR rules.
Feature extraction and interference modeling in unlabeled DIA uses neural networks to rank fragment evidence in crowded windows (Demichev et al. 2020).
Missing-value imputation uses learned or heuristic models to fill absent peptide intensities. Imputation is a statistical choice, not missing biology by default.
Contrast modeling uses mixed models or regularized classifiers on peptide tables. The predefined contrast must still be declared before tuning.
Machine learning accelerates or stabilizes declared analysis steps. It does not freeze contrasts, match prep, or interleave run order.
Principle context appears in What Is Label-Free Analysis?.
ML-Assisted Steps in DDA and Unlabeled DIA Pipelines
Acquisition route sets which machine learning steps are relevant.
DDA LFQ usually relies on database search plus MS1 peak integration. Learned rescoring or post-search machine learning may rerank identifications when the pipeline documents FDR control. Quantification still flows through alignment and normalization modules.
Unlabeled DIA often pairs library-free or library-based extraction with neural network engines that model interference across windows. Extractor version and window plan must match acquisition files (Label-Free DIA Quantitative Proteomics).
Retention time alignment may use learned warping functions in some platforms. Alignment quality still depends on chromatography stability from acquisition.
Deep learning peak picking on raw profiles is not a default replacement for vendor peak detection in most service records. Pilot evidence should justify any custom detector before cohort scale.
Broader extraction conventions appear in DIA Data Analysis Methods in Proteomics.
Missing Values, Normalization, and Statistical ML Layers
Missing values dominate many LFQ matrices, especially in DDA cohorts.
Detection limits should be declared before imputation. Model-based imputation can increase apparent completeness while smoothing real dropout.
Normalization remains required after extraction. Median scaling, MaxLFQ-style ratio models, and variance-stabilizing transforms address scale drift. Normalization does not remove confounded batch if run order tracks treatment (How to Normalize Data in Label-Free Quantitative Proteomics?).
Mixed-model packages such as MSstats fit group contrasts on peptide tables with explicit variance structures when input formats match the pipeline.
Classifier-based protein ranking beyond the frozen contrast risks overfitting when sample count is low. Cross-validation and holdout design belong in the analysis plan when predictive models are requested.
QC Review Where ML Outputs Need Human Checks
Machine learning outputs still need matrix QC before biology language.
Review principal component structure against run metadata. Separation that tracks injection day should trigger design review, not only model retuning.
Compare imputed versus observed peptide counts per arm. Imputation-heavy arms need explicit flags in reports.
Track extractor or model version changes across blocks. A version swap mid cohort splits comparability with earlier files.
Reproducibility remediation follows the same metadata logic when QC fails after model-assisted processing (How to Overcoming Reproducibility Issues in Label-Free Proteomics?).
Integrated Label-Free Analysis Workflow With Documented ML Steps
A practical analysis spine with optional machine learning extensions usually runs as follows.
- Confirm contrast, acquisition route, and pipeline scope including any ML modules.
- Convert raw files; lock search or DIA extractor parameters.
- Identify and quantify peptides to a table with software versions archived.
- Align and normalize with declared methods.
- Run optional ML imputation or rescoring only when the analysis plan names them.
- Execute matrix QC against metadata.
- Test predefined contrast with documented variance model.
- Report optional pathway overlay separately from contrast statistics.
Steps 2 through 4 are core LFQ analysis. Steps 5 through 7 are where machine learning modules must stay transparent.
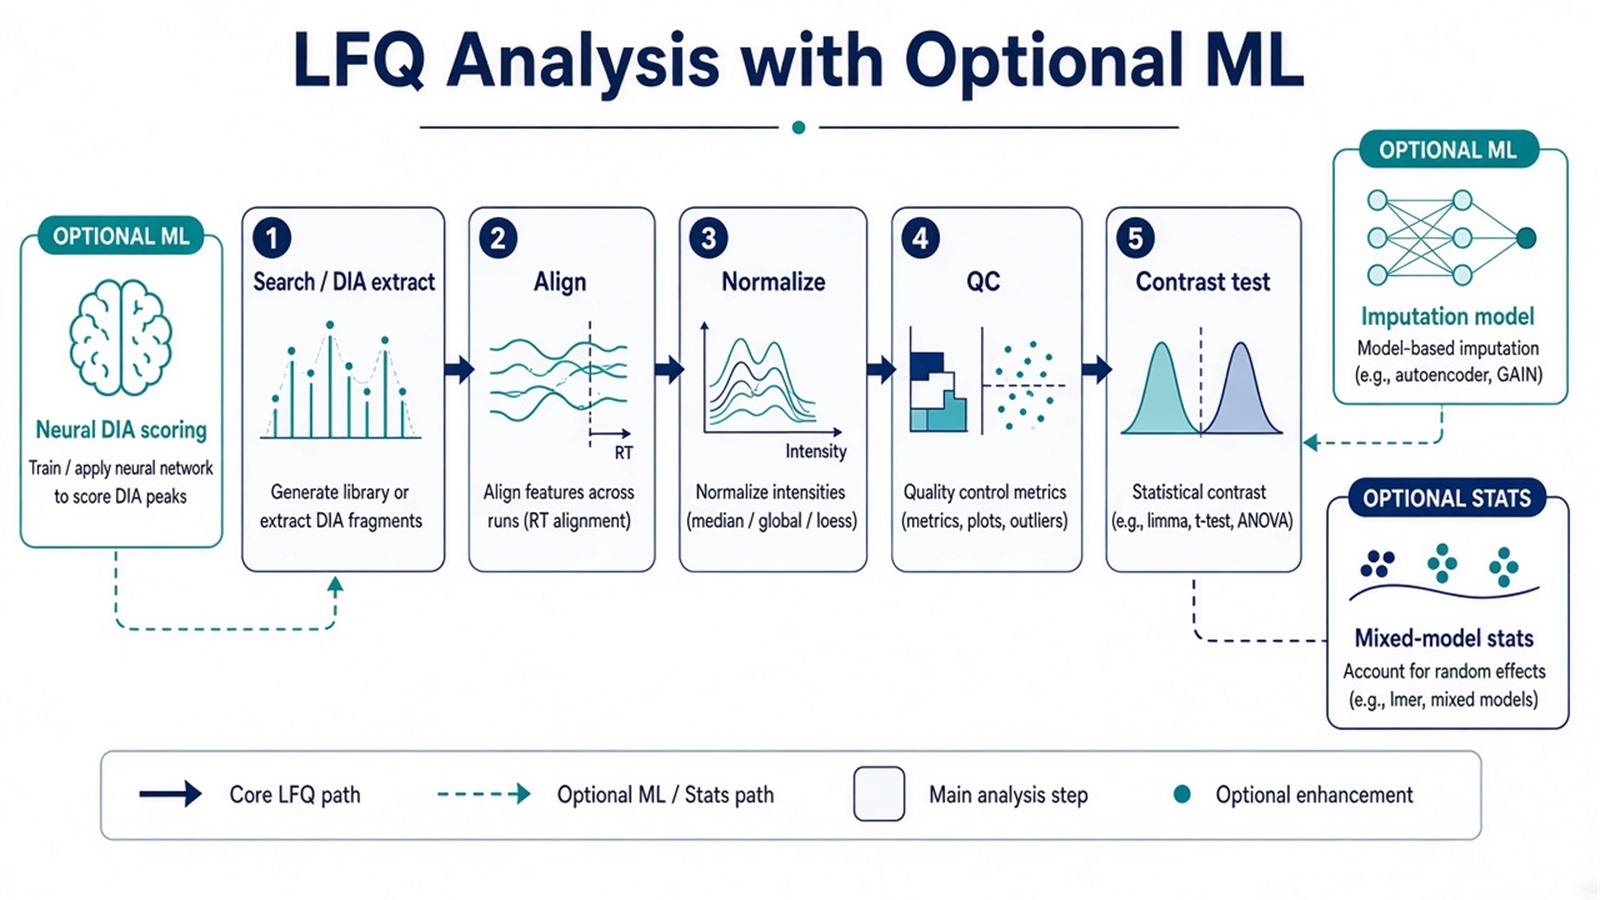
Figure 1. Machine learning modules sit inside declared LFQ analysis steps; design and prep layers remain outside model tuning.
End-to-end framing appears in A Guide to Label-Free Quantitative Proteomics: From Experiment to Data Analysis.
Parameters and Limits of ML in LFQ Interpretation
Analysis step |
ML-related parameter to declare |
Limit if mis-set |
|---|---|---|
DIA extraction |
Extractor version and library route |
Window plan mismatch |
Imputation |
Model class and timing versus QC |
Imputed biology without flags |
Normalization |
Scope excluding or including QC pools |
Scale drift read as regulation |
Contrast |
Frozen before model tuning |
Post hoc relabeling |
Predictive models |
Cross-validation and holdout |
Overfit biomarker lists |
Block integrity |
One pipeline per cohort segment |
Mixed versions in one contrast |
Claim |
Relative discovery default |
Classifier score as diagnostic cutoff |
Limits follow the same table. Machine learning does not certify clinical diagnostics from discovery cohorts. Nonlinear models can fit batch noise when sample count is small. Multi-omic fusion after LFQ still requires a tested protein contrast first.
Method route context appears in Mass Spectrometry-Based Quantitative Proteomics: Labeled and Label-Free Quantification Strategies.
How to Choose Analysis Scope With or Without ML Extensions
Use cohort size, acquisition route, and claim unit together.
Project need |
Analysis plan that often fits |
Recheck before committing |
|---|---|---|
Standard DDA LFQ discovery |
Search plus MS1 quant plus mixed-model stats |
Heavy imputation without QC review |
Large unlabeled DIA cohort |
Neural network DIA extractor plus FDR lock |
DDA tools on DIA files |
High missingness after QC |
Documented imputation or unlabeled DIA rescue |
Impute before batch diagnosis |
Small n, many proteins |
Simple contrast model |
Complex classifiers on n below 10 |
Predictive biomarker wording |
Holdout validation design |
Training and testing on same files |
Specification amount on peptides |
Targeted SIS assay outside open LFQ ML |
Discovery classifier as clinical panel |
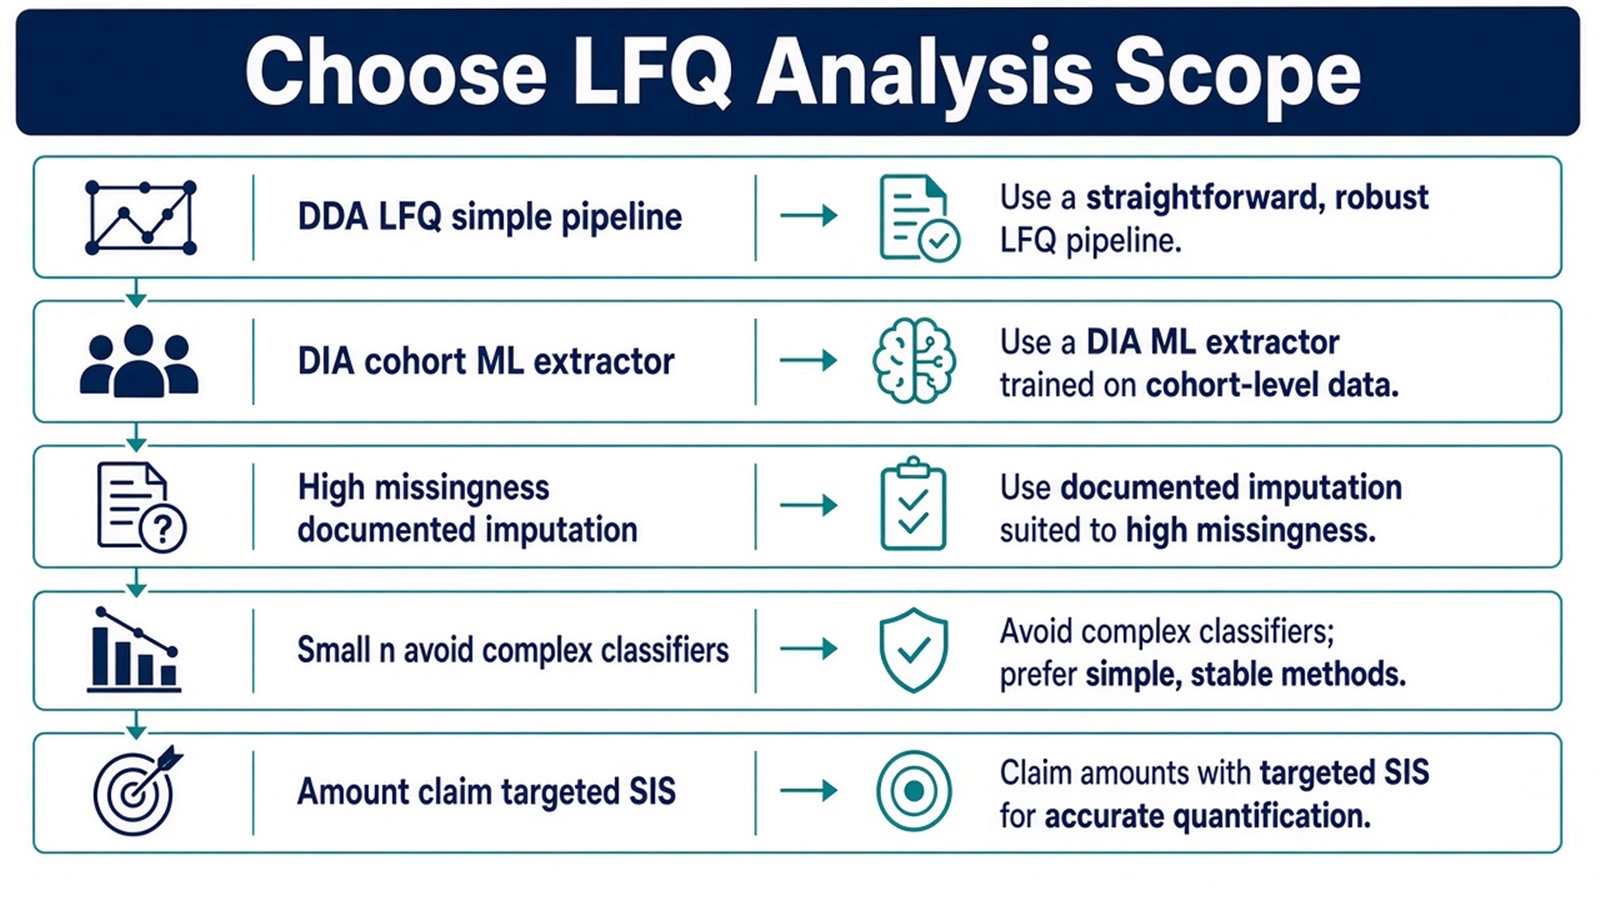
Figure 2. Add ML-assisted DIA or imputation when pilots justify them; keep contrasts and QC outside opaque model defaults.
Enrollment checks appear in Exploring Quantitative Analysis in Proteomics. Route selection appears in Protein Quantification Method.
Teams with acquisition route, pipeline scope, and contrast design can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for analysis planning alignment.
Frequently Asked Questions
1. Does machine learning replace label-free sample preparation?
No. Prep, run order, and contrast design stay experimental layers. Models operate on tables after acquisition.
2. Is DIA-NN the same as generic AI proteomics?
DIA-NN is a documented DIA extraction engine with neural network scoring. It is one optional step inside unlabeled DIA analysis, not a whole study design.
3. Should missing values always be imputed with ML?
No. Imputation is optional and changes statistics. Many projects report sensitivity with and without imputation.
4. Can classifiers replace differential contrast testing?
No for predefined group contrasts. Classifiers address prediction tasks with separate validation design.
5. When should analysis skip ML extensions?
When DDA LFQ pilots already meet contrast needs with simpler locked pipelines and QC passes without imputation.
MtoZ Biolabs can discuss label-free analysis planning when pipeline scope, model steps, and contrast design are documented.
If further evaluation of DIA extractor choice, imputation policy, or discovery-to-targeted staging is needed, project details can be submitted for a feasibility review.
Reference
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- V. Demichev, C. Messner, S. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- M. Choi, C. Chang, N. Clough, D. Broudy, T. Killeen, B. MacLean, M. Vitek (2014). MSstats: an R package for statistical analysis of quantitative mass spectrometry-based proteomic experiments. Bioinformatics, 30, 2524-2526. https://doi.org/10.1093/bioinformatics/btu305
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, H. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
