



High-throughput sequential window acquisition of all theoretical fragment ion spectra (SWATH-MS) is often applied when a large unlabeled cohort needs a relative protein matrix with scheduled-window data-independent acquisition (DIA) on separate injections (Gillet et al. 2012). In biomarker-oriented language, that usually means finding candidate proteins that change between predefined groups after discovery statistics, not certifying a clinical test. The guide below maps SWATH application choices for those cohort designs. It is not a diagnostic promise, not a software pipeline manual, and not a DDA versus DIA theory page.
SWATH is a window plan on unlabeled digests. Label-free chemistry and DIA acquisition stay separate decisions from downstream candidate ranking. In MtoZ Biolabs offerings, unlabeled digests are commonly acquired as DIA or SWATH-style schedules, with extraction and contrast testing documented after prep and windows are locked.
Application Contexts Where High-Throughput SWATH Fits
Three application contexts appear most often when teams describe biomarker discovery with SWATH.
Large case-control or risk-group cohorts that need one relative contrast across many files. Separate injections fit open enrollment when sample arrival spans weeks.
Multi-condition screens with stable chromatography and a locked extractor. Windowed DIA can extract peptides later even when precursors were not top-ranked in real time, which often suits high file count studies when prep and gradients stay matched (Rosenberger et al. 2017).
Candidate narrowing before targeted follow-up. SWATH discovery yields a short list for parallel reaction monitoring (PRM) or multiple reaction monitoring (MRM) remeasurement. Discovery candidates are not validated biomarkers until a separate confirmation design exists.
High-throughput SWATH application value is a defensible relative matrix plus a predefined contrast, not a clinical panel by default.
Researchers who need label-free SWATH pretreatment rules can refer to SWATH-MS Label-Free Protein Quantification Technology Analysis.
Study Designs for Candidate Discovery Cohorts
Application success follows enrollment and contrast design more than a biomarker keyword.
Matched prep across arms. Cases and controls, or treatment and vehicle, must share lysis, digestion, and cleanup rules. Unequal depletion or batch-specific prep creates list differences that look like candidates.
Interleaved acquisition order. High throughput still needs run order that does not track group labels. Throughput without interleaving trades speed for confounding.
Library or library-free extraction declared upfront. Library-based SWATH uses provenance-matched spectral evidence. Library-free direct DIA searches under false discovery rate (FDR) control remove a separate library campaign but still need interference review (Demichev et al. 2020).
Optional targeted stage. When decisions require remeasurement, a closed PRM panel follows discovery. Amount claims on named peptides need stable isotope-labeled internal standard (SIS) assays, not discovery intensities alone (Gerber et al. 2003).
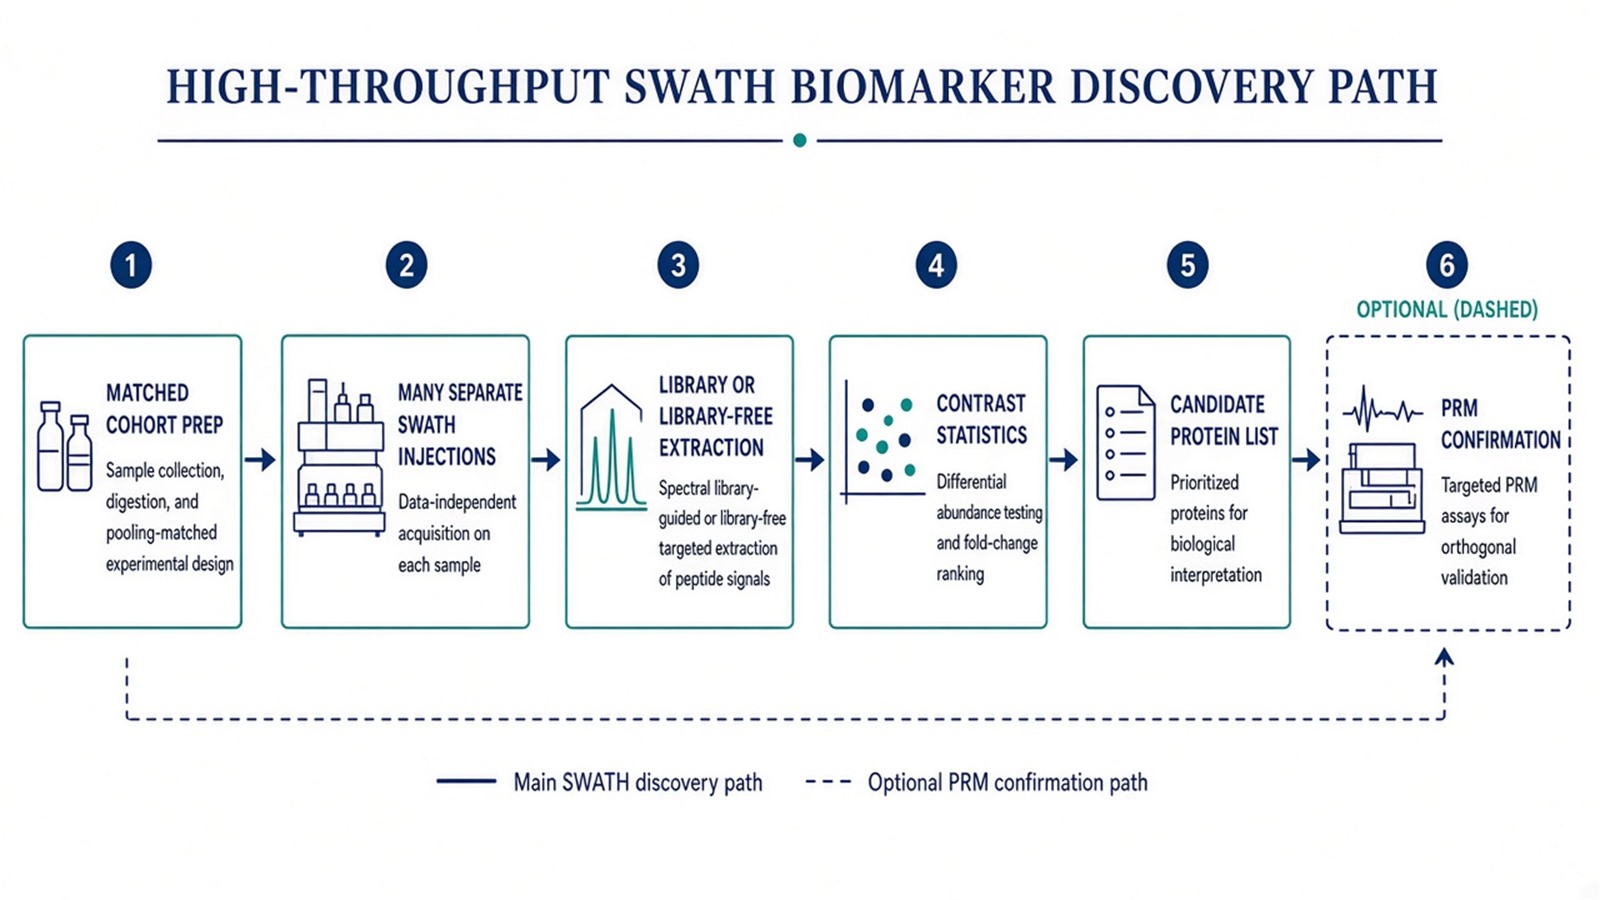
Figure 1. SWATH biomarker discovery applications move from matched cohort prep to a contrast-tested matrix, then optional targeted confirmation.
Extraction and matrix statistics belong with DIA Data Analysis Methods in Proteomics. This page stays on when SWATH fits the cohort application, not on extractor settings alone.
Shared Workflow From Cohort Sample to Candidate Context
A practical high-throughput SWATH discovery spine usually runs as follows.
- Confirm matrix, contrast, and relative claim across separate injections.
- Prepare matched digests with shared cleanup and declared loads.
- Acquire SWATH windows under a locked plan across the cohort.
- Extract peptides by library or library-free route under FDR and interference rules.
- Normalize, handle missing values, and test the predefined contrast only.
- Rank candidates for follow-up; document batch and missingness flags.
- Optional PRM or MRM on a shortened list when remeasurement is required.
Steps 1 and 2 are application gates. Skipping matched prep or running all cases before controls in one batch often produces candidate lists that fail confirmation. Step 5 is where biomarker language must stay at candidate status unless validation design exists.
Pathway or multi-omic overlay can help interpret a cleaned list. It cannot repair undefined contrasts or amount claims made without SIS (Lazar et al. 2016).
Parameters and Limits That Bound SWATH Discovery Claims
Parameter |
Why it matters in cohort applications |
Failure mode if ignored |
|---|---|---|
Contrast definition |
Separates discovery from post hoc fishing |
Regrouped files after acquisition |
Matched pretreatment |
Keeps peptide yield comparable |
Prep artifacts as candidates |
Window and cycle plan |
Constrains extraction |
Changed windows mid cohort |
FDR and interference filters |
Control false candidates |
Long lists with weak traces |
Missing-value policy |
Handles dropout at low abundance |
Imputed differences without evidence |
Follow-up plan |
Defines candidate versus validated |
Discovery peaks called diagnostic |
Limits follow the same table. SWATH does not ensure detection of low-abundance proteins in every matrix. Throughput does not remove abundance-dependent missingness. Reanalysis of stored spectra still needs a declared extractor and contrast. Clinical screening, personalized therapy, and diagnostic utility require assays outside an open discovery SWATH table.
Multi-center work adds shipping and freeze-thaw variables. They must be matched across arms, not balanced only at acquisition.
Researchers who need broader disease or drug contrast framing can refer to Quantitative Proteomics in Disease and Drug Discovery. For targeted confirmation trade-offs, see Advantages and Disadvantages of Targeted Proteomics.
How to Choose SWATH for the Next Discovery Project
Use cohort size, enrollment flexibility, and follow-up goal together.
Project need |
SWATH application plan that often fits |
Recheck before committing |
|---|---|---|
Many files, open enrollment, relative contrast |
Label-free SWATH with locked extractor |
Run order identical to group |
Large plasma cohort, equal prep |
SWATH after matched depletion |
Depletion on only one arm |
Freezable multi-arm set in one labeling day |
TMT may fit better than SWATH |
Forced SWATH when mixing is required |
Candidate list then remeasurement |
SWATH discovery then PRM panel |
Panel longer than duty cycle |
Mass or molar unit on finalists |
Targeted SIS assay |
Discovery SWATH as concentration |
Small pilot without contrast power |
Define groups before scaling throughput |
Biomarker wording on n equals 3 |
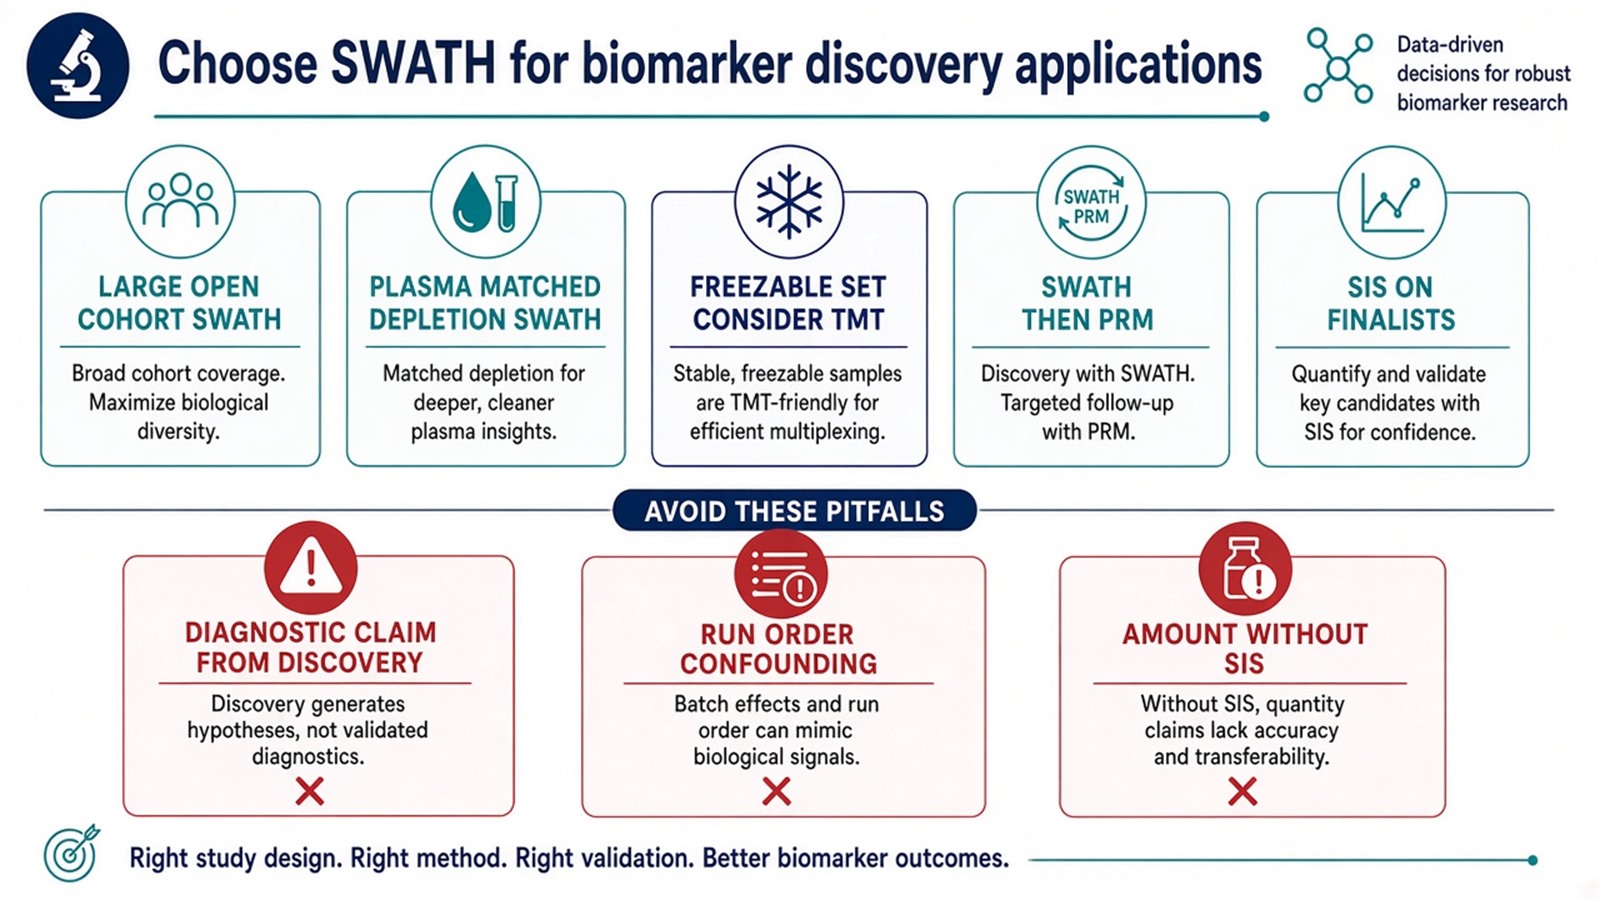
Figure 2. Choose SWATH for open high-file cohorts with a fixed contrast; validation and amount claims need targeted designs.
High-throughput SWATH more often fits open cohort candidate discovery with separate injections. TMT more often fits a freezable multi-group set. Targeted confirmation more often fits after names freeze. Exceptions exist when a pilot SWATH matrix already supports a tiny PRM subset without reopening enrollment rules.
Teams that already have matrix, contrast, cohort size, and follow-up goal can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for project-specific SWATH application planning. For three-axis route selection, see Protein Quantification Method.
Frequently Asked Questions
1. Does SWATH biomarker discovery equal a clinical test?
No. SWATH discovery yields candidate proteins for predefined contrasts. Clinical assays need separate validation designs.
2. Is high throughput the same as high power?
No. Throughput raises file count. Power still depends on replicate structure, effect size, and contrast QC.
3. Can SWATH replace PRM in validation studies?
Not when a locked targeted method is required. SWATH remains discovery-oriented. PRM or MRM fits closed remeasurement.
4. Must a DDA library exist before SWATH cohort acquisition?
No. Library-free extraction is an option. Prep and window plans still must be matched across the cohort.
5. Does deeper protein count mean stronger biomarker evidence?
No. Count and quantitative precision differ. Contrast quality and missing-value rules decide candidate strength.
MtoZ Biolabs can support high-throughput SWATH application planning when sample type, contrast, cohort design, and the intended relative claim are available.
If further evaluation of cohort prep, window locking, extractor choice, or discovery-to-targeted staging is needed, project details can be submitted for a feasibility review.
Reference
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- V. Demichev, C. Messner, S. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- G. Rosenberger, S. Liu, J. Röst, H.L. Ludwig, C. Buil, B. Borchers, R. Aebersold, L. Collins (2017). Statistical control of peptide and protein error rates in large-scale targeted data-independent acquisition analyses. Nat. Commun., 8, 14224. https://doi.org/10.1038/ncomms14224
