



Label-free proteomics analysis with MaxQuant or DIA-NN starts from independently prepared, unlabeled digests rather than from a software icon. Each sample is extracted, digested, and cleaned without isotopic or isobaric tags, then injected as its own liquid chromatography-tandem mass spectrometry (LC-MS/MS) run under a matched chromatography and run-order plan. Data-dependent acquisition (DDA) files are commonly processed in MaxQuant with MaxLFQ relative quantification (Cox et al. 2014). Data-independent acquisition (DIA) files are commonly processed in DIA-NN with library-based or library-free search (Demichev et al. 2020). The tools summarize relative protein change across those runs. They do not repair unmatched digestion, confounded injection order, or convert intensities into absolute concentration.
Researchers who already have unlabeled samples or a defined cohort design can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for project-specific feasibility and analysis planning.
Sample Preparation Decisions That Choose the Analysis Path
MaxQuant and DIA-NN sit downstream of sample handling. The same label-free chemistry can feed either tool; the acquisition mode decides which pipeline is primary.
Shared label-free sample requirements
Protein extraction, reduction and alkylation, protease digestion, and peptide cleanup must keep samples comparable. Residual detergent, uneven loading, and unstable chromatography create batch structure that neither MaxLFQ nor DIA-NN normalization can fully erase. Randomize or block run order by group. Record digestion protocol, column ID, and instrument block with the analysis record.
Where the paths diverge
Sample / acquisition plan |
Typical analysis tool |
Quantitative readout |
|---|---|---|
Independent digests acquired as DDA |
MaxQuant (+ Perseus for many downstream stats) |
MS1 feature / MaxLFQ protein intensities |
Independent digests acquired as DIA |
DIA-NN |
Fragment chromatogram intensities under FDR control |
Later enrollment under a compatible regime |
Same tool family as the original block |
Relative matrix extension with new QC |
Need absolute units for a shortlist |
Targeted SIS assay, not MaxQuant/DIA-NN alone |
Calibrated concentration |
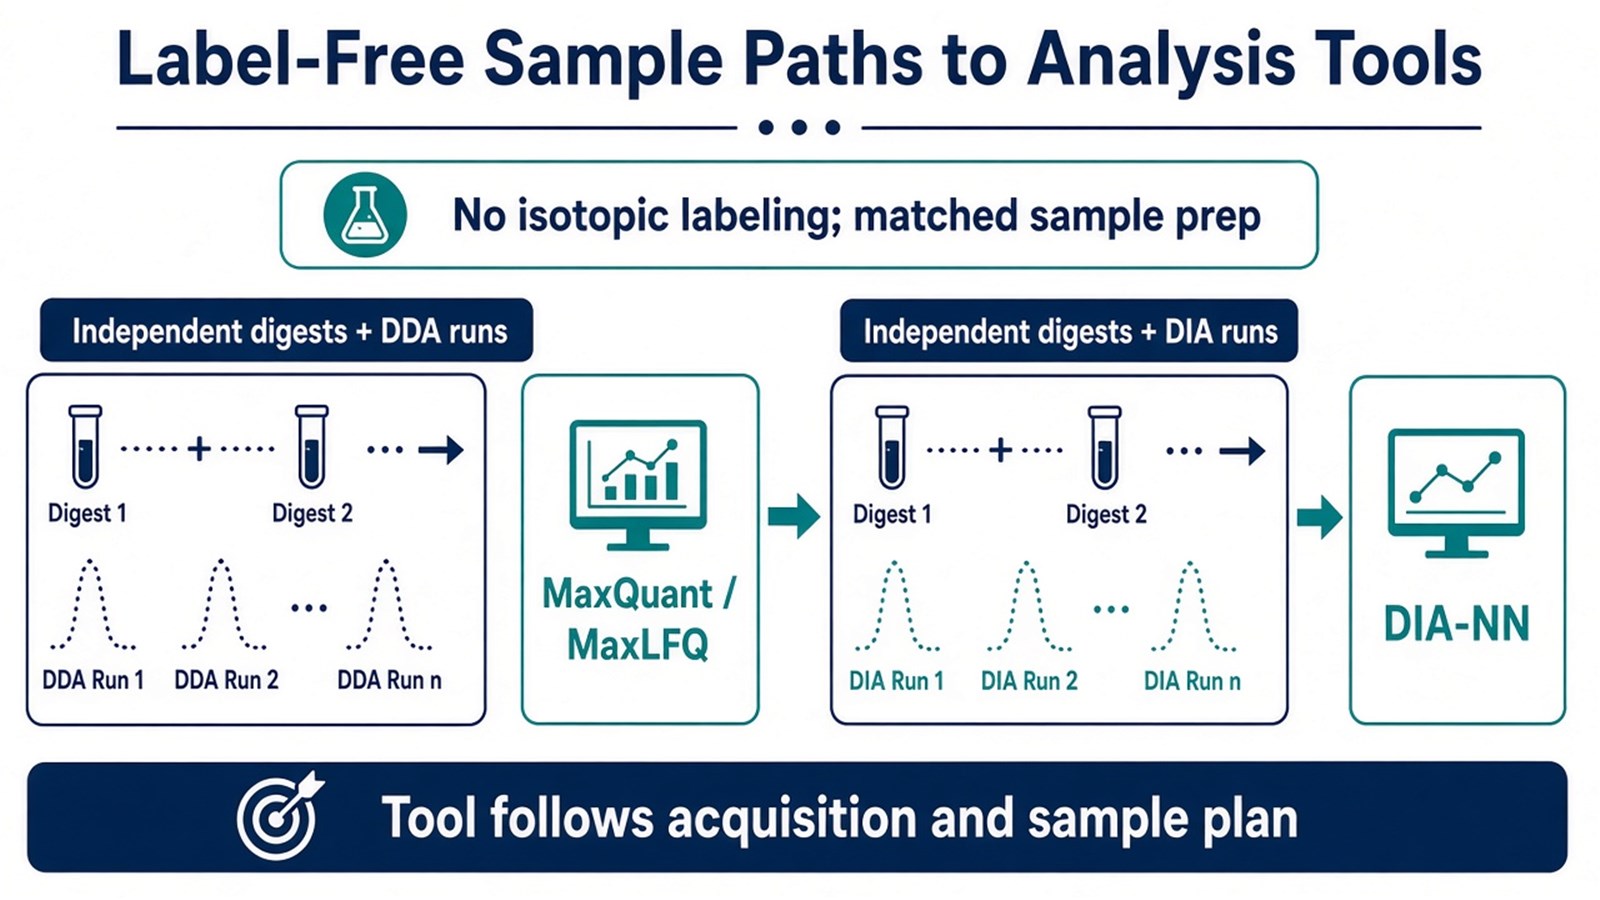
Figure 1. MaxQuant and DIA-NN follow the sample and acquisition plan: unlabeled independent digests acquired as DDA or DIA, then relative protein summarization.
Choose the digests and acquisition mode first; then choose MaxQuant or DIA-NN to match those files.
MaxQuant for DDA Label-Free Quantification
MaxQuant is widely used for high-resolution DDA proteomics. Andromeda searches identify peptides. For unlabeled quantification, MaxLFQ estimates protein profiles from peptide ratios with delayed normalization across runs (Cox et al. 2014). Match-between-runs (MBR) can transfer identifications to reduce missing values, but transferred features still need QC because incorrect transfer can create false completeness.
MaxQuant also supports labeled workflows such as SILAC or isobaric tags in other project designs. In this label-free review, the relevant claim is relative DDA-LFQ after independent sample injections. Perseus or equivalent tools often handle differential testing and visualization after the MaxQuant matrix is exported.
DIA-NN for DIA Label-Free Quantification
DIA-NN processes DIA runs in which precursors are fragmented in scheduled windows. It supports empirical libraries and library-free or predicted-library routes, with neural-network-assisted scoring and FDR control (Demichev et al. 2020). Quantification typically comes from extracted fragment chromatograms rather than from DDA MS1 features alone.
Library-free analysis can remove a separate DDA library-construction block, but it does not remove window interference or the need for matched sample preparation. Cross-run normalization improves comparability only when digestion, chromatography, and batch structure remain coherent. For unlabeled DIA project context beyond the software review, researchers can refer to Label-Free DIA Quantitative Proteomics.
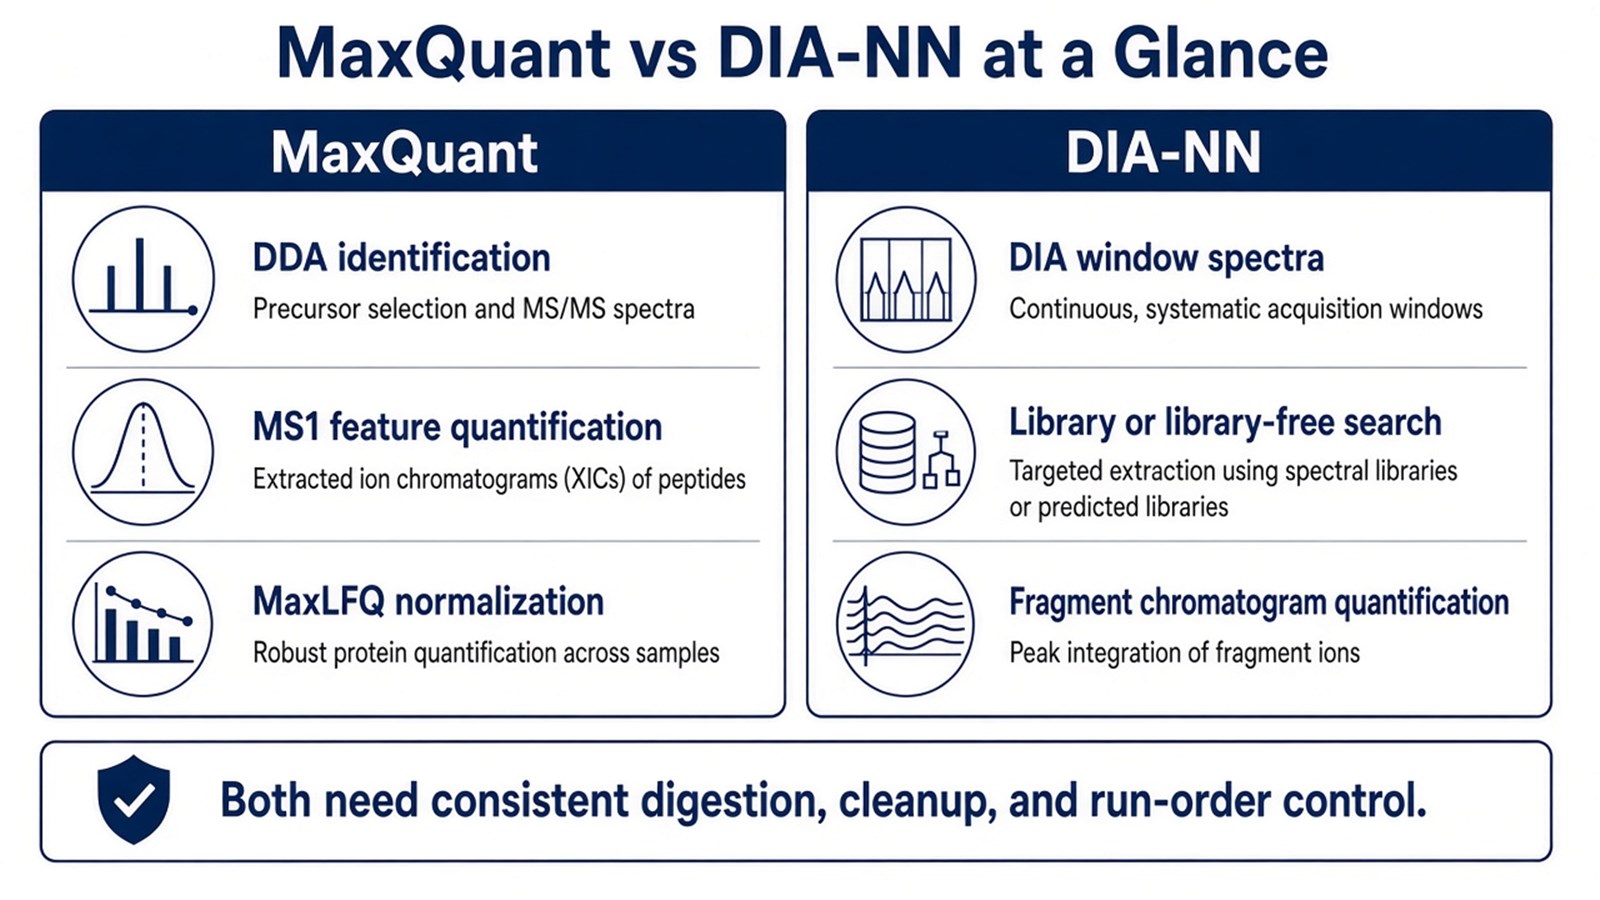
Figure 2. MaxQuant and DIA-NN differ mainly by acquisition class and quantitative feature type; both inherit sample-prep and batch limits of label-free designs.
Judgment Criteria: When MaxQuant, DIA-NN, or Another Route Fits
Study need |
Prefer MaxQuant |
Prefer DIA-NN |
Reassess LFQ tools |
|---|---|---|---|
Acquisition |
DDA files already planned or acquired |
DIA files already planned or acquired |
Wrong tool for the file type |
Sample plan |
Independent unlabeled digests; moderate cohort |
Independent unlabeled digests; larger DIA cohorts |
Samples must enter one TMT plex |
Main claim |
Relative DDA-LFQ discovery |
Relative DIA discovery with scheduled windows |
Absolute concentration required |
Library logistics |
DDA identification-centric workflow |
Library or library-free DIA extraction |
Targeted closed panel only |
Prep status |
Digestion and run order controlled |
Digestion and run order controlled |
Unmatched prep or broken batch design |
Prefer MaxQuant when the cohort is unlabeled DDA and MaxLFQ is the intended protein matrix. Prefer DIA-NN when the cohort is unlabeled DIA. Prefer TMT when a closed plex and same-run comparison fit better. Prefer MRM or PRM with SIS when absolute units for a shortlist are required.
Researchers comparing label-free design trade-offs can also refer to What Is Label-Free Quantification in Proteomics? and Advantages and Disadvantages of Label-Free Quantitative Proteomics.
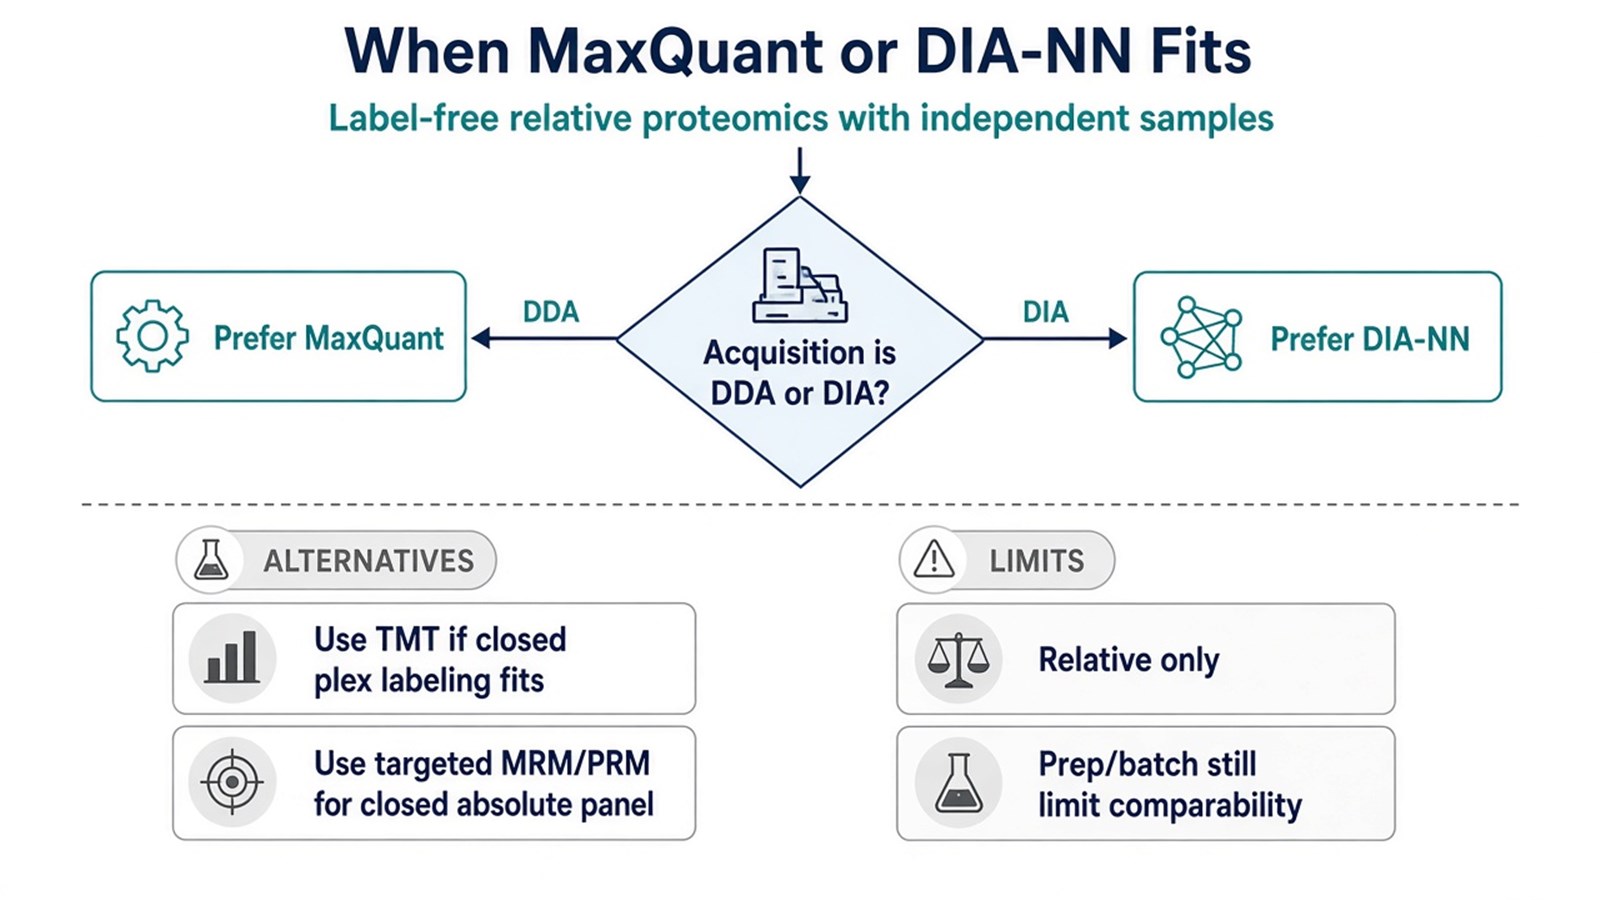
Figure 3. Tool choice follows sample preparation and acquisition: MaxQuant for DDA-LFQ, DIA-NN for DIA; other claims need other methods.
Limits and Application Boundaries
Neither tool invents absolute protein amounts. MaxQuant MBR and DIA-NN library strategies can improve matrix completeness and can also propagate error if QC is weak. Software speed or neural-network scoring does not override poor digestion, column changes mid-cohort, or confounded run order. Diagnostic cutoffs sit outside ordinary discovery LFQ reporting unless a separately validated assay framework is in place.
Typical applications are treatment or genotype screens, tissue-state comparisons, and clinical or preclinical discovery cohorts that keep samples independent and unlabeled. Pathway enrichment on the resulting candidate list reflects overrepresentation relative to a quantified background. It does not prove pathway activity.
Once the sample set, acquisition mode, and relative comparison design are defined, the project can be evaluated as a label-free MaxQuant or DIA-NN analysis. Researchers can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for sample evaluation, feasibility assessment, and workflow planning. For DIA-centered offerings, see Label-Free DIA Quantitative Proteomics.
Frequently Asked Questions
1. Does sample preparation differ between MaxQuant and DIA-NN projects?
Core label-free chemistry is shared: independent unlabeled digests with matched cleanup. The divergence is acquisition (DDA vs DIA), which then selects the software.
2. Can MaxQuant analyze DIA files as its main LFQ path?
MaxQuant is primarily established for DDA-centric workflows and MaxLFQ. DIA cohorts are typically analyzed in DIA-dedicated tools such as DIA-NN.
3. Does DIA-NN remove the need for careful sample prep?
No. Library-free search removes some library logistics. Digestion quality, loading, chromatography, and batch design still limit relative comparability.
4. Are MaxQuant and DIA-NN absolute quantification tools?
No. Ordinary outputs are relative protein matrices. Absolute amount needs matched standards and a calibration model.
5. When should TMT replace a MaxQuant or DIA-NN LFQ plan?
When the contrast can be frozen in one labeling kit and same-run relative comparison is more important than independent sample enrollment.
Reference
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, N. Nagaraj, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031591
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
