



In label-free quantification (LFQ), choose data-independent acquisition (DIA) when relative unlabeled discovery needs scheduled-window fragment coverage and lower stochastic missingness across many independent liquid chromatography-tandem mass spectrometry (LC-MS/MS) runs. Choose data-dependent acquisition (DDA) when real-time top-N precursor selection, cleaner single-precursor MS2 spectra, or a matched DDA spectral library for later DIA are the priority. DDA-LFQ usually quantifies from MS1 peak areas such as MaxLFQ after peptide identification. Unlabeled DIA quantifies from fragment-ion chromatograms with library-based or library-free extraction (Gillet et al. 2012; Cox et al. 2014). Both support relative same-protein comparison inside one coherent plan. Neither reports absolute concentration by default, and neither replaces isobaric tandem mass tag (TMT) labeling when a closed multiplex kit is required.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service and Deep DIA Proteomics Service for project-specific feasibility and analysis planning.
DDA-LFQ vs DIA-LFQ at a Glance
Dimension |
DDA inside LFQ |
DIA inside LFQ |
|---|---|---|
Precursor selection |
Intensity-triggered top-N MS2 picks |
Fixed m/z windows fragmented each cycle |
Typical quantitative feature |
MS1 peak-area LFQ (e.g., MaxLFQ) |
Fragment-ion chromatograms |
MS2 character |
Often fewer co-fragmented precursors |
Multiplexed window spectra; interference risk |
Missing-value pattern |
More stochastic gaps across runs |
Often more complete matrices; still QC-dependent |
Software examples |
MaxQuant and related DDA-LFQ paths |
DIA-NN, Spectronaut, EncyclopeDIA-class tools |
Library role |
Can build empirical libraries for later DIA |
Library-based SWATH-style or library-free DIA |
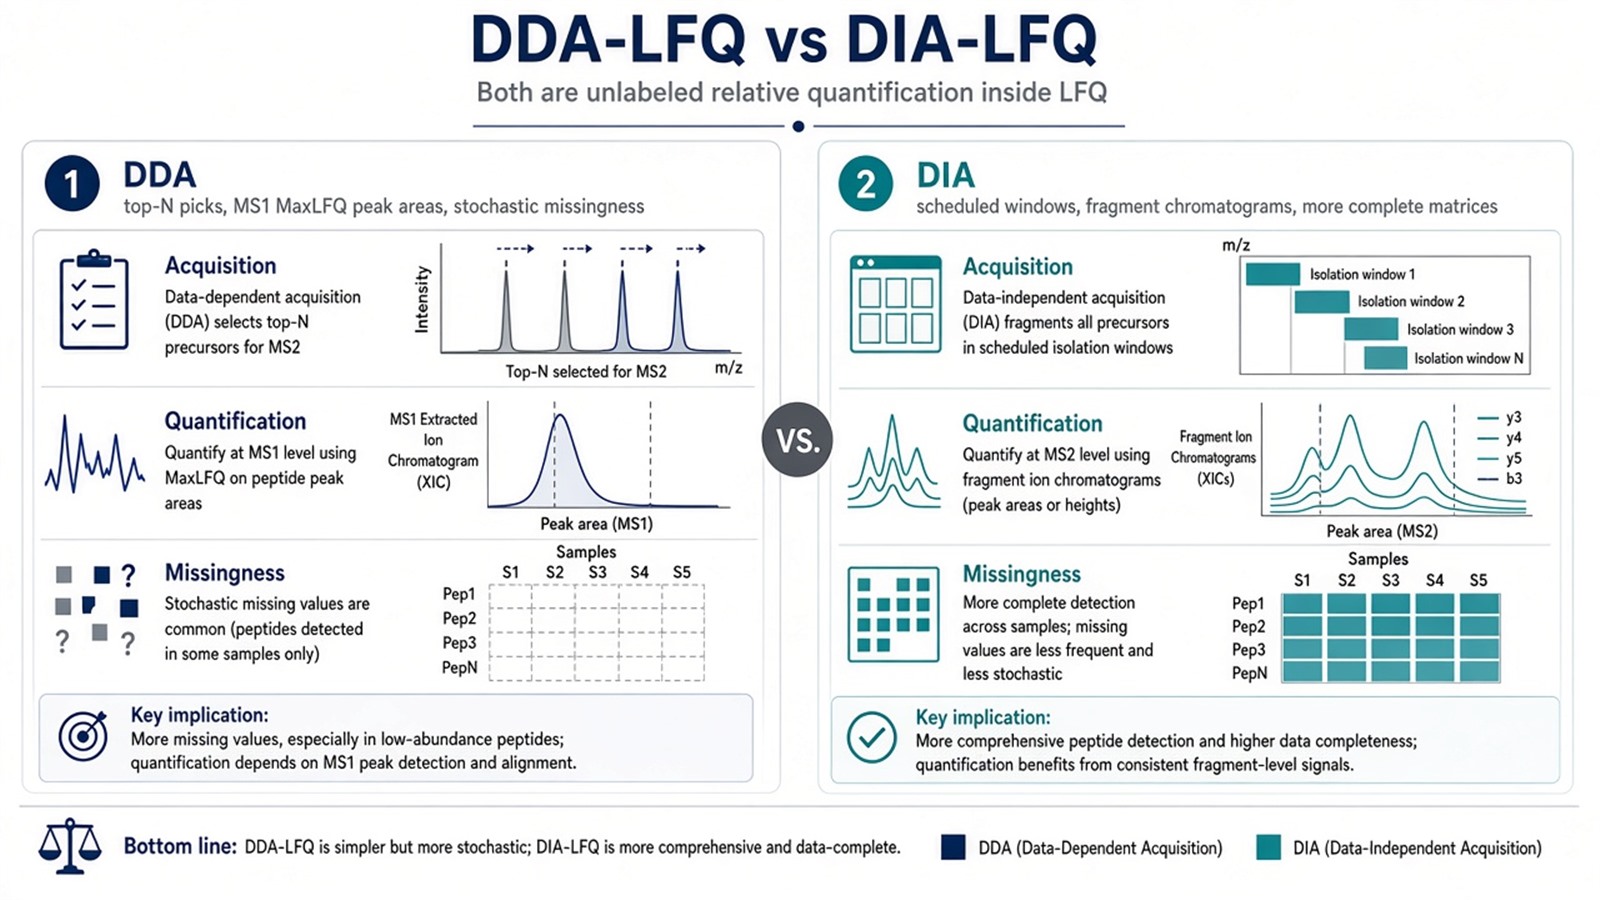
Figure 1. Within LFQ, DDA and DIA differ in precursor selection and which spectral features carry relative quantification.
Acquisition choice sits inside the unlabeled workflow; pick the selection logic that matches the cohort claim, not a universal ranking.
How Each Route Behaves in Label-Free Quantification
DDA-LFQ: identification-centric runs with stochastic depth
Each sample is injected separately. DDA surveys MS1, then fragments the most intense precursors. Identified peptides are quantified from aligned MS1 areas across runs. That path is mature for discovery statistics when normalization and run-order QC are controlled. High-abundance precursors are favored, so low-abundance peptides may appear in some runs and not others, which raises missing values in large matrices.
DIA-LFQ: scheduled coverage with software-dependent extraction
DIA fragments ions inside predefined windows on a fixed schedule, including SWATH-style sequential windows (Gillet et al. 2012). Peptides can be extracted even if they were never top-ranked in a given run. Matrices are often more complete, but window design, chromatography, and FDR-controlled extraction software become part of the method. Mixed spectra can still fail specific peptides despite the label-free DIA name.
For broader acquisition definitions beyond this LFQ-focused comparison, researchers can refer to DIA vs DDA Proteomics: Key Differences and Applications Explained and What Is DIA and SWATH? Understanding Data-Independent Acquisition in Proteomics?. For labeling versus unlabeled strategy stacks, see DDA vs. DIA vs. TMT in LC-MS/MS Proteomics: How to Choose the Right Strategy.
Judgment Criteria: Choosing DIA-LFQ or DDA-LFQ
Study need |
Prefer DIA-LFQ |
Prefer DDA-LFQ |
Reassess both |
|---|---|---|---|
Cohort quantification |
Lower stochastic missingness across many runs |
Pilot ID or library-first design |
Absolute concentration required |
Spectral priority |
Fragment chromatogram completeness |
Cleaner MS2 for confident identification |
Closed peptide panel for PRM/MRM |
Library logistics |
Empirical library ready, or library-free DIA planned |
Build a matched DDA library for later DIA |
Unmatched library with no library-free path |
Sample complexity |
Complex digests needing consistent coverage |
IP or interactome samples needing clear MS2 |
TMT multiplex fits better than any LFQ route |
Analysis tooling |
DIA pipeline and QC already chosen |
MaxQuant-centered DDA-LFQ plan in place |
No stable batch or normalization plan |
Prefer DIA-LFQ when the project is relative unlabeled discovery and scheduled-window completeness is the scarce resource. Prefer DDA-LFQ when identification clarity, MaxLFQ workflows, or spectral-library construction dominates. Prefer a DDA library followed by DIA quantification when library quality and cohort throughput must both be planned explicitly. Prefer PRM or MRM when targets are closed.
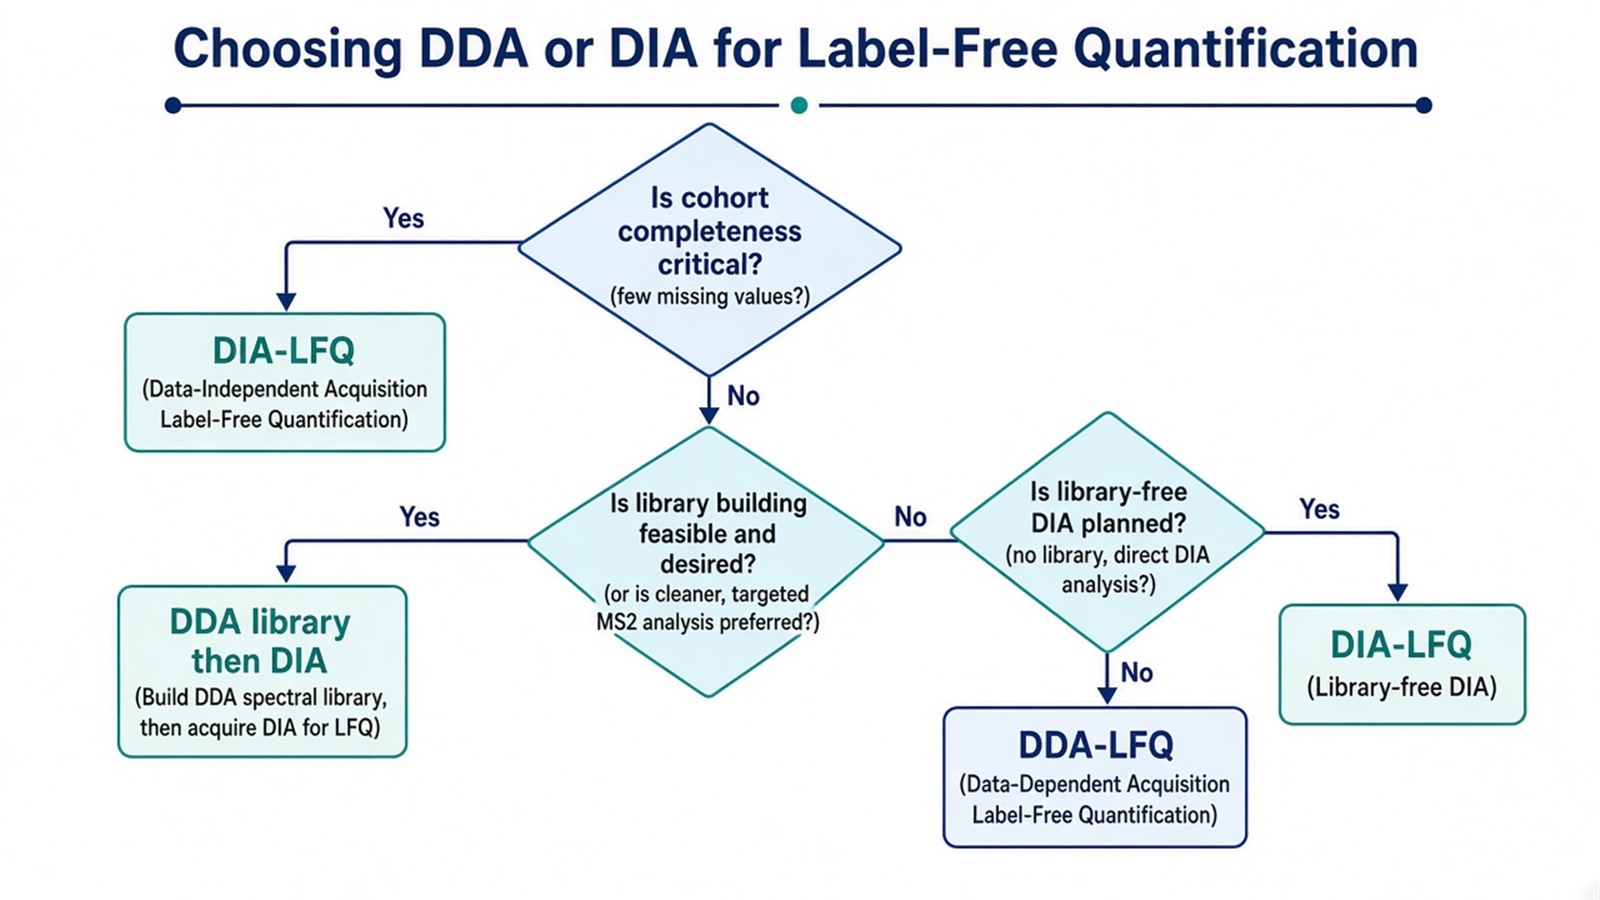
Figure 2. Label-free acquisition selection starts from missing-value tolerance, spectral needs, and library or library-free tooling.
For normalization choices that affect both routes, see How to Normalize Data in Label-Free Quantitative Proteomics?. For software depth, see Essential Analysis Tools for Label-Free Proteomics: A Comprehensive Review of MaxQuant and DIA-NN. For library-free DIA inside LFQ, see Direct DIA: High-Efficiency Proteomics without a Spectral Library and Label-Free DIA Quantitative Proteomics.
Limits and Application Boundaries
DIA-LFQ does not remove window interference or guarantee every protein is measured. DDA-LFQ does not remove stochastic missingness or batch drift across independent injections. Calling either universally more accurate overstates method class alone. Ordinary intensities from both routes remain relative unless matched standards and calibration are added. Cross-batch comparability needs design and QC, not only the DIA or DDA name.
Typical label-free applications:
- DDA-LFQ: novel-matrix identification, interactome or immunoprecipitation studies needing clearer MS2, and cohorts centered on MaxLFQ-style plans.
- DIA-LFQ: treatment or genotype screens, larger unlabeled cohorts, complex-matrix relative discovery, and projects that may re-extract stored files under updated libraries or search settings.
- Combined path: DDA spectral library construction on matched material, then DIA-LFQ quantification across the cohort.
Diagnostic cutoffs sit outside ordinary research DDA-LFQ or DIA-LFQ reporting unless a separately validated assay framework is in place.
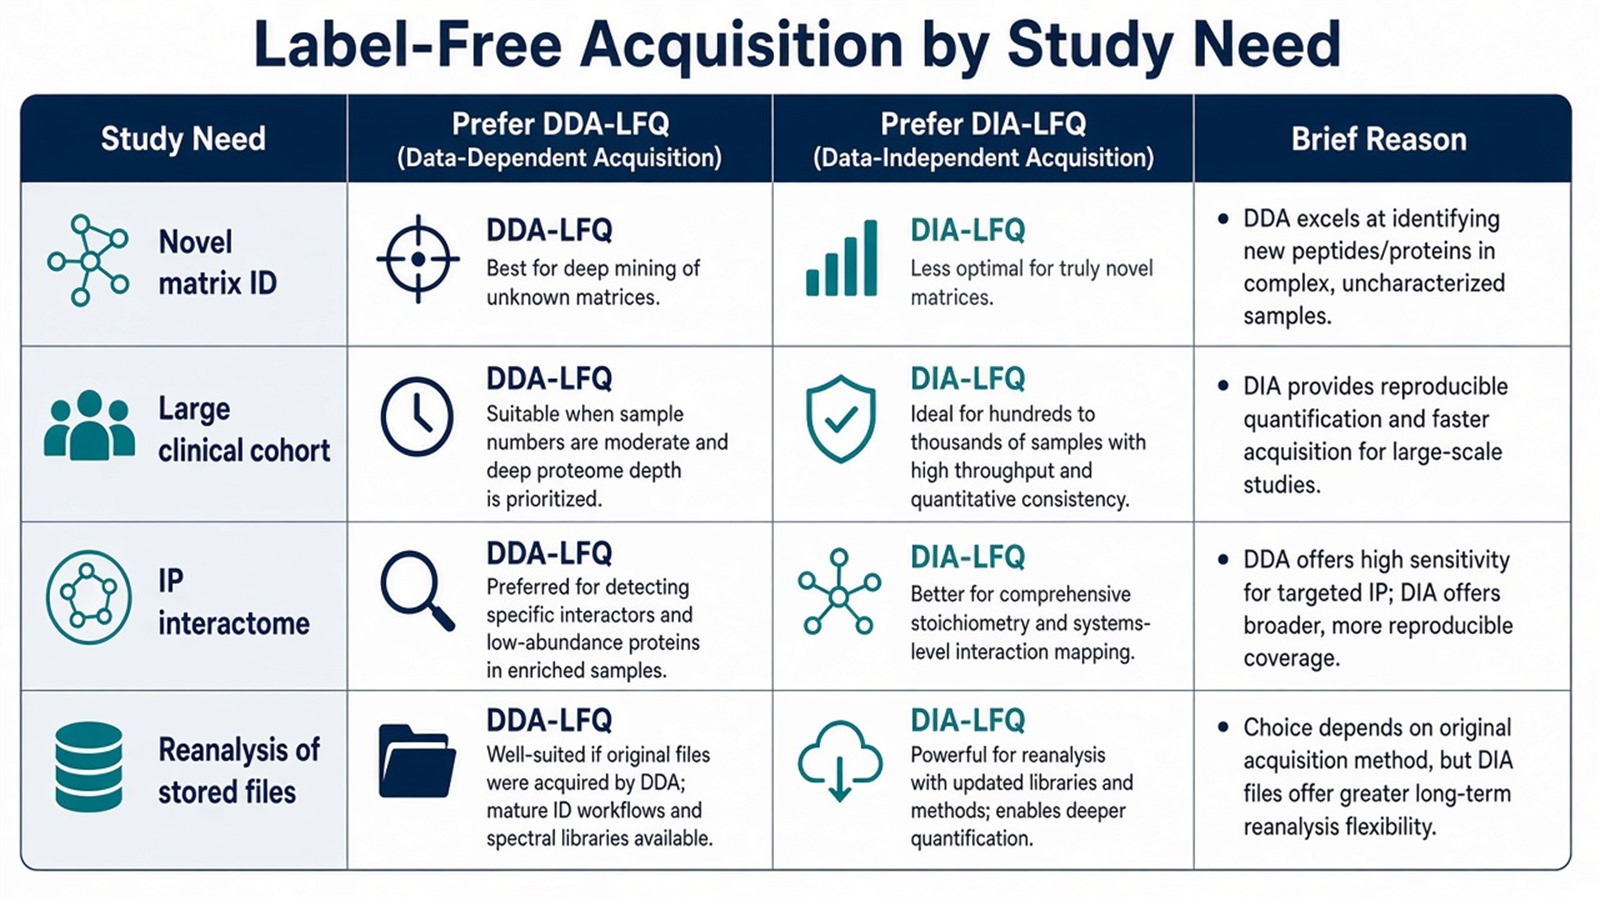
Figure 3. Match label-free acquisition to the study need: DDA-LFQ for identification-centric paths, DIA-LFQ for cohort completeness when tooling supports it.
Once digestion consistency, acquisition mode, normalization rules, and the relative comparison design are defined, the project can be evaluated as a DDA-LFQ or DIA-LFQ study. Researchers can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for DDA-LFQ planning and the Deep DIA Proteomics Service for unlabeled DIA options. For LFQ operations, see What Is Label-Free Analysis? LFQ Principles, Workflow, Advantages, and Limitations.
Frequently Asked Questions
1. Is DIA always better than DDA for label-free quantification?
No. DIA-LFQ often reduces stochastic missingness in large cohorts. DDA-LFQ can still fit identification-first work, MaxLFQ plans, and library building when QC is controlled.
2. Does label-free DIA still need a spectral library?
Some workflows use empirical DDA libraries or direct library-free extraction. The requirement follows the chosen DIA pipeline, not the word label-free alone.
3. Can DDA and DIA be combined in one LFQ project?
Yes. A common sequence is DDA on matched samples to build a library, then DIA-LFQ quantification across the cohort, or DIA discovery followed by PRM confirmation.
4. Is SWATH a separate method from DIA in LFQ?
SWATH-MS is one DIA implementation using sequential windows, commonly with library extraction. It is not a third class beside DIA and DDA.
5. Do DDA-LFQ and DIA-LFQ provide absolute protein concentration?
Not by default. Both report relative values inside a coherent plan unless matched standards and calibration are added.
Reference
- L.C. Gillet, P. Navarro, S. Tate, et al. (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.M111.016717
- J. Cox, M.Y. Hein, C.A. Luber, et al. (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031591
