



Most DIA proteomics data-analysis failures come from five places: using a spectral library that does not match the cohort, treating identification counts as proof of quantitative quality, applying normalization or missing-value rules without a design assumption, leaving software versions unlocked, and reading differential lists without QC for batch, missingness, and interference. Data-independent acquisition (DIA) can improve matrix completeness relative to stochastic data-dependent acquisition (DDA), but it does not remove window interference or create absolute protein amounts. SWATH-MS is one library-oriented DIA implementation, not a separate labeling chemistry and not a synonym for every modern DIA pipeline. Avoid the pitfalls by declaring the extraction route, locking the analysis record, and checking QC before biological interpretation.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Deep DIA Proteomics Service for project-specific feasibility and analysis planning.
What DIA Data Analysis Is Responsible For
DIA fragments precursors in scheduled m/z windows and recovers peptide quantities from extracted fragment-ion chromatograms (Gillet et al. 2012). The analysis task is to turn those chromatograms into a protein matrix that can support a relative comparison across independently injected samples that share one coherent chromatographic and processing plan.
Analysis does not repair failed digestion, confounded injection order, or undeclared batch structure. It also does not convert DIA intensities into calibrated concentrations. Ranking proteins by molar amount, transferring a fold change across incompatible software versions, or equating a large identification list with a trustworthy differential call are outside what the analysis step can defend.
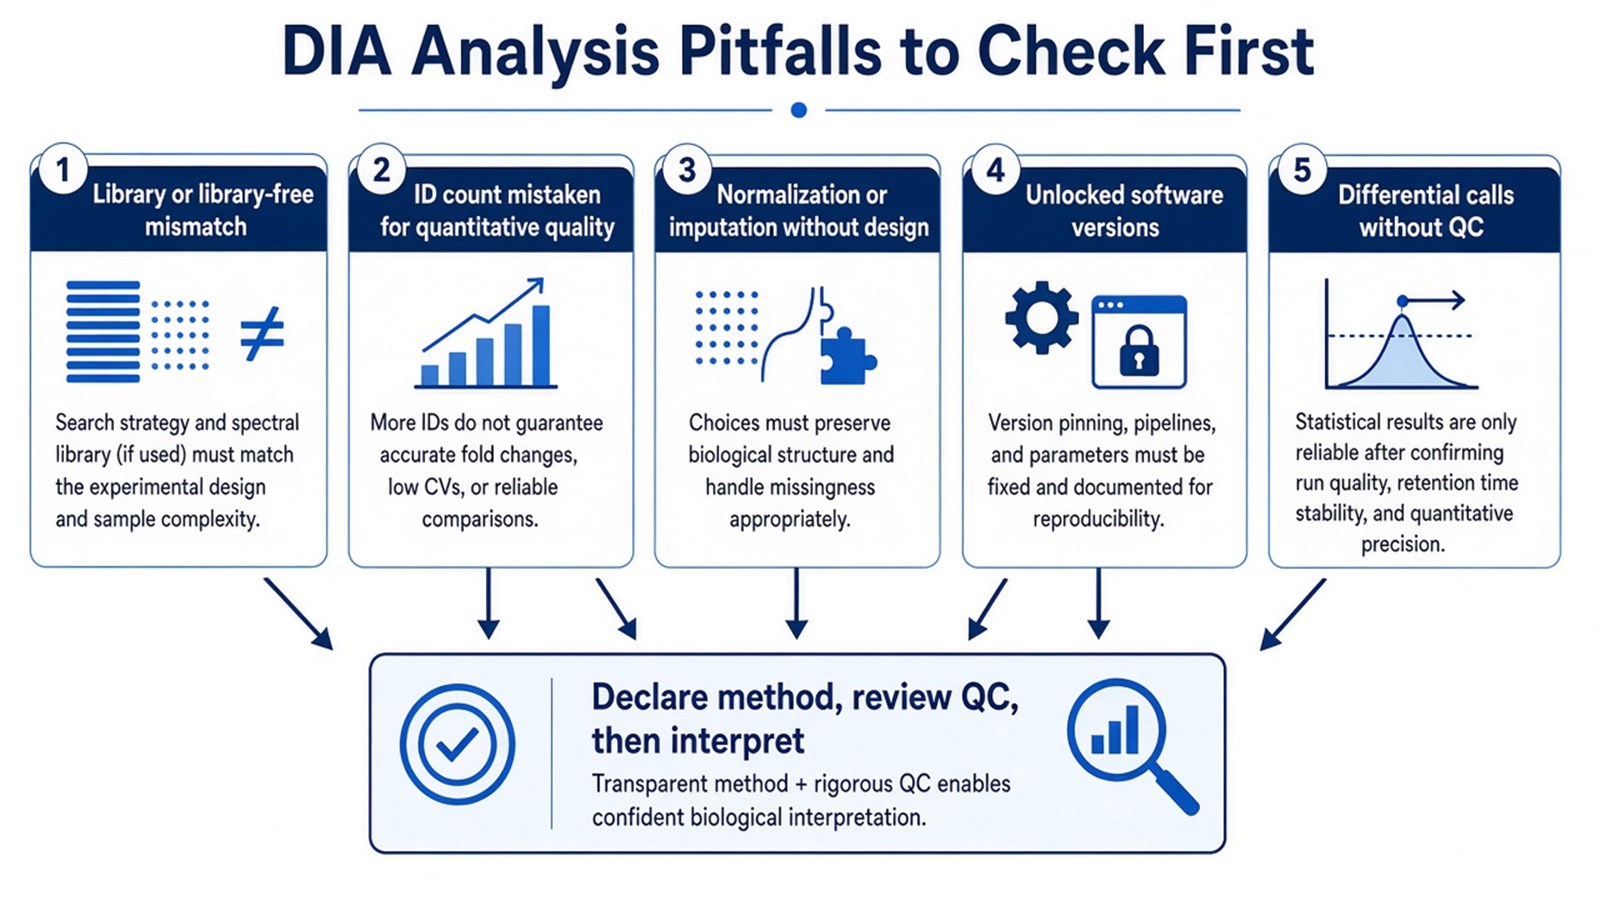
Figure 1. DIA analysis troubleshooting usually starts with library strategy, quantitative QC, normalization design, software lock-in, and differential review order.
A reproducible DIA table is a declared extraction and QC record, not the largest protein count the software can print.
Pitfall 1: Library Strategy That Does Not Match the Cohort
Many SWATH-style and related DIA workflows extract transitions against a spectral library. If that library was built from unmatched tissues, stale DDA batches, or incomplete fractionation, DIA coverage and quantitative assignments inherit those gaps. Library-free or direct-DIA search routes avoid that dependency, but they still require false discovery rate (FDR) control, retention-time handling, and interference review (Demichev et al. 2020).
Avoidance is operational. Declare whether the project is library-based or library-free. If a library is used, document its sample origin, acquisition method, and version. Do not mix incompatible library formats across tools without a validated conversion path. Naming SWATH does not specify window width, instrument, or whether a library-free alternative would have been a better match.
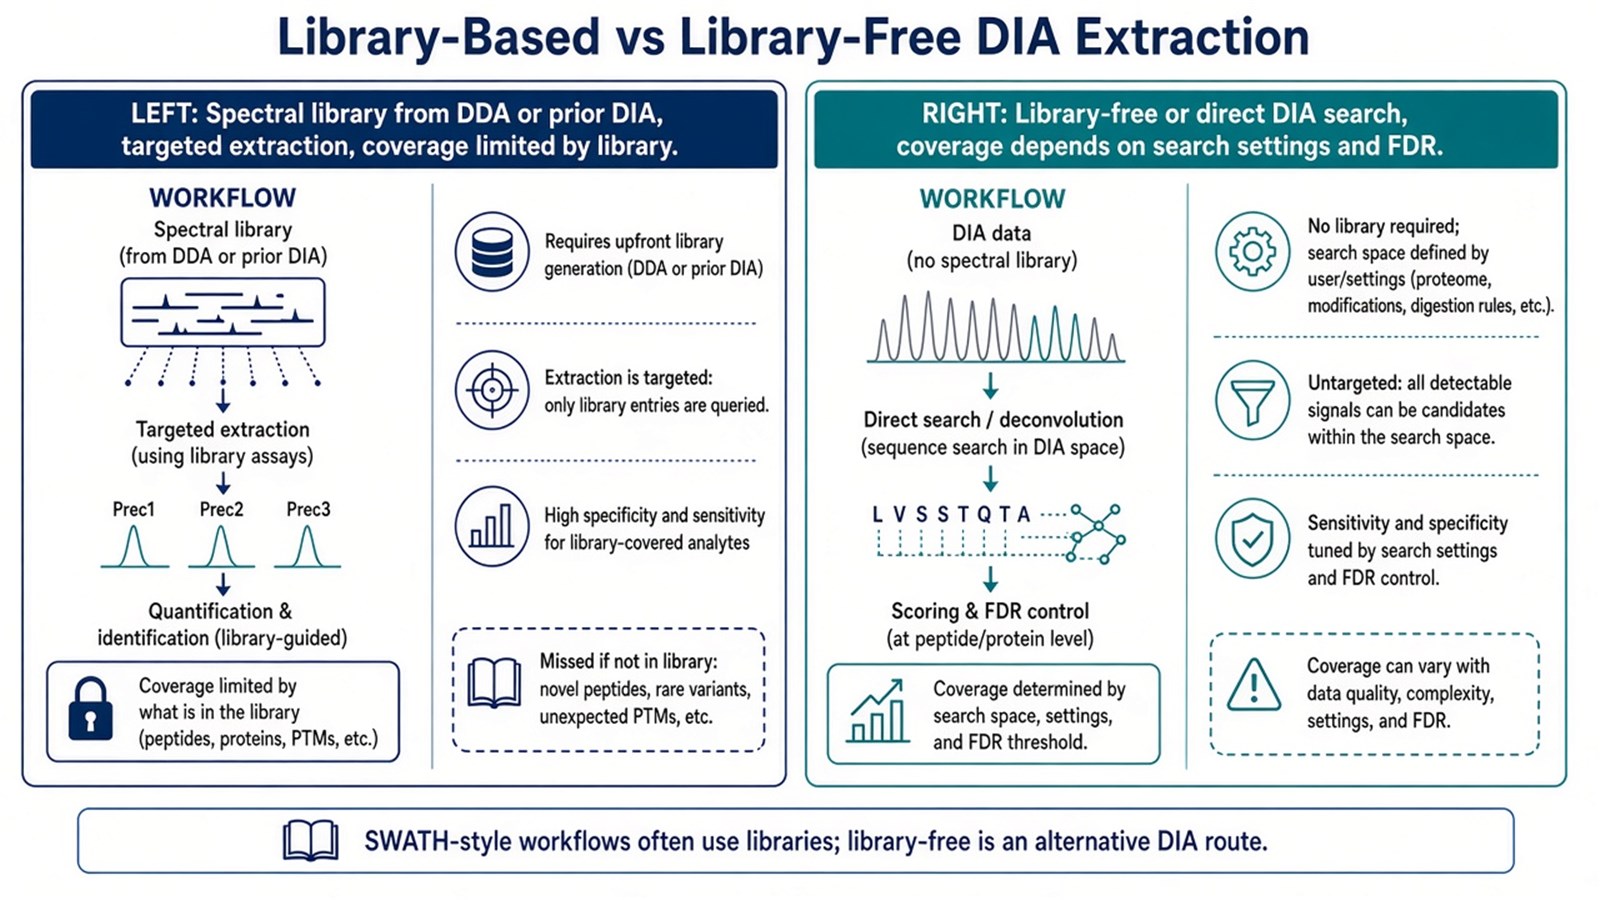
Figure 2. Library-based DIA coverage is bounded by the library; library-free search shifts the burden to search settings and FDR, and SWATH-style work commonly follows the library route.
Researchers who need SWATH-centered acquisition and extraction concepts can refer to Principles and Workflow of DIA Proteomics: A Case Study of SWATH-MS.
Pitfall 2: Treating Identification Depth as Quantitative Quality
A high peptide or protein count can still include unstable peak groups, interfered transitions, and entries that fail replicate consistency. Reporting depth without coefficient of variation (CV) summaries, missingness patterns, or dynamic-range context invites overinterpretation. Depth and quantitative usability are related outputs, not the same claim.
Avoidance means separating totals. Report identified proteins, proteins that pass quantitative filters, and the QC metrics used to accept those filters. High CV or sparse detection in one group should trigger review or exclusion before pathway language is written. Targeted follow-up such as parallel reaction monitoring (PRM) can test a short candidate list; it does not validate the entire DIA matrix.
Pitfall 3: Normalization, Imputation, and Batch Correction Without Design
Independent DIA runs still carry loading and instrument-scale differences. Normalization rescales intensities under an assumption about which signals are technical. Imputation fills missing cells with a model. Batch correction can remove acquisition-date structure, and it can also remove biology if phenotype and batch are aligned.
Avoidance starts from design. Randomize groups across run order when possible. Choose normalization after stating whether a global abundance shift is expected. Treat missingness as informative when low-abundance peptides drop out systematically. Apply batch models only when batch is recorded and not perfectly confounded with the contrast. Default software settings are not a substitute for those decisions.
Pitfall 4: Unlocked Software Versions and Mixed Pipelines
Spectronaut, DIA-NN, Skyline, and related tools change scoring, FDR behavior, and report formats across versions. Mixing outputs from incompatible workflows, or reanalyzing one cohort with an undocumented upgrade, breaks comparability. Format mismatches between library and extraction tools create silent assignment errors.
Avoidance is documentation. Lock software version, parameters, library identity, and FDR thresholds in the methods record. Prefer one coherent pipeline per study block. If a reanalysis is required, state what changed and whether previous conclusions still hold under the new settings.
Pitfall 5: Differential Calls Without QC Context
P-value or fold-change cutoffs alone do not prove that a protein change is supported by clean transitions, adequate peptide evidence, and stable chromatography. Enrichment analysis on an unchecked candidate list can amplify noise into a pathway story.
Avoidance restores order. Inspect intensity distributions, missingness, and principal component analysis (PCA) for batch-versus-biology structure before ranking candidates. Require peptide-level support and consistent direction across biological replicates for claims that will enter the paper. Multi-omics agreement can strengthen interpretation when sample identity aligns; it is not a repair for a poorly filtered DIA table.
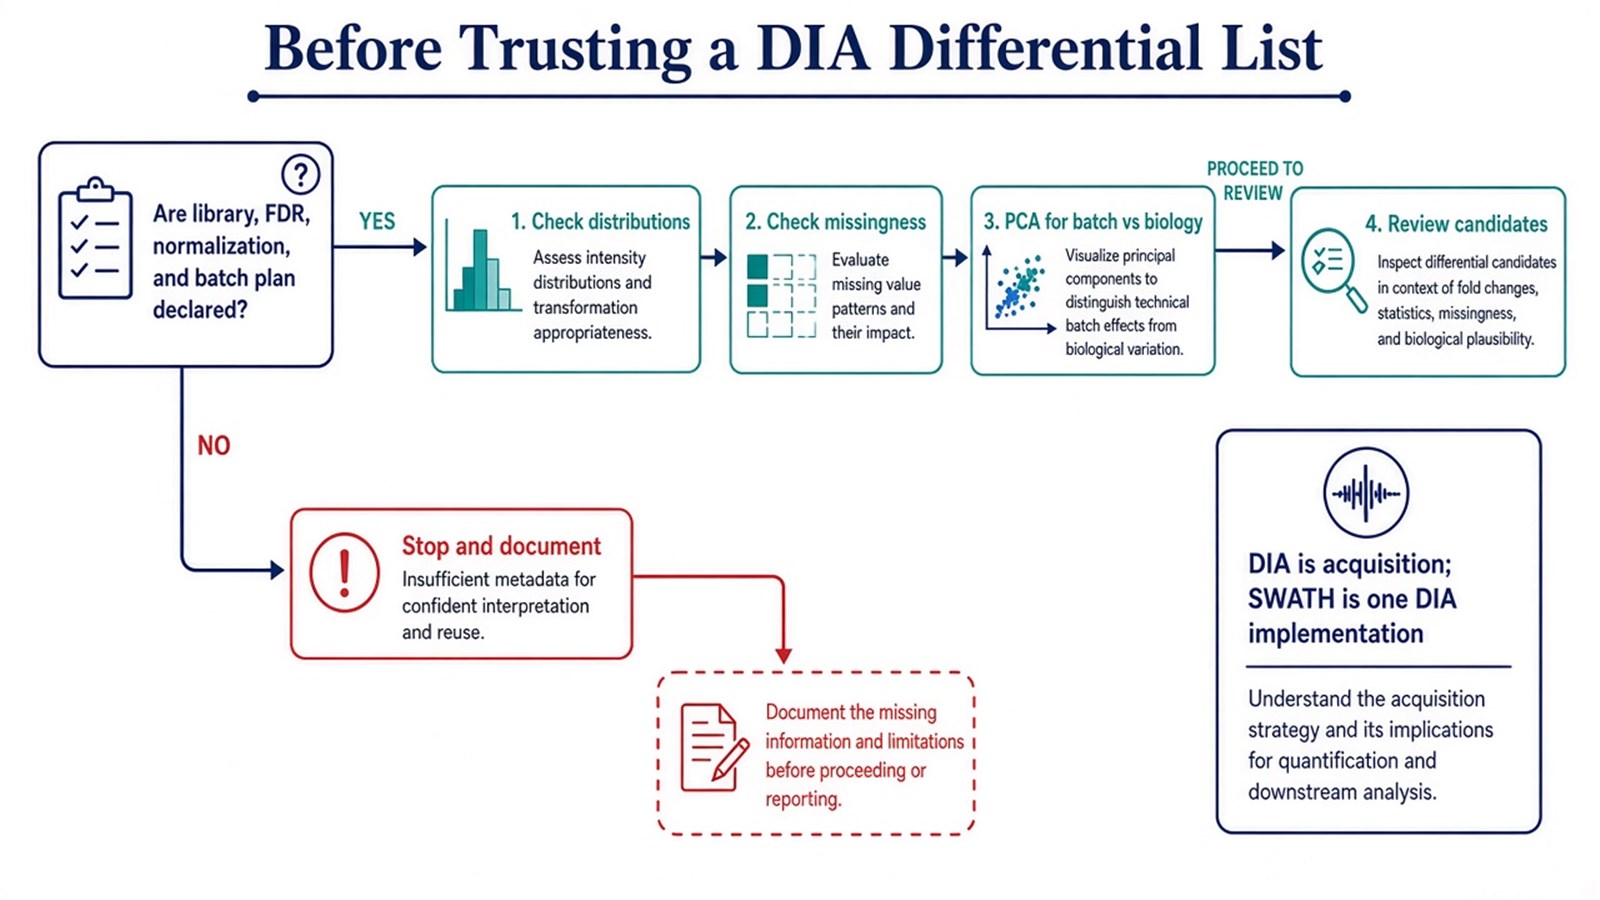
Figure 3. A DIA differential list should be read only after method declaration and QC checks separate technical structure from the biological contrast.
DIA and SWATH Judgment Limits Around Analysis
DIA is an acquisition class. SWATH-MS is one sequential-window, often library-driven implementation inside that class (Gillet et al. 2012). Platform-specific unlabeled DIA routes, including Astral-class narrow-window methods, change speed and window practicality, but they still need the same analysis discipline: declared extraction, FDR, normalization, and QC.
Analysis decision |
Safer practice |
Reassess if |
|---|---|---|
Extraction route |
Match library-based or library-free choice to cohort and software |
Library origin does not match samples |
Quality metric |
Pair ID depth with quantitative filters and CV or missingness review |
Only protein counts are reported |
Scaling |
Normalize under a stated assumption; document imputation |
Global biology is forced to equal totals |
Reproducibility |
Lock versions and parameters |
Tools or formats are mixed mid-study |
Interpretation |
QC first, then differentials and enrichment |
Pathway language precedes QC |
For platform-level DIA framing beyond analysis pitfalls, researchers can also review Astral DIA: Accurate and Efficient Quantitative Proteomics Solution.
Application Contexts Where These Pitfalls Matter Most
Large clinical or multi-batch cohorts amplify library mismatch and batch confounding. Time-course studies amplify drift if run order tracks treatment. Complex biofluids amplify interference inside wide windows, so transition review becomes more important than raw depth. In each setting, the analysis report should make the extraction route and QC acceptance rules readable to a reviewer.
Once the unlabeled DIA plan, library or library-free strategy, and QC gates are defined, the project can be evaluated as a DIA study with a documented analysis path. Researchers can review the MtoZ Biolabs Deep DIA Proteomics Service for sample evaluation, feasibility assessment, and workflow planning.
Frequently Asked Questions
1. What should be checked first when a DIA result looks unstable?
Check whether the library or library-free route matches the cohort, whether software versions are locked, and whether PCA or distributions show batch or loading structure before revisiting fold-change cutoffs.
2. Is a DDA spectral library required for every DIA project?
No. Many SWATH-style workflows use libraries, but library-free DIA search is a valid alternative when FDR and interference control are declared.
3. Does a larger DIA protein list mean better quantification?
No. Identification depth and quantitative usability are separate. Filter by evidence quality, missingness, and replicate consistency before interpretation.
4. Can normalization and imputation fix a confounded acquisition design?
No. They can reduce technical scale differences. They cannot legitimately separate biology from batch when the two are perfectly aligned.
5. Is SWATH a different data-analysis problem from other DIA methods?
SWATH names a common library-oriented DIA acquisition and extraction tradition. The core analysis pitfalls, library match, FDR, normalization, version lock-in, and QC before differentials, still apply across DIA implementations.
Reference
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
