What Is PPI Prediction?
PPI prediction is a computational inference: existing sequence, structure, network, or experimental records are used to rank whether two proteins are likely to interact. The output is a scored or ranked pair list for the samples that will be tested next. Proteins act mainly through coordinated assemblies in signaling, metabolism, immune responses, and many disease-associated processes. Exhaustive wet-lab testing of all pairwise combinations is not practical, which is why prediction is used to complement incomplete experimental catalogs and to decide which pairs or baits to clone next. Resource efficiency follows when the ranked list is treated as a shortlist that then enters a matched assay.
Prediction therefore sits upstream of, or beside, yeast two-hybrid (Y2H), co-immunoprecipitation–mass spectrometry (Co-IP-MS), affinity purification–mass spectrometry (AP-MS), and crosslinking mass spectrometry (XL-MS). Those assays still report their own physical events and still need their own controls.
Laboratories with a predicted pair list, a bait to test, or a project objective can also review the MtoZ Biolabs Protein-Protein Interaction Analysis Service for project-specific feasibility and analysis planning.
What PPI Prediction Reports
A predictor can return a likelihood, a rank, a docked pose, or a missing-edge score on a graph. That output can inform which pairs enter a screen. A cellular complex, a drug-interface starting point, or a functional role is then assigned when a matched experiment supports that sentence. For how prediction and measurement should be looped rather than ranked by abstract accuracy, Experimental vs Computational Methods for Protein Interaction Detection provides a more detailed comparison of reporting paths.
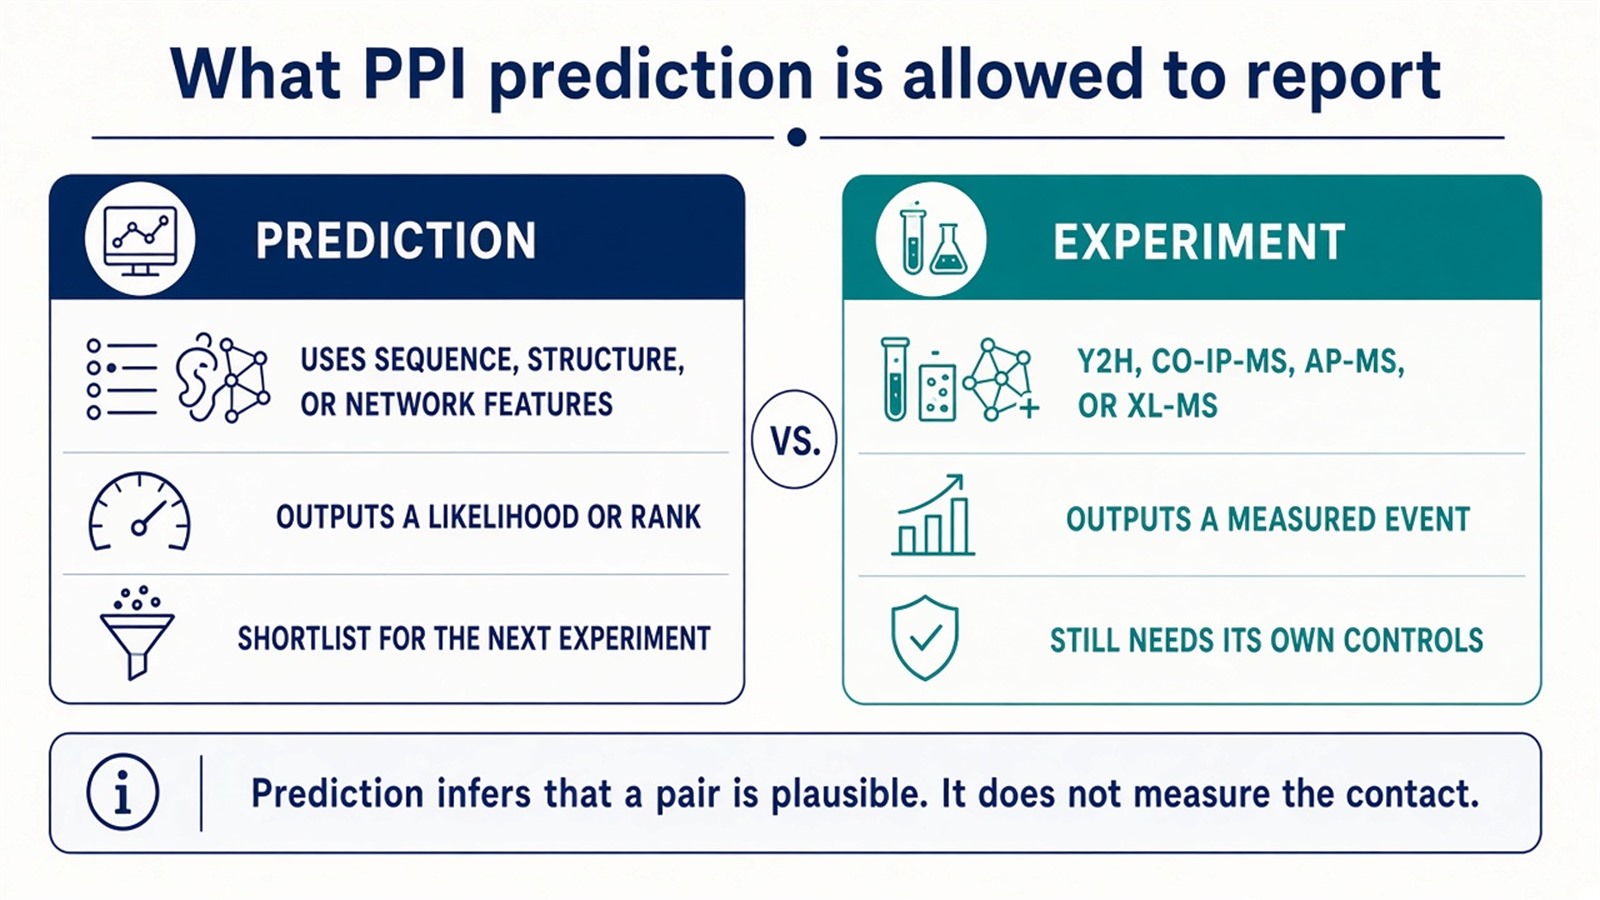
Figure 1. Prediction ranks plausible pairs from sequence, structure, or network features. Experiment still has to measure Y2H, Co-IP-MS, AP-MS, or XL-MS events.
Prediction infers that a pair is plausible. Y2H, Co-IP-MS, AP-MS, or XL-MS then measure the nominated contact.
Basic Principles and Classification of PPI Prediction
1. Sequence-based methods
These models use the amino-acid sequence only.
Homology inference transfers a known interaction to proteins that look like a documented pair. Transfer quality follows alignment coverage and whether the interface residues are conserved.
Co-evolution analysis looks for coordinated residue changes between two proteins. Co-variation can flag a contact. It can also reflect shared phylogeny or shared expression rather than binding.
Feature-based machine learning extracts composition, hydrophobicity, polarity, or conservation and trains a support-vector machine or random forest. The model learns the training pairs and returns a score on new pairs.
2. Structure-based methods
Predicted or experimental structures, including AlphaFold-class monomer models, feed docking and interface scans. Docking samples possible poses and scores them. Interface methods look for hydrophobic patches or charged patches that resemble known binding surfaces.
A plausible pose is a structural hypothesis for the pair. AlphaFold-Multimer can propose complex geometry. The proposal remains a model until the pair and the site are measured.
3. Network inference and database-driven methods
STRING, BioGRID, and IntAct supply prior edges. Guilt-by-association argues that proteins sharing partners are more likely to associate, directly or indirectly. Graph embeddings and graph neural networks encode those graphs and score missing edges.
The prediction inherits the graph’s errors. Text-mined STRING channels and incomplete negative sets both propagate. Degree or betweenness on the same graph is not independent evidence. For how those databases should be drawn as overlays, Protein-Protein Interaction Mapping Methods and Applications provides a more detailed discussion of evidence layers.
4. Deep learning and protein language models
Transformer protein language models such as ESM and ProtBERT learn contextual sequence embeddings. Graph neural networks can add network context. Multimodal models fuse sequence, structure, annotation, and expression.
These architectures can reduce hand-built feature lists on some benchmarks. They remain one scoring route beside feature-based methods, and interpretability still depends on how the model is inspected. A fused score is still a score used to rank pairs for follow-up.
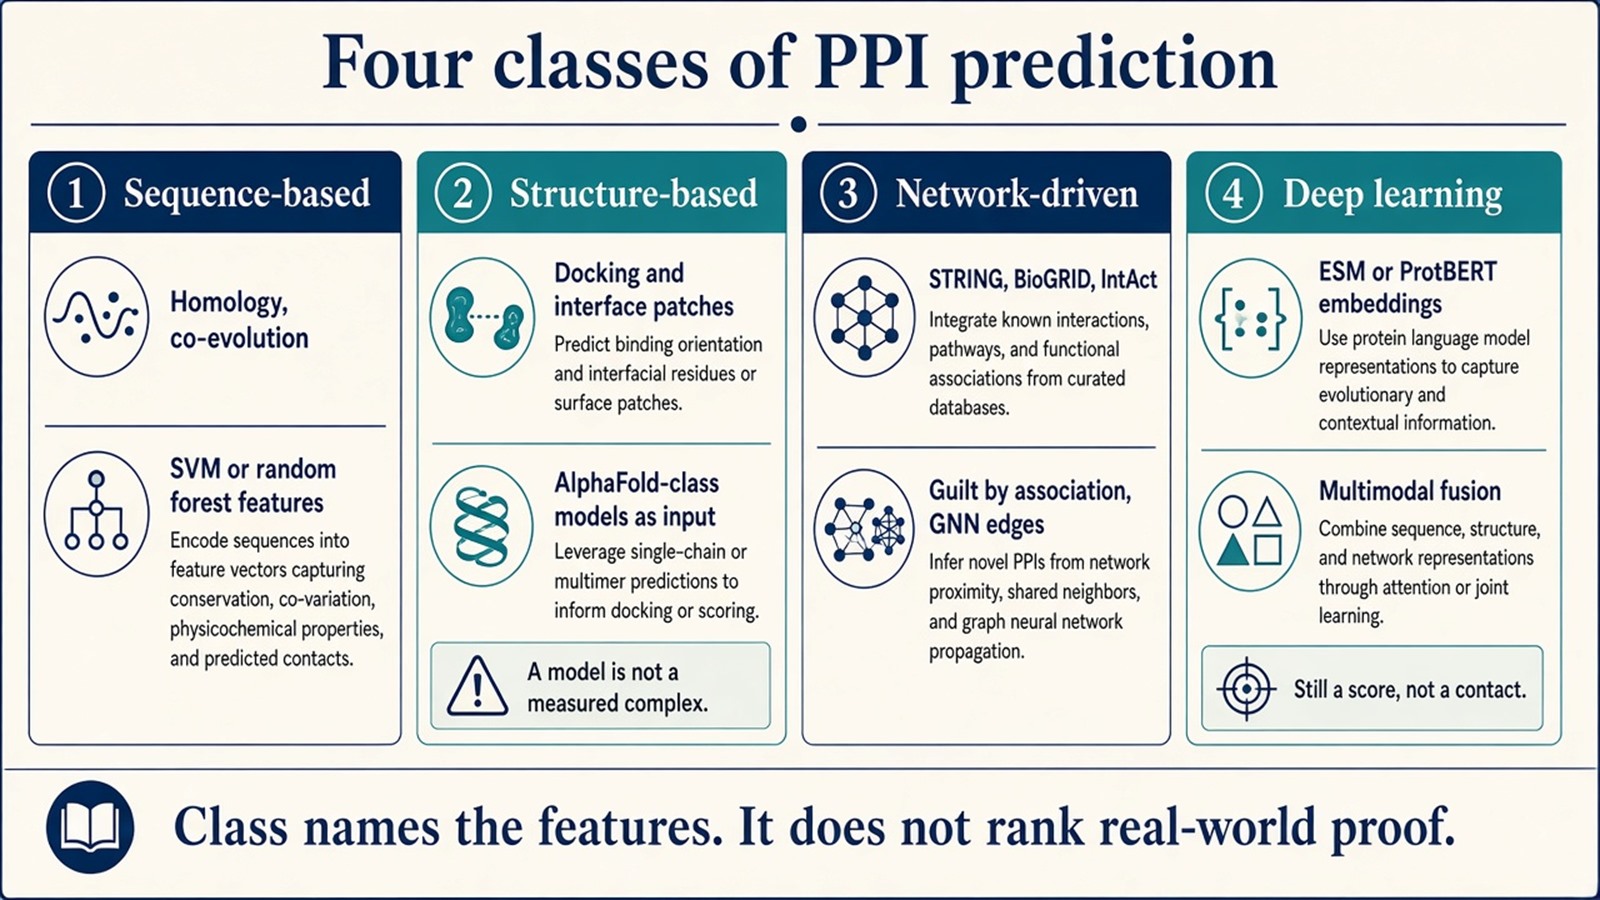
Figure 2. Prediction classes differ by input features. The class name identifies the features used to rank pairs.
Technical Challenges and Development Directions
1. Persistent challenges
True negative pairs are hard to define, so training sets are biased and reported metrics can look stronger than wet-lab follow-up. Models trained on human or model-organism edges often lose performance in other species. Database entries with unclear provenance inflate false positives. Sequence and structure scores also omit functional context: a predicted pair can be structurally plausible and still unused in the cell state under study.
2. Directions, not current defaults
Multimodal integration of proteomic or transcriptomic covariates is being tested to add biological context. AlphaFold-Multimer-class models make interface hypotheses more available for multi-protein assemblies. Individual-specific or “precision medicine” PPI maps remain a research direction, not a reporting framework for ordinary studies. Explainable architectures are being developed because many current deep models are hard to inspect.
How Predicted Pairs Should Be Closed Experimentally
A usable prediction project names the model class, the training bias, and the first assay that will test the top pairs. MtoZ Biolabs scopes complementary measurement on selected nominations:
- Co-IP-MS identifies proteins that remain with an antibody-captured bait after a stated wash.
- AP-MS builds a control-filtered neighborhood around a tagged bait.
- XL-MS assigns spatially proximal residues when the pair or complex is already closed enough to crosslink.
PRM or MRM can quantify a nominated protein in an eluate or digest. Targeted quantification confirms that a protein is present at a reportable level. Interaction still requires an enrichment, pairwise, or crosslinking design that matches the next sentence.
For evidence-type limits on those mass spectrometry routes, How to Identify Protein–Protein Interactions Using Mass Spectrometry provides a more detailed explanation.
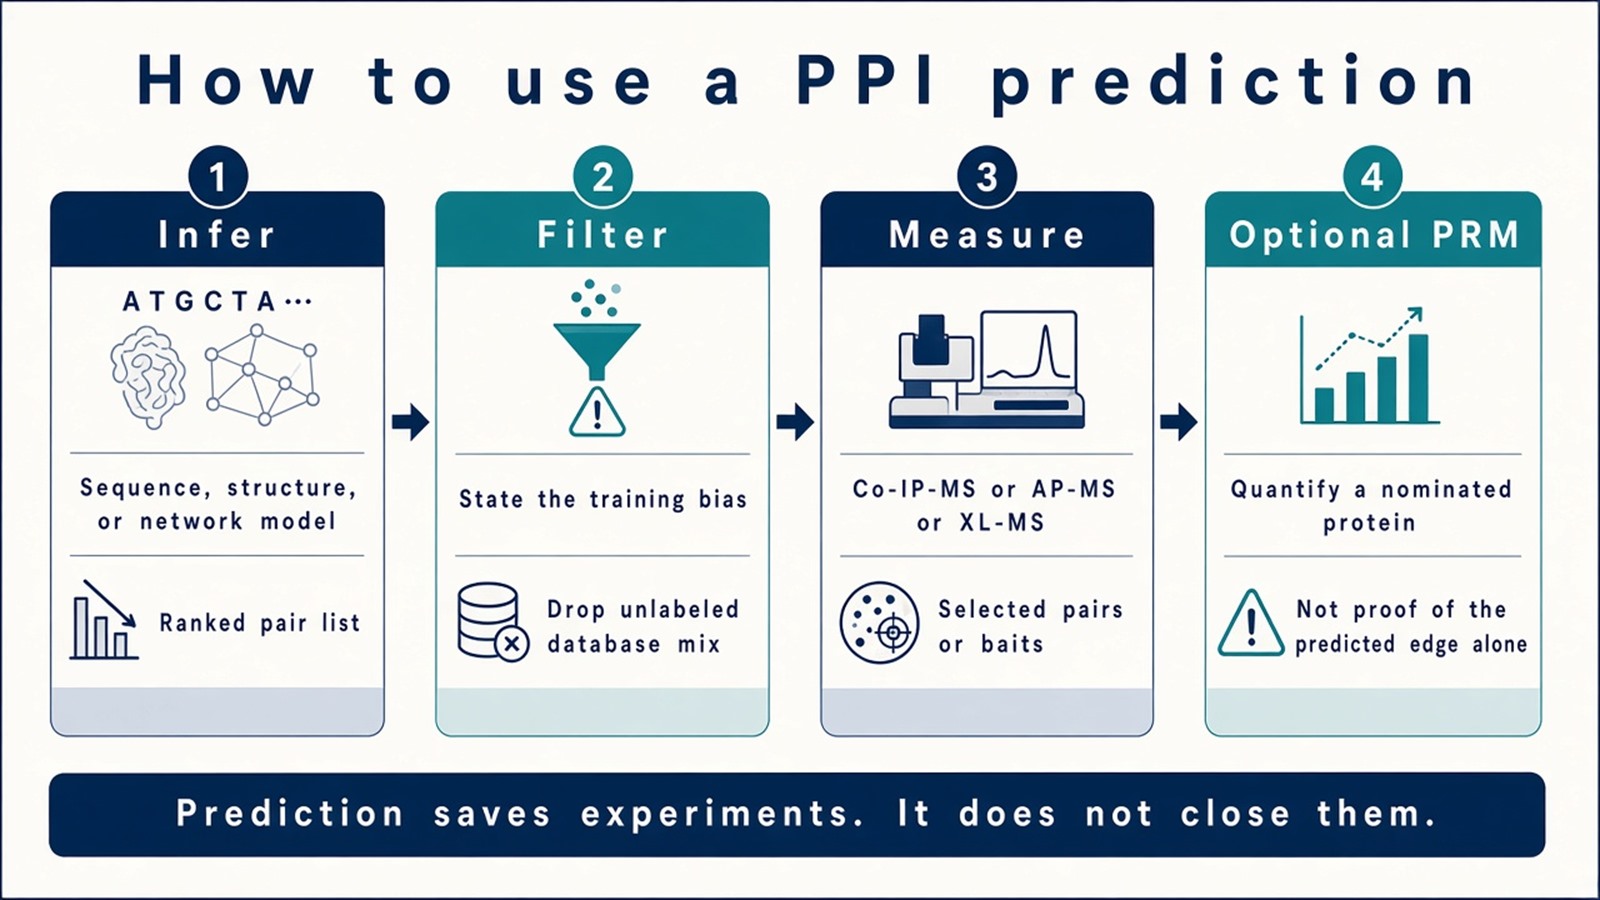
Figure 3. Prediction produces a ranked list; Co-IP-MS, AP-MS, or XL-MS measure selected pairs. PRM can quantify a nominated protein as a follow-up abundance check.
Prediction ranks experiments that can wait. The next sentence still comes from the assay chosen for those top pairs.
Project Planning and Service Scope
A usable plan names the protein pair space, the predictor class, how negatives were defined, and which orthogonal MS or pairwise assay will test the top hits. Homology transfer quality follows interface conservation. Docking returns a scored pose. Network models inherit the graph. Language models inherit the training pairs. MtoZ Biolabs scopes affinity-tag strategies, including FLAG, HA, Strep, and GFP, across common cell systems, Orbitrap-class LC-MS/MS for Co-IP-MS, AP-MS, or XL-MS, and optional PRM follow-up on nominated proteins. Recovery of a predicted partner still depends on whether that partner survives the chosen capture.
Once the predictor, shortlist rule, and measurement path are defined, the project can be scoped as a prediction-guided PPI study. Researchers can review the MtoZ Biolabs Protein-Protein Interaction Analysis Service for project-specific sample evaluation, feasibility assessment, and workflow planning.
Frequently Asked Questions
1. What does PPI prediction return?
It is a computational ranking of whether two proteins are likely to interact, based on sequence, structure, network, or mixed features. Wet-lab demonstration of the contact then uses Y2H, Co-IP-MS, AP-MS, or XL-MS on selected pairs.
2. How do AlphaFold or docking sit beside Co-IP-MS or AP-MS?
Structure models propose geometry. Enrichment assays report proteins recovered under a stated wash and control set.
3. How should a STRING or GNN score be used?
Those scores inherit database mix and graph bias. Sample-level evidence still needs an experimental assay.
4. How do deep language models sit beside classical sequence features?
They change how features are learned. Negative-sample bias and follow-up assay choice remain part of the project plan.
5. How can PRM or MRM support a predicted interaction?
PRM or MRM can quantify a nominated protein. Interaction still requires an enrichment, pairwise, or crosslinking design that matches the claim.
Reference
- Skrabanek L., Saini H.K., Bader G.D., Enright A.J. (2008). Computational prediction of protein-protein interactions. Mol. Biotechnol., 38, 1-17. https://doi.org/10.1007/s12033-007-0069-2
- Jumper J., Evans R., Pritzel A., et al. (2021). Highly accurate protein structure prediction with AlphaFold. Nature, 596, 583-589. https://doi.org/10.1038/s41586-021-03819-2
- Evans R., O'Neill M., Pritzel A., et al. (2022). Protein complex prediction with AlphaFold-Multimer. bioRxiv. https://doi.org/10.1101/2021.10.04.463034
- Szklarczyk D., Gable A.L., Lyon D., et al. (2019). STRING v11: protein-protein association networks with increased coverage, supporting functional discovery in genome-wide experimental datasets. Nucleic Acids Res., 47, D607-D613. https://doi.org/10.1093/nar/gky1131
- Rives A., Meier J., Guo T., et al. (2021). Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences. Proc. Natl. Acad. Sci. U.S.A., 118, e2016239118. https://doi.org/10.1073/pnas.2016239118
- Gingras A.C., Gstaiger M., Raught B., Aebersold R. (2007). Analysis of protein complexes using mass spectrometry. Nat. Rev. Mol. Cell Biol., 8, 645-654. https://doi.org/10.1038/nrm2208