Unlabeled Quantitative Proteomics
Unlabeled quantitative proteomics names relative protein measurement on digests that enter mass spectrometry without isobaric or metabolic discovery tags on separate liquid chromatography-tandem mass spectrometry (LC-MS/MS) injections. In quantitative proteomics portfolios, it sits beside labeled multiplex routes and targeted remeasurement assays. The usual discovery readout is label-free quantification (LFQ) from MS1 precursor areas or from unlabeled data-independent acquisition (DIA) fragment traces after false discovery rate (FDR) control (Bantscheff et al. 2012; Cox et al. 2014). The guide below integrates unlabeled quantitative proteomics as a project theme with workflow, parameters, limits, and route choice. It is not a reagent catalog, not an instrument model list, and not a turnkey promise that one platform covers every matrix without documented scope.
Unlabeled quantitative tables support relative change across predefined groups in one study. They do not report molar amount on named peptides, clinical cutoffs, or interaction proof without separate targeted or functional design (Gerber et al. 2003).
In MtoZ Biolabs offerings, unlabeled quantitative proteomics is scoped when contrast design, matched pretreatment, and declared LFQ or unlabeled DIA processing fit the cohort block described in the project record.
LFQ terminology appears in LFQ. Chemistry contrast appears in What Is Label-Free Analysis?.
What Unlabeled Quantitative Proteomics Covers in a Project Record
Four scopes belong in the brief and stay separated.
Chemistry scope is unlabeled on discovery injections: no TMT, iTRAQ, or SILAC tags on the main contrast path unless a separate labeled block is declared.
Acquisition scope covers DDA, unlabeled DIA, or SWATH-style window plans with templates locked across the cohort block.
Metric scope is usually intensity-based LFQ. Spectral counting from peptide identification counts can support coarse screens but is a weak primary metric for group fold changes when MS1 areas exist on the same files.
Statistics scope covers normalization, missing-value policy, protein rollup, and testing on frozen contrasts only.
Unlabeled quantitative proteomics is a relative discovery theme. It does not replace enrollment design, replicate planning, or a signed methods appendix.
Broader quantitative framing appears in Exploring Quantitative Analysis in Proteomics. Route axes appear in Protein Quantification Method.
Unlabeled Metrics and Acquisition Routes Within Quantitative Proteomics
Quantitative proteomics can share hardware while differing in chemistry and readout.
MS1 peak-area LFQ integrates precursor chromatograms after peptide identification in DDA. MaxLFQ-style rollup uses peptide ratio relationships after delayed normalization (Cox et al. 2014).
Spectral counting compares assigned MS/MS counts per protein. It correlates with abundance in simple mixtures but is easily biased in complex lysates and complex enrichment pulls.
Unlabeled DIA quantifies extracted fragment traces under unified FDR (Gillet et al. 2012). Pilots often compare DDA missingness against DIA completeness before cohort scale.
Targeted parallel reaction monitoring (PRM) or stable isotope-labeled internal standard (SIS) assays are quantitative proteomics follow-ups, not synonyms for open unlabeled discovery.
Labeled TMT or SILAC blocks belong in the same quantitative proteomics map when multiplex or metabolic encoding fits enrollment.
Method survey appears in Mass Spectrometry-Based Quantitative Proteomics: Labeled and Label-Free Quantification Strategies. DIA depth appears in Label-Free DIA Quantitative Proteomics.
End-to-End Workflow for Unlabeled Quantitative Proteomics
A practical unlabeled quantitative spine usually runs as follows.
- Confirm matrix, contrast, relative claim, and whether DDA LFQ or unlabeled DIA fits the question.
- Prepare matched digests without discovery tags to injection-ready load.
- Run a pilot when matrix or enrichment type is new.
- Acquire separate LC-MS/MS injections with interleaved order when cohort size allows.
- Lock gradient, load, and acquisition template for the cohort block.
- Search with declared database, enzyme, modifications, and FDR.
- Extract unlabeled quantitative features; apply declared protein rollup.
- Normalize within study groups; document missing-value policy; run QC before statistics.
- Test predefined contrast only; archive methods and software versions with deliverables.
Steps 1 through 5 are experimental layers shared with Label-Free LC-MS/MS. Steps 6 through 9 complete the quantitative record.
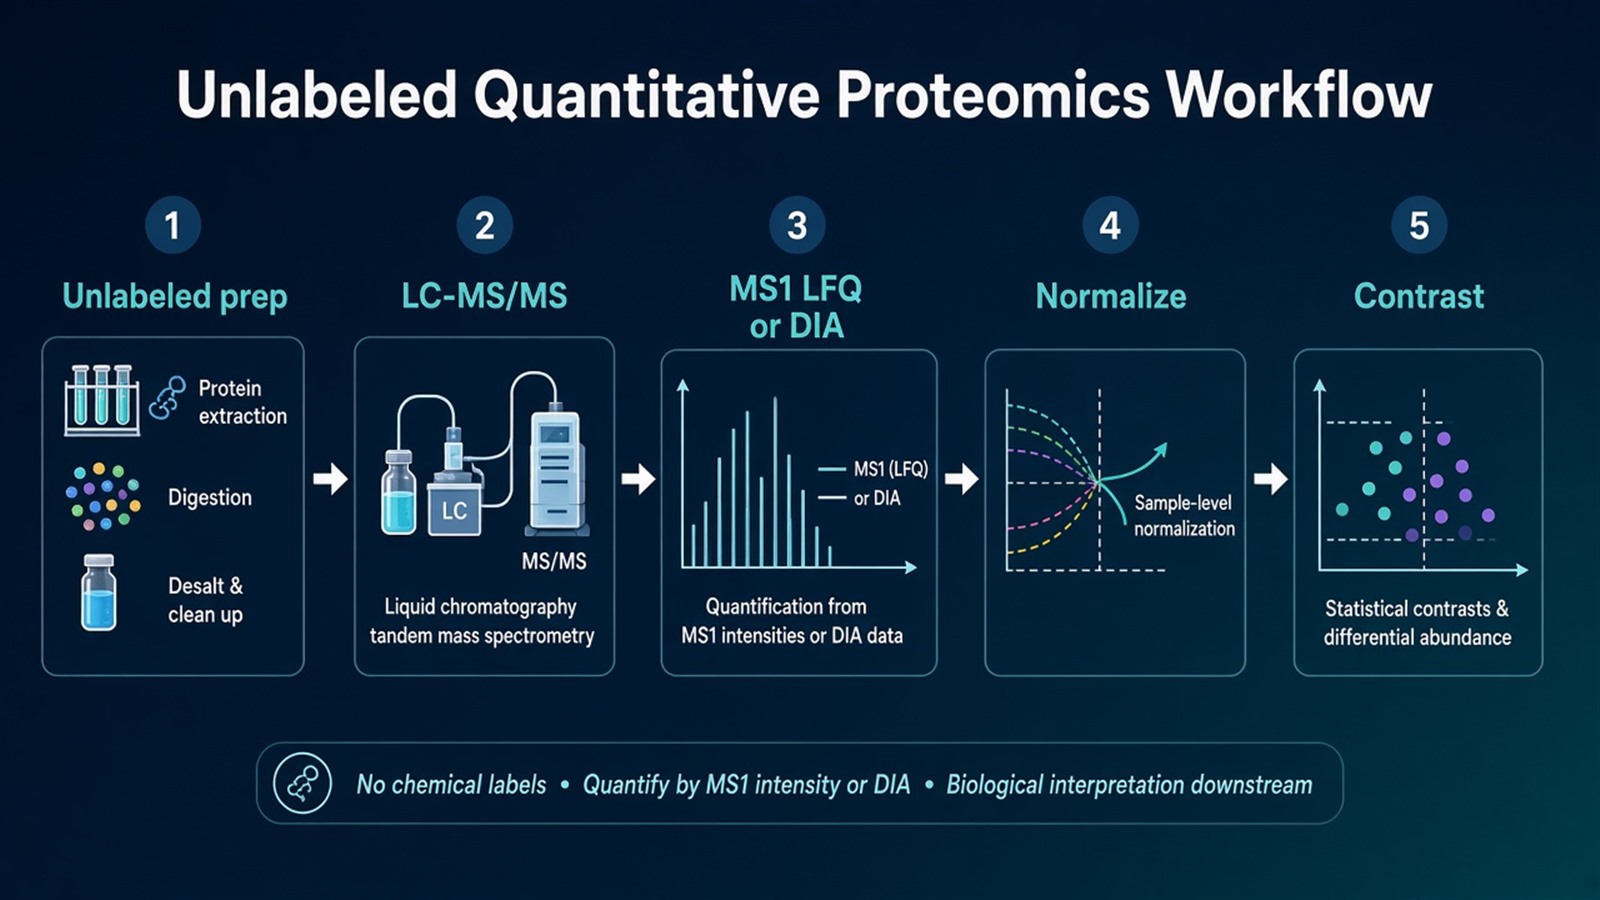
Figure 1. Unlabeled quantitative proteomics requires one locked chain from prep through statistics; metric choice must stay consistent across the block.
Experiment handoff appears in A Guide to Label-Free Quantitative Proteomics: From Experiment to Data Analysis. Tool layers appear in Tools for Label-free Peptide Quantification.
Parameters That Must Be Locked Across Unlabeled Quant Work
Layer |
Parameter that must be declared |
Failure mode if ignored |
|---|---|---|
Contrast |
Groups and claim unit before tuning |
Post hoc relabeling |
Prep |
Matched extraction and digest |
Peptide pool shifts |
Enrichment |
Co-IP, pull-down, or fractionation parity |
Bait arm-only artifacts |
Injection |
Separate unlabeled runs |
Multiplex assumptions |
Acquisition |
DDA or DIA template fixed |
Mixed modes in one matrix |
Quant metric |
MS1 LFQ versus spectral counting |
Incomparable fold changes |
Search |
FDR, database, modifications |
Inflated ID-driven counts |
Normalization |
Method and scope |
Global drift as biology |
Missing values |
Filter and imputation policy |
Hidden model bias |
Processing |
One pipeline version per block |
Mid-cohort drift |
Limits follow the same table. Unlabeled quantitative work on enriched baits or subcellular fractions still needs control arms and realistic expectations for quantifiable depth (How Many Proteins Can Label-Free Detect?). Low-complexity pulls simplify interpretation but do not remove nonspecific binding or run-order confounding (Lazar et al. 2016).
Quality integration appears in How to Improve Data Quality and Reproducibility in Label-Free Proteomics?. Tradeoffs appear in Advantages of Label-Free Proteomics Analysis.
How to Choose Unlabeled Versus Other Quantitative Proteomics Routes
Use enrollment, matrix complexity, metric need, and follow-up unit together.
Quantitative proteomics need |
Route that often fits |
Recheck before committing |
|---|---|---|
Large open cohort, staggered samples |
Unlabeled LFQ separate injections |
Spectral counting as sole metric |
Closed arms, one labeling day |
TMT or iTRAQ multiplex |
Forced unlabeled when tags required |
Cultivable SILAC system |
Metabolic labeled quant |
Label-free when media routing fails |
High DDA missingness |
Unlabeled DIA quantitative pilot |
DDA when DIA adds little |
Co-IP or pull-down contrast |
Matched controls; MS1 LFQ |
ID counts alone in complex binders |
Amount on named peptides |
SIS or PRM targeted quant |
Discovery LFQ as concentration |
Cross-study absolute scale |
Not from open unlabeled LFQ |
iBAQ or targeted calibration scope |
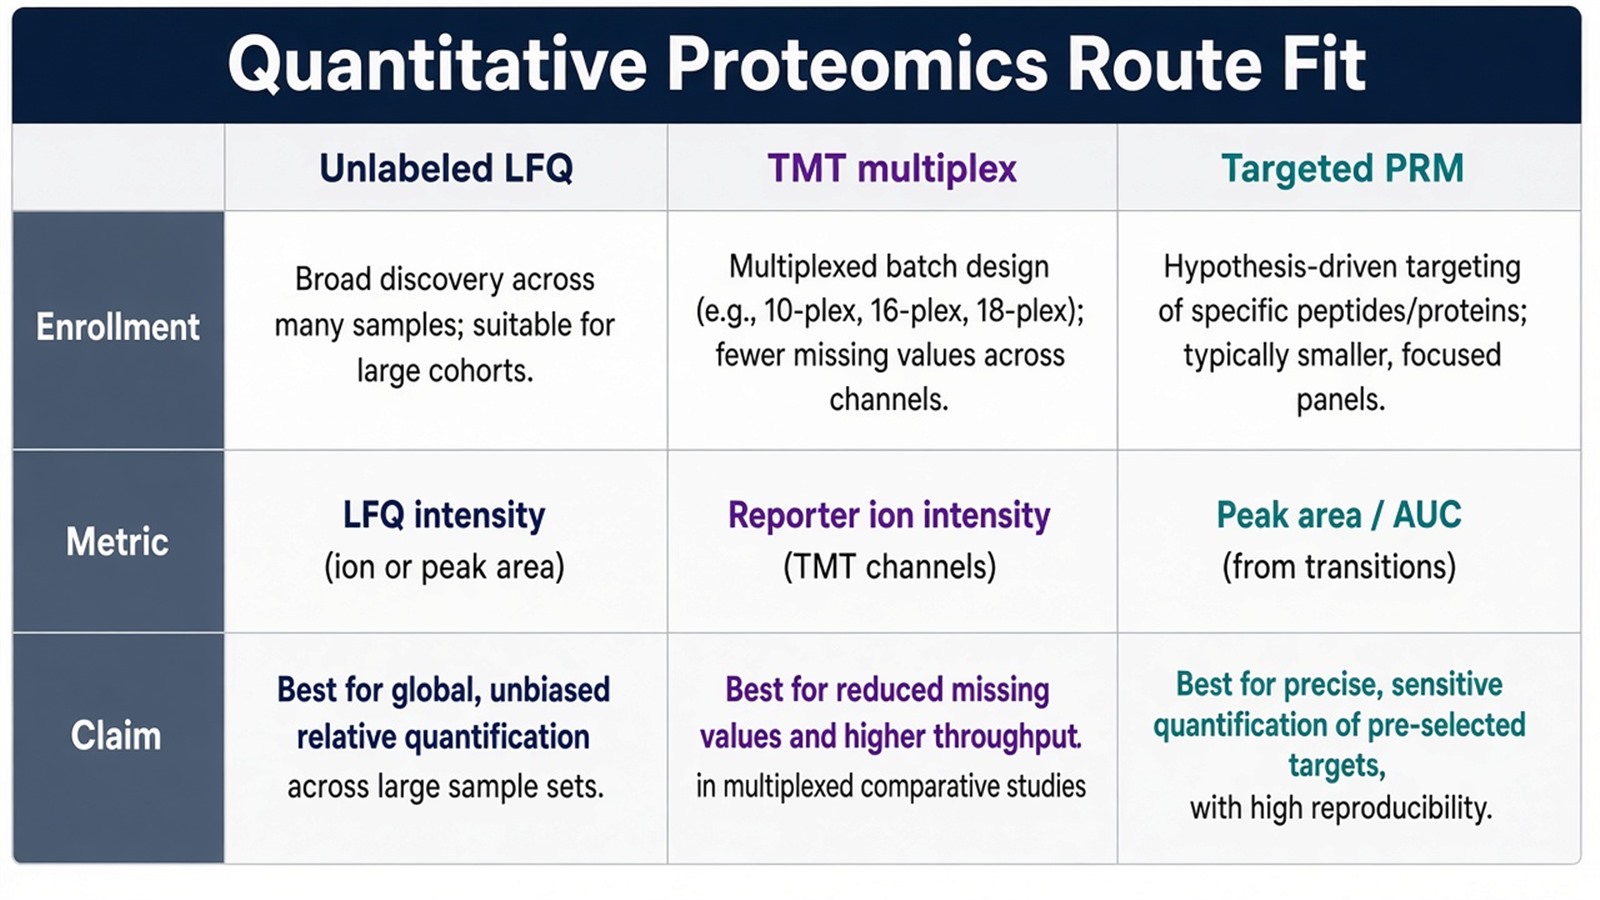
Figure 2. Unlabeled quantitative proteomics fits open relative discovery; labeled multiplex or targeted quant fit other enrollment and claim patterns.
Decode context appears in Decoding Proteomics: A Dive into Label-Free Technology. iBAQ contrast appears in What Is the Difference between LFQ and iBAQ?.
Teams with matrix documentation, contrast map, and metric choice can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for unlabeled quantitative proteomics alignment when declared in the project record.
Frequently Asked Questions
1. Is unlabeled quantitative proteomics the same as label-free quantification?
Unlabeled quantitative proteomics is the project theme. LFQ is the common intensity-based relative readout on unlabeled injections. Spectral counting is another unlabeled readout with narrower fit.
2. When is spectral counting acceptable?
In low-complexity mixtures or rough ranking when MS1 LFQ is not configured, spectral counting may suffice. Complex lysates and group statistics usually need MS1 or DIA intensity LFQ on the same design.
3. Does unlabeled quant avoid all labeling steps?
Discovery injections are unlabeled. Some projects add parallel SIS or PRM assays on the same study questions, which is a separate quantitative block.
4. Can unlabeled quantitative proteomics replace targeted assays?
Open unlabeled discovery prioritizes breadth on a contrast. Targeted quantitative proteomics on named peptides supports follow-up amount or specification-style reporting.
5. What should clients document before service scoping?
Matrix, contrast arms, replicates, pretreatment parity, pilot availability, preferred acquisition mode, and whether the claim is relative discovery or targeted follow-up. Cell culture or labeling scope, when needed, must match the chemistry declared in the brief, not assumed from an unlabeled discovery page.
MtoZ Biolabs can discuss unlabeled quantitative proteomics when contrast design, locked methods, and follow-up intent are documented.
If further evaluation of DDA versus unlabeled DIA pilots, metric choice, or discovery-to-targeted staging is needed, project details can be submitted for a feasibility review.
Reference
- M. Bantscheff, S. Lemeer, H.U. Haab, B. Kuster (2012). Quantitative mass spectrometry in proteomics: a critical review. Anal. Bioanal. Chem., 404, 939-965. https://doi.org/10.1007/s00216-012-5892-4
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
Support Documents
Protein Quantification for Deeper Discovery
Gain a clearer understanding of protein quantification approaches and their applications in studying protein abundance changes by downloading our detailed brochure.