



Decoding label-free proteomics in project language means turning unlabeled liquid chromatography-tandem mass spectrometry (LC-MS/MS) raw files into auditable label-free quantification (LFQ) tables and tested contrasts, not summarizing proteins in abstract terms (Bantscheff et al. 2012). Label-free technology here names matched prep, separate injections, locked acquisition, search with false discovery rate (FDR) control, feature extraction, normalization, and statistics on predefined groups (Cox et al. 2014). The guide below integrates those layers as one readable LFQ record with workflow, parameters, limits, and fit. It is not a disease diagnosis narrative, not an advantages list without methods, and not a biomarker promise page.
Decoded LFQ outputs support relative change of the same protein across samples in one study. They do not report clinical cutoffs, drug target validation, or molar amount on named peptides without targeted stable isotope-labeled internal standard (SIS) or parallel reaction monitoring (PRM) follow-up (Gerber et al. 2003).
In MtoZ Biolabs offerings, label-free technology is scoped when open contrasts, matrix documentation, and separate unlabeled injections fit the cohort block.
Core LFQ terms appear in LFQ. Chemistry definition appears in What Is Label-Free Analysis?.
What Decoding Label-Free Data Means in LFQ Projects
Four decode stages belong in the project record.
Experimental decode turns digests into time-resolved MS1 and MS/MS detection under locked LC-MS/MS methods (Label-Free LC-MS/MS).
Identification decode assigns peptide sequences from fragment evidence with declared database, enzyme, modifications, and FDR thresholds.
Quantification decode aligns features across runs, integrates intensities, rolls peptides to proteins, and applies normalization within study groups.
Interpretation decode tests only the frozen contrast after missing-value policy and matrix QC. Pathway or interaction language stays downstream of a tested protein list.
Decoding label-free proteomics is the documented chain from raw files to contrast statistics, not a headline protein count from one run.
Unlabeled detection context appears in Unlabeled Mass Spectrometry Detection: Label-Free Proteomics Frontier.
Label-Free Technology Layers Versus Labeling Routes
Technology choice splits chemistry, acquisition, and readout.
Label-free technology keeps discovery injections untagged. LFQ readout compares extracted intensities after alignment and scale correction.
Metabolic labeling such as stable isotope labeling by amino acids in cell culture (SILAC) encodes state before harvest for cultivable systems with defined media.
Isobaric tagging such as tandem mass tag (TMT) or isobaric tags for relative and absolute quantitation (iTRAQ) reads reporter ions from multiplexed digests when arms can be labeled the same day.
Data-dependent acquisition (DDA) LFQ decodes MS1 precursor areas after dependent MS/MS identification. Data-independent acquisition (DIA) decodes fragment traces under windowed schedules (Gillet et al. 2012).
Spectral counting decodes MS/MS assignment counts. It is a weak primary readout for group fold changes when MS1 areas are available on the same files.
Method comparison appears in Mass Spectrometry-Based Quantitative Proteomics: Labeled and Label-Free Quantification Strategies. DIA decode context appears in Label-Free DIA Quantitative Proteomics.
End-to-End Workflow to Decode Label-Free Proteomics Data
A practical decode spine usually runs as follows.
- Confirm matrix, contrast, relative claim, and DDA LFQ versus unlabeled DIA fit.
- Prepare matched digests without discovery tags.
- Acquire separate injections with interleaved order when cohort size allows.
- Lock LC gradient, load, and acquisition template for the cohort block.
- Convert and store raw files with versioned import settings.
- Search peptides under locked FDR and modification rules.
- Extract label-free features; apply declared protein rollup.
- Normalize; document missing-value handling; run QC before statistics.
- Test predefined contrast only; archive software versions with deliverables.
Steps 1 through 4 protect experimental decode. Steps 5 through 9 protect informatics decode.
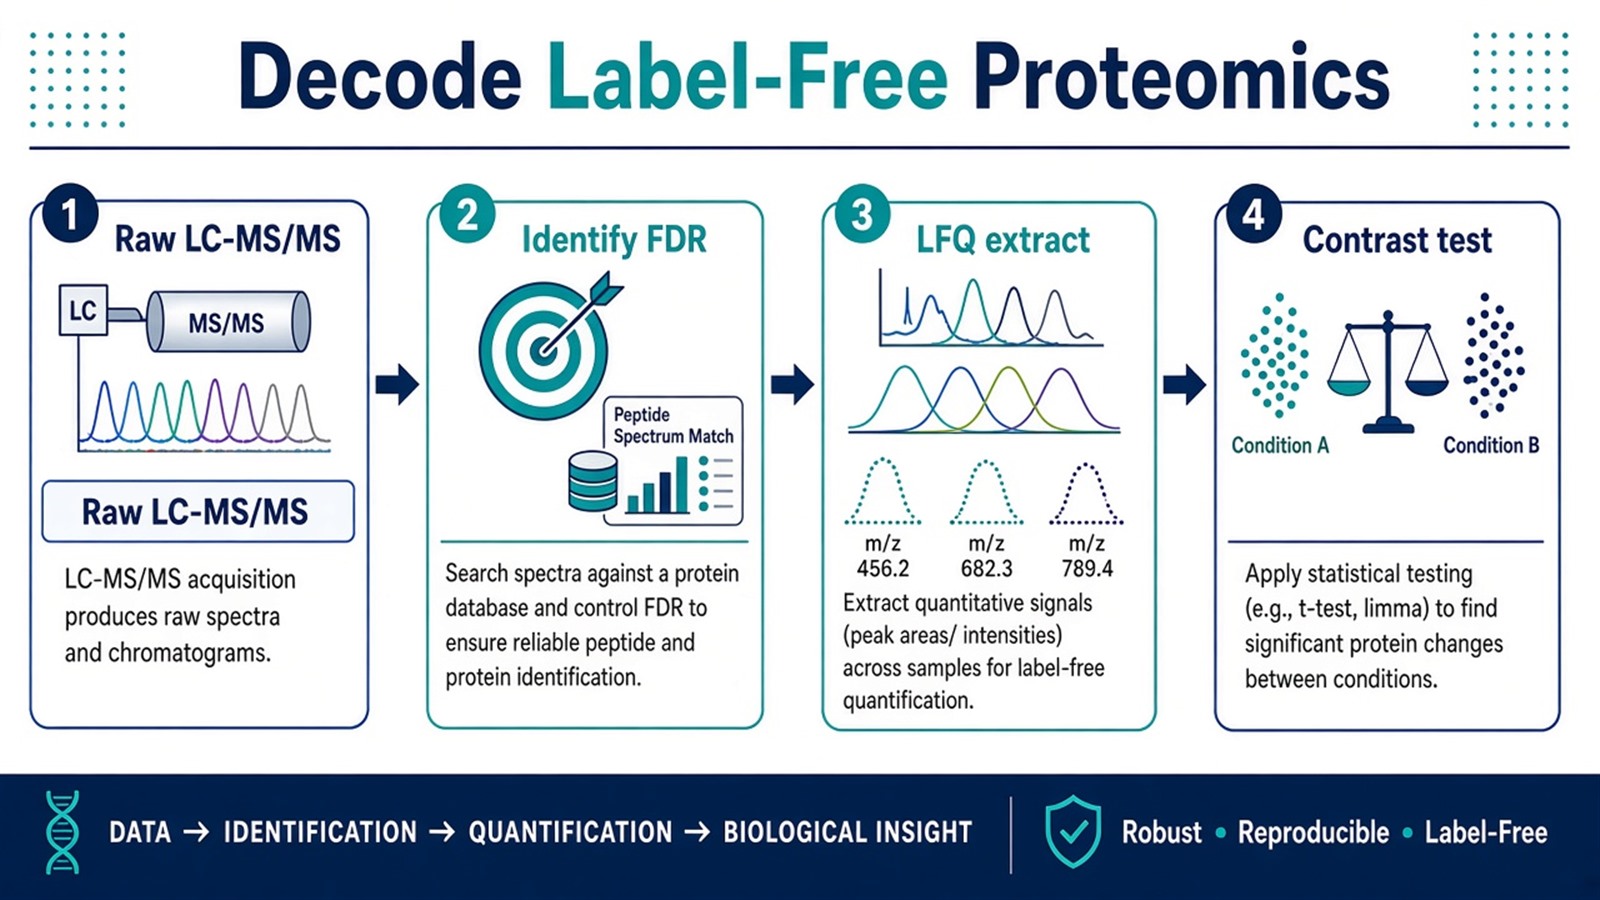
Figure 1. Readable LFQ results depend on locked methods at each decode stage, not only on search output.
Tool layers appear in Tools for Label-free Peptide Quantification. Quality gates appear in How to Improve Data Quality and Reproducibility in Label-Free Proteomics?.
Parameters That Must Be Locked When Decoding LFQ
Decode stage |
Parameter that must be declared |
Failure mode if ignored |
|---|---|---|
Contrast |
Groups frozen before tuning |
Post hoc relabeling |
Prep |
Matched extraction and digest |
Peptide pool shifts |
LC-MS/MS |
Gradient, column, load, acquisition mode |
Broken alignment |
Raw import |
Converter and checksum policy |
Silent file corruption |
Search |
Database, enzyme, FDR, modifications |
Mixed identification spaces |
Quant |
MS1 versus fragment metric |
Incomparable intensities |
Rollup |
Protein grouping rule |
Shared peptide ambiguity |
Normalization |
Method and study scope |
Global drift as biology |
Missing values |
Filter and imputation policy |
Hidden model bias |
Statistics |
Contrast model and software version |
Non-reproducible decode |
Limits follow the same table. Decoding does not turn discovery contrasts into diagnostic tests or drug target proof without separate study design. High identification counts do not replace replicate balance or prep parity (How Many Proteins Can Label-Free Detect?). Missing values remain common in DDA LFQ (Lazar et al. 2016).
Normalization detail appears in How to Normalize Data in Label-Free Quantitative Proteomics?. Reproducibility remediation appears in How to Overcoming Reproducibility Issues in Label-Free Proteomics?.
How to Choose Label-Free Technology for Your Project
Use enrollment, decode goal, pilot evidence, and follow-up unit together.
Project need |
Label-free technology plan that often fits |
Recheck before committing |
|---|---|---|
Open cohort, staggered samples |
DDA LFQ decode on separate injections |
Same-day multiplex tagging assumption |
High DDA missingness after pilot |
Unlabeled DIA decode pipeline |
DDA when DIA adds little |
Closed arms, one labeling day |
TMT or iTRAQ labeled decode |
Forced LFQ when mixing required |
Need export to mixed models |
MSstats-compatible peptide tables |
Manual edits between tools |
Drug mechanism headline from one run |
Not supported without design |
Discovery decode as target proof |
Biomarker panel intent |
LFQ discovery then PRM |
Discovery p-values as final panel |
Amount on named peptides |
SIS or AQUA targeted decode |
Open LFQ as concentration |
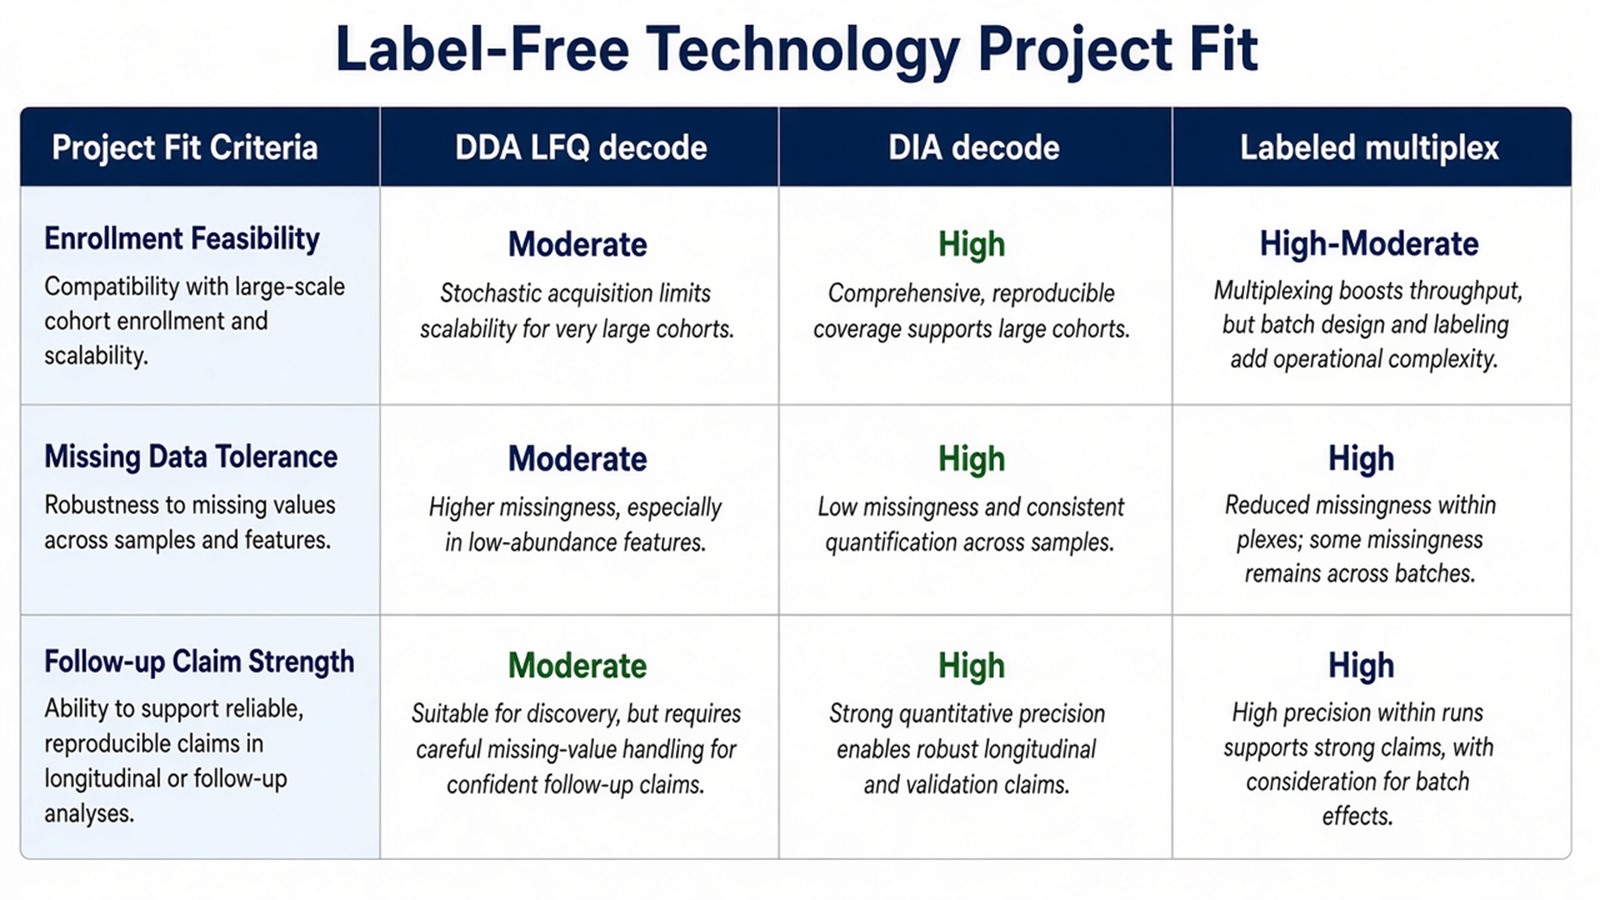
Figure 2. Choose label-free technology when unlabeled separate injections and a locked decode chain fit the contrast; tagging or targeted routes fit other claim patterns.
Route selection appears in Protein Quantification Method. Enrollment checks appear in Exploring Quantitative Analysis in Proteomics.
Teams with contrast map, matrix documentation, and decode scope can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for label-free technology alignment when declared in the project record.
Frequently Asked Questions
1. Does decoding label-free data mean running search software only?
No. Search is one stage. Decoding includes acquisition lock, quant extraction, normalization, missing-value policy, and contrast testing on frozen groups.
2. Is label-free technology always higher throughput than TMT?
Separate injections scale cohort size flexibly but add run count. Multiplex tagging increases comparisons per run with labeling-day constraints. Throughput follows enrollment, not chemistry name alone.
3. Can decoded LFQ lists support diagnosis or drug labels?
Discovery LFQ supports relative contrasts in a declared study. Diagnostic or regulatory claims need separate validation design not implied by decode depth alone.
4. Should AI tools replace locked decode parameters?
Machine learning may assist scoring or imputation when documented in the pipeline. It does not replace frozen contrasts, prep parity, or versioned methods (How AI & Machine Learning Enhance Label-Free Proteomics Data Analysis Efficiency?).
5. When should decode move from DDA LFQ to unlabeled DIA?
When pilots show acceptable identification but poor quantifiable coverage on proteins near the decision threshold, unlabeled DIA pilots are a common next step if window schedules fit the matrix.
MtoZ Biolabs can discuss label-free decode planning when raw format, locked methods, and contrast design are documented.
If further evaluation of DDA versus unlabeled DIA decode pilots, normalization choice, or discovery-to-targeted staging is needed, project details can be submitted for a feasibility review.
Reference
- M. Bantscheff, S. Lemeer, H.U. Haab, B. Kuster (2012). Quantitative mass spectrometry in proteomics: a critical review. Anal. Bioanal. Chem., 404, 939-965. https://doi.org/10.1007/s00216-012-5892-4
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
