



Mass spectrometry-based quantitative proteomics analysis turns matched peptide digests into protein-by-sample values under a declared quantitative signal and claim (Bantscheff et al. 2012). Principles and sample pretreatment belong in one plan because lysis, cleanup, and labeling chemistry decide which signals can be read after liquid chromatography-tandem mass spectrometry (LC-MS/MS). The guide below links prep principles to MS quantification principles. It is not a disease-application catalog, not a bioinformatics pipeline manual, and not a platform marketing page.
A complete method statement names labeling chemistry, acquisition mode, and whether the claim is a relative ratio or a stable isotope-labeled internal standard (SIS) amount. Unlabeled digests can be acquired as data-dependent acquisition (DDA) or data-independent acquisition (DIA). Isobaric tandem mass tag (TMT) work typically reads reporter ions after mixing. Named proteins are typically followed by parallel reaction monitoring (PRM) or multiple reaction monitoring (MRM) / selected reaction monitoring (SRM). In MtoZ Biolabs offerings, unlabeled discovery is commonly run as DDA label-free or DIA, multiplexed isobaric work is typically evaluated as TMT, and closed lists are typically followed by PRM, with MRM when a scheduled triple-quadrupole panel already exists.
What MS-Based Quantitative Proteomics Analysis Means
Quantitative proteomics analysis requires a usable quantitative trace for peptides that pass stated identification or extraction rules. Identification alone is not quantification. Spectral counting ranks sampling frequency. It is a weak substitute for intensity-based matrices when group contrasts need fold-change statistics.
Relative quantification compares the same protein across samples inside one study. Absolute quantification reports mass or molar units only when a matched SIS and a calibration rule are declared (Gerber et al. 2003). Bulk Bradford, bicinchoninic acid (BCA), Lowry, and 280 nm assays match total protein input before digestion. They are not the MS quantitative result.
MS-based quantitative proteomics analysis is peptide-level LC-MS/MS with a declared signal, contrast, and claim, not a protein name list alone.
Researchers who need a full method-family definition set can refer to What Are the Quantitative Methods for Proteomics?.
Sample Pretreatment Principles That Must Match the Claim
Pretreatment principles follow matrix type and the planned labeling route.
Matched input and chemistry. Cells, tissues, plasma, serum, and formalin-fixed paraffin-embedded (FFPE) material each need a declared extraction and digestion plan. Groups must share that plan. Unequal lysis or cleanup recovery creates intensity shifts that look biological after search.
Detergent and amine compatibility. Chaotropes and detergents must be removed before stable LC and ionization (Wisniewski et al. 2009). TMT labels free amines on peptides after digestion. Residual primary amines in buffers compete with channel tagging.
Labeling timing. Metabolic labeling such as stable isotope labeling by amino acids in cell culture (SILAC) requires growable cells. Chemical isobaric tagging happens on digested peptides. SIS peptides for amount claims need a declared spike point relative to cleanup (Gerber et al. 2003).
Desalting and LC-ready loads. Peptides must reach the column in a matched solvent and load. Prep inconsistency breaks cross-run alignment for unlabeled work and softens reporters inside a TMT plex (Rappsilber et al. 2007).
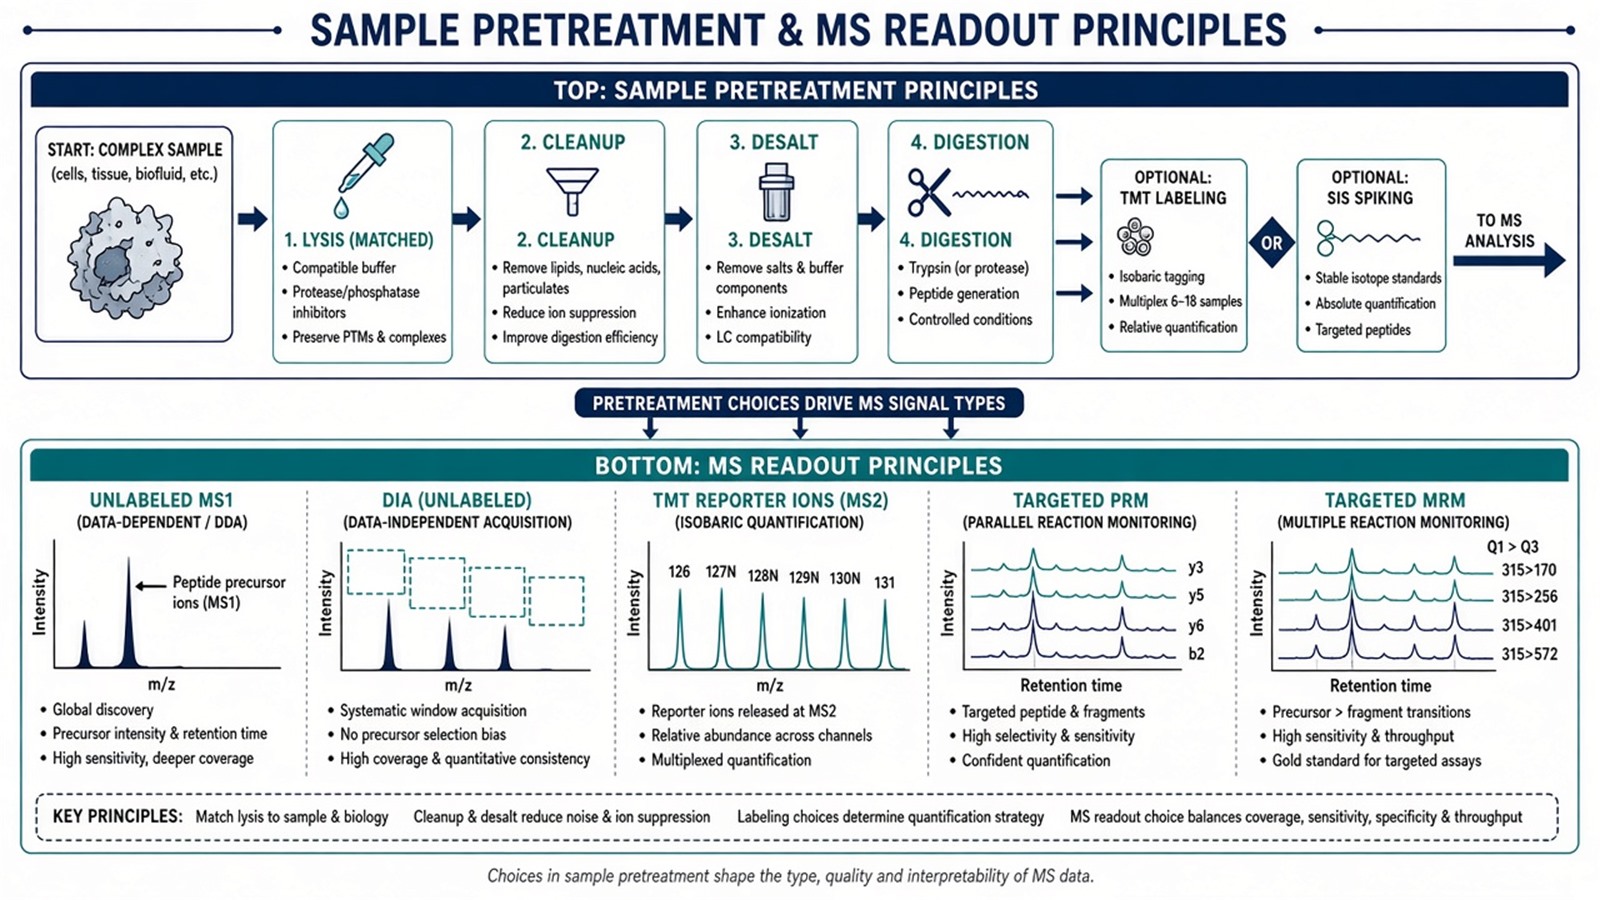
Figure 1. Pretreatment principles must match the quantitative signal that LC-MS will read: unlabeled intensities, isobaric reporters, or targeted traces.
The lysis-to-digest spine for matched matrices is covered in Quantitative Protein Analysis. This page stays on how prep choices couple to quantification principles.
How MS Readout Principles Create Quantitative Signals
Signal principles stay separate from prep details but must align with them.
Unlabeled relative signals come from MS1 peak areas after DDA identification, or from fragment chromatograms extracted from DIA windows (Cox et al. 2014; Gillet et al. 2012). Each digest stays on its own injection path. Alignment and missing-value rules are part of the principle.
Isobaric TMT signals come from reporter ions after channel mixing (Thompson et al. 2003). Reporters support same-peptide relative comparison across channels. They do not by themselves rank unrelated proteins as copy numbers.
Targeted signals come from scheduled precursor isolation and extracted fragment peaks (Lange et al. 2008; Peterson et al. 2012). The list is closed. Proteins outside the schedule are not quantified in that assay.
Acquisition mode is not labeling. DIA names a window schedule. Label-free names the absence of sample tags. Targeted names a closed list. A methods record must state both prep and readout axes.
Shared Workflow From Sample to Quantitative Matrix
Applied MS quantitative analysis follows one order even when the biological theme changes.
- Confirm matrix, contrast, and relative versus SIS amount claim.
- Prepare matched digests with shared lysis, digestion, and cleanup rules.
- Apply metabolic labeling, TMT tagging, or SIS only when the design requires them.
- Acquire LC-MS/MS under one declared mode: unlabeled DDA, unlabeled DIA, TMT, or targeted schedule.
- Identify or extract peptides under declared false discovery rate (FDR) rules.
- Roll up to proteins, apply normalization and missing-value rules, then test the predefined contrast.
Where samples diverge defines the principle in practice. Unlabeled work separates injections before alignment. TMT mixes after labeling. Targeted work schedules before cohort acquisition. Pathway enrichment or multi-omic overlay can interpret a cleaned matrix. It cannot repair confounded prep batches or amount claims made without SIS (Lazar et al. 2016).
Parameters and Limits at the Prep and Principle Layer
Layer |
Parameter that must be declared |
Failure mode if ignored |
|---|---|---|
Prep |
Matched input, lysis, and cleanup |
Load or batch bias |
Prep |
Amine-free buffers before TMT |
Incomplete reporters |
Signal |
Quantitative object (MS1, DIA trace, reporter, targeted peak) |
Mixed models on incompatible traces |
Signal |
Acquisition and FDR rules |
Long lists with weak quant traces |
Claim |
Normalization and missing-value policy |
Soft or imputed contrasts |
Claim |
SIS identity and spike point |
Relative peaks read as concentration |
Limits follow the same table. MS quantitative analysis does not prove diagnostic utility, predict therapy, or replace validated clinical assays. FFPE and biofluids can work when prep is validated for that matrix. They are not automatic upgrades over matched fresh lysates. Targeted analysis does not resurvey an open proteome. Isobaric ratios can compress when co-isolation is severe.
Application language such as mechanism study or biomarker screening only holds when prep and signal principles return a defensible relative matrix for predefined groups. It does not hold as a clinical claim by default.
Researchers who need route selection after principles are clear can refer to Protein Quantification Method. A cross-technique map sits in Quantitative Proteomics Techniques.
How to Choose Prep and Readout Principles for the Next Project
Use matrix, enrollment flexibility, and claim unit together.
Project need |
Prep and readout that often fit |
Recheck before committing |
|---|---|---|
Open cohort, cells or tissue |
Matched prep, unlabeled DDA or DIA |
Run order identical to treatment |
Freezable multi-group set |
Matched digest, TMT, mixed LC path |
Late harvests without a bridge |
Growable cells with metabolic label plan |
SILAC-style prep plus relative readout |
Tissue or plasma without culture labeling |
Named peptides after discovery |
Clean digest, PRM or MRM schedule |
Panel longer than one duty cycle |
Amount on named peptides |
Prep plus matched SIS and calibration |
Reporter or MS1 height as concentration |
Only total protein load |
Bulk dye or A280 assay |
Not MS peptide quantification |
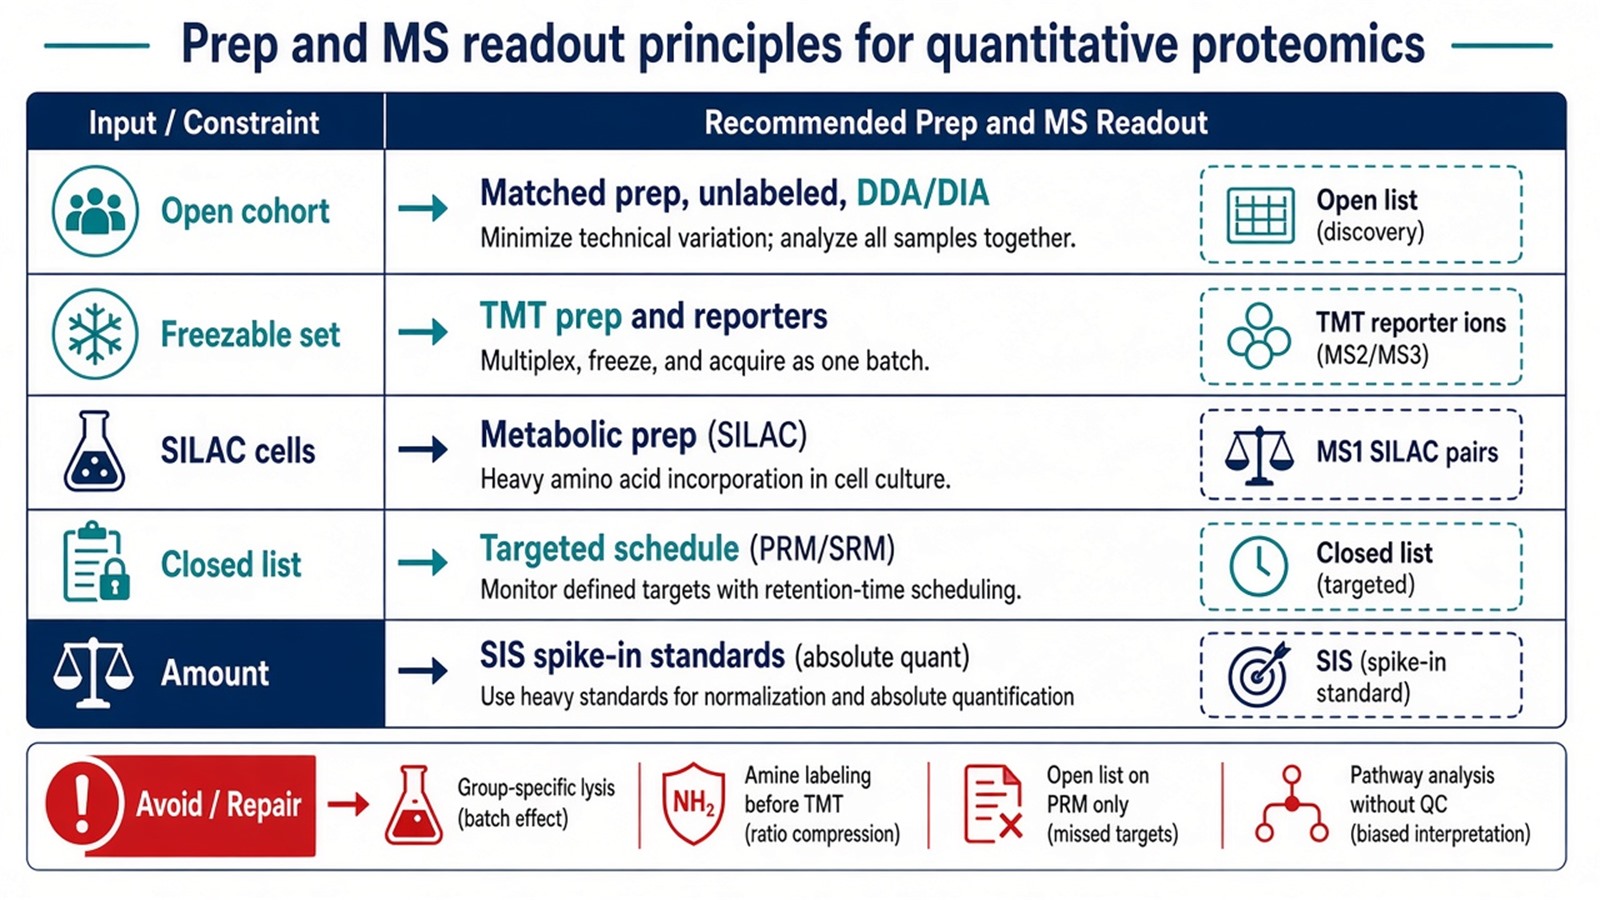
Figure 2. Choose prep and MS readout from matrix and claim type; amine interference, open lists on targeted schedules, and amount-without-SIS need repair first.
Unlabeled prep and readout more often fit open enrollment. TMT more often fits freezable sets after amine cleanup. Targeted confirmation more often fits after names freeze. Exceptions exist when a tiny validated panel never needed discovery.
Teams that already have matrix, contrast, and a requested claim can also review the MtoZ Biolabs Quantitative Proteomics Service for project-specific prep and MS quantification planning.
Frequently Asked Questions
1. Is database search the same as MS quantitative analysis?
No. Search assigns identities. Quantitative analysis extracts declared signals and tests a predefined contrast under stated rules.
2. Can sample prep differ by group if the MS method is the same?
No. Prep must stay matched across groups unless the contrast explicitly includes a prep arm. Batch-specific lysis breaks relative claims.
3. Does TMT labeling define the entire quantitative principle?
No. TMT is labeling chemistry. Acquisition must still read reporters, and prep must keep amines available for tagging.
4. When does targeted readout replace discovery principles?
When the peptide list is closed and only scheduled precursors are quantified. Open discovery remains the first step when names are still unknown.
5. Do pathway results validate prep and quantification choices?
No. Enrichment interprets a cleaned matrix. It cannot repair missingness, batch effects, or amount claims made without SIS.
MtoZ Biolabs can support mass spectrometry-based quantitative proteomics analysis across unlabeled DDA or DIA discovery, TMT relative plexes, and targeted PRM or MRM follow-up when sample type, study design, and the intended claim are available.
If further evaluation of matrix-matched prep, labeling compatibility, signal choice, or SIS planning is needed, project details can be submitted for a feasibility review.
Reference
- M. Bantscheff, S. Lemeer, M.M. Savitski, B. Kuster (2012). Quantitative mass spectrometry in proteomics: critical review update from 2007 to the present. Anal. Bioanal. Chem., 404, 939-965. https://doi.org/10.1007/s00216-012-6203-4
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- V. Lange, P. Picotti, B. Domon, R. Aebersold (2008). Selected reaction monitoring for quantitative proteomics: a tutorial. Mol. Syst. Biol., 4, 222. https://doi.org/10.1038/msb.2008.61
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- A.C. Peterson, J.D. Russell, D.J. Bailey, M.S. Westphall, J.J. Coon (2012). Parallel reaction monitoring for high resolution and high mass accuracy quantitative, targeted proteomics. Mol. Cell. Proteomics, 11, 1475-1488. https://doi.org/10.1074/mcp.O111.013698
- A. Thompson, J. Schafer, K. Kuhn, S. Kienle, J. Schwarz, G. Schmidt, T. Neumann, R. Johnstone, A.K. Mohammed, C. Hamon (2003). Tandem mass tags: a novel quantification strategy for comparative analysis of complex protein mixtures by MS/MS. Anal. Chem., 75, 1895-1904. https://doi.org/10.1021/ac0262560
- J. Rappsilber, M. Mann, Y. Ishihama (2007). Protocol for micro-purification, enrichment, pre-fractionation and storage of peptides for proteomics using StageTips. Nat. Protoc., 2, 1896-1906. https://doi.org/10.1038/nprot.2007.261
- J.R. Wisniewski, A. Zougman, N. Nagaraj, M. Mann (2009). Universal sample preparation method for proteome analysis. Nat. Methods, 6, 359-362. https://doi.org/10.1038/nmeth.1322
