



Label-free quantification (LFQ) is the usual name for relative protein discovery on unlabeled liquid chromatography-tandem mass spectrometry (LC-MS/MS) injections: separate samples, matched prep, extracted intensities aligned across runs, normalization, and contrast statistics on predefined groups (Cox et al. 2014). In project language, LFQ names the quantification record built after identification, not a labeling chemistry and not a single instrument brand (Bantscheff et al. 2012). The guide below integrates LFQ scope, workflow, locked parameters, limits, and fit for label-free proteomics planning. It is not a metabolomics methods page, not a software tutorial for every search engine, and not a disease biomarker catalog.
LFQ tables support relative change of the same protein across samples in one study. They do not report molar concentration across proteins, copy number, or clinical cutoffs without targeted stable isotope-labeled internal standard (SIS) or parallel reaction monitoring (PRM) follow-up (Gerber et al. 2003).
In MtoZ Biolabs offerings, LFQ commonly runs as data-dependent acquisition (DDA) MS1 peak-area quantification or as unlabeled data-independent acquisition (DIA) extraction when windowed schedules fit the cohort.
Terminology and chemistry contrast appear in What Is Label-Free Analysis?. Experimental LC-MS/MS scope appears in Label-Free LC-MS/MS.
What LFQ Covers in Label-Free Proteomics Projects
Four scopes belong in the brief and stay separated.
Chemistry scope is label-free: no isobaric or metabolic tags on discovery injections. Each arm follows matched pretreatment to an injection-ready digest.
Acquisition scope covers DDA precursor selection or DIA and SWATH-style window plans on the same unlabeled prep. Mode must stay locked across the cohort block that shares one contrast.
Metric scope is usually MS1 precursor chromatogram integration after peptide identification. Spectral counting from assigned MS/MS counts can support screening but is a weak primary metric for group fold changes when MS1 areas are available.
Statistics scope covers normalization, missing-value policy, protein rollup rules, and testing on frozen contrasts only.
LFQ is the relative quantification layer on label-free injections. It does not replace replicate design, interleaved run order, or a single declared processing pipeline.
Service enrollment context appears in Exploring Quantitative Analysis in Proteomics.
LFQ Metrics and Acquisition Routes on Label-Free Data
Unlabeled prep can pair with more than one acquisition and metric.
DDA LFQ integrates MS1 precursor areas for peptides identified from dependent MS/MS. Stochastic sampling drives missing values at low abundance.
MaxLFQ-style rollup uses peptide ratio relationships after delayed normalization within a processing chain (Cox et al. 2014).
Unlabeled DIA or SWATH-style LFQ quantifies from extracted fragment traces under false discovery rate (FDR) control (Gillet et al. 2012). Completeness may improve in some matrices after pilot evidence; prep and contrast rules stay the same.
Spectral counting ranks by assigned spectrum counts per protein. It does not replace intensity-based LFQ when fold-change statistics are the goal on the same files.
Within-sample abundance proxies such as intensity-based absolute quantification (iBAQ) answer a different question than cross-run LFQ contrasts.
DIA depth compares with Label-Free DIA Quantitative Proteomics. iBAQ contrast compares with What Is the Difference between LFQ and iBAQ?.
End-to-End LFQ Workflow
A practical LFQ spine on label-free LC-MS/MS usually runs as follows.
- Confirm matrix, contrast, relative claim, and DDA LFQ versus unlabeled DIA fit.
- Prepare matched digests without discovery tags.
- Acquire separate injections with interleaved order when cohort size allows.
- Lock acquisition template and raw handling for the cohort block.
- Search with declared enzyme, modifications, database, and FDR.
- Extract label-free features; apply declared protein rollup.
- Normalize within study groups; document missing-value policy.
- Run matrix QC on intensity and identification depth before statistics.
- Test predefined contrast only; archive software version and methods with deliverables.
Steps 1 through 4 are experimental layers. Steps 5 through 9 are LFQ informatics layers.
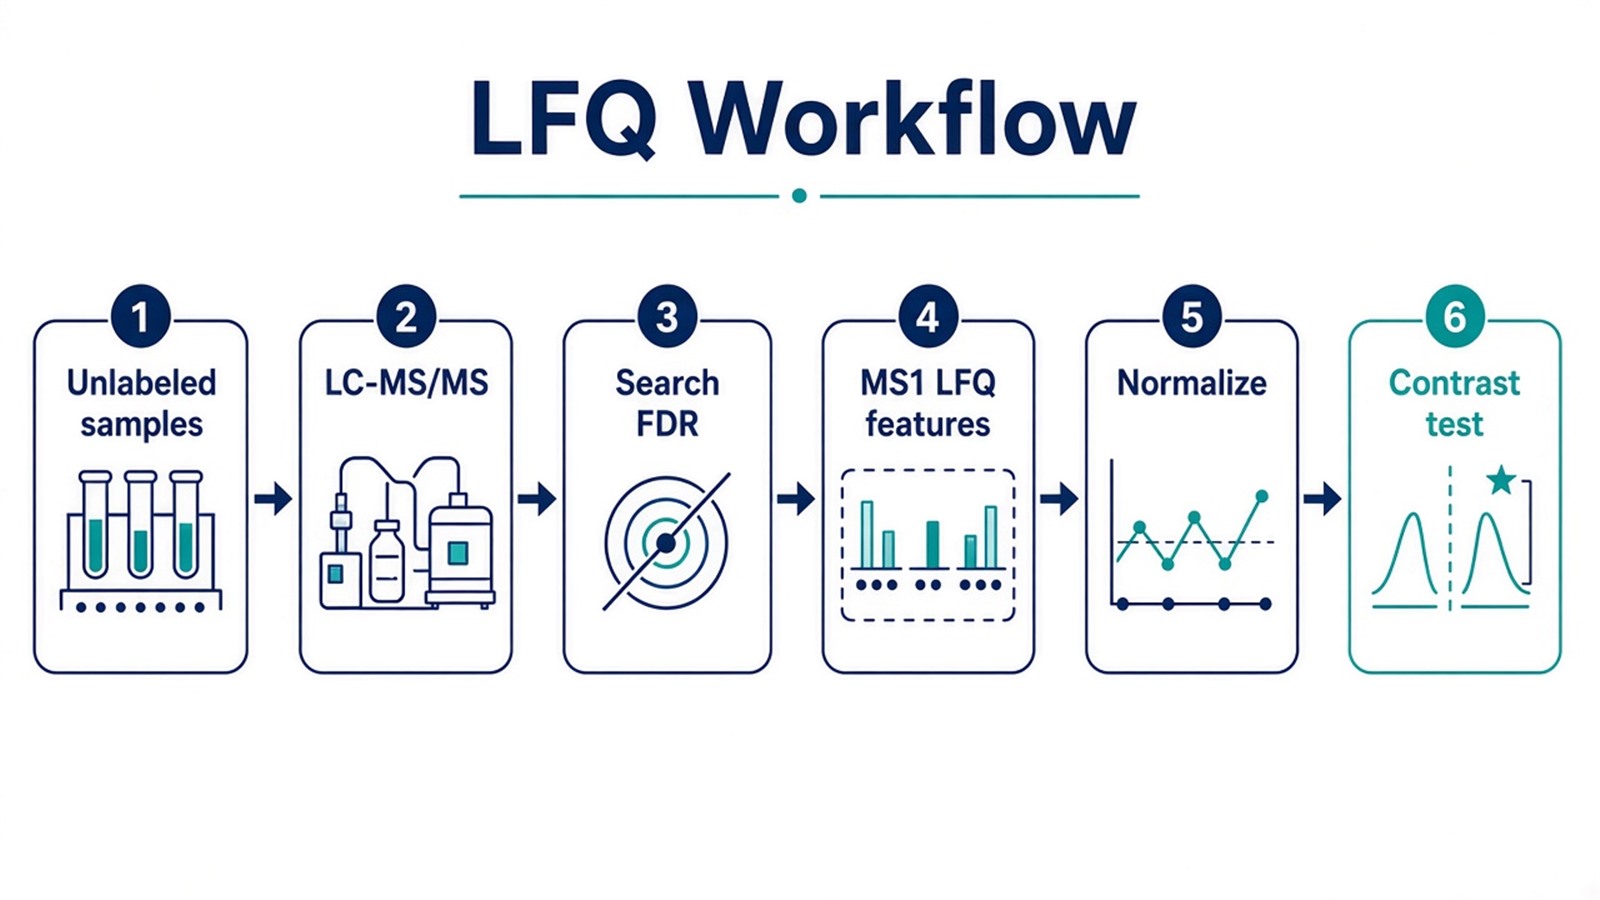
Figure 1. LFQ comparability depends on matched prep, locked acquisition, and one processing record before contrast statistics.
Normalization choices appear in How to Normalize Data in Label-Free Quantitative Proteomics?. Quality integration appears in How to Improve Data Quality and Reproducibility in Label-Free Proteomics?.
Parameters That Must Be Locked for LFQ
Layer |
Parameter that must be declared |
Failure mode if ignored |
|---|---|---|
Contrast |
Groups and claim unit before tuning |
Post hoc relabeling |
Prep |
Matched extraction and digest |
Peptide pool shifts |
Injection |
Separate runs, documented load |
Mixed multiplex assumptions |
Acquisition |
DDA or DIA template locked |
Mixed modes in one matrix |
Search |
Database, FDR, modifications |
Mixed identification spaces |
Quant |
MS1 area versus fragment metric |
Incomparable intensities |
Rollup |
Protein grouping rule |
Shared peptide ambiguity |
Normalization |
Method and scope |
Global drift as biology |
Missing values |
Filter and imputation policy |
Hidden model bias |
Processing |
One pipeline version per block |
Mid-cohort software drift |
Limits follow the same table. LFQ does not remove batch confounding when run order tracks treatment. Low-abundance dropout stays common in DDA LFQ (Lazar et al. 2016). Imputation does not replace biological replicates.
Reproducibility remediation appears in How to Overcoming Reproducibility Issues in Label-Free Proteomics?. Tool chain context appears in Tools for Label-free Peptide Quantification.
How to Choose LFQ for Your Project
Use enrollment pattern, acquisition pilot, processing plan, and follow-up unit together.
Project need |
LFQ plan that often fits |
Recheck before committing |
|---|---|---|
Open cohort, staggered samples |
DDA LFQ separate injections |
Same-day isobaric multiplex assumption |
High DDA missingness after pilot |
Unlabeled DIA or SWATH-style LFQ |
DDA when DIA adds little |
Closed arms, one labeling day |
TMT or iTRAQ multiplex |
Forced LFQ when mixing required |
Thermo DDA with PD declared |
Locked Proteome Discoverer LFQ chain |
Mixed MaxQuant mid contrast |
Need mixed-model stats on exports |
MSstats-compatible peptide tables |
Manual table edits |
Candidate list needs remeasurement |
LFQ discovery then PRM |
Discovery p-values as final panel |
Amount on named peptides |
SIS or AQUA targeted assay |
Open LFQ as concentration |
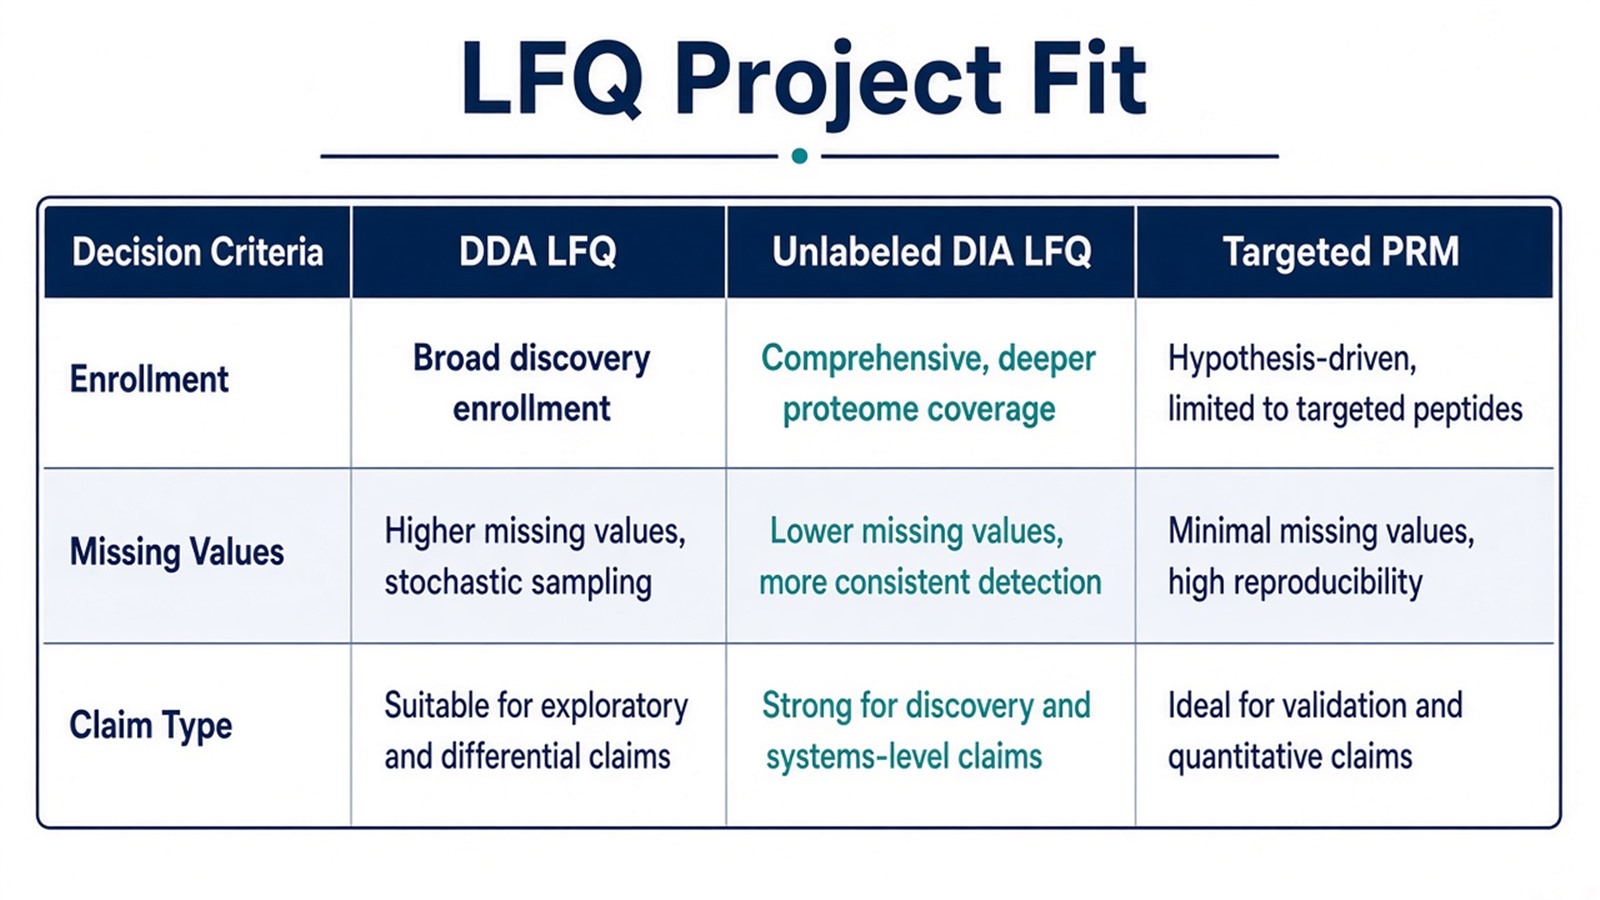
Figure 2. Choose LFQ when unlabeled separate injections and a relative contrast fit the brief; tagging, DIA-only pivots, or targeted assays fit other patterns.
Route selection compares with Protein Quantification Method. Proteome Discoverer LFQ context compares with Proteome Discoverer Label-Free Quantification.
Teams with contrast map, matrix documentation, and acquisition pilot notes can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for LFQ alignment when declared in the project record.
Frequently Asked Questions
1. Is LFQ the same as label-free proteomics?
Label-free names unlabeled discovery chemistry on separate injections. LFQ names relative quantification from extracted signals after search and normalization. Many label-free projects use LFQ; targeted assays are a different scope.
2. Should spectral counting be the main LFQ metric?
When MS1 peak areas are available from the same DDA files, intensity-based LFQ usually supports group fold-change statistics more directly than spectrum counts alone.
3. Can LFQ replace SILAC or TMT?
LFQ fits open cohorts without tagging. SILAC fits cultivable systems with defined media. TMT or iTRAQ fit closed multiplex arms labeled the same day. Chemistry follows enrollment, not habit.
4. Does LFQ output validate biomarkers?
LFQ supports relative discovery contrasts. Validation panels need separate study design and often targeted remeasurement.
5. When should pilots precede full cohort LFQ?
When matrix is new, load is uncertain, or DDA missingness is unknown, a short pilot should lock prep, gradient, acquisition, and processing before scaling injections.
MtoZ Biolabs can discuss LFQ planning when contrast design, locked methods, and follow-up intent are documented.
If further evaluation of DDA versus unlabeled DIA fit, normalization choice, or discovery-to-targeted staging is needed, project details can be submitted for a feasibility review.
Reference
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
- M. Bantscheff, S. Lemeer, H.U. Haab, B. Kuster (2012). Quantitative mass spectrometry in proteomics: a critical review. Anal. Bioanal. Chem., 404, 939-965. https://doi.org/10.1007/s00216-012-5892-4
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
