



Thermo Scientific Proteome Discoverer is one software environment used to process label-free quantification (LFQ) tables from unlabeled liquid chromatography-tandem mass spectrometry (LC-MS/MS) injections. In project language, Proteome Discoverer names a declared processing chain for search, feature extraction, normalization, and contrast statistics, not a separate labeling chemistry or acquisition mode (Bantscheff et al. 2012). Label-free still means separate injections, matched prep, and a frozen contrast tested after alignment and scale correction (Cox et al. 2014). The guide below integrates Proteome Discoverer within LFQ workflows, parameters, limits, and project fit. It is not a click-by-click manual for every node, not a vendor comparison scorecard, and not a disease application catalog.
Proteome Discoverer outputs remain relative matrices unless a targeted stable isotope-labeled internal standard (SIS) design supports amount claims on named peptides (Gerber et al. 2003). Switching processors mid cohort without a new analysis record splits comparability.
In MtoZ Biolabs offerings, unlabeled discovery may use Proteome Discoverer or other declared pipelines when data-dependent acquisition (DDA) raw files and project scope fit the cohort block.
Tool survey context appears in Tools for Label-free Peptide Quantification. Principle language appears in What Is Label-Free Analysis?.
What Proteome Discoverer Covers in LFQ Projects
Proteome Discoverer bundles steps that other ecosystems split across programs.
Database search and protein inference assign peptide-spectrum matches under declared enzyme rules, modifications, and false discovery rate (FDR) thresholds.
Label-free quantification nodes extract precursor intensities or related features from MS1 maps and roll peptides to proteins with configurable rules.
Normalization and study grouping apply scale correction before contrast testing when the workflow is configured that way.
Reporting exports peptide and protein tables with processing metadata for audit.
Proteome Discoverer is the analysis record layer. It does not replace contrast design, interleaved run order, or matched pretreatment.
Quality integration appears in How to Improve Data Quality and Reproducibility in Label-Free Proteomics?.
Proteome Discoverer Versus Other LFQ Processing Routes
Pipeline choice is independent of label-free chemistry.
MaxQuant with MaxLFQ uses delayed normalization and peptide ratio models on many DDA cohorts (Cox et al. 2014). Proteome Discoverer offers parallel LFQ nodes with different defaults. The cohort block should use one chain end to end.
Unlabeled data-independent acquisition (DIA) or SWATH-style files usually require DIA extractors such as library-based or library-free engines, not DDA-centric PD nodes alone (Label-Free DIA Quantitative Proteomics).
Spectral counting can be exported from search results but is a weak primary metric for group fold changes when MS1 areas are available.
R-centric packages such as MSstats consume peptide tables from Proteome Discoverer or other exporters when input formats match.
Method route context appears in Mass Spectrometry-Based Quantitative Proteomics: Labeled and Label-Free Quantification Strategies.
End-to-End Workflow When Proteome Discoverer Is Declared
A practical Proteome Discoverer LFQ spine usually runs as follows.
- Confirm matrix, contrast, relative claim, and that DDA LFQ fits the question.
- Prepare matched digests to injection-ready loads without discovery tags.
- Acquire separate LC-MS/MS runs with interleaved order when cohort size allows.
- Import raw files into a locked Proteome Discoverer version and workflow template.
- Search with fixed FDR, modification, and database settings.
- Extract label-free features; roll up proteins with a declared rule.
- Normalize within the workflow or export for external mixed-model testing.
- Apply missing-value policy; run matrix QC before contrast statistics.
- Test predefined contrast only; archive workflow file and version with deliverables.
Steps 1 through 3 are experimental layers. Steps 4 through 9 are Proteome Discoverer layers when that processor is in scope.
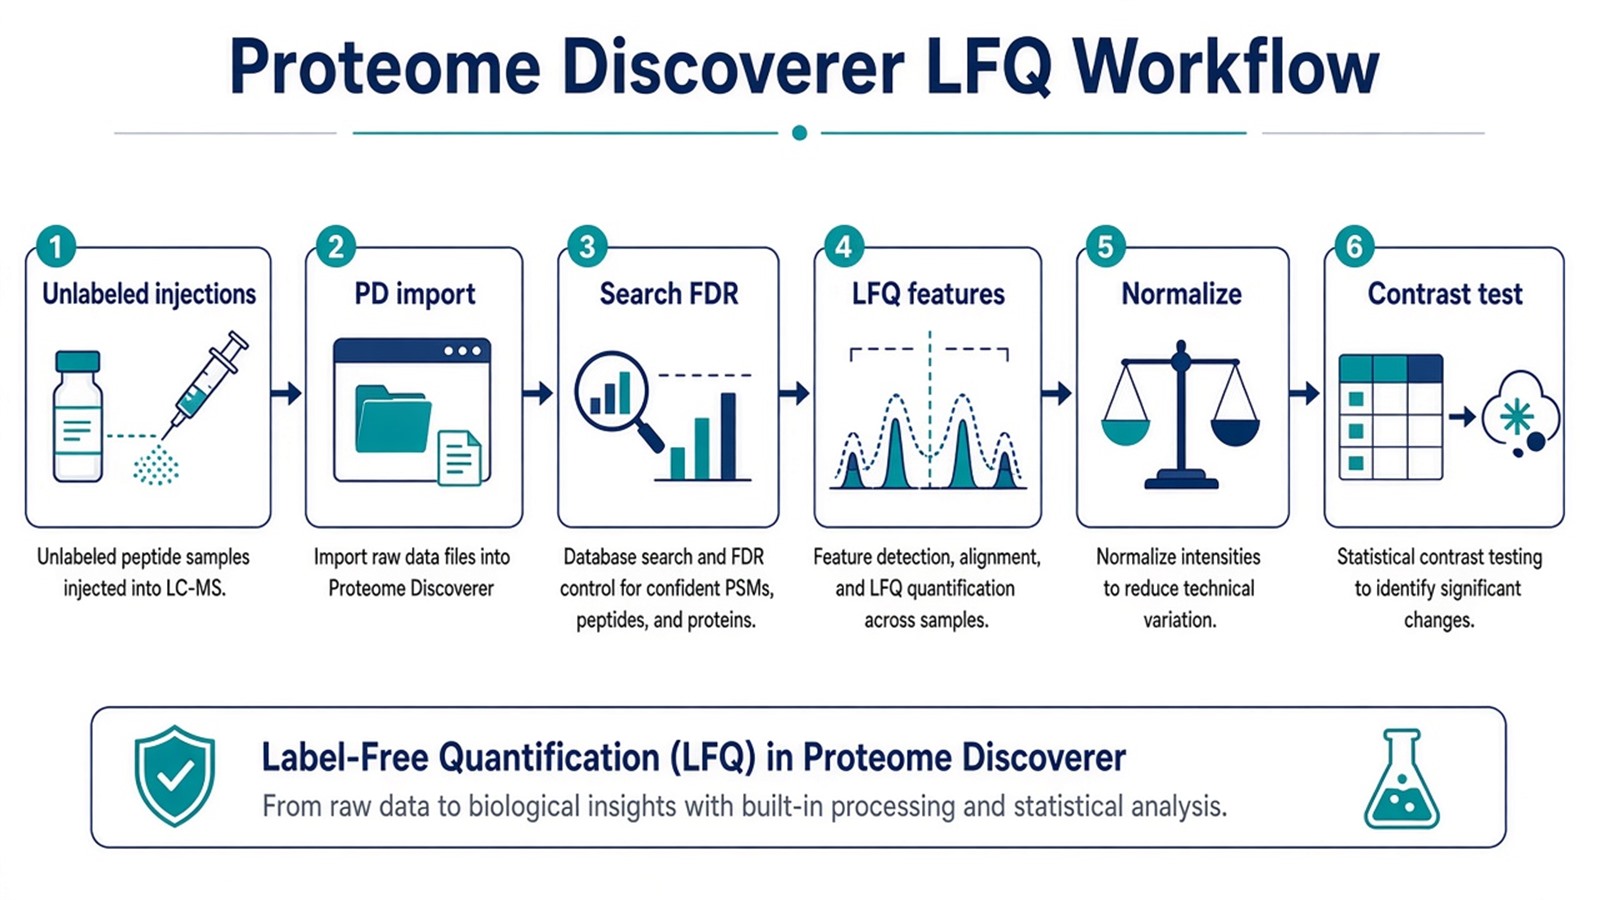
Figure 1. Proteome Discoverer sits in the analysis record after acquisition; prep and run order remain upstream gates.
Experiment framing appears in A Guide to Label-Free Quantitative Proteomics: From Experiment to Data Analysis. Normalization choices appear in How to Normalize Data in Label-Free Quantitative Proteomics?.
Parameters That Must Be Locked in Proteome Discoverer LFQ Runs
Layer |
Parameter that must be declared |
Failure mode if ignored |
|---|---|---|
Software |
Proteome Discoverer version and workflow file |
Mid-cohort template drift |
Search |
Database, enzyme, modifications, FDR |
Mixed search spaces |
Quant node |
Precursor feature definition |
Incomparable intensities |
Rollup |
Protein grouping rule |
Shared peptide ambiguity |
Normalization |
Method and study groups |
Global drift as biology |
Missing values |
Filter and imputation policy |
Hidden model bias |
Contrast |
Frozen before tuning |
Post hoc relabeling |
Export |
Table format for downstream stats |
Broken MSstats inputs |
Limits follow the same table. Proteome Discoverer does not remove batch confounding when run order tracks treatment. Low-abundance dropout remains common in DDA LFQ (Lazar et al. 2016). Vendor node names do not substitute for biological replicates.
Reproducibility remediation appears in How to Overcoming Reproducibility Issues in Label-Free Proteomics?. Prep discipline appears in Quantitative Protein Analysis.
How to Choose Proteome Discoverer Versus Other LFQ Pipelines
Use acquisition route, cohort block plan, and follow-up unit together.
Project need |
Processing plan that often fits |
Recheck before committing |
|---|---|---|
Thermo DDA raw, PD in scope |
Locked Proteome Discoverer workflow |
MaxQuant mid block without record |
Multi-vendor DDA, open tools |
MaxQuant MaxLFQ chain |
Forced PD without raw compatibility |
Unlabeled DIA or SWATH cohort |
DIA extractor plus stats |
PD DDA nodes on DIA files |
External mixed models required |
PD export to MSstats-compatible table |
Manual copy errors between tools |
High missingness after QC |
Pilot unlabeled DIA or imputation policy |
Ignore batch before imputation |
Amount on named peptides |
Targeted SIS outside PD discovery |
PD ratios as clinical amount |
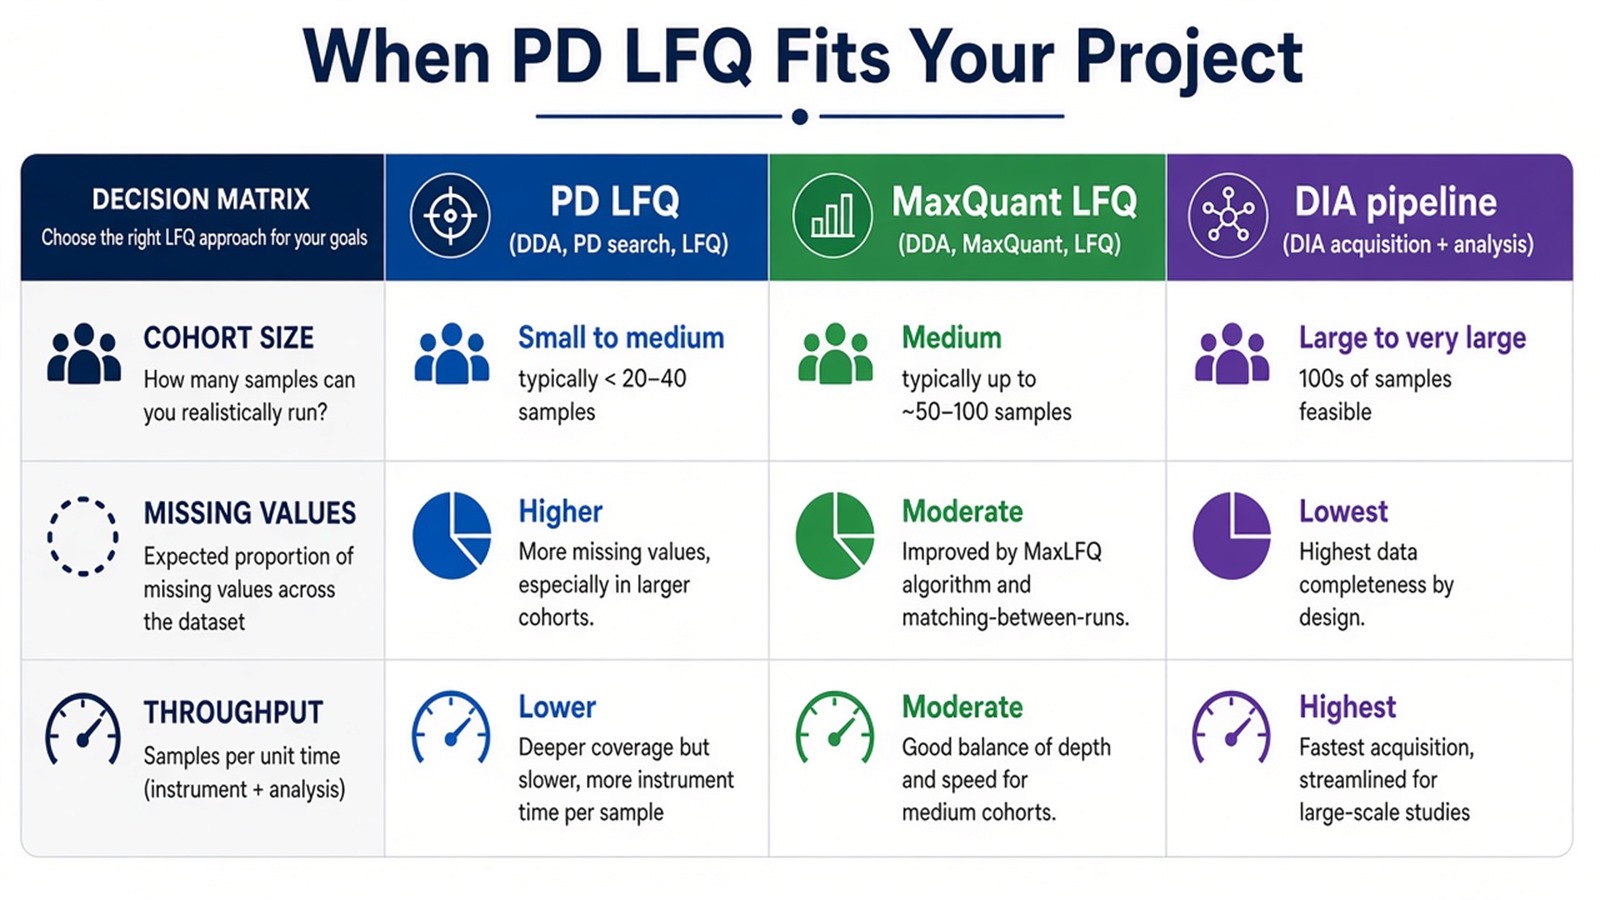
Figure 2. Choose Proteome Discoverer when DDA label-free files and a locked PD workflow fit the cohort block; DIA or targeted routes use other chains.
Route selection appears in Protein Quantification Method. Enrollment checks appear in Exploring Quantitative Analysis in Proteomics.
Teams with acquisition format, contrast design, and pipeline scope can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for Proteome Discoverer alignment when declared in the project record.
Frequently Asked Questions
1. Is Proteome Discoverer the same as label-free quantification?
No. Label-free names unlabeled separate injections. Proteome Discoverer is one processing environment for search and quant nodes on compatible raw data.
2. Can Proteome Discoverer process SWATH files alone?
DIA or SWATH-style quantification usually needs DIA-aware extractors. Proteome Discoverer may participate in parts of the chain when the workflow documents DIA nodes and libraries.
3. Should MaxQuant and Proteome Discoverer be mixed in one contrast?
Not without treating each processor block as a separate analysis segment with documented bridging if required.
4. Does Proteome Discoverer replace normalization review?
No. Normalization scope and QC plots still need review against run metadata.
5. When should projects skip Proteome Discoverer?
When pilots show another locked pipeline already meets contrast needs on the same raw format and cohort block.
MtoZ Biolabs can discuss label-free processing plans when raw format, Proteome Discoverer workflow scope, and contrast design are documented.
If further evaluation of PD versus MaxLFQ lock, export to external stats, or DIA handoff is needed, project details can be submitted for a feasibility review.
Reference
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
- M. Bantscheff, S. Lemeer, H.U. Haab, B. Kuster (2012). Quantitative mass spectrometry in proteomics: a critical review. Anal. Bioanal. Chem., 404, 939-965. https://doi.org/10.1007/s00216-012-5892-4
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- M. Choi, C. Chang, N. Clough, D. Broudy, T. Killeen, B. MacLean, M. Vitek (2014). MSstats: an R package for statistical analysis of quantitative mass spectrometry-based proteomic experiments. Bioinformatics, 30, 2524-2526. https://doi.org/10.1093/bioinformatics/btu305
