



Label-free proteomics analysis in discovery usually means label-free quantification (LFQ) on unlabeled liquid chromatography-tandem mass spectrometry (LC-MS/MS) injections. Project teams ask about advantages because open cohorts, staggered enrollment, and separate sample streams often fit unlabeled prep. The same teams must weigh tradeoffs: missing values in data-dependent acquisition (DDA), run-count cost, batch sensitivity, and relative-only claims (Bantscheff et al. 2012; Cox et al. 2014). The guide below states label-free LFQ strengths and limits in project language and ties them to workflow, parameters, and route choice. It is not a one-sided marketing list, not a claim that label-free beats every labeled design, and not a diagnostic or biomarker promise page.
Advantages appear only when contrast design, prep parity, locked acquisition, and one processing pipeline match the question. Limits appear when multiplex labeling, cultivable SILAC, or targeted amount on named peptides is the real need (Gerber et al. 2003).
In MtoZ Biolabs offerings, label-free analysis is scoped when documented pilots support separate unlabeled injections and a frozen relative contrast.
LFQ spine context appears in LFQ. Chemistry definition appears in What Is Label-Free Analysis?.
When Label-Free LFQ Advantages Matter in Real Projects
Strengths are situational, not automatic.
Open enrollment without a shared labeling day favors unlabeled separate injections. Each arm can enter after matched prep without waiting for a multiplex tagging slot.
No discovery tags avoids isobaric ratio compression and metabolic label routing decisions on the main contrast path. Prep still must match across arms.
Flexible cohort sizing adds injections as samples arrive, at the cost of more LC-MS/MS runs than a same-day TMT set.
Relative discovery on many matrices is supported when MS1 or DIA fragment LFQ pipelines are locked and QC passes before statistics.
Pilot-friendly entry allows a short unlabeled block to test prep and missingness before committing full scale.
Label-free advantages hold when prep, run order, and processing stay locked; they erode when batch tracks treatment or methods drift mid cohort.
Experimental scope appears in Label-Free LC-MS/MS.
Practical Limitations and Tradeoffs of Label-Free LFQ
Every listed strength carries a paired cost.
Separate injections increase instrument time versus same-day multiplex when all arms can be tagged together.
DDA LFQ shows stochastic missingness at low abundance. Missing values complicate contrast testing unless policy is declared (Lazar et al. 2016).
Dynamic range is wide in theory but ion suppression and load still compress quantifiable depth on complex lysates.
No tag does not remove batch effects. Run order confounding needs interleaving and design, not only normalization.
Relative LFQ matrices do not deliver molar amount on named peptides without SIS or PRM follow-up.
High identification counts do not prove contrast integrity or replicate balance (How Many Proteins Can Label-Free Detect?).
Quality limits appear in How to Improve Data Quality and Reproducibility in Label-Free Proteomics?.
Label-Free Versus Labeling Routes on the Same Decision Axes
Compare routes on enrollment, claim unit, and follow-up, not slogans.
Decision axis |
Label-free LFQ tendency |
Labeled or targeted tendency |
|---|---|---|
Enrollment |
Staggered, open cohort |
Closed arms, same labeling day |
Chemistry steps |
No discovery tags |
SILAC, TMT, or iTRAQ required |
Run structure |
One sample per injection common |
Multiplex per injection common |
Primary metric |
MS1 or DIA fragment LFQ |
Reporter or SILAC pair ratios |
Missing data |
Common in DDA |
Tag loss or ratio compression |
Follow-up amount |
Needs PRM or SIS |
May still need targeted assay |
Pilot cost |
Few unlabeled runs |
Tag inventory and mixing rules |
Method routes appear in Protein Quantification Method. DIA tradeoffs appear in Label-Free DIA Quantitative Proteomics.
End-to-End Workflow Where Pros and Cons Are Tested
A practical label-free advantage check usually runs as follows.
- Write contrast, claim unit, and alternatives if label-free limits appear.
- Prepare matched digests without discovery tags.
- Run a pilot with locked gradient, load, and acquisition template.
- Score quantifiable proteins, missingness, and replicate overlap before scale-up.
- Compare pilot against unlabeled DIA if DDA missingness blocks the contrast.
- Lock one processing pipeline version for the cohort block.
- Acquire interleaved injections when cohort size allows.
- Normalize and apply missing-value rules; QC before statistics.
- Test frozen contrast; archive methods with deliverables.
Steps 3 through 5 turn marketing advantages into evidence. Steps 6 through 9 protect comparability.
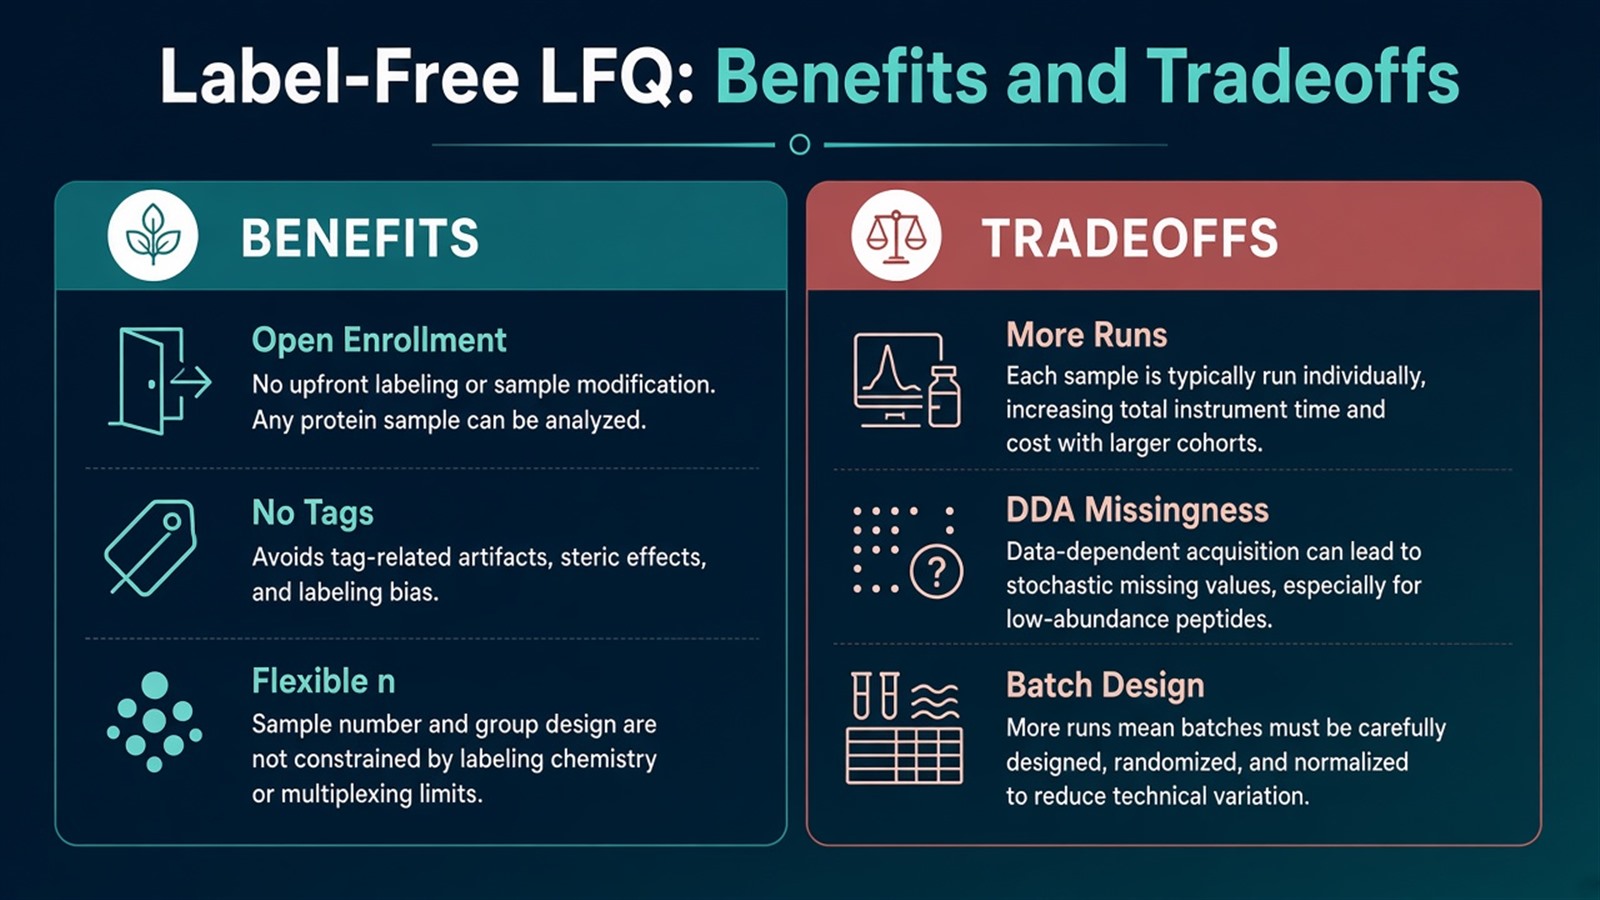
Figure 1. Advantages apply after pilot QC; limitations appear when missingness, batch, or claim unit mismatch label-free scope.
Normalization choices appear in How to Normalize Data in Label-Free Quantitative Proteomics?. Reproducibility remediation appears in How to Overcoming Reproducibility Issues in Label-Free Proteomics?.
Parameters That Shift Label-Free Benefit Versus Risk
Layer |
Parameter that must be declared |
Advantage side when locked |
Risk side when loose |
|---|---|---|---|
Prep |
Matched across arms |
Comparable peptide pools |
False biology from prep drift |
Injection |
Separate unlabeled runs |
Open enrollment |
Longer instrument schedule |
Acquisition |
DDA or DIA template fixed |
Stable LFQ features |
Mixed modes in one matrix |
Run order |
Interleaving across groups |
Batch visible in QC |
Treatment tracks day |
Search |
FDR and database fixed |
Auditable IDs |
Inflated protein lists |
Quant |
MS1 or fragment rule fixed |
Fold-change ready tables |
Mixed metrics |
Missing values |
Policy before testing |
Honest contrast |
Hidden imputation bias |
Contrast |
Frozen groups |
Defensible statistics |
Post hoc arm relabeling |
Limits follow the same table. Label-free analysis does not simplify poor replicate planning or undefined contrasts. Software brand does not remove missingness in DDA.
Processing context appears in Tools for Label-free Peptide Quantification. Decode chain context appears in Decoding Proteomics: A Dive into Label-Free Technology.
How to Choose Label-Free Analysis or an Alternative
Use pilot evidence, enrollment, and follow-up unit together.
Project need |
Route that often fits |
Recheck before committing |
|---|---|---|
Staggered open cohort |
Label-free LFQ |
TMT same-day assumption |
All arms ready, one tag day |
TMT or iTRAQ multiplex |
Forced LFQ when mixing required |
Cultivable SILAC system |
Metabolic labeled discovery |
Label-free when media routing fails |
DDA pilot high missingness |
Unlabeled DIA LFQ |
DDA when DIA adds little |
Low-abundance focus after pilot |
Fractionation or DIA |
Load alone as fix |
Amount on named peptides |
SIS or PRM |
Open LFQ as concentration |
High-throughput within tag budget |
Multiplex labeled |
Label-free run count underestimated |
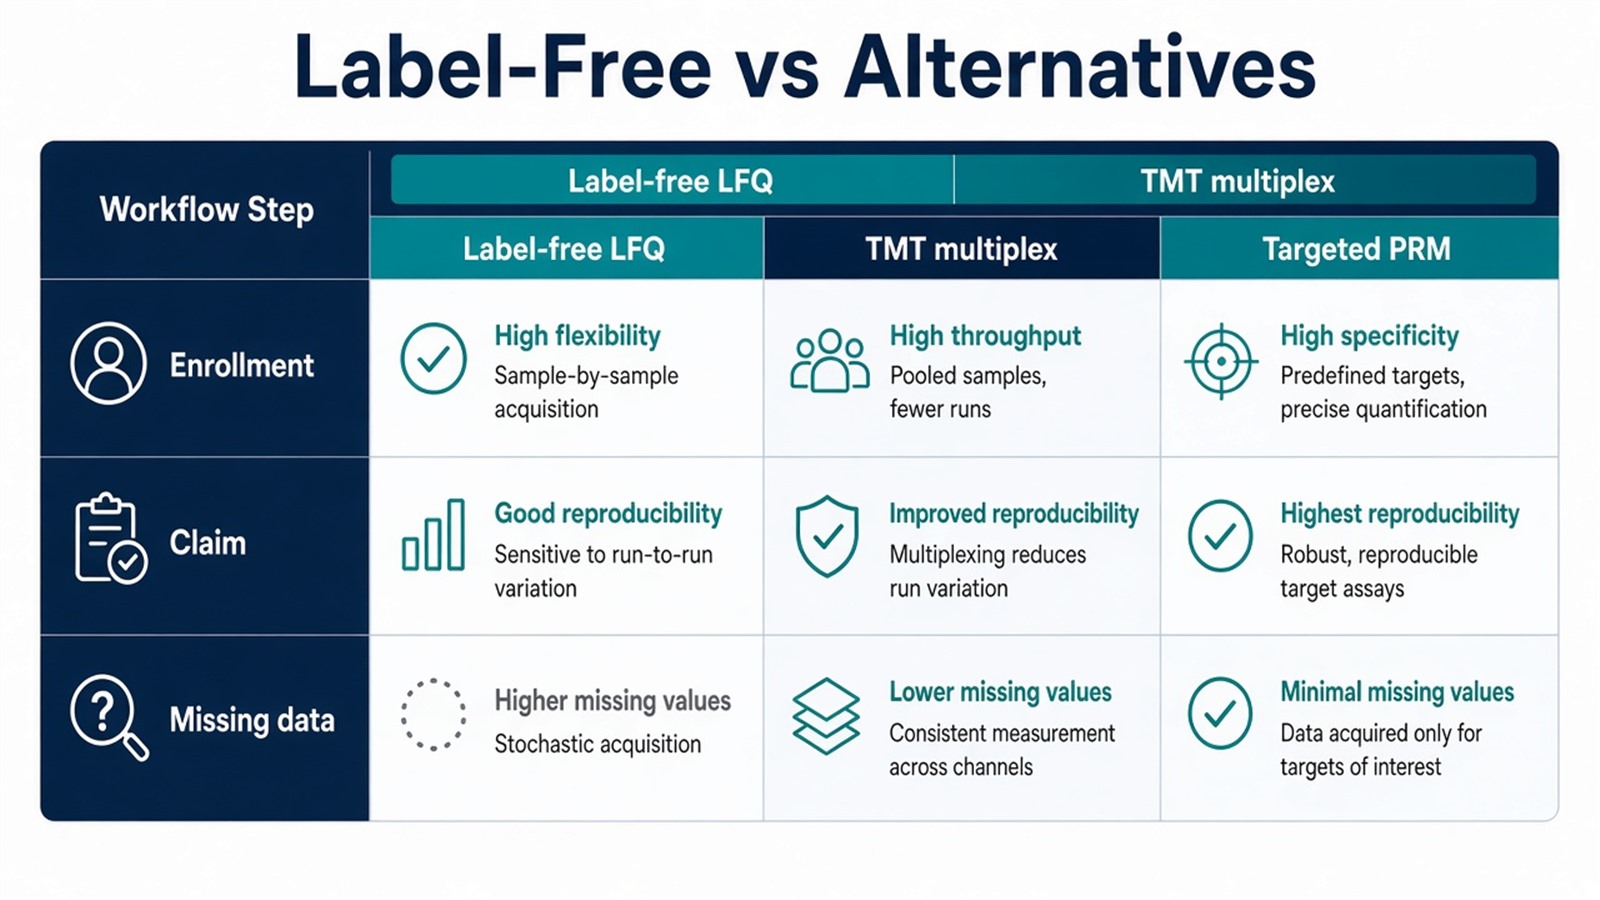
Figure 2. Choose label-free when pilots support separate injections and relative contrasts; choose labeling or targeted routes when enrollment or claim unit demands it.
Enrollment checks appear in Exploring Quantitative Analysis in Proteomics. Prep discipline appears in Quantitative Protein Analysis.
Teams with contrast map, pilot metrics, and follow-up intent can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for label-free analysis fit when declared in the project record.
Frequently Asked Questions
1. Is label-free analysis always cheaper than TMT?
Not always. Label-free avoids tag cost but often uses more separate injections. Total cost follows run count, cohort size, and prep complexity.
2. Does label-free sensitivity exceed labeled methods for every protein?
Low-abundance detection depends on matrix, load, acquisition, and missingness. Label-free removes tag chemistry effects but not ion suppression or DDA stochasticity.
3. Does wide dynamic range mean every protein quantifies in every replicate?
No. Dynamic range remains limited by suppression and acquisition mode. Many proteins appear in identification lists but drop out of quant columns.
4. When do label-free advantages disappear?
When batch confounds treatment, prep differs between arms, acquisition changes mid block, or the brief needs multiplex same-day comparison that unlabeled separate runs cannot support.
5. Should label-free be the default for every proteomics project?
No. Route follows enrollment, claim unit, and pilot missingness. Labeled or targeted designs remain appropriate for closed multiplex arms or amount claims on named peptides.
MtoZ Biolabs can discuss label-free analysis fit when contrast design, pilot data, and follow-up goals are documented.
If further evaluation of label-free versus TMT or SILAC, DDA versus unlabeled DIA pilots, or discovery-to-targeted staging is needed, project details can be submitted for a feasibility review.
Reference
- M. Bantscheff, S. Lemeer, H.U. Haab, B. Kuster (2012). Quantitative mass spectrometry in proteomics: a critical review. Anal. Bioanal. Chem., 404, 939-965. https://doi.org/10.1007/s00216-012-5892-4
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
