



Data-independent acquisition (DIA) strengthens relative protein quantification by fragmenting precursors in scheduled m/z windows, which can lower stochastic missingness compared with intensity-triggered data-dependent acquisition (DDA) and allow later re-extraction of fragment chromatograms. The matching limitations are window interference in chimeric MS2 spectra, dependence on library quality or library-free search settings, heavier analysis tooling demands, and the fact that ordinary DIA intensities remain relative rather than absolute. SWATH-MS is one sequential-window DIA implementation, often library-based, not a separate claim that removes those limits (Gillet et al. 2012). DIA advantages appear only when chromatography, batch design, and false discovery rate (FDR) control stay coherent across the cohort.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Deep DIA Proteomics Service for project-specific feasibility and analysis planning.
Strengths and Limitations at a Glance
Dimension |
DIA strength when controls hold |
Matching DIA limitation |
|---|---|---|
Coverage pattern |
Scheduled windows can recover peptides missed by stochastic top-N picks |
Window multiplexing raises fragment interference |
Missing values |
Often more complete relative matrices across runs |
Completeness is not the same as accuracy |
Reproducibility |
Fixed acquisition logic supports cohort consistency |
Run-order, column, and batch drift still matter |
Data reuse |
Stored fragment evidence can be re-extracted under updated libraries or searches |
Re-analysis inherits library gaps and search assumptions |
Quantitative claim |
Relative same-protein discovery at scale |
Absolute concentration needs matched standards |
Analysis path |
Library-based SWATH-style or library-free DIA available |
Software, FDR, and interference filters decide usable peaks |
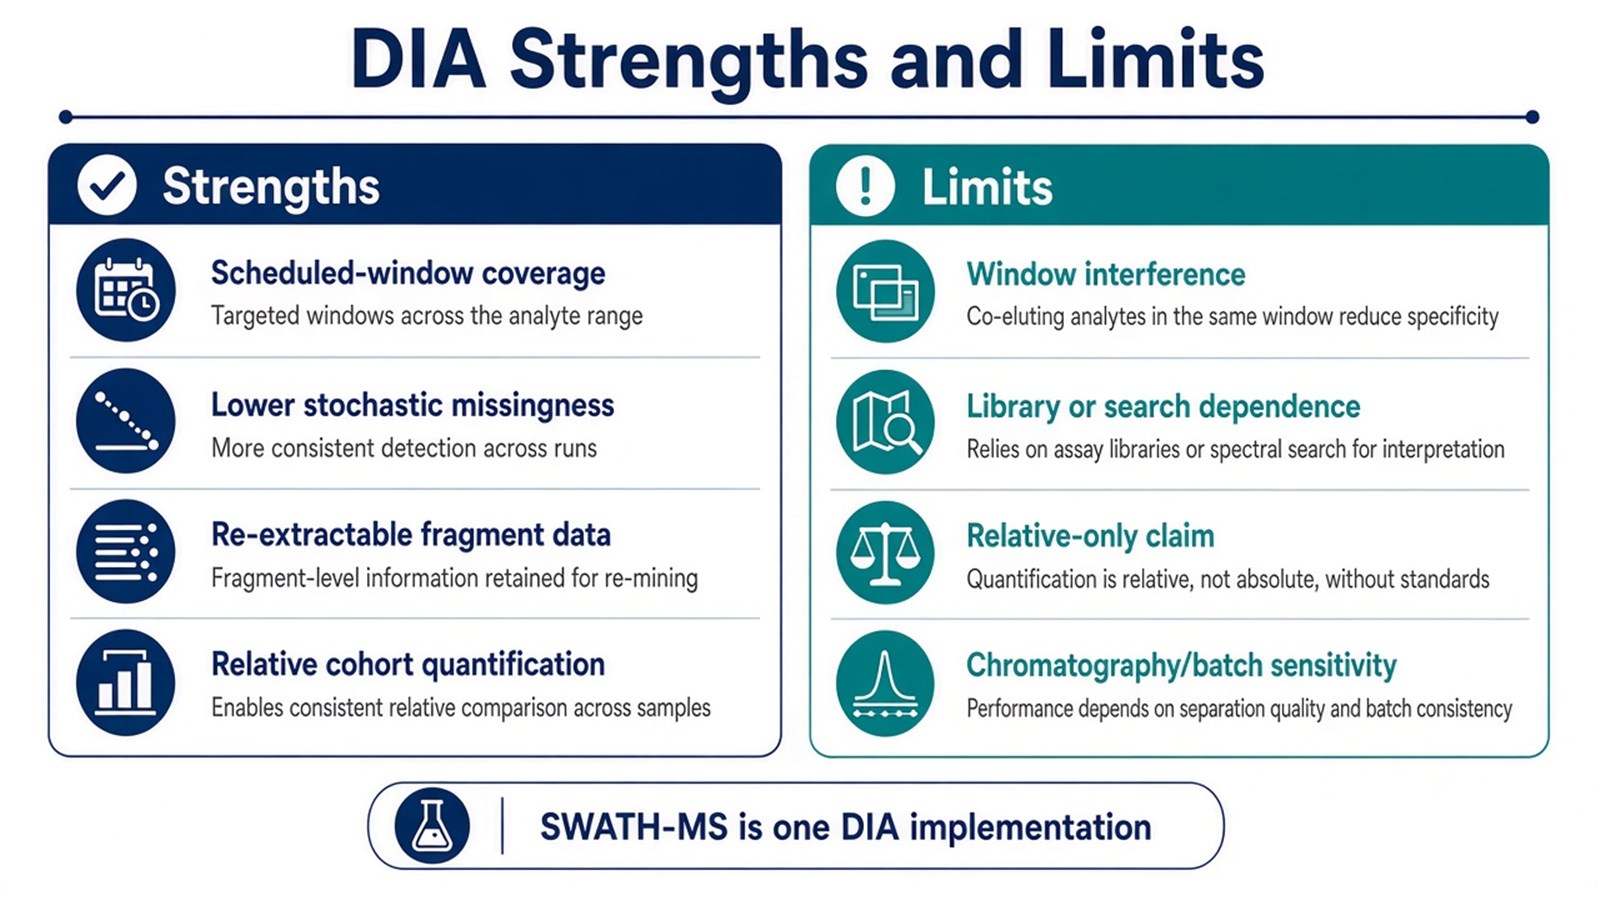
Figure 1. DIA strengths and limits arise together: scheduled-window coverage improves relative cohort matrices, while interference and relative-only claims remain design constraints.
A more complete DIA matrix is still a relative matrix; it is not proof of absolute amount or interference-free peaks.
Where the Strengths Come From
DIA divides the precursor range into isolation windows and fragments ions in each window on a fixed schedule. Peptide quantities are commonly recovered from extracted fragment-ion chromatograms rather than only from precursors that happened to be selected as top peaks in DDA. That design is why DIA is used for larger unlabeled cohorts that need consistent fragment coverage.
SWATH-style workflows typically match transitions to a spectral library (Gillet et al. 2012). Library-free or Direct DIA routes reduce dependence on a separate empirical library but still require FDR control and interference review (Demichev et al. 2020). Naming DIA or SWATH does not specify instrument vendor, window scheme, or labeling chemistry.
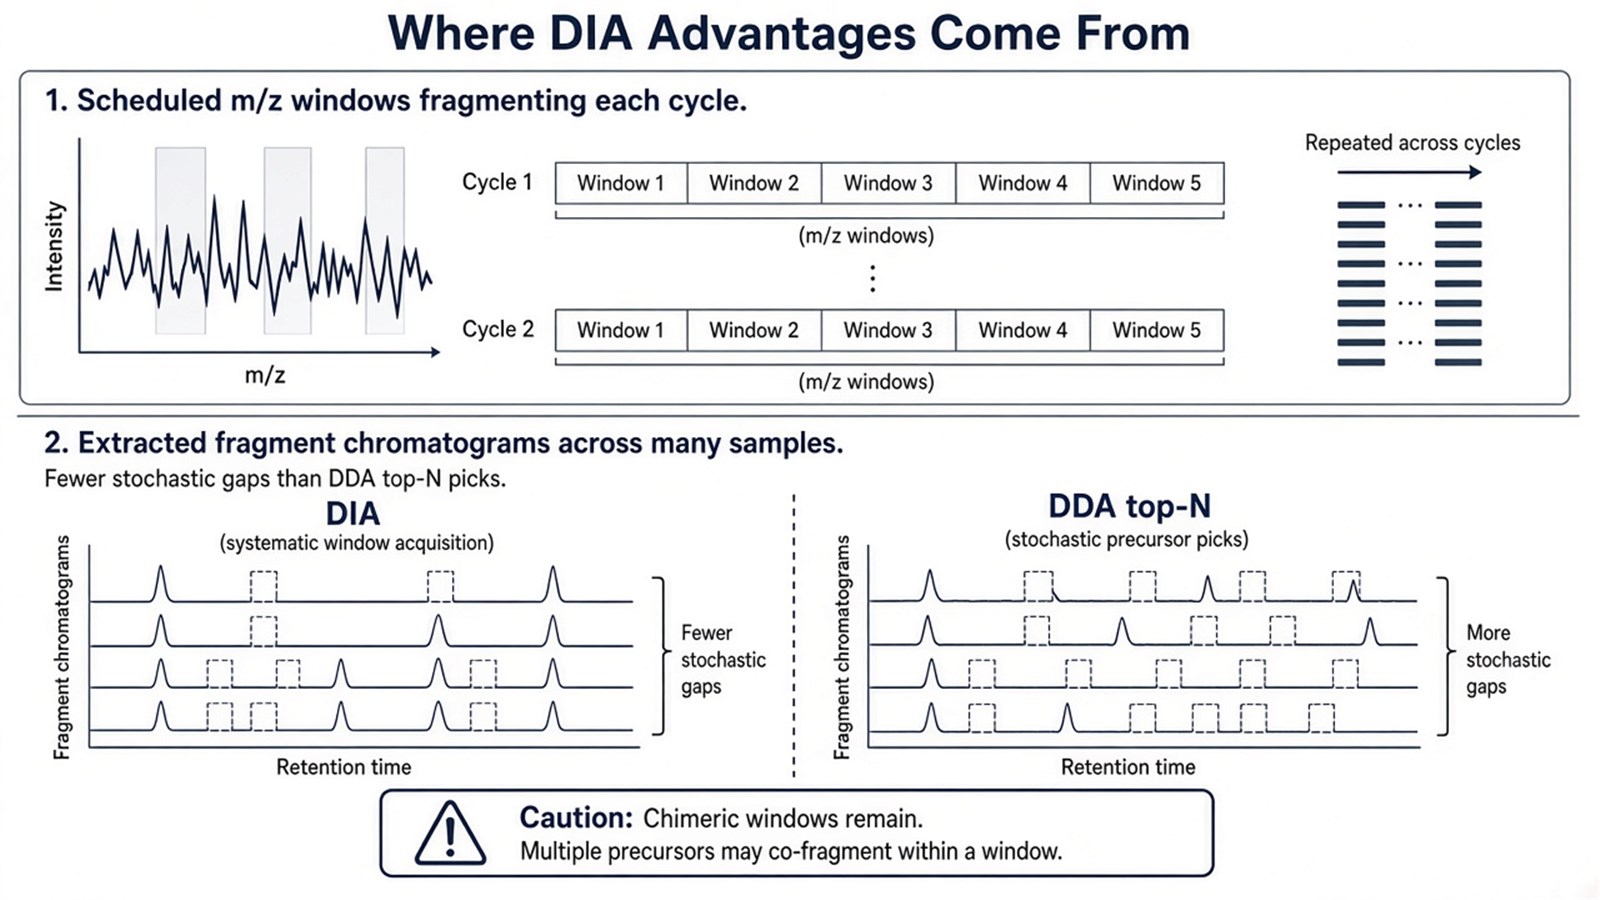
Figure 2. DIA advantages come from scheduled-window fragment coverage; chimeric windows are the main accuracy cost of that design.
For selection against DDA beyond this strengths-and-limits page, researchers can refer to DIA vs DDA Proteomics: Key Differences and Applications Explained. For definitions of DIA versus SWATH, see What Is DIA and SWATH? Understanding Data-Independent Acquisition in Proteomics?.
Where the Limitations Bite
Window interference
Multiple precursors in one window contribute fragments to the same spectrum. Narrower or variable windows, better chromatography, and stricter peak-group filters reduce but do not erase that risk.
Library and search dependence
Library-based SWATH-style quantification cannot recover peptides absent from the library. Library-free search expands reach under model assumptions and still needs QC. Unmatched libraries transfer tissue or batch bias into the matrix.
Relative-only claim and upstream chemistry
Ordinary DIA intensities support same-protein relative comparison inside one coherent plan. Absolute amount requires stable isotope-labeled standards (SIS) and a calibration model. Digestion mismatch and confounded run order remain upstream failures that software cannot repair.
Analysis and PTM difficulty
DIA processing depends on specialized tools and declared FDR rules. Low-abundance modified peptides can be especially hard because enrichment, co-fragmentation, and site assignment add layers beyond unmodified discovery DIA.
Judgment Criteria: When DIA Strengths Outweigh the Limits
Study need |
DIA often worth the trade-off |
Reassess before committing |
|---|---|---|
Claim |
Relative unlabeled discovery across many runs |
Absolute units or clinical cutoff |
Missing-value risk |
Stochastic DDA gaps would dominate statistics |
Simple matrix where DDA depth already suffices |
Library logistics |
Matched library available, or library-free DIA planned |
No workable library or library-free path |
Interference tolerance |
Window design and QC can be enforced |
Severe chimeric interference expected without mitigation |
Panel status |
Open discovery inventory still needed |
Closed shortlist ready for PRM or MRM |
Prefer DIA when scheduled-window completeness is the scarce resource for relative discovery. Prefer DDA when cleaner single-precursor MS2 or library building comes first. Prefer Direct DIA when empirical library construction is the bottleneck. Prefer PRM or MRM when targets are already closed.
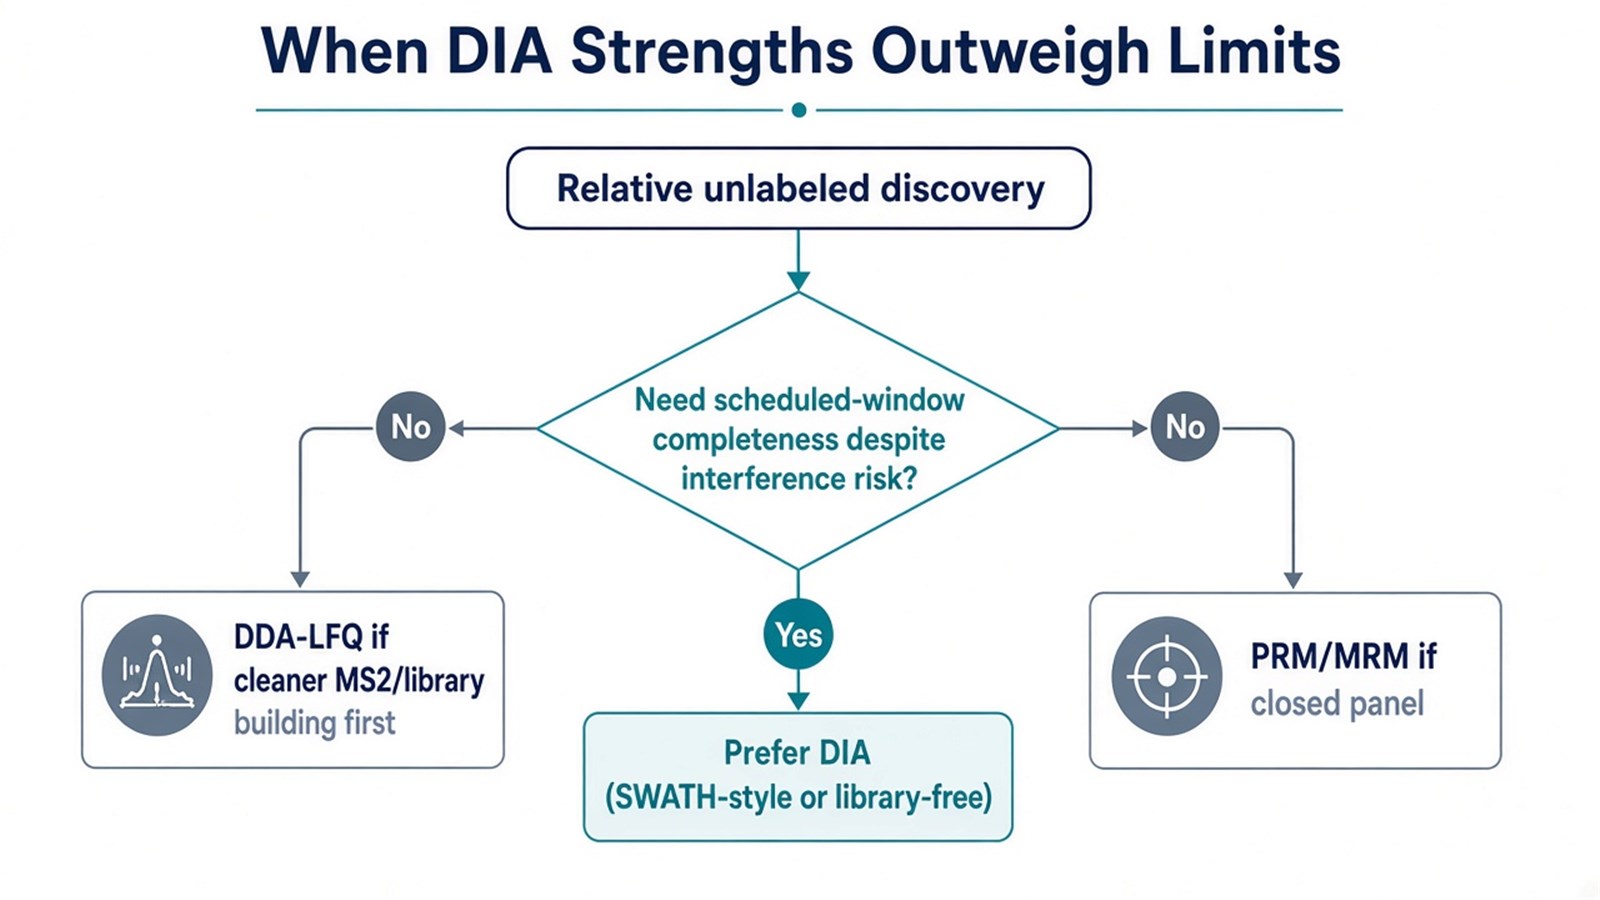
Figure 3. Use DIA when relative cohort completeness justifies window-interference management; keep DDA or targeted assays when the claim or panel status differs.
Applications and Boundaries
Typical applications are treatment or genotype screens, tissue or biofluid discovery cohorts, projects that may re-extract stored DIA files, and unlabeled studies that later confirm a shortlist by PRM. Pathway enrichment on a DIA candidate list reflects overrepresentation relative to a quantified background. It does not prove pathway activity. Diagnostic cutoffs sit outside ordinary research DIA reporting unless a separately validated assay framework is in place.
Fixed protein-count or CV claims without matrix, gradient, and filter details overstate what method class alone decides. Report window scheme, library or library-free route, FDR, normalization, and QC with every strength statement.
Once the relative claim, library strategy, and interference controls are defined, the project can be evaluated as a DIA quantification study. Researchers can review the MtoZ Biolabs Deep DIA Proteomics Service for sample evaluation, feasibility assessment, and workflow planning. For library-free extraction, see Direct DIA: High-Efficiency Proteomics without a Spectral Library.
Frequently Asked Questions
1. Is lower missingness the same as higher accuracy?
No. DIA can fill the matrix more consistently and still quantify interfered transitions incorrectly. Accuracy needs peak-group QC, not completeness alone.
2. Does SWATH remove DIA limitations?
No. SWATH-MS is one DIA implementation. It inherits window interference and relative-only claims, and it adds library dependence when library extraction is used.
3. Can DIA provide absolute protein quantification?
Not from ordinary intensities. Absolute amount requires matched standards and a calibration model.
4. When do DIA strengths fail in practice?
When libraries are unmatched, run order is confounded, windows are too wide for the matrix, or FDR and interference filters are undeclared.
5. Should every DDA project switch to DIA?
No. Switch when scheduled-window relative completeness is worth the interference and analysis cost. Keep DDA for identification-first or library-building priorities.
Reference
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
