



Mutual protein identification is a claim that both members of a named pair have been recovered by a defined experiment, not a claim that a structure or a predicted edge has been solved. In mass spectrometry work, the phrase usually points to one of three records: both proteins appear in a single IP-MS eluate, each protein recovers the other in reciprocal captures, or an inter-chain crosslink names residues on both partners. Computational tools can propose a mutual pair from sequence or literature. That proposal is not an experimental identification and should stay out of the results sentence until a capture or crosslink is measured.
The original mix-up is to treat any two protein names as mutually identified interactors. A spectrum search identifies sequences present in a sample. A database edge predicts or reprints an association. Neither output should be restated as reciprocal experimental proof. Researchers who already have two baits, matched controls, and a written pair claim can review MtoZ Biolabs Protein-Protein Interaction Analysis for feasibility. The broader split between MS analysis and prediction is covered in How Can Mass Spectrometry Be Used to Analyze or Predict Protein-Protein Interactions.
What Mutual Protein Identification Can Mean
Mutual protein identification should be defined before samples are processed. The weakest reading is that protein A and protein B were both identified in the same enrichment. The stronger reading is that A-directed capture recovers B above controls and B-directed capture recovers A above controls. A third reading is that XL-MS reports an inter-protein link between residues on A and B.
Each reading is an experimental constraint with a different strength. Co-identification in one tube can still be a shared complex, a contaminant, or a bridging protein (Hein et al. 2015). Reciprocal enrichment reduces one-way antibody or tag artifacts, but it still reports co-recovery, not a contact surface. An inter-chain crosslink constrains proximity for those two residues. It does not predict the rest of the interactome.
Prediction sits outside all three readings. A bidirectional STRING edge or a docking pose that names both chains is a model. It can prioritize which pair to test. It cannot be filed as an identification result.
IP-MS: Two Names in One Run Are Not Mutual Proof
IP-MS and AP-MS identify proteins that remain with a bait after capture and washing. If the bait is A, recovery of B is a one-direction enrichment record. Listing A and B together in the protein table is expected whenever A is the bait. That table is not mutual identification of an independent pair.
A one-direction list becomes more credible when empty-bead, isotype, or empty-tag controls are searched in parallel and when contaminant frequency is considered (Choi et al. 2011; Mellacheruvu et al. 2013). Even then, B can ride on a third protein. The constraint is: B was enriched with A under the submitted lysis and wash. The constraint is not: A and B identify each other, bind directly, or occupy a predicted interface.
Do not convert a Mascot or SEQUEST hit pair into a predicted structure. Search engines assign peptide identity. They do not assign mutual interaction. Antibody-based discovery intake is scoped through the IP-Mass Spectrometry Service. Projects that already have eluates from both members of a planned pair can be reviewed under the MS-Based Protein-Protein Interaction Analysis Service.
Reciprocal Capture and XL-MS as Mutual Experimental Constraints
Reciprocal IP-MS is the experimental form closest to mutual protein identification. Capture A, identify B versus controls. Capture B with a separate antibody or tag, identify A versus a matched control set. Both arms should use comparable lysis, wash, and digestion. A name that appears in only one arm remains a one-way candidate.
Reciprocal success still has limits. Shared background, common sticky proteins, and antibody cross-reactivity can appear in both directions. Membrane pairs and low-abundance partners can fail one arm because the second antibody is weak, not because the pair is false. Reciprocal MS is stronger than a single list. It is not a structure and not a prediction.
XL-MS supplies a different mutual constraint. An inter-protein crosslink identifies peptides from both chains in one covalently linked species (Leitner et al. 2016). That is mutual residue identification for those two positions. Intra-protein links do not count as mutual pair evidence. Missing links do not count as mutual exclusion. XL-MS should be scoped when the pair is already named and the sample can tolerate the reagent. Distance-restraint intake appears in the Crosslinking Mass Spectrometry Service.
Measured mutual records and predicted mutual pairs are not interchangeable labels. The comparison below keeps reciprocal MS and inter-chain XL-MS on the experimental side.
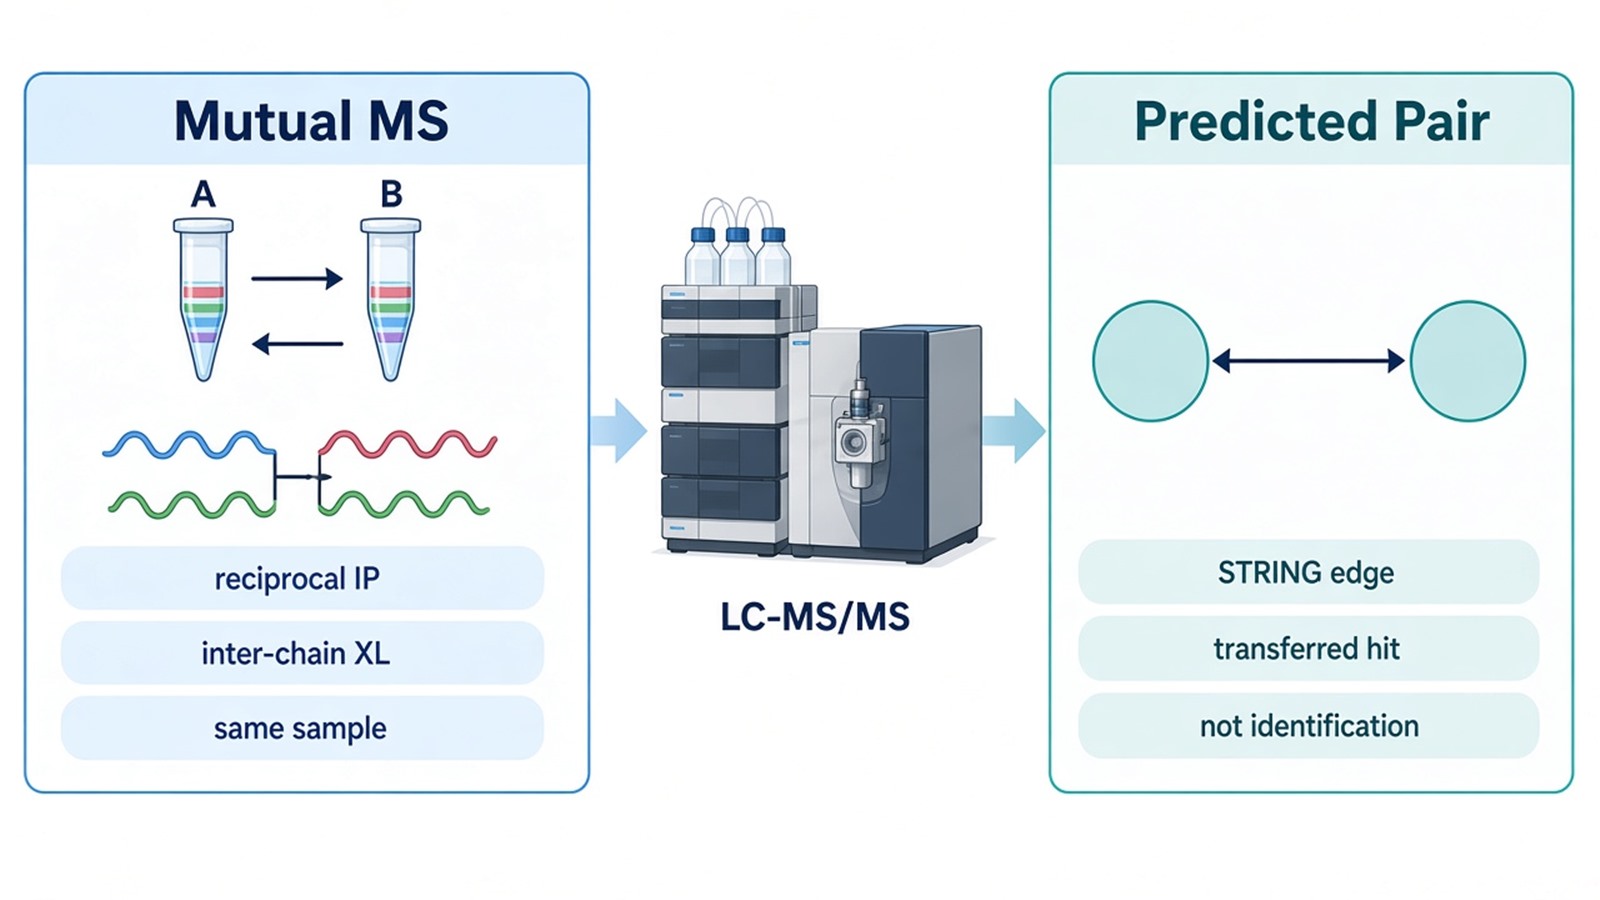
Figure 1. Mutual MS Identification vs Predicted Mutual Pair.
Predicted Mutual Pairs From Databases and Servers
Databases and prediction tools often draw an edge in both directions. STRING can report A-B with a composite score built from experiments, text mining, and interolog transfer (Szklarczyk et al. 2019). Homology or docking servers can return a pose that contains both chains. Residue classifiers can mark surfaces on each monomer.
Those outputs can supplement a two-bait identification plan. A published reciprocal AP-MS edge can justify running both baits. A docked pose can suggest lysines for XL-MS. A high-score residue on each chain can become a mutant pair. They remain supplements. A predicted mutual pair has not been identified in the current sample.
Keep score types separate. A STRING confidence value is not a SAINT probability and not a crosslink spectrum match. When the next task is residue shortlisting rather than pair identification, use the coordinate workflow in Protein-Protein Interface Analysis Server and attach any IP-MS or XL-MS tables as the reason the pair was chosen.
Evidence Limits of a Mutual-Identification Claim
A mutual-identification sentence should name the experiment that made it mutual. “A and B were both in the A-IP” is co-identification. “A recovered B and B recovered A” is reciprocal identification. “An A-B inter-link was identified” is residue-level mutual identification. “A and B are connected in a database” is not identification.
Claim that is often written |
Experiment that can support it |
What the record constrains |
What the record does not prove |
|---|---|---|---|
Both proteins were identified together |
One IP-MS or AP-MS run |
Presence in that eluate |
Mutual recovery or a contact |
Each protein identifies the other |
Reciprocal IP-MS with matched controls |
Two-way co-enrichment |
Direct binding or a pose |
Both chains are named in one link |
Inter-protein XL-MS |
Residue proximity within reagent reach |
A unique structure or a predicted network |
The pair is mutual in a database |
STRING or literature mining |
Prior or transferred association |
Identification in the submitted sample |
Both chains appear in a model |
Docking or assembly analysis |
A possible geometry |
That the pair was measured |
Combining a one-way IP-MS hit with a predicted mutual edge does not upgrade the sentence to reciprocal identification. Combining reciprocal IP-MS with docking does not upgrade the sentence to a solved interface. Mechanism-level domain, affinity, and mutation tests remain a later claim, outlined in Mechanism of Protein-Protein Interaction.
Sample mismatch is a second stop rule. Reciprocal identification requires two capture arms on comparable material. A purified-domain XL-MS link does not mutually identify the full-length pair in lysate. A predicted dimer does not stand in for the missing second IP.
Samples, Deliverables, and Feasibility Intake
For one-way IP-MS, send bait identity, antibody or tag, lysis and wash history, and controls. For reciprocal two-bait work, send both capture plans, both control arms, and construct maps so numbering and tags stay aligned. For XL-MS mutual residue identification, send the named pair, purity, buffer amines, and whether a model will be used only to interpret links.
The diagram below maps common mutual-ID wordings to the evidence that can support them during feasibility review.
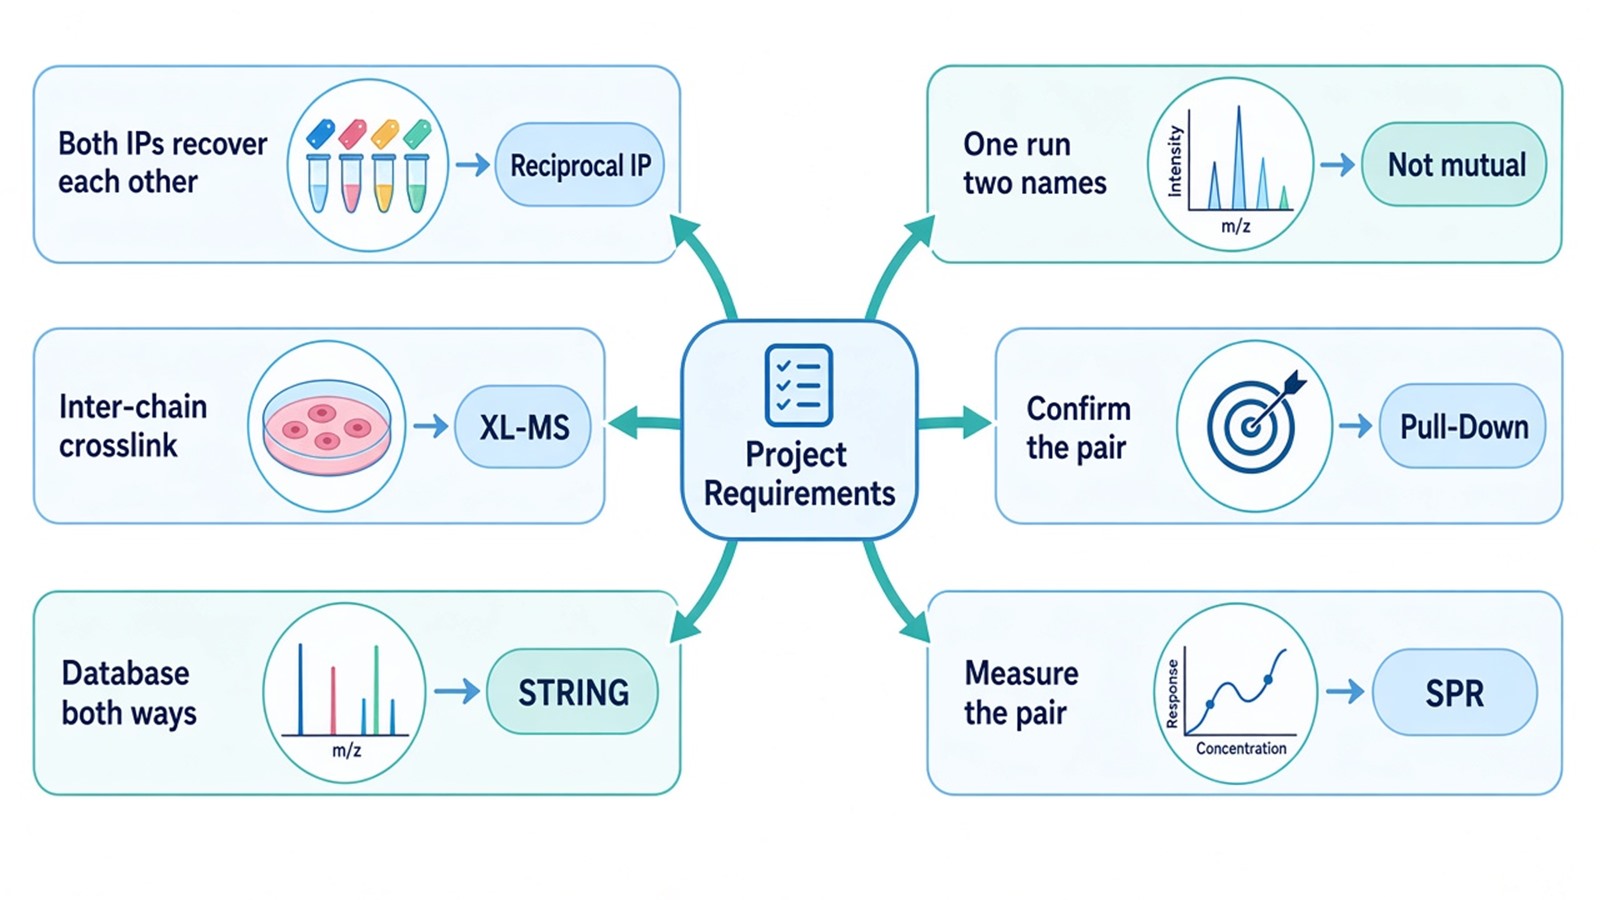
Figure 2. Matching Mutual-ID Claims With Evidence.
Deliverables should keep the claim label honest. One-way reports list proteins enriched with one bait. Reciprocal reports present both arms and a short overlap table. XL-MS reports list inter-protein residue pairs separately from intra-protein links. Database or docking files can be attached as supplements. They should not be titled as a mutual identification result. To start intake, send the intended claim, both protein names, available antibodies or tags, and sample format to info@MtoZ-Biolabs.com or use the site inquiry form so the experimental arm can be confirmed before shipment.
Frequently Asked Questions
1. If both proteins appear in one IP-MS table, is that mutual protein identification?
No. The bait is expected in its own eluate. A second name is a co-identified candidate. Mutual identification in the stronger sense needs a reciprocal capture or an inter-protein crosslink.
2. Does a reciprocal IP-MS pair prove a predicted binding site?
No. Reciprocal enrichment supports two-way co-recovery. A binding site still needs interface mapping, mutation, or a structure-level experiment. Prediction tools can suggest residues, but they do not complete the identification claim.
3. Can XL-MS be used instead of a second IP when the second antibody is unavailable?
It can supply mutual residue evidence for a named pair if the complex can be prepared and the reagent is compatible. It does not replace discovery-scale IP-MS for unknown partners. The missing second antibody should be stated in the project brief.
4. Is a bidirectional STRING edge equal to reciprocal MS?
No. The edge summarizes mixed prior information. Reciprocal MS measures two capture experiments on the current samples. A database edge can prioritize the second bait. It cannot skip that bait.
5. What should be sent if the goal is mutual protein identification rather than a broad interactome?
Name the two proteins, state whether the need is reciprocal IP-MS or inter-protein XL-MS, and list antibodies, tags, controls, and sample amounts for both arms. Feasibility review will not treat a prediction file as a substitute arm.
Researchers can specify which mutual protein identification record is required, then confirm both capture arms or the XL-MS pair through MtoZ Biolabs Protein-Protein Interaction Analysis intake.
Reference
- M.Y. Hein, N.C. Hubner, I. Poser, J. Cox, N. Nagaraj, Y. Toyoda, I.A. Gak, I. Weisswange, J. Mansfeld, F. Buchholz, et al. (2015). A human interactome in three quantitative dimensions organized by stoichiometries and abundances. Cell, 163, 712-723. https://doi.org/10.1016/j.cell.2015.09.053
- H. Choi, B. Larsen, Z.Y. Lin, A. Breitkreutz, D. Mellacheruvu, D. Fermin, Z.S. Qin, M. Tyers, A.C. Gingras, A.I. Nesvizhskii (2011). SAINT: probabilistic scoring of affinity purification-mass spectrometry data. Nat. Methods, 8, 70-73. https://doi.org/10.1038/nmeth.1541
- D. Mellacheruvu, Z. Wright, A.L. Couzens, J.P. Lambert, N.A. St-Denis, T. Li, Y.V. Miteva, S. Hauri, M.E. Sardiu, T.Y. Low, et al. (2013). The CRAPome: a contaminant repository for affinity purification-mass spectrometry data. Nat. Methods, 10, 730-736. https://doi.org/10.1038/nmeth.2557
- A. Leitner, M. Faini, F. Stengel, R. Aebersold (2016). Crosslinking and mass spectrometry: an integrated technology to understand the structure and function of molecular machines. Trends Biochem. Sci., 41, 20-32. https://doi.org/10.1016/j.tibs.2015.10.008
- D. Szklarczyk, A.L. Gable, D. Lyon, A. Junge, S. Wyder, J. Huerta-Cepas, M. Simonovic, N.T. Doncheva, J.H. Morris, P. Bork, et al. (2019). STRING v11: protein-interaction networks, with increased coverage and integration. Nucleic Acids Res., 47, D607-D613. https://doi.org/10.1093/nar/gky1131
