



Direct DIA, also called library-free DIA, is a data-analysis route for data-independent acquisition (DIA) files that identifies and quantifies peptides without first building an empirical spectral library from separate data-dependent acquisition (DDA) runs. DIA itself still fragments precursors in scheduled m/z windows; what changes is the extraction strategy. Classical SWATH-style workflows usually match transitions to a spectral library (Gillet et al. 2012). Direct DIA searches DIA spectra against a protein database, predicted fragment spectra, or a library generated from the DIA data themselves, under false discovery rate (FDR) control (Demichev et al. 2020). The practical gain is removing a library-construction block. The claim remains relative protein change across comparable runs, not absolute concentration, and window interference still requires QC.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Deep DIA Proteomics Service for project-specific feasibility and analysis planning.
What Direct DIA Changes, and What It Does Not
Three layers must stay separate. DIA is the acquisition schedule. SWATH-MS is one sequential-window DIA implementation that historically emphasizes library-based targeted extraction. Direct DIA is an analysis choice that removes dependence on an external empirical library for that project.
Direct DIA does not redefine labeling chemistry. Unlabeled digests are commonly acquired as DIA in discovery work, but a labeled digest could also be acquired with DIA in other designs. It does not remove chimeric spectra inside isolation windows. It does not make protein counts interchangeable with quantitative quality. And it does not automatically outperform a high-quality, sample-matched library when that library already covers the cohort well.
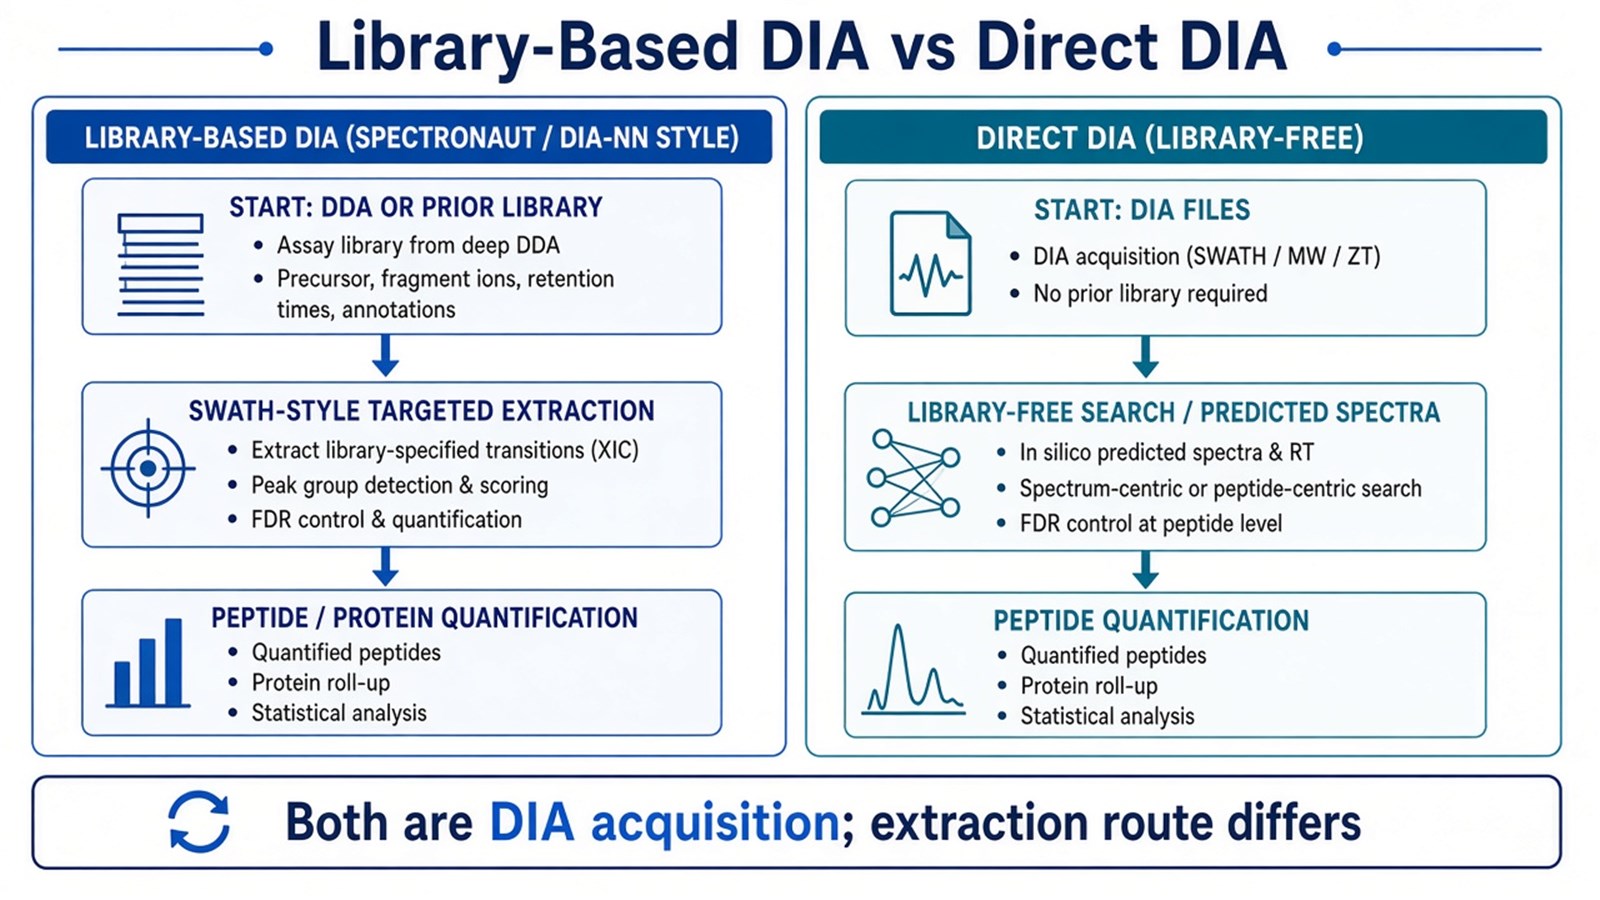
Figure 1. Library-based DIA and Direct DIA share DIA acquisition; they differ in whether quantification depends on an empirical spectral library.
Direct DIA removes an empirical-library prerequisite; it does not remove the need for FDR control, interference review, and a relative-only claim.
How Direct DIA Analysis Usually Works
A practical Direct DIA path still starts with matched digests, liquid chromatography, and DIA acquisition under one chromatographic plan. Analysis then proceeds without a separate DDA library campaign.
Predicted-spectrum or deep-learning-assisted tools can generate fragment expectations from peptide sequences and match them into DIA windows. Some pipelines also build an internal library from gas-phase fractionation or from the DIA files themselves. In either case, decoy strategies and protein-level FDR rules decide which peptides enter the matrix. Retention-time alignment, peak-group scoring, and interference filtering remain part of the quantitative step, commonly in tools such as DIA-NN or related library-free modes in other platforms (Demichev et al. 2020).
Computational cost can be high because many fragment traces are scored. Hardware acceleration helps throughput. It is an operations detail, not evidence that the biology is correct.
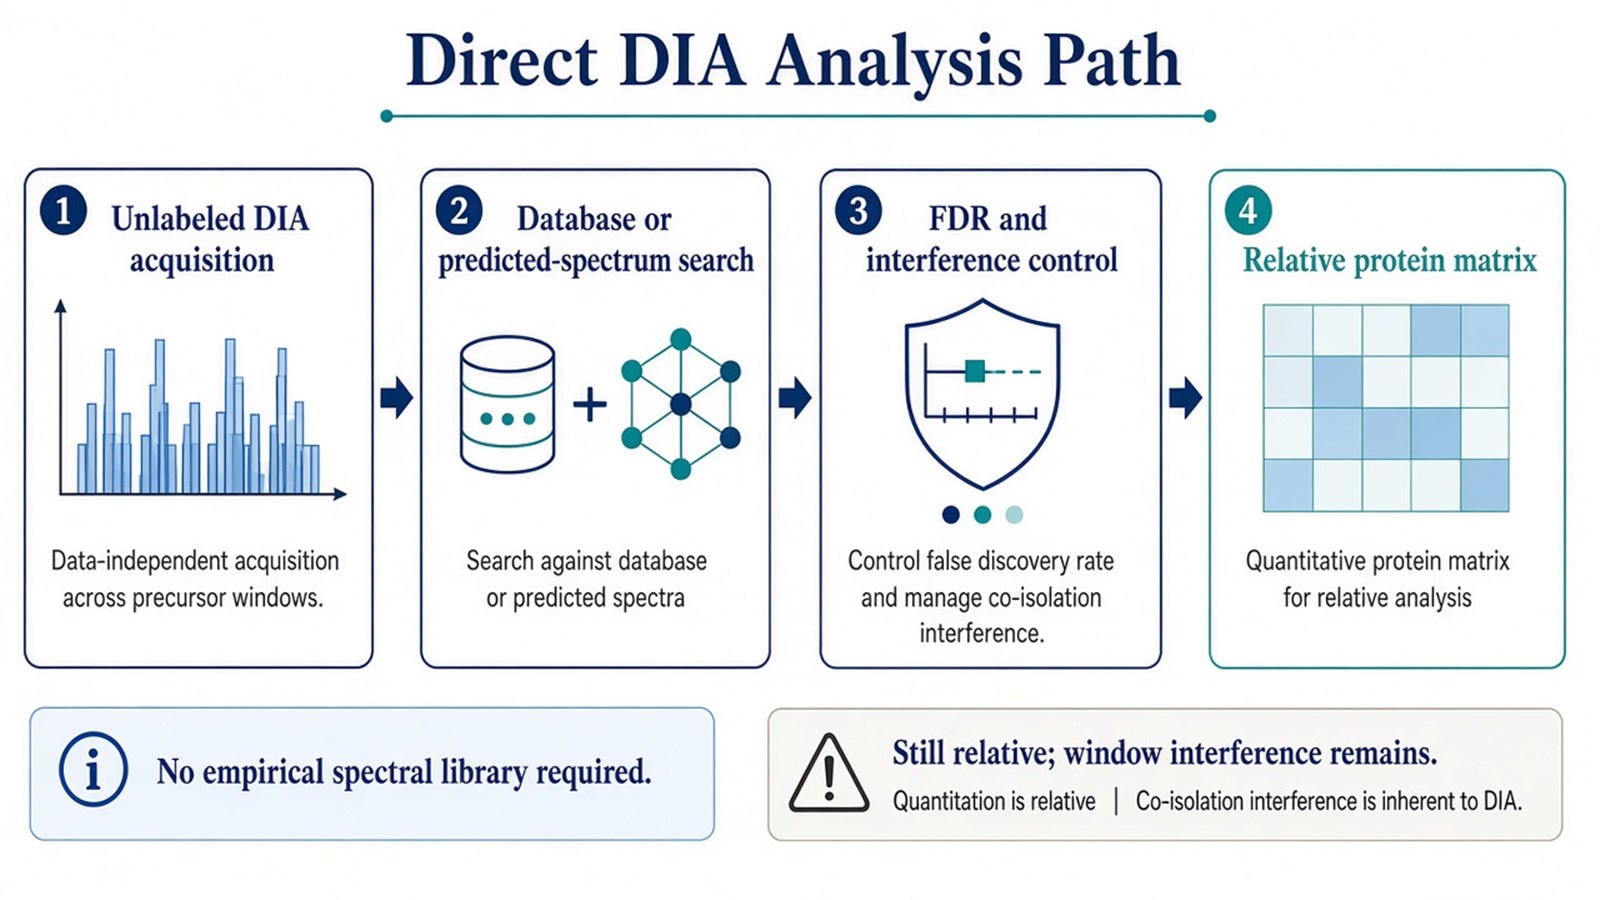
Figure 2. Direct DIA moves from DIA acquisition to library-free search and FDR-controlled quantification; the output remains a relative protein matrix.
Direct DIA Versus SWATH-Style Library Workflows
Dimension |
SWATH-style library DIA |
Direct DIA / library-free |
|---|---|---|
Acquisition |
Scheduled-window DIA |
Scheduled-window DIA |
Main analysis dependency |
Empirical spectral library |
Database, predicted spectra, or DIA-derived library |
Early project cost |
Extra DDA or library-building effort |
Lower library-building burden |
Coverage risk |
Limited by library provenance |
Limited by search space, prediction quality, and FDR |
Best fit tendency |
Stable projects with a matched, deep library |
Cohorts where matched libraries are costly or unstable |
Shared limits |
Window interference; relative claim |
Window interference; relative claim |
For the classical library-oriented definition of SWATH inside DIA, researchers can refer to What Is SWATH Mass Spectrometry?. For analysis failure modes that apply to both routes, see Common Pitfalls in DIA Proteomics Data Analysis and How to Avoid Them.
Judgment Criteria: When Direct DIA Fits
Study need |
Direct DIA often fits |
Reassess before committing |
|---|---|---|
Library logistics |
No reliable matched DDA library can be built in time |
A deep, sample-matched library already exists |
Sample type |
Clinical or irregular matrices where library transfer is weak |
Highly standardized matrix with transferable libraries |
Completeness goal |
Need DIA completeness without a second acquisition campaign |
DDA depth already sufficient for a small pilot |
Analysis control |
FDR, software version, and QC can be locked |
No plan for interference filtering or version lock-in |
Quantitative claim |
Relative discovery across independent injections |
Absolute amount without matched standards |
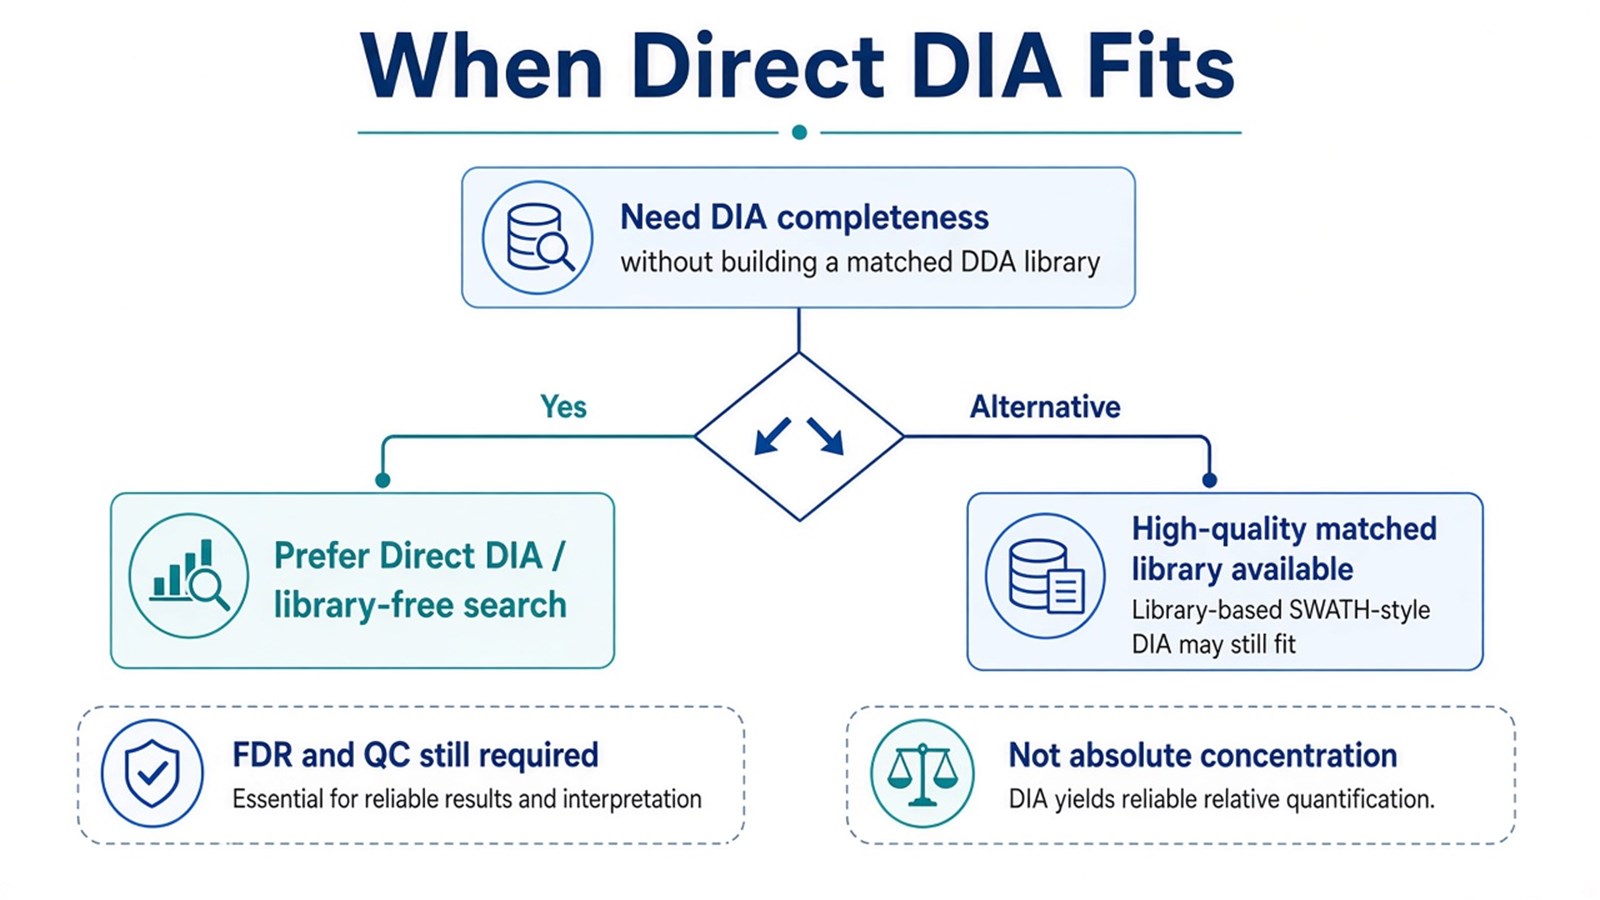
Figure 3. Prefer Direct DIA when library construction is the bottleneck; a high-quality matched library can still justify a SWATH-style extraction route.
Limits and Application Boundaries
Direct DIA still inherits DIA acquisition limits: window interference, missing low-signal peak groups, and batch structure across long sequences. Predicted spectra can misrepresent unusual modifications or unexpected cleavage products. Over-wide search spaces raise FDR burden. Cross-study comparison still needs declared software versions and processing parameters.
Application contexts are the same relative-discovery settings where unlabeled DIA is useful: treatment screens, tissue-state comparisons, biomarker discovery cohorts, and multi-batch studies that cannot support a fresh matched library for every block. Pathway enrichment on a Direct DIA candidate list reflects overrepresentation relative to a quantified background. It does not prove pathway activity. Diagnostic or release decisions sit outside ordinary discovery reporting.
Once the need for DIA completeness, the library-versus-library-free choice, and the relative claim are defined, the project can be evaluated as a Direct DIA study. Researchers can review the MtoZ Biolabs Deep DIA Proteomics Service for sample evaluation, feasibility assessment, and workflow planning.
Frequently Asked Questions
1. Is Direct DIA a different mass spectrometer method from SWATH?
Not necessarily. Both usually sit on DIA acquisition. Direct DIA changes whether an empirical spectral library is required for extraction. SWATH-style work traditionally uses a library.
2. Does Direct DIA always outperform library-based DIA?
No. A deep, sample-matched library can still yield strong extraction. Direct DIA is often preferred when library building is costly, slow, or poorly transferable.
3. Can Direct DIA report absolute protein concentration?
No. Ordinary library-free DIA intensities support relative comparison. Absolute claims need matched standards and a calibration model.
4. Is FDR control optional because there is no library?
No. Library-free search still requires decoy strategies and stated peptide and protein FDR thresholds.
5. When should a project keep a classical spectral library?
When a high-quality library already matches the matrix and acquisition conditions, or when the study depends on extracting a predefined transition set that the library already supports well.
Reference
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
