DIA Data Analysis Service
MtoZ Biolabs provides Proteomics Data Analysis Service using Spectronaut and DIA-NN for protein and peptide identification, quantification, QC, differential analysis, and bioinformatics interpretation.
Professional analysis of DIA raw MS data using Spectronaut and DIA-NN for protein and peptide identification, relative quantification, quality control, differential analysis, and bioinformatics interpretation.
- Protein & Peptide Identification
- Reliable Relative Quantification
- QC, Differential Analysis & Bioinformatics
MtoZ Biolabs provides professional DIA Data Analysis Service for existing DIA raw mass spectrometry data, supporting protein and peptide identification, relative quantification, quality control, differential statistical analysis, and bioinformatics interpretation.
Depending on data type, instrument platform, spectral library availability, and research objectives, workflows can be developed using mainstream tools such as Spectronaut and DIA-NN, with flexible selection between spectral library-driven and library-free / direct DIA strategies. For projects that have not yet completed mass spectrometry acquisition, a complete DIA quantitative proteomics service can also be provided.
What Is DIA Data Analysis?
During DIA acquisition, each isolation window often contains multiple precursor ions, resulting in highly complex MS/MS signals. The central task of DIA data analysis is to extract reliable peptide evidence from these multiplexed signals and obtain stable quantitative signals that can be compared across samples. Typical analysis steps include raw data quality control, spectrum- or peptide-level evidence matching, FDR control, peak group extraction, protein inference, normalization, differential statistical analysis, and downstream functional interpretation.
Choose the Right DIA Data Analysis Workflow
DIA data can be interpreted from different evidence levels. Spectrum-Centric and Peptide-Centric approaches are not simply two alternative software choices, but represent analytical strategies with different emphases. The most suitable approach should be selected according to data structure and research objectives.
|
Analysis Strategy |
Best-Suited Projects |
Core Focus |
Project Value |
|
Spectrum-Centric DIA Analysis |
Projects with a high-quality spectral library or those requiring stronger spectrum-level matching and identification evidence |
Uses MS/MS spectral features for matching, scoring, deconvolution, and FDR-controlled identification |
Supports systematic identification in complex proteomes and makes effective use of high-resolution fragment ion information |
|
Peptide-Centric DIA Analysis |
Projects emphasizing cross-sample consistency, targeted peptide tracking, PTM analysis, or candidate biomarker evaluation |
Extracts and scores target peptide evidence using precursor ions, fragment ions, retention time, and peak shape |
Supports stable peptide-level quantification and improves the traceability of specific peptides across multiple samples |
|
Library-Free / Direct DIA |
Routine DIA projects without an existing spectral library or projects requiring direct analysis of DIA raw data |
Uses protein sequence databases and algorithm-predicted or learned information for peptide identification and quantification |
Reduces the need for additional spectral library construction and enables efficient DIA data analysis |
Analysis Workflow
1. Data and Project Review
Raw file format, acquisition instrument, DIA window settings, sample grouping, biological replicates, species database, and key comparisons are reviewed to determine the appropriate analysis strategy.
2. Raw Data Quality Control
Chromatographic peaks, signal intensity, mass accuracy, overall sample distribution, and data completeness are evaluated to identify abnormalities that may affect identification or quantification.
3. Peptide Identification and Evidence Extraction
Depending on the selected workflow, spectral library matching or direct DIA searching is performed. Retention time, precursor and fragment ions, peak shape, and scoring information are integrated for peptide evidence filtering and FDR control.
4. Protein Inference and Relative Quantification
High-confidence peptides are summarized at the protein level. Quantitative signal extraction, normalization, and replicate consistency assessment are performed to generate comparable protein and peptide quantitative matrices.
5. Differential Statistical Analysis
According to the experimental design, correlation analysis, PCA, clustering, and differential protein screening are performed, together with visualization using volcano plots, heatmaps, and other graphical outputs.
6. Bioinformatics Interpretation
GO, KEGG, PPI, and other customized pathway analyses can be performed according to research objectives. DIA proteomics results can also be integrated with transcriptomics, metabolomics, and other omics datasets.
Service Advantages
1. Multiple DIA Data Analysis Strategies
Spectrum-Centric, Peptide-Centric, Library-Based, and Library-Free / Direct DIA approaches can be selected or combined according to project conditions, avoiding the use of a single fixed workflow for all datasets.
2. Mainstream DIA Software Support
Spectronaut, DIA-NN, and other mainstream tools can be used for protein identification, relative quantification, and quality control according to the raw data and project objectives. Statistical analysis and customized scripts can also be applied for downstream result processing.
3. Quantitative Quality Control for Large Sample Cohorts
Data completeness, sample correlation, quantitative distribution, replicate consistency, and batch effects are systematically evaluated to provide a stable data foundation for large-cohort and multi-group comparisons.
4. Historical DIA Data Reanalysis
Historical DIA raw data can be reprocessed using updated databases, software versions, parameter settings, or new research hypotheses, increasing the value of existing datasets.
5. Customized Bioinformatics Analysis
In addition to standard differential analysis, GO, KEGG, and PPI analysis, customized workflows can support candidate protein prioritization, pathway integration, and multi-omics joint analysis.
Applications
1. Large-Cohort and Clinical Proteomics
Standardized quantification, batch assessment, and group comparison can be performed for large sample cohorts, supporting disease classification, clinical subgroup analysis, and longitudinal studies.
2. Disease Mechanism and Biomarker Research
Protein expression changes can be compared between disease and control groups, different disease stages, or distinct phenotypes to identify candidate biomarkers and associated biological pathways.
3. Drug Mechanism and Target Research
Protein abundance changes before and after drug treatment can be analyzed to identify drug-responsive proteins, potential targets, and regulatory networks.
4. PTM and Functional Proteomics
For suitable DIA datasets from modification-enriched samples, modified peptide identification, relative quantification, and downstream functional analysis can be performed.
5. Multi-Omics Integration
DIA proteomics quantitative matrices can be integrated with transcriptomics, metabolomics, or clinical phenotype data to investigate biological mechanisms at multiple molecular levels.
Deliverables
1. Peptide and Protein Identification Results
2. Protein and Peptide Relative Quantification Matrices
3. Data Quality Control and Sample Consistency Results
4. Differential Protein Statistics with PCA, Clustering, Volcano Plots, and Other Visualizations
5. GO, KEGG, PPI, and Other Bioinformatics Analysis Results
6. Excel Analysis Files and Project Report
FAQ
Q1. Can DIA Raw Data Be Analyzed Directly?
Yes. Once complete DIA raw files, species or database information, sample grouping, and key comparisons are provided, the data format and quality can first be evaluated before selecting the appropriate analysis workflow.
Q2. How Should Spectronaut and DIA-NN Be Selected?
Both are widely used for DIA data analysis. The choice depends on raw data type, spectral library conditions, project scale, previous analysis framework, and output requirements.
Q3. Can PTM or Multi-Omics Integration Analysis Be Performed?
Yes. Suitable PTM DIA datasets can be analyzed at the modified peptide level. Proteomics results can also be integrated with transcriptomics, metabolomics, and other omics datasets for joint interpretation.
Start Your Project with MtoZ Biolabs
If you already have DIA raw data, provide the acquisition platform, sample grouping, species, and research objectives. MtoZ Biolabs will recommend a suitable analysis strategy and define the expected quantitative and bioinformatics outputs.
For projects without completed MS acquisition, a full DIA quantitative proteomics service is also available.
MtoZ Biolabs, an integrated chromatography and mass spectrometry (MS) services provider.
Related Services
DIA Quantitative Proteomics Analysis Service
DIA MS (Data-Independent Acquisition Mass Spectrometry)-Based Quantitative Service
Demo for DIA Proteomics Analysis
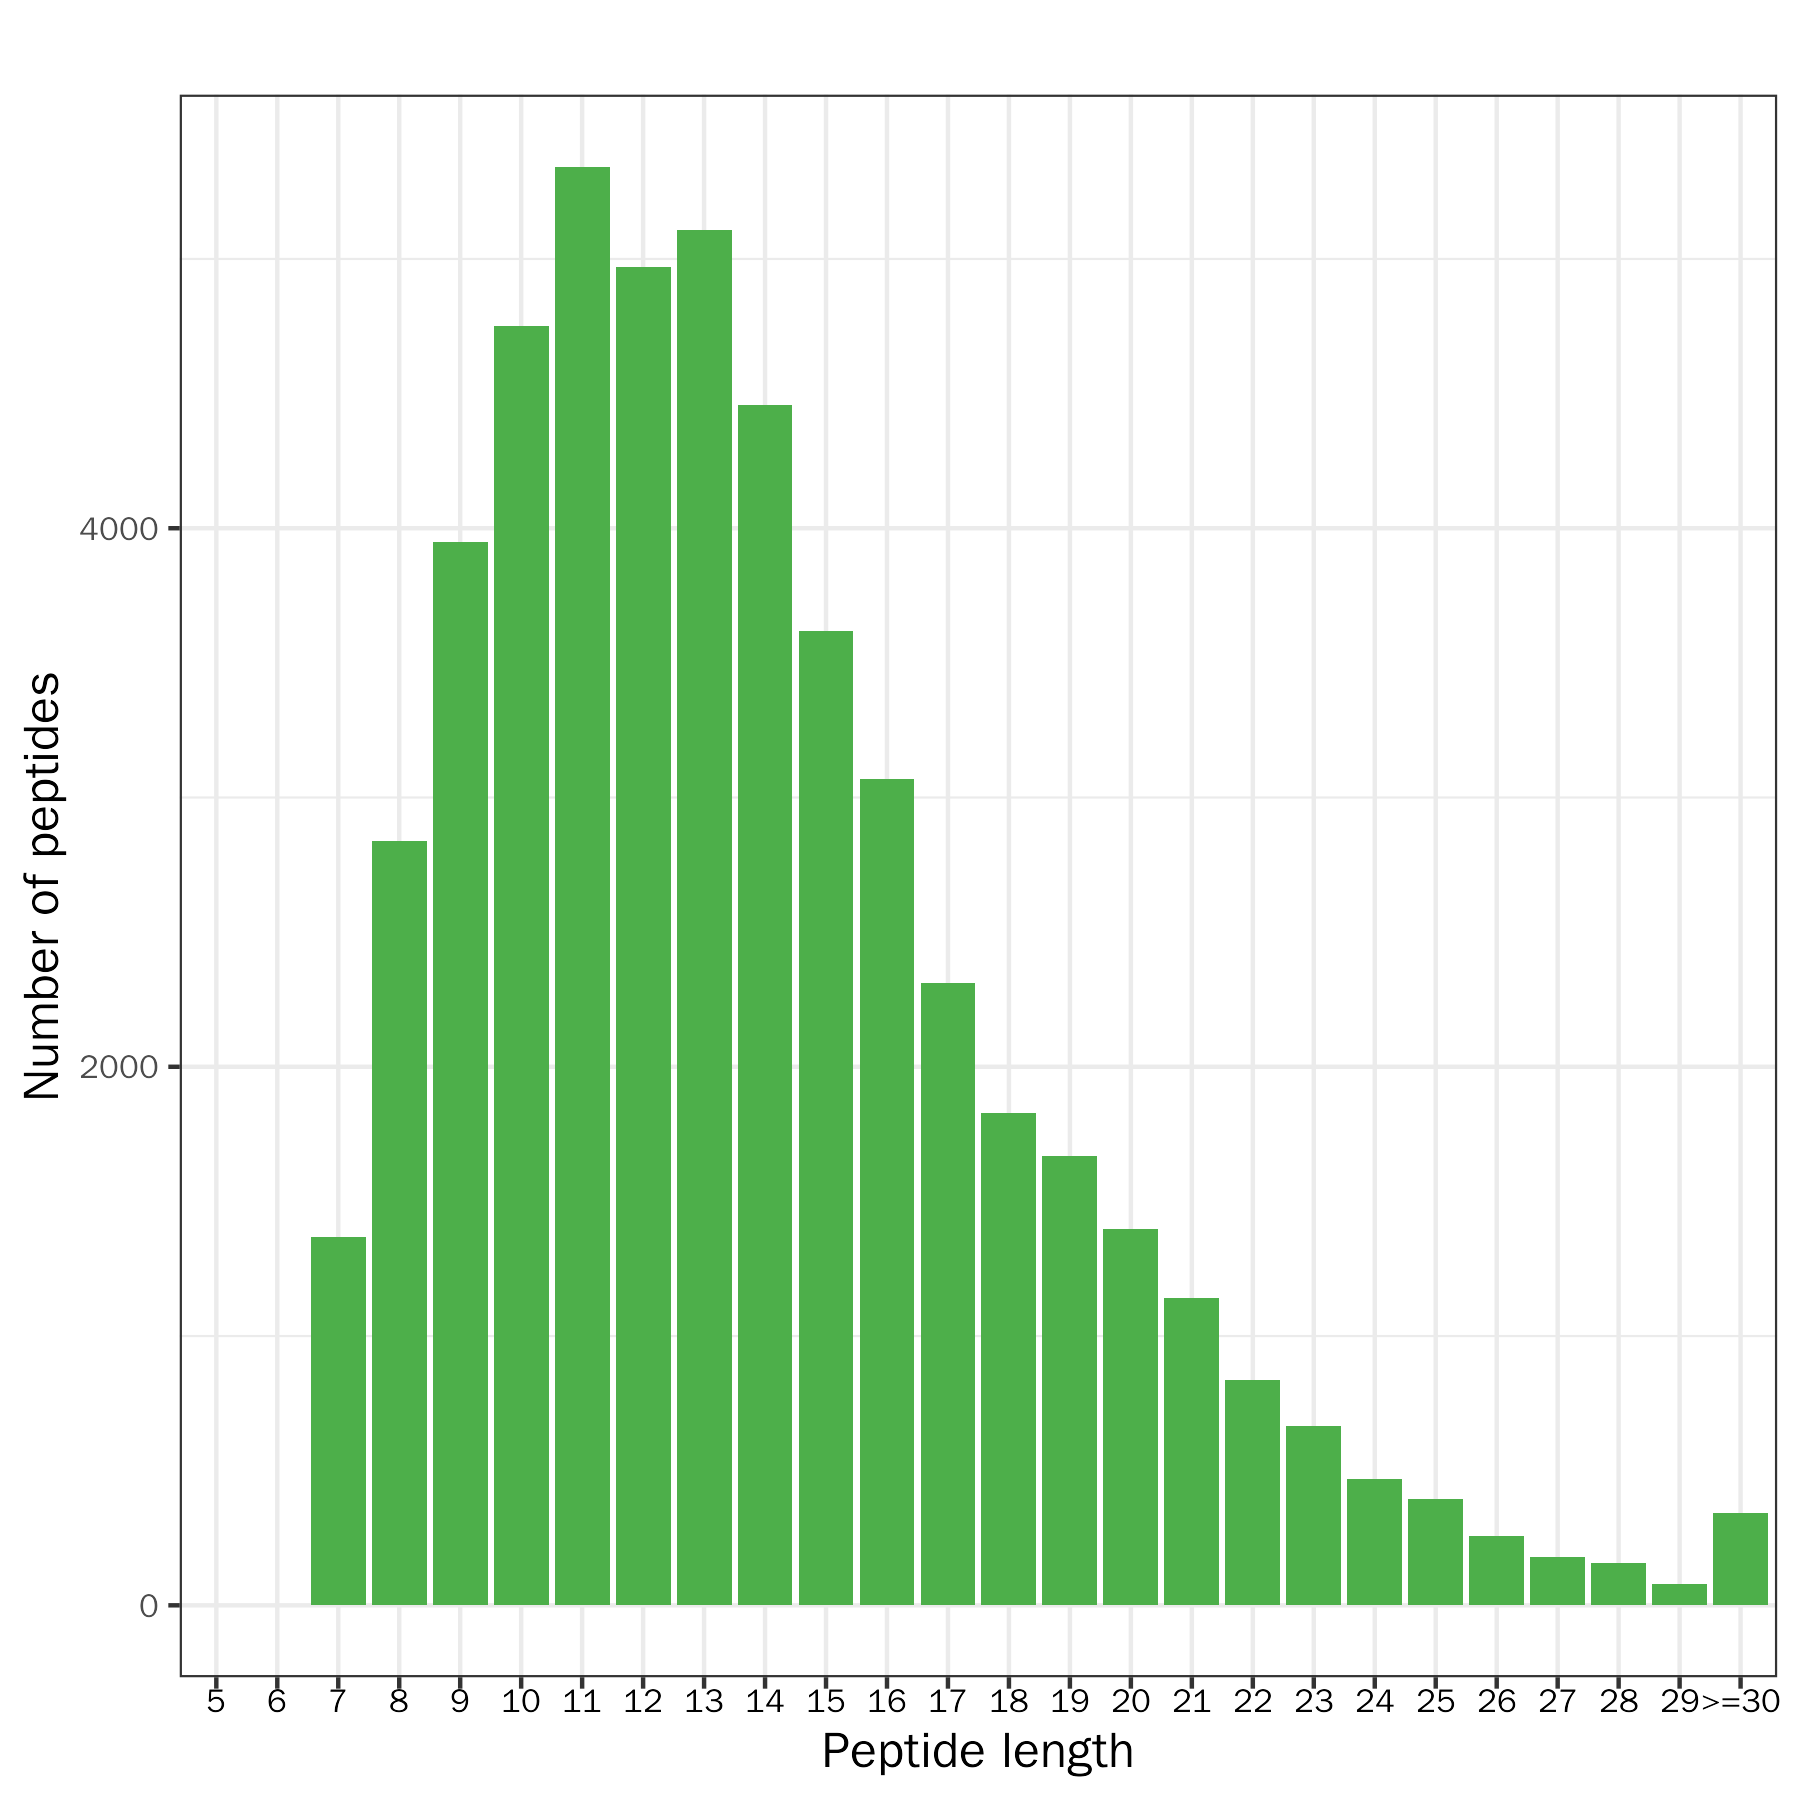
Peptide Length Distribution
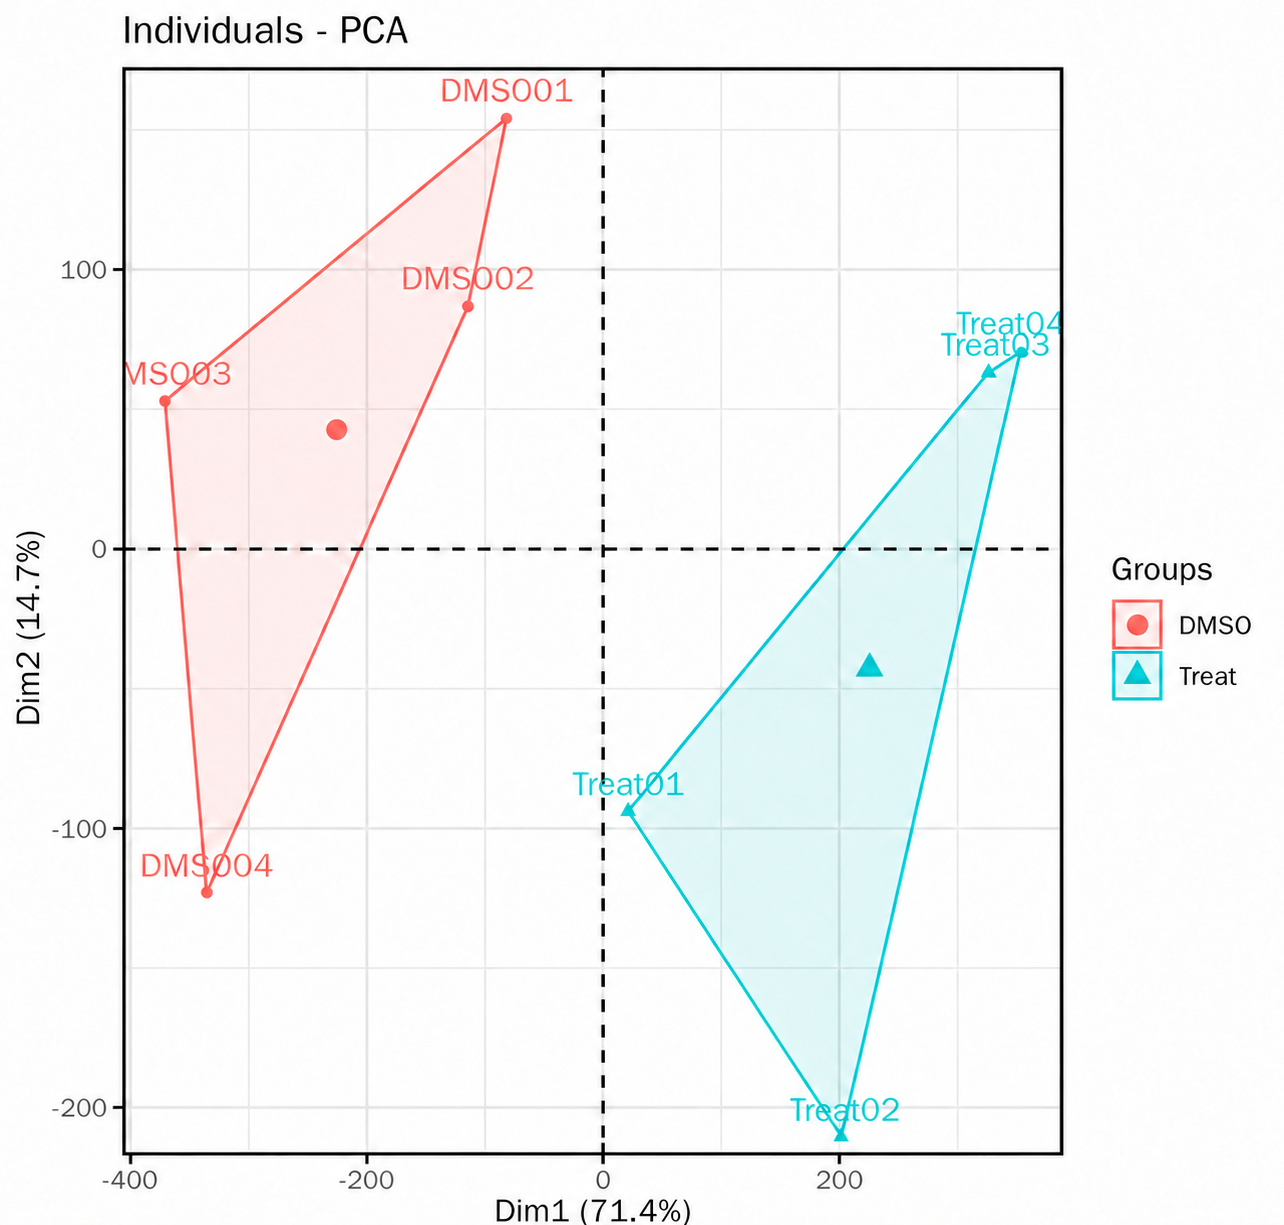
PCA Plot of Sample Grouping
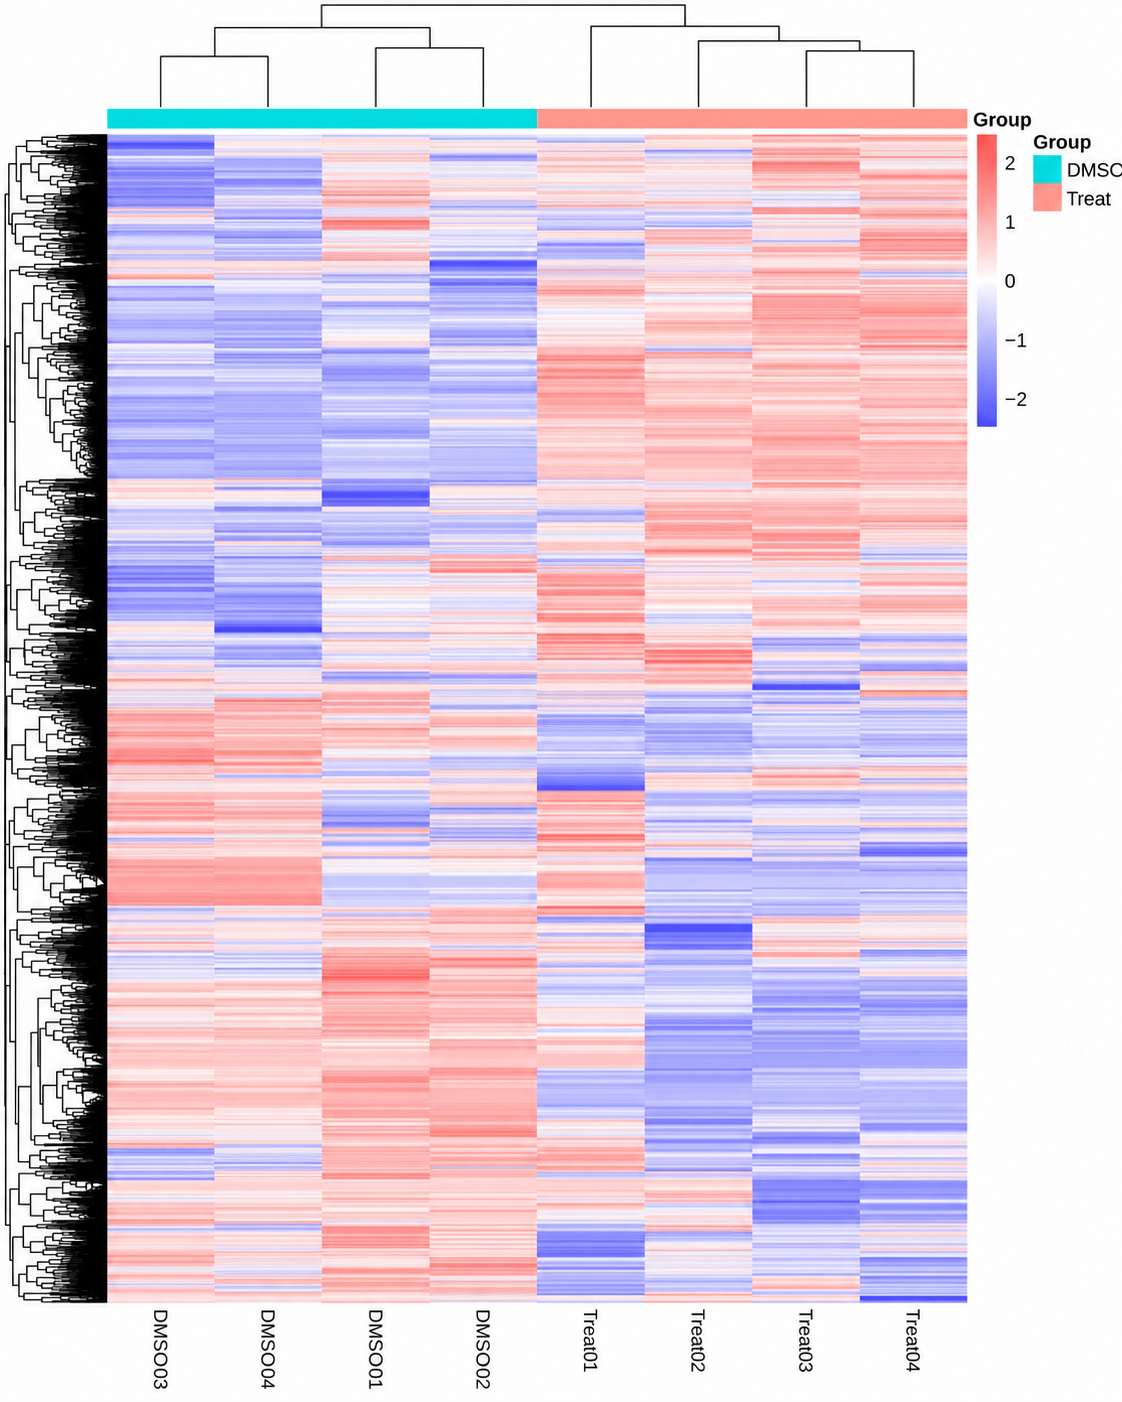
Hierarchical Clustering of Protein Abundance