



A DIA or SWATH project usually arrives at analysis as independently injected liquid chromatography-tandem mass spectrometry (LC-MS/MS) files, a declared isolation-window scheme, and a group contrast that still needs a protein-by-sample matrix. Data-independent acquisition (DIA) fragments precursors inside scheduled m/z windows. Sequential window acquisition of all theoretical fragment ion spectra (SWATH-MS) is one sequential-window implementation that typically recovers quantities by targeted extraction against a spectral library (Gillet et al. 2012). Analysis maps those mixed fragment traces to peptides, controls error rates, and summarizes a relative matrix. Naming a software package does not replace those decisions.
Labeling chemistry and acquisition stay separate. In MtoZ Biolabs offerings, unlabeled digests are commonly acquired as DIA. A labeled digest can be acquired with DIA in other designs. TMT reporter workflows are typically acquired as data-dependent acquisition (DDA).
What DIA Data Analysis Can Return
DIA analysis can support a same-protein relative comparison across runs that share one chromatographic plan and one extraction route. After peptide and protein false discovery rate (FDR) control, fragment chromatograms are summarized, samples are normalized, and a predefined contrast can be tested. Completeness is often higher than stochastic DDA sampling because a peptide can be extracted later even if it was never chosen as a top precursor.
DIA analysis cannot invent peptides that never produced extractable fragments. It cannot rank different proteins as copy numbers from intensity. It cannot report ng or fmol without a matched stable isotope-labeled internal standard (SIS). Pathway enrichment is optional after the matrix passes quality checks. It is not a substitute for extraction QC.
If the files were acquired as DDA label-free MS1, the extractor should stay on MS1 peak areas. Researchers can refer to How to Analyze Quantitative Proteomics Data for generic protein-matrix statistics after a DIA table already exists. Acquisition-class definitions belong with What Is DIA and SWATH: Understanding Data-Independent Acquisition in Proteomics.
How Library-Based and Library-Free Extraction Build a Matrix
A practical order is stable even when the search environment changes. Raw files are converted. Peptide evidence is scored either against a spectral library or against a library-free search. Peak groups are aligned across runs. Interfering fragments are filtered. Peptide quantities are summarized to proteins. Only then should group contrasts be tested.
Library-based SWATH-style work extracts fragment chromatograms for transitions stored in a library that holds sequence, fragments, and retention-time information (Gillet et al. 2012; Röst et al. 2014). Library provenance bounds the peptide set. A library built from unmatched tissue, an old gradient, or a different instrument can miss real peptides or assign the wrong peak group.
Library-free, sometimes called direct DIA, searches DIA spectra against a protein database, predicted fragments, or a library built from the DIA files themselves under FDR control (Demichev et al. 2020). That route removes a separate DDA library campaign. It still requires retention-time handling, interference review, and a relative-only claim. Researchers who need that route in more depth can refer to Direct DIA: High-Efficiency Proteomics Without a Spectral Library.
DIA intensities become comparable only after the extraction route, FDR rule, and interference filters are locked to the window scheme.
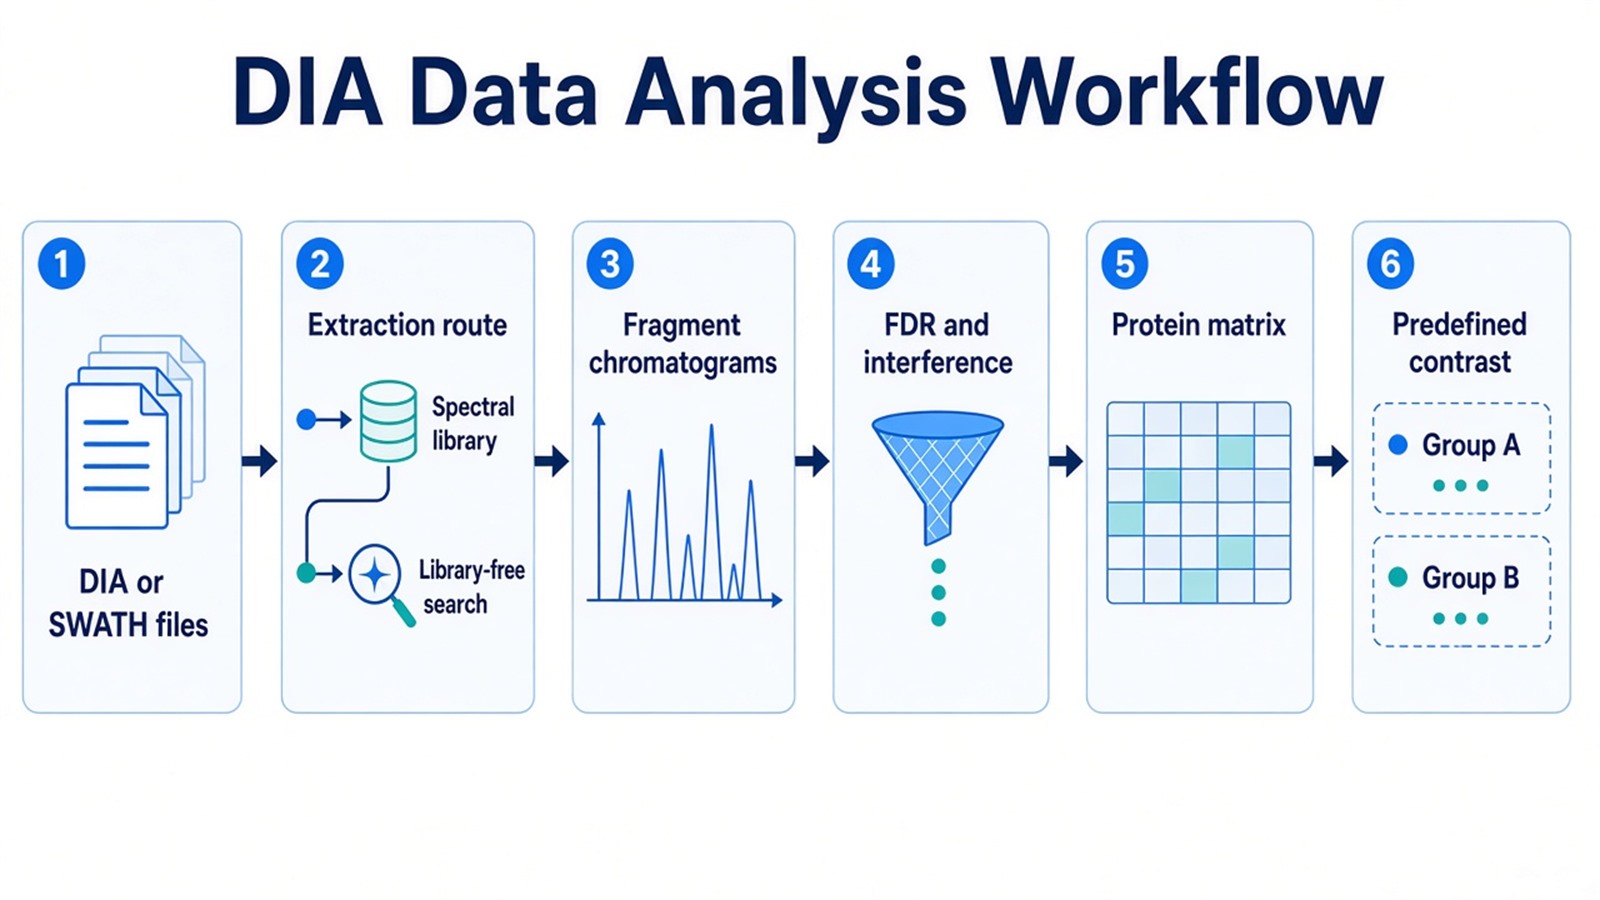
Figure 1. DIA data analysis turns scheduled-window files into a protein matrix before any differential call is reviewed.
Mixing DDA MS1 tables with DIA fragment tables in one statistical model, without a bridging design, creates contrasts the data cannot defend. Mixing two DIA extractors on the same cohort without documenting the change has the same problem.
Parameters That Control Windows, FDR, and Interference
Window width and cycle time are acquisition settings, yet they constrain analysis. Wider windows raise fragment overlap. Narrower windows reduce chimeric spectra and may starve chromatography if the cycle is too slow. The analysis record should store the window scheme with the matrix, because extraction tolerances are meaningless without it.
FDR must be declared at peptide and protein levels using a decoy strategy suited to the extractor. Large-scale targeted DIA needs explicit control of peptide and protein error rates, not only a software default (Rosenberger et al. 2017). A long identification list can still contain interfered peak groups. Quantitative filters, coefficient of variation (CV) summaries, and missingness maps belong beside protein counts.
Retention-time alignment and mass calibration decide whether the same peptide occupies the same row. Over-wide tolerances transfer incorrect peak groups across runs. Interference filters drop fragments that do not co-elute or that show unexpected relative intensities. Those filters can shrink the matrix. They can also prevent a fold change that was never measured for the intended peptide.
Normalization removes a global offset when a stated fraction of the proteome is expected to stay stable. It does not unmix a batch that is identical to the experimental factor. Missing values still occur at low abundance. Imputation can enable a test and can invent a difference. Proteins missing in every group are weak discovery claims. Missingness that copies one treatment arm is a detection or design problem.
Key parameters to record include the extractor and version, library identity or library-free settings, peptide and protein FDR, interference rules, normalization assumption, missing-value rule, and the exact group contrast.
Limits of a DIA Table After Extraction
Windowed fragmentation records mixed ions. Analysis can score a peak group; it cannot always prove that no co-fragmented peptide contributed. Library-free search expands the candidate space and can raise computational cost. It does not remove chimeric windows.
A spectral library is not a universal dictionary. Cross-project reuse is valid only when chromatography, digestion, and species match closely enough for retention time and fragments to transfer. Public libraries need the same provenance check as in-house libraries.
DIA analysis remains relative. Cross-protein ranking from intensity is not an amount. Software upgrades change scoring. Reanalysis of an old cohort with a new version should be reported as a new matrix, not as a silent update of a published table.
If names are already closed and fragment confirmation is the remaining task, a scheduled targeted assay is the closer next step. If chromatograms or run order still dominate variance, the failure is often sample processing or acquisition, not a missing pathway test.
When DIA Analysis Fits, and When Files Need Another Route
The useful test is whether the files are scheduled-window DIA, whether one extraction route can be declared, and whether the claim is a relative contrast.
Observed situation |
Check first |
Analysis step that often fits |
|---|---|---|
DIA or SWATH files, open protein list |
Window scheme and chromatography match |
Library-based or library-free extraction, then QC |
Matched, deep library already exists |
Library origin versus this cohort |
SWATH-style targeted extraction |
No usable empirical library |
Search space and FDR settings |
Library-free DIA extraction |
Library from a different tissue or gradient |
Provenance |
Rebuild or switch to library-free; do not force the old library |
DDA MS1 files only |
Acquisition type |
DDA label-free analysis, not a DIA extractor |
Named peptides, confirmation required |
List length |
Targeted PRM or MRM in a new digest |
Amount or concentration unit requested |
SIS availability |
Relative DIA is not sufficient |
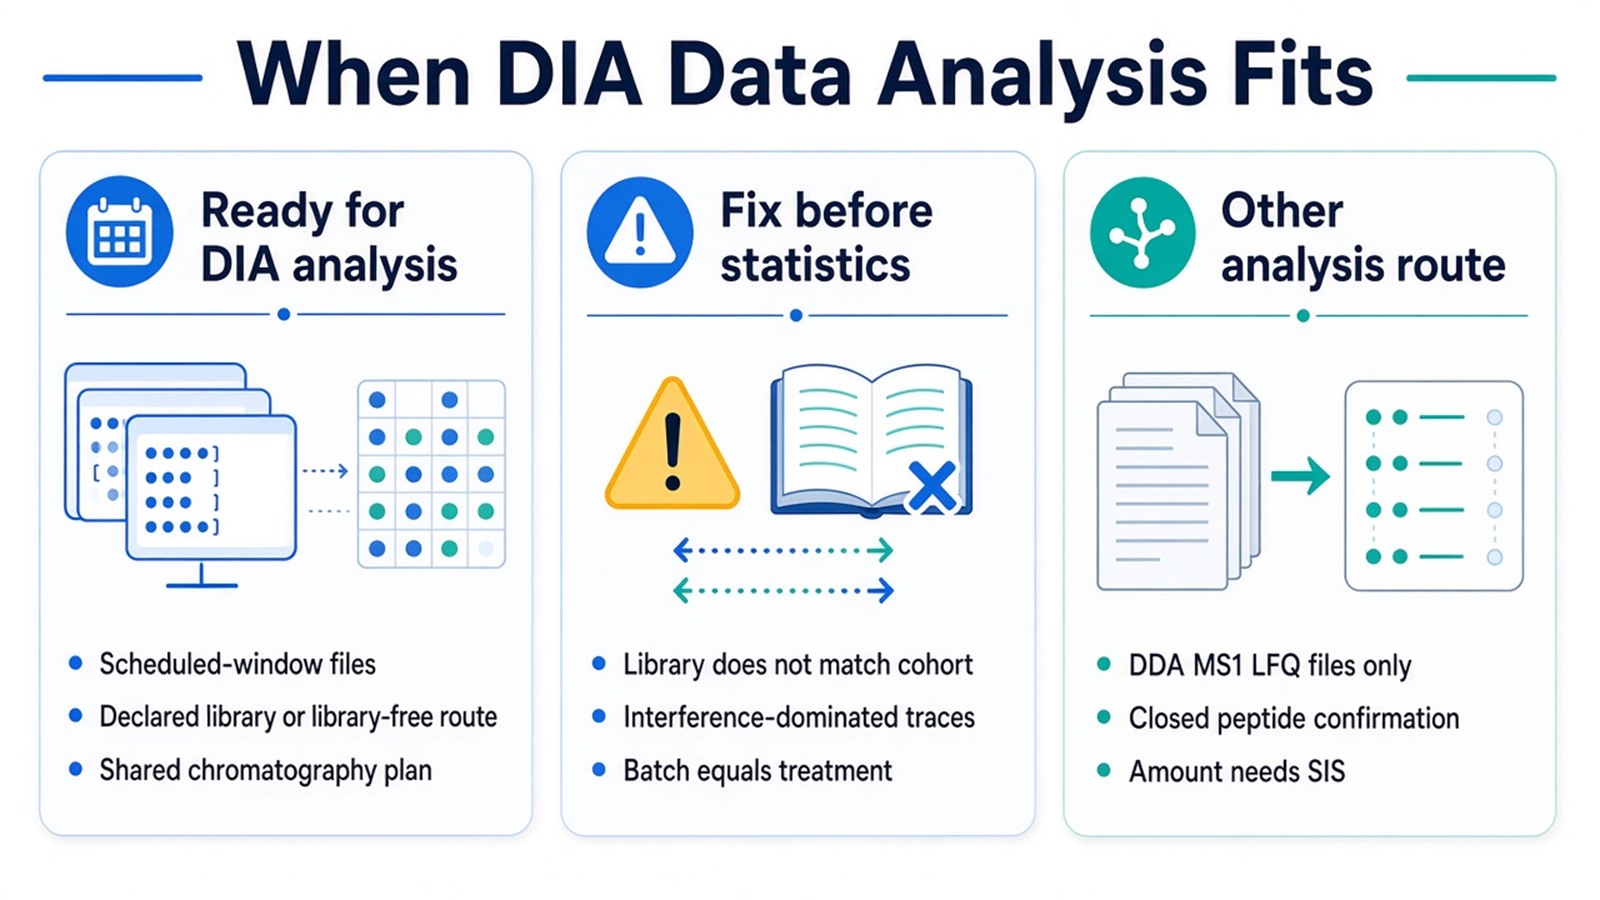
Figure 2. DIA data analysis fits scheduled-window files with a declared extraction route; DDA-only files, closed confirmation lists, and amount claims need a different plan.
Library-based extraction more often fits a stable project that already has a sample-matched library. Library-free extraction more often fits a new cohort where building that library would delay analysis. Neither route is required in every study. Researchers who already have DIA or SWATH raw files, defined groups, and a requested contrast can also review the MtoZ Biolabs DIA based Protein Quantitative Service for project-specific extraction planning.
Frequently Asked Questions
1. Can DDA and DIA files be analyzed as one protein matrix?
They use different quantitative traces. Combine them only when the study includes an explicit bridge and the analysis plan documents how features were matched.
2. Does a larger protein identification list mean the quantification is better?
No. Depth and quantitative usability are related outputs, not the same claim. Interfered peak groups and high missingness can sit inside a long list. Report proteins that pass quantitative filters alongside totals.
3. Must a DDA spectral library be built before every DIA analysis?
No. A matched library can stabilize SWATH-style extraction. Library-free search is a valid alternative when a matched library is costly or outdated. The methods record should name which route was used.
4. Can DIA intensities be converted to ng per mL after extraction?
No reliable conversion exists without a matched SIS and a declared calibration for that peptide. Window extraction does not create concentration units.
5. Is SWATH data analysis a different science from other DIA pipelines?
SWATH-MS is a sequential-window DIA implementation, historically paired with library-based targeted extraction (Gillet et al. 2012). Other DIA pipelines may use different window schemes or library-free scoring. The shared analysis job is still FDR-controlled fragment extraction into a relative matrix.
MtoZ Biolabs can provide DIA and SWATH data analysis for scheduled-window LC-MS/MS projects, including library-based or library-free extraction, documented FDR and interference filters, and predefined group contrasts when project files and study design are available.
If further evaluation of library provenance, extractor settings, or whether DDA label-free analysis is the better match is needed, project details can be submitted for a feasibility review.
Reference
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- G. Rosenberger, I. Bludau, U. Schmitt, M. Heusel, C.L. Hunter, Y. Liu, M.J. MacCoss, A.I. Nesvizhskii, P.G.A. Pedrioli, L. Reiter, H.L. Rost, S. Tate, Y.S. Ting, B.C. Collins, R. Aebersold (2017). Statistical control of peptide and protein error rates in large-scale targeted data-independent acquisition analyses. Nat. Methods, 14, 687-694. https://doi.org/10.1038/nmeth.4398
- H.L. Rost, G. Rosenberger, P. Navarro, L. Gillet, S.M. Miladinovic, O.T. Schubert, W. Wolski, B.C. Collins, G. Malmstrom, L. Malmstrom, R. Aebersold (2014). OpenSWATH enables automated, targeted analysis of data-independent acquisition MS data. Nat. Biotechnol., 32, 219-223. https://doi.org/10.1038/nbt.2841
