
- Biological Products Analysis Service Primary Structure Analysis Service Therapeutics Characterization Service | Advanced Structural Charge Heterogeneity Analysis Service Biopharmaceutical Impurities Analysis Service
- Preclinical Drug Development Active Ingredients Identification and Screening Service Drug Target Analysis Service Biopharmaceuticals Characterization Service Targeted Drug Delivery Service | Precise and Efficacious Customized Drug Development and Optimize Service
- Thematic Analysis Service High-Throughout Gene Knockout Services Biopharmaceutical Stability Analysis Service PROTAC Drug Off-Target Protein Assessment Service Biosimilar Assessment Service Generic Peptide Pharmaceuticals Assessment Service Research on Media Development and Optimization Vaccine Quality Research and Testing Solutions Antibody Drug Analysis Service mRNA Drug Analysis Service Medical Device Analysis Service
- Proteomics Analysis Service Sample Preparation Service Protein Analysis Service Quantitative Proteomics Service Post-Translational Modifications Proteomics Service Proteomics Service of Different Sample Types Targeted Proteomics Service Peptidomics Analysis Service Proteomics Bioinformatic Analysis Service High-Throughout Proteomics Analysis Service for Gene Knockout Chemical Proteomics Analysis Service
- Metabolomics Analysis Service Untargeted Metabolomics Service Targeted Metabolomics Analysis Service High-Throughput Metabolomics Service After Gene Knockout Metabolomics Bioinformatic Analysis Service More Services
- Lipidomics Analysis Service Untargeted Lipidomics Analysis Service Targeted Lipidomics Analysis Service Exosome Lipidomics Service Lipidomics MALDI Imaging Service Oxylipidomics Service
- Multi-Omics Analysis Service Integrative Lipidomics-Proteomics Analysis Service Integrative Transcriptomics-Metabolomics Analysis Service Integrative Transcriptomics-Proteomics Analysis Service Integrative Transcriptomics-Lipidomics Analysis Service Integrative Metabolomics-16S rDNA Sequencing Analysis Service Integrative Proteomics-Metabolomics Analysis Service Integrative PTM-Metabolomics Analysis Transcriptome Sequencing (RNA-sequencing) Service Metatranscriptomics Sequencing Service Full-Length 16S/18S/ITS Sequencing Service Prokaryotic Transcriptomics Sequencing Service Eukaryotic Non-Ginseng Transcriptome Sequencing Service Eukaryotic Transcriptome Sequencing Service 16S/18S/ITS Amplicon Sequencing Service Exosomal Sequencing Service
- Single Cell Analysis Service Single Cell Sequencing Service Single Cell Mass Cytometry Analysis
- Bioinformatics
Unknown Metabolite Identification Analysis Service
Published: May 21, 2024
Metabolomics generally divides the credibility of metabolite identification into the following four dimensions: compounds reliably identified (Level 1), compounds obtained through assumed annotations (Level 2), identification of compound categories through assumed annotations (Level 3), and unknown compounds (Level 4). Level 1 identification requires comparing two or more orthogonal properties of the target metabolite (such as retention time, m/z, and fragmentation spectra) with the same properties of real chemical standards observed under the same analytical conditions. Presumed (Level 2 or Level 3) annotations primarily rely on one or two properties and are usually based on comparisons of data collected from different laboratories and obtained through various analytical methods, rather than a direct comparison with real chemical standards under the same analytical conditions.
Unknown metabolites refer to small molecules that can be repeatedly detected but whose chemical identities have not yet been determined. Although these compounds have not been identified and classified, they can still be distinguished and quantified in metabolomics experiments based on spectral data. In LC-MS experiments, an unknown compound is defined by a unique retention time, one or more masses, or a specific primary ion fragmentation pattern. In NMR experiments, an unknown compound is defined by a pattern of chemical shifts. Unknowns may represent previously unrecognized small molecules, such as secondary metabolites of metabolism or rare exogenous substances, or they may be composed of molecules from established pathways but cannot be assigned to existing NMR reference spectra or MS fragmentation patterns.
The identification of unknown compounds is very time-consuming and costly, usually requiring preparatory scale separation for NMR studies, or extensive chemical synthesis for structural comparison using MS/MS. Therefore, most reports focus on detecting metabolites that have available real commercial standards or are at least present in metabolite databases, i.e., metabolites classified as Level 1, 2, and 3. Due to the inherent instability of many metabolites and the lack of demand, only a few thousand commercial analytical standards are available. However, these standards and metabolites present in databases represent only a small fraction of endogenous metabolites. Thus, for metabolomics research, effective methods for sorting, studying, and ultimately identifying non-characteristic metabolites are very important. The successful identification of unknown metabolites will have a significant impact on the discovery of biomarkers and omics research.
To identify unknown compounds in metabolomics samples, it is important to differentiate among metabolites of the same discernible nominal mass, those with the same discernible nominal mass but different molecular formulas and isotopic masses, and those with the same discernible nominal mass and isotopic mass but different chemical structures. For example, leucine and isoleucine are structural isomers, but have the same discernible nominal mass and isotopic mass. Additionally, as a single metabolite can be detected in the mass spectrometer with different derivatives, it is also important to correctly assign the different derivative species to the parent metabolite. For example, in amino acid analysis, the chemical derivatization reaction of trimethylsilylation (TMS) with amino acids can produce amino acids containing 1, 2, or 3 TMS groups, all of which should belong to the same parent amino acid.
MtoZ Biolabs combines NMR, LC-MS/MS, and bioinformatics analysis methods to offer mass spectrometry-based identification of unknown metabolites in complex biological samples. MtoZ Biolabs continuously develops tools and databases, hoping to achieve automated, true, and complete identification of all metabolites. Free project evaluation!
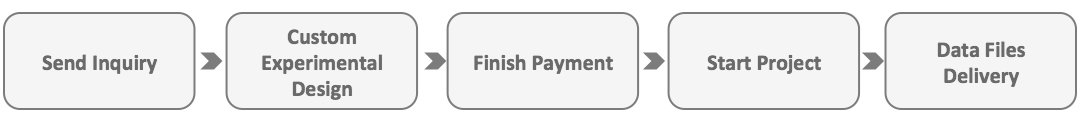
How to order?