



A proteomics service is an outsourced mass spectrometry workflow that answers a protein-level question from submitted samples. Quantitative proteomics is not a more advanced brand of the same catalog. It is the subset that compares abundance of the same protein across defined samples or groups. Identification, post-translational modification (PTM) mapping, and interaction capture can proceed without a quantitative design. A quantitative design cannot proceed without a defined contrast, a comparable analytical plan, and a claim that matches the chosen route. Mixing those jobs produces a protein list that is read as a fold-change study, or a fold-change table that is read as an identity certificate. The first decision is the scientific claim, not a technique name.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Quantitative Proteomics Service for project-specific feasibility and analysis planning.
What a Proteomics Service Can Answer Without Quantification
Proteomics work is larger than abundance comparison. A project may need a protein inventory, modification-site evidence, or interaction partners. Those tasks use digestion, liquid chromatography-tandem mass spectrometry (LC-MS/MS), and a searchable protein database. They do not require reporter ions, cross-run alignment, or a multiplex kit.
Identification asks which proteins are present above the evidence threshold of that search. PTM analysis asks where a mass shift maps on a peptide or proteoform. Interaction work asks which partners copurify or sit near a bait. Composition-level sample proteomics asks what is detectable in one matrix. None of those outputs is a calibrated concentration, and none is a group contrast until a quantitative design is added.
When the remaining need is identification, PTM mapping, or interaction capture rather than a group comparison, researchers can review Proteomics Analysis Service for the broader analytical menu.
Quantitative proteomics does not replace those tasks. A TMT or label-free matrix still depends on peptide identification. A modification site still needs fragment evidence. Treating every proteomics request as a quantitative service hides the claim that will later appear in the figure legend.
A proteomics service answers a protein-level question; quantitative proteomics answers whether the same protein changed across a defined contrast.
When the Project Is Actually a Quantitative Comparison
The project is quantitative when the scientific sentence has a comparison: treatment versus control, genotype, time point, dose, or tissue state. The operational measurement is usually peptide ion signal after digestion, most often with trypsin. Protein values are inferred from identified peptide features (Bantscheff et al. 2007). The valid statement is relative change of the same protein inside one coherent analytical plan, or an amount only when a matched standard and a calibration model are part of the design.
Group definitions, replicate structure, and whether later samples may still enroll should be fixed before the first digest is queued. Unlabeled discovery keeps each digest as its own LC-MS/MS run and reconstructs comparability after acquisition. Isobaric labeling codes peptides, mixes them, and reads reporter ions in one run. Metabolic labeling such as stable isotope labeling by amino acids in cell culture (SILAC) requires a system that incorporates heavy amino acids. Targeted monitoring follows a short peptide list. Those are different routes to a quantitative claim, not interchangeable product names.
A biomarker-discovery narrative does not by itself specify the route. Differential proteins from a discovery matrix remain candidates. They are not diagnostic markers, clinical cutoffs, or proof of a drug mechanism. Pathway maps interpret a differential list. They do not convert a poorly designed comparison into a quantitative result.
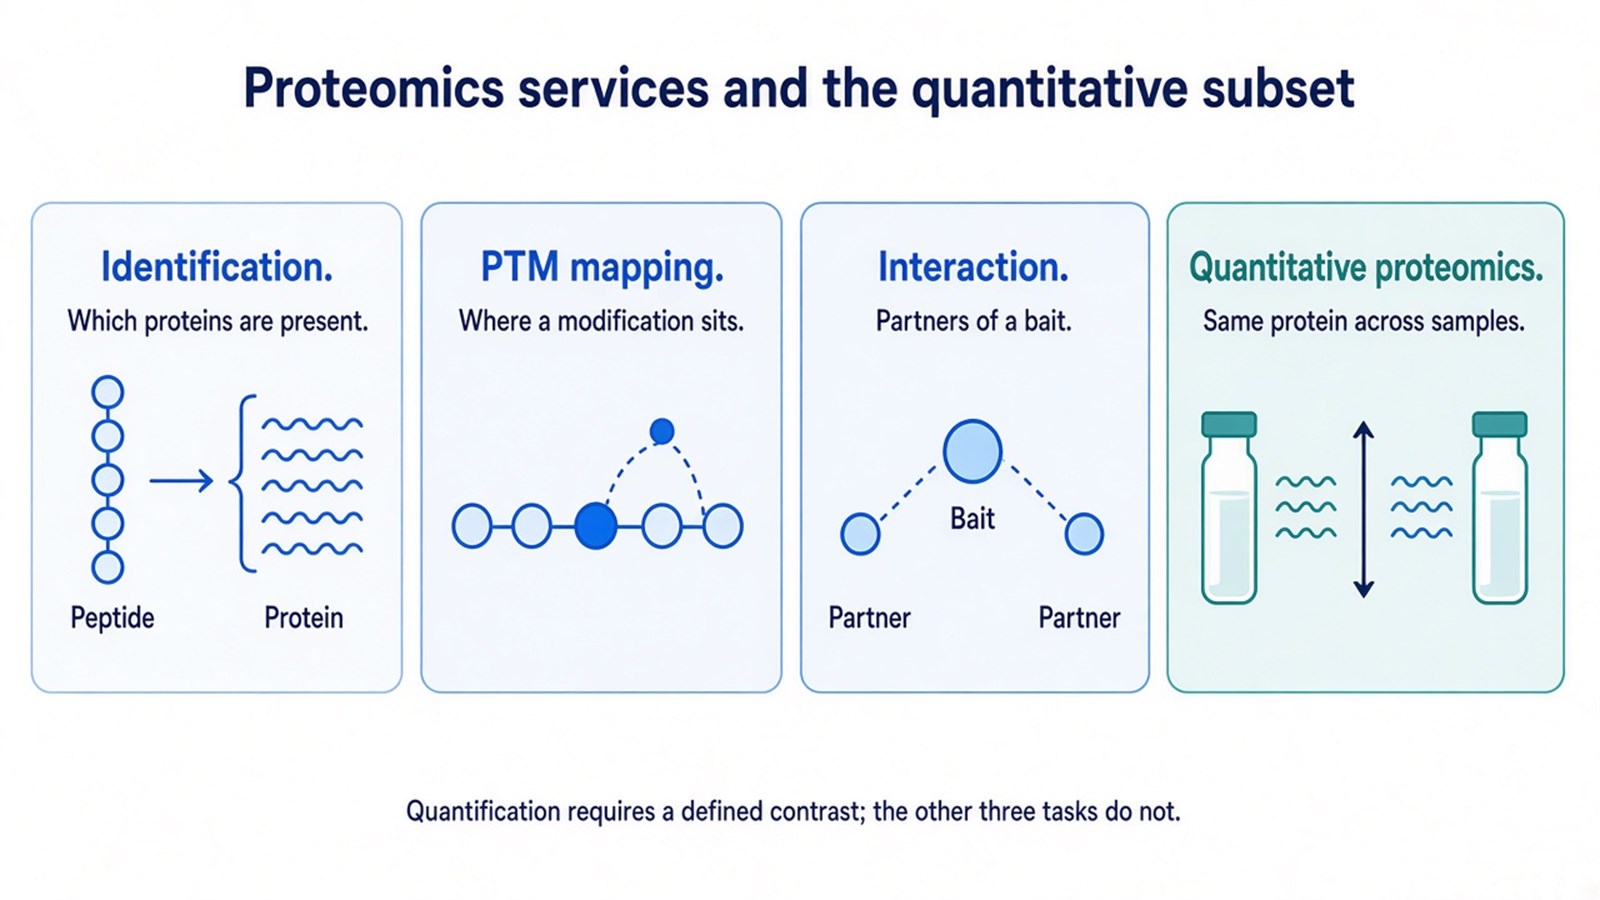
Figure 1. Identification, PTM, and interaction work can stand without a group contrast; quantitative proteomics is the subset that compares the same protein across defined samples.
How Quantitative Routes Differ Without Repeating a Method Catalog
Labeling, acquisition, and assay scope are separate decisions. Label-free quantification (LFQ) means isotopic or isobaric labels were not used. Data-dependent acquisition (DDA) and data-independent acquisition (DIA) name how the instrument schedules fragmentation. An unlabeled digest can be run as DDA or DIA. A labeled digest can also be acquired under more than one method. DIA is not a synonym for unlabeled work.
Decision layer |
Common options |
What the researcher is choosing |
Do not treat as |
|---|---|---|---|
Scientific claim |
Relative change vs amount vs identity |
The sentence the table must support |
A vendor package name |
Labeling |
Unlabeled; isobaric tags; SILAC |
Whether samples stay separate or are coded and pooled |
An acquisition mode |
Acquisition |
DDA or DIA |
How precursors are fragmented and recorded |
Proof that the experiment is unlabeled |
Assay scope |
Discovery vs MRM or PRM |
Proteome-wide relative change vs predefined targets |
Another discovery algorithm |
Peak-area LFQ supports relative discovery on independently injected samples when chromatography can stay stable enough for alignment. Spectral counting can help with rough ranking of identification-centric DDA files. Protein-level fold changes for downstream statistics should use peak-area values. Tandem mass tags (TMT) support a same-run relative comparison when every sample in the contrast can be labeled and mixed. Targeted multiple reaction monitoring (MRM) or parallel reaction monitoring (PRM) asks whether selected peptides change as expected.
Researchers can refer to Protein Quantification Measured by Mass Spectrometry for how peptide signals become protein values and how relative change differs from an amount claim.
In MtoZ quantitative offerings, unlabeled discovery is typically reported from DDA peak-area LFQ, isobaric workflows are typically acquired as TMT in DDA, and short candidate lists are typically followed by MRM or PRM. Sequential window acquisition of all theoretical fragment ions (SWATH) is a DIA implementation, not a separate labeling chemistry. Service configuration is not an academic rule that other laboratories must copy.
What a Quantitative Result Can Support
After the chosen route is processed, a protein-level value can support a relative statement: protein A is higher or lower in group 1 than in group 2 inside this study. Peptide support, missingness, plex or run-block structure, and the stated normalization belong next to that statement. Ordinary discovery intensities should not rank different proteins by copy number, infer a diagnostic cutoff, or transfer a ratio from one instrument to another study as a calibrated quantity.
Identification evidence and quantitative values should stay in one processing trail. Exporting a protein list from one tool and intensities from another, without a shared peptide-to-run map, breaks the link between a spectrum and a reported ratio. Future multi-omics integration does not repair that gap.
If independent runs cannot be kept comparable, isobaric labeling is often the better match for a closed multi-group contrast. If samples cannot enter a labeling reaction, unlabeled discovery remains the workable route. If the endpoint is a short candidate list with a calibration model, targeted MS is the matching assay.
When sample number, multiplexing, or acquisition strategy makes that choice less straightforward, researchers can refer to Comparing LFQ and Isobaric Labeling Strategies in Proteomics Quantification for a more detailed strategy-selection framework.
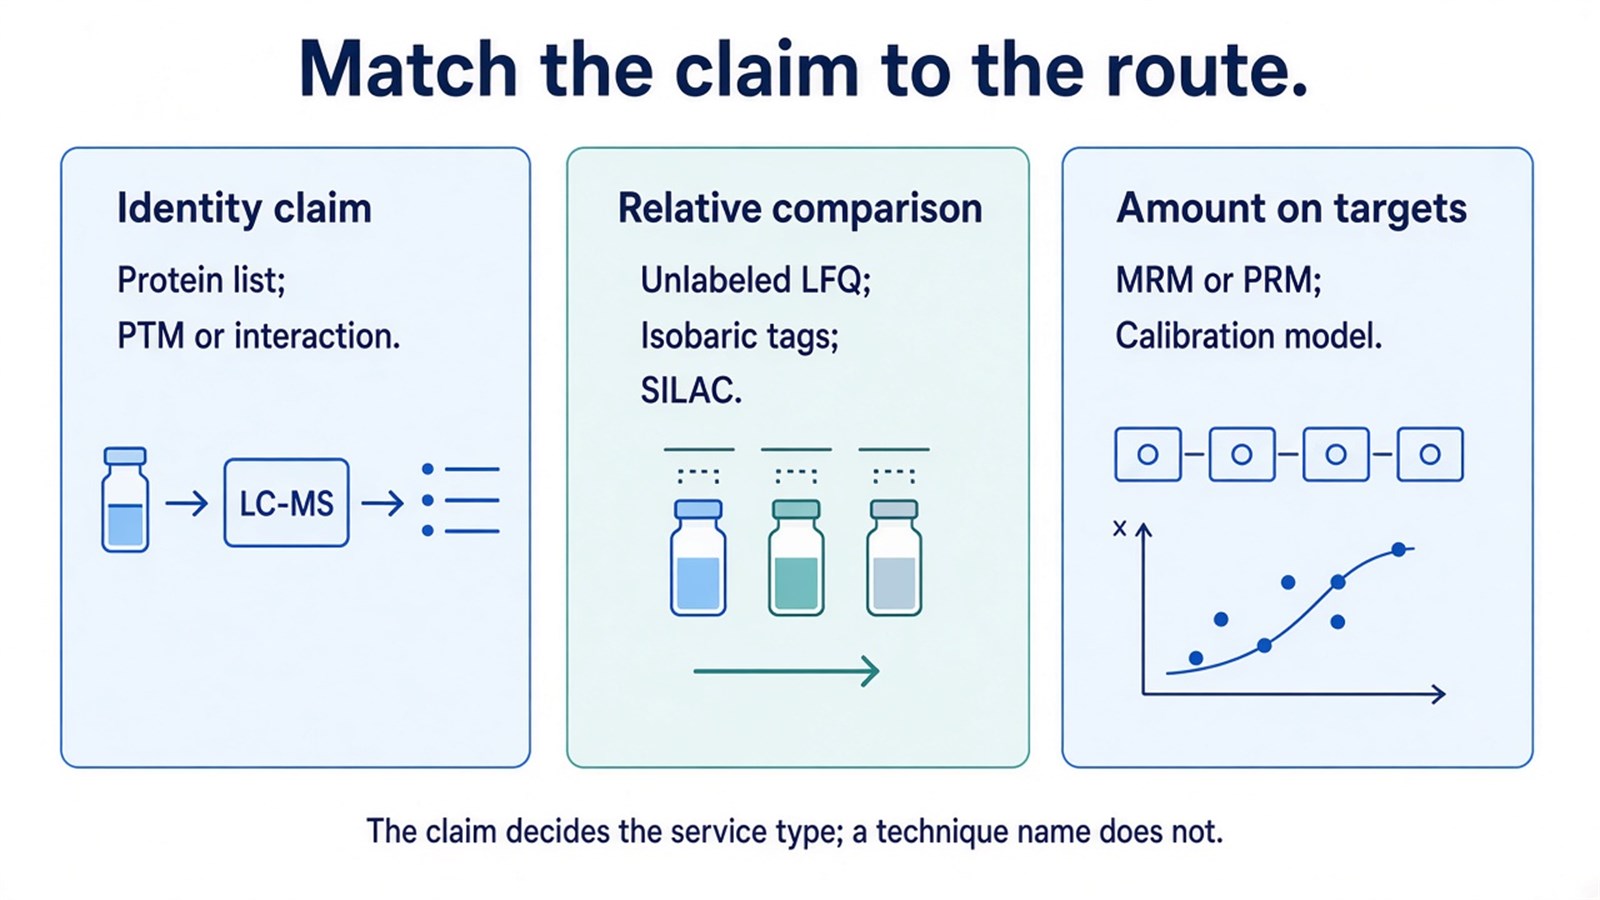
Figure 2. An identity claim stays in general proteomics work; a relative comparison selects an unlabeled, isobaric, or metabolic route; an amount on predefined targets points to targeted MS.
Quantitative proteomics supports relative change of one protein inside one study, or an amount only when standards and calibration are part of the design.
Frequently Asked Questions
1. Are proteomics services the same as quantitative proteomics?
No. Proteomics services include identification, PTM, interaction, and quantification work. Quantitative proteomics is only the abundance-comparison subset. Ordering a proteomics service does not automatically produce a valid fold-change table.
2. Do I need a quantitative method if I only need a protein list?
No. A discovery identification search can report which proteins were detected. Adding LFQ or TMT without a defined contrast creates quantitative files that cannot support a group claim.
3. Is label-free quantification the default quantitative service?
No. Unlabeled peak-area LFQ fits relative discovery on independent runs under one chromatographic plan. Closed multi-group contrasts that can be labeled often fit TMT. SILAC fits only systems that incorporate heavy amino acids. Targeted MS fits a short candidate list.
4. Can one LC-MS dataset support both identification and quantification?
Yes, when identification and quantification share one processing trail and the design matches the claim. Identification evidence does not by itself make intensities comparable across runs or channels. Comparability still depends on alignment, labeling, or a targeted assay.
Once the scientific claim, sample set, and expected protein-level readout are defined, the project can be evaluated as identification-only work or as a quantitative study. Researchers can review the MtoZ Biolabs Quantitative Proteomics Service for project-specific sample evaluation, feasibility assessment, and workflow planning.
