



Label-free quantification (LFQ) strategies estimate relative protein abundance from liquid chromatography-tandem mass spectrometry (LC-MS/MS) signals without isotopic or chemical tags. The main mass spectrometry-based routes are MS1 peak-area methods such as MaxLFQ, spectral counting from identification frequency, and unlabeled data-independent acquisition (DIA) fragment chromatograms, including SWATH-style extraction (Cox et al. 2014; Gillet et al. 2012). All share independent injections, cross-run alignment, and relative-only intensities unless matched standards are added. Prefer peak-area DDA-LFQ for identification-centric discovery with controlled run order; prefer unlabeled DIA when matrix completeness matters; keep spectral counting for coarse ranking only; switch to TMT or targeted assays when multiplex labeling or a closed amount panel fits better.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service and Deep DIA Proteomics Service for project-specific feasibility and analysis planning.
Strategy Map: Mass Spectrometry-Based Label-Free Routes
Label-free is a chemistry choice. Strategy choice still combines acquisition mode with the quantitative feature extracted from those files.
Strategy |
Acquisition and feature |
Typical use inside LFQ |
Main strategy limit |
|---|---|---|---|
MS1 peak-area DDA-LFQ (e.g., MaxLFQ) |
DDA identification; precursor chromatogram areas |
Relative discovery with mature MaxQuant-centered stats |
Stochastic missing values across runs |
Spectral counting |
DDA identification frequency or related counts |
Coarse abundance ranking |
Weak for subtle fold changes |
Unlabeled DIA / SWATH-style XIC |
Scheduled windows; fragment chromatograms |
Larger cohorts needing more complete matrices |
Window interference and library or library-free FDR burden |
Within-sample intensity proxies (e.g., iBAQ) |
Often from DDA intensities divided by observable peptides |
Composition ranking inside one sample |
Not calibrated concentration; not a cross-sample LFQ substitute |
These routes are not interchangeable names for one algorithm. Peak-area LFQ and spectral counting can share DDA files yet answer different precision needs. DIA changes both acquisition and the usual quantitative feature. iBAQ-style proxies answer within-sample composition questions and should not be reported as differential LFQ without a separate design.
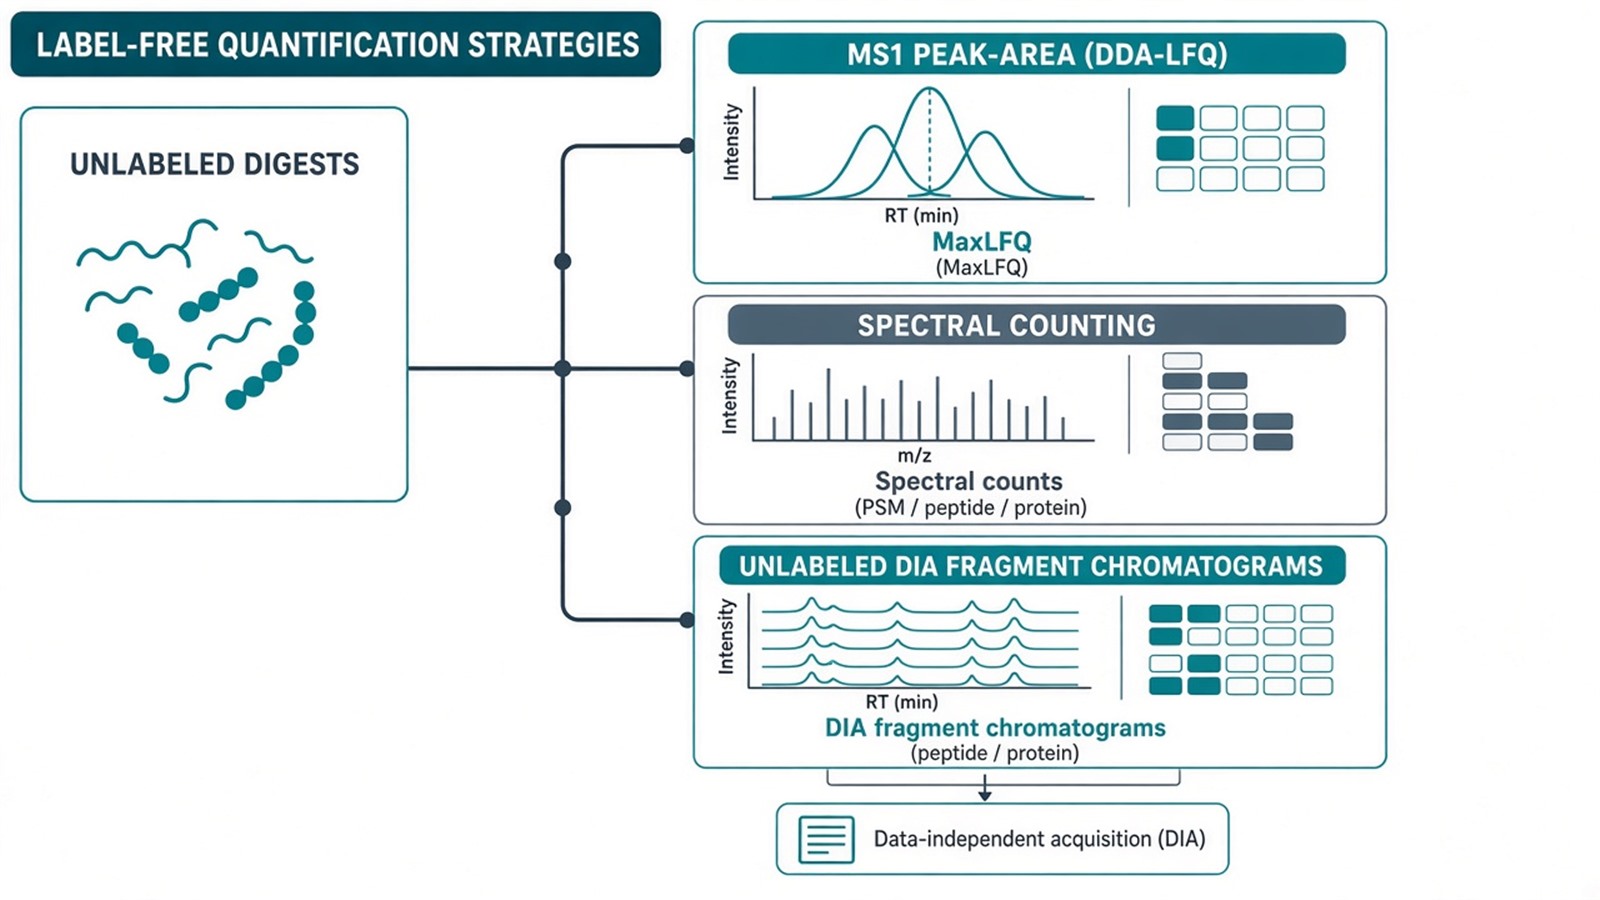
Figure 1. Mass spectrometry-based LFQ strategies share unlabeled chemistry but differ in acquisition and in which spectral features carry relative quantification.
Selecting “label-free” without naming the strategy layer (peak area, counts, or DIA fragments) leaves the quantitative claim underspecified.
Shared Layers Across LFQ Strategies
Every LFQ strategy still depends on the same upstream and downstream controls.
- Matched unlabeled prep: extraction, digestion, and loading stay comparable across the cohort.
- Independent LC-MS/MS injections under a declared DDA or DIA plan and controlled run order.
- Alignment, normalization, missing-value rules, and FDR filters that decide which peaks enter the matrix.
- A relative same-protein claim unless stable isotope-labeled standards and calibration are added later on a closed panel.
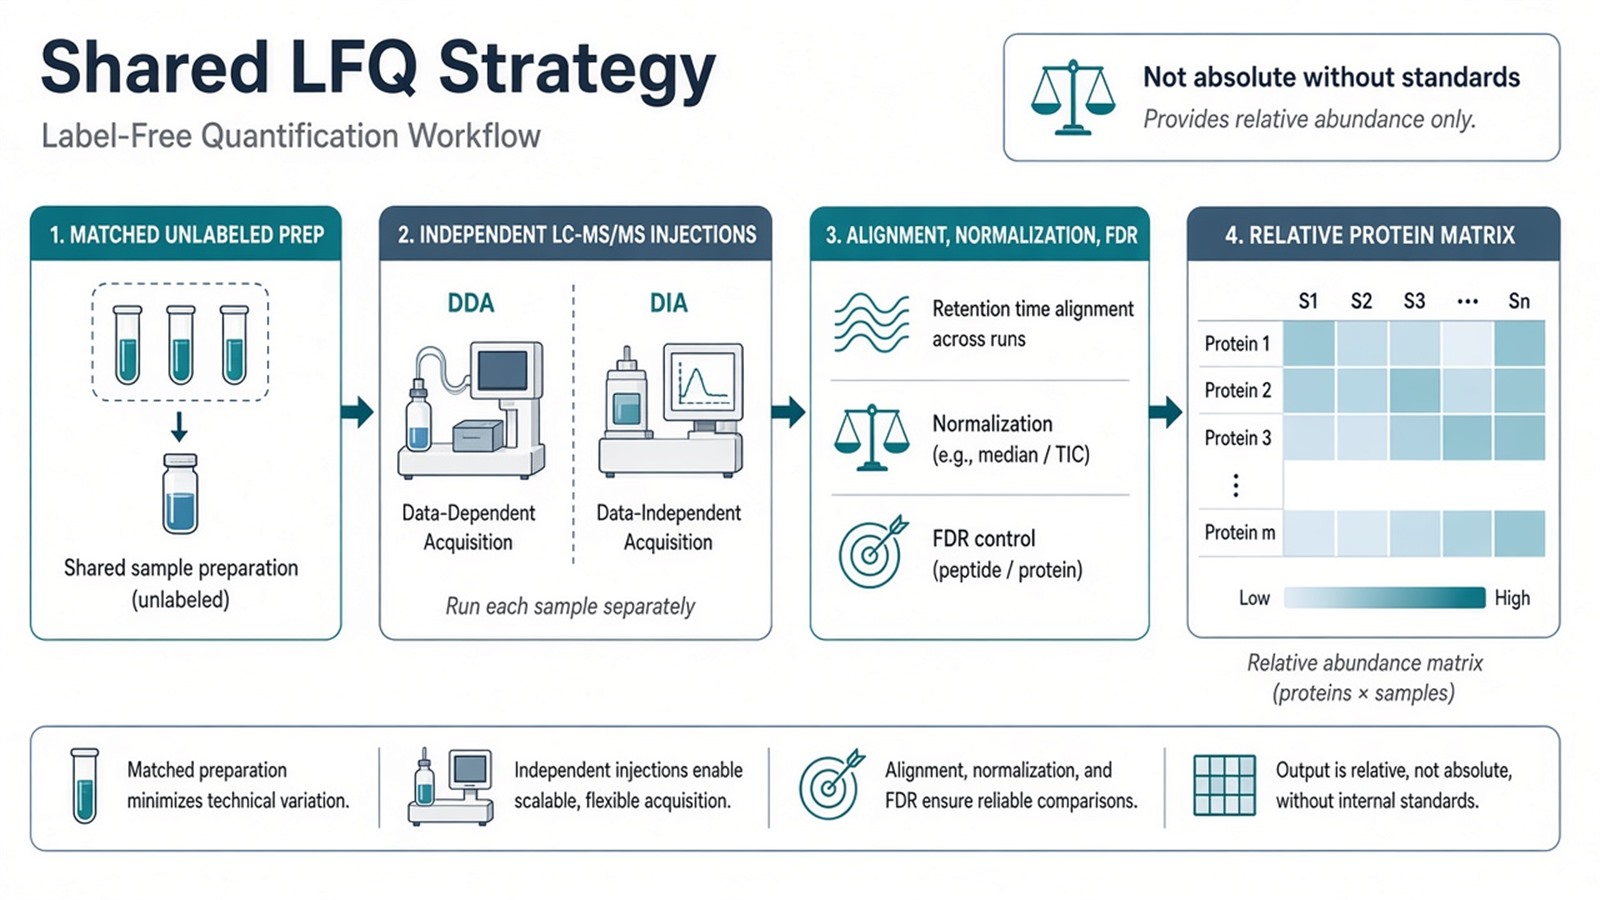
Figure 2. LFQ strategies diverge at the quantitative feature, but they share matched prep, independent runs, and relative-only reporting unless standards are added.
For operational workflow detail, see What Is Label-Free Analysis? LFQ Principles, Workflow, Advantages, and Limitations. For advantage-focused method variants, see Label-Free Protein Quantification Methods: Advantages and Limitations. For DDA versus DIA inside LFQ, see DIA vs. DDA in Label-Free Quantitative Proteomics: A Comparative Analysis. For analysis tools, see Essential Analysis Tools for Label-Free Proteomics: A Comprehensive Review of MaxQuant and DIA-NN.
Judgment Criteria: Which LFQ Strategy Fits
Study need |
Prefer this LFQ strategy |
Reassess or change family |
|---|---|---|
Identification-centric relative discovery |
MS1 peak-area DDA-LFQ |
Absolute amount or closed multiplex kit required |
Completeness across many independent runs |
Unlabeled DIA fragment quantification |
Window scheme unstable or tooling unavailable |
Only coarse ranking from ID frequency |
Spectral counting |
Subtle fold changes are the claim |
Within-sample abundance composition |
iBAQ-style proxy (separate claim) |
Cross-group differential LFQ needed |
Same-run multi-arm ratios in one mix |
Not LFQ; prefer TMT |
Enrollment open or amine chemistry fails |
Closed peptide amount units |
Not LFQ alone; prefer PRM, MRM, or AQUA |
Discovery inventory still changing |
Prefer peak-area DDA-LFQ when MaxLFQ-style statistics and controlled run order fit the cohort. Prefer unlabeled DIA when completeness is the priority and QC can defend peak groups. Prefer spectral counting only as a coarse aid. Prefer TMT when a frozen plex and amine-compatible labeling fit better. Prefer targeted SIS assays when concentration is required.
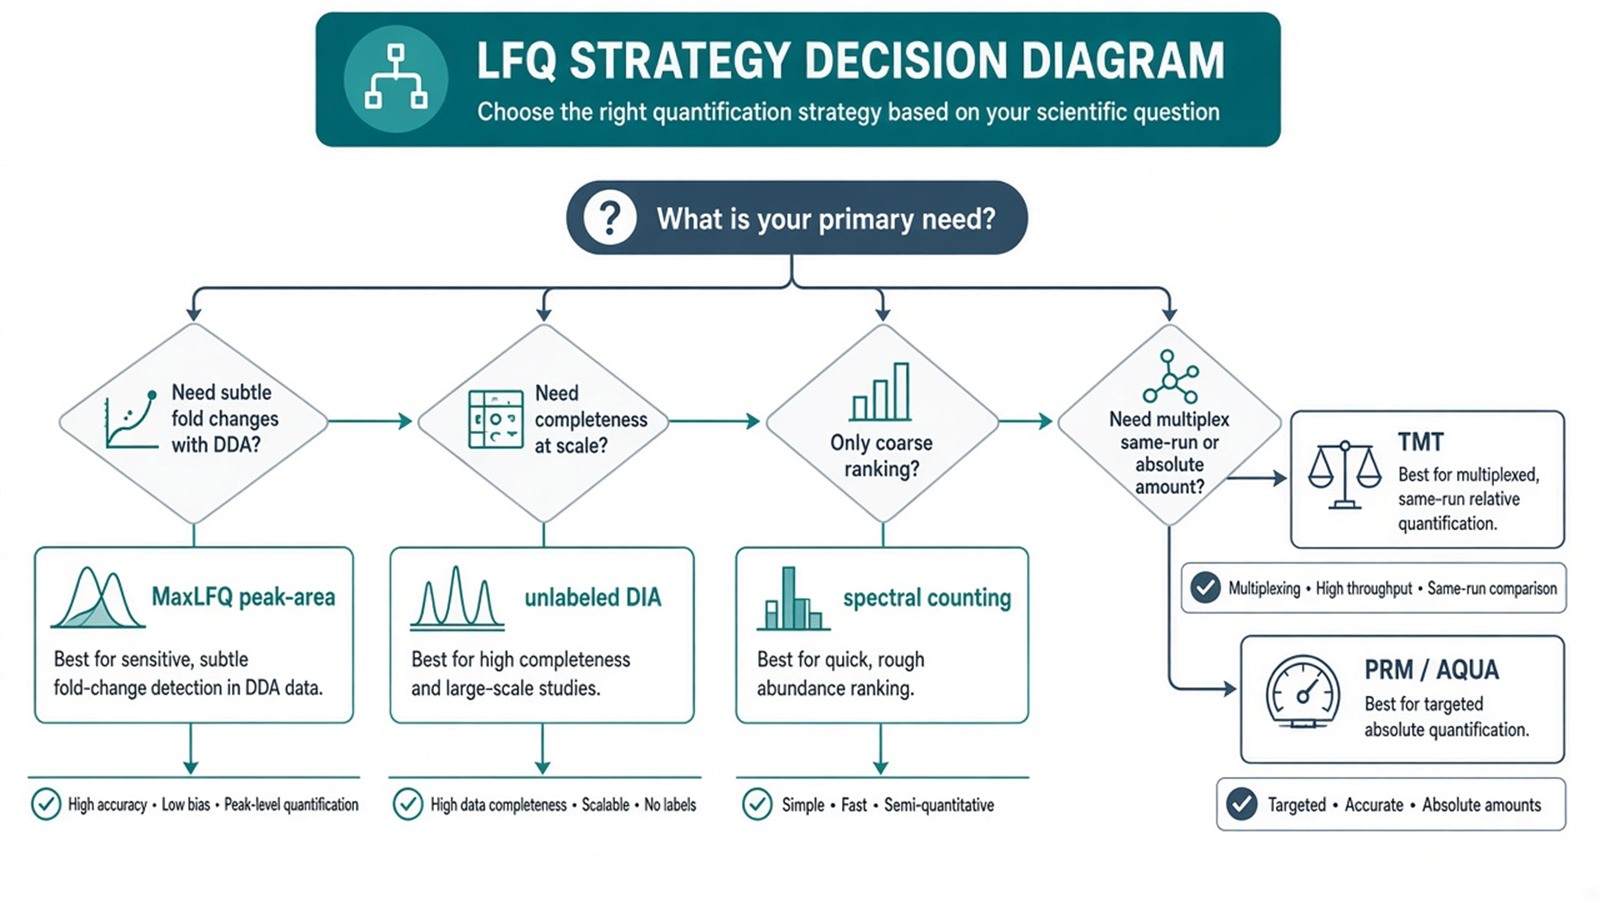
Figure 3. Choose an LFQ strategy from the quantitative feature and cohort needs; leave the label-free family when multiplex labeling or absolute units dominate.
For labeling versus unlabeled selection, see TMT vs Label Free Quantitative Proteomics and Comparing LFQ and Isobaric Labeling Strategies in Proteomics Quantification. For LFQ versus iBAQ claim separation, see What Is the Difference Between LFQ and iBAQ?. For normalization that affects every LFQ strategy, see How to Normalize Data in Label-Free Quantitative Proteomics?.
Limits and Application Boundaries
No LFQ strategy removes batch effects without design. DIA completeness is not accuracy. Spectral counts are not interchangeable with MaxLFQ peak areas for small effects. Ordinary intensities remain relative unless matched standards and calibration are added. Pathway enrichment from a differential list shows overrepresentation relative to the quantified background; it does not prove pathway activity.
Typical applications for these strategies:
- Tumor-versus-adjacent or treatment screens that need relative protein change across independent samples.
- Clinical or preclinical biofluid discovery with flexible enrollment under DDA-LFQ or unlabeled DIA.
- Matrices where labeling chemistry is risky or sample input is scarce.
- Discovery followed by PRM, MRM, or AQUA confirmation of a closed shortlist.
Diagnostic cutoffs and absolute stoichiometry sit outside ordinary research LFQ reporting unless a separately validated assay framework is in place.
Once the strategy layer, acquisition mode, and QC rules are defined, the project can be scoped as an LFQ or unlabeled DIA study. Researchers can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for sample evaluation and workflow planning. For biomedical use maps, see A Complete Guide to Label-Free Quantitative Proteomics (LFQ) in Biomedical Research and Applications of LC-MS/MS in Label-Free Quantitative Proteomics.
Frequently Asked Questions
1. Are all label-free quantification methods the same strategy?
No. They share unlabeled chemistry but differ in quantitative features: MS1 peak areas, spectral counts, or DIA fragment chromatograms.
2. Is MaxLFQ the only DDA label-free strategy?
No. MaxLFQ is a leading peak-area approach. Spectral counting is another DDA-derived strategy with coarser precision.
3. Does choosing DIA automatically improve quantification accuracy?
Not automatically. DIA can improve completeness. Accuracy still depends on window design, interference QC, alignment, and normalization.
4. Can iBAQ replace cross-sample LFQ?
No. iBAQ-style proxies rank composition within a sample under model assumptions. Cross-group differential claims need an LFQ or other comparative design.
5. When should I leave LFQ strategies for TMT or targeted assays?
When same-run multiplex ratios fit a frozen plex, or when a closed peptide list needs amount units with matched standards.
Reference
- J. Cox, M.Y. Hein, C.A. Luber, et al. (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031591
- L.C. Gillet, P. Navarro, S. Tate, et al. (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.M111.016717
