



Label-free protein quantification methods estimate relative abundance from mass spectrometry without isotopic or chemical tags. Shared advantages are simpler sample chemistry, flexible enrollment across independent liquid chromatography-tandem mass spectrometry (LC-MS/MS) runs, and compatibility with matrices that resist clean labeling. Shared limitations are chromatographic drift, missing values under data-dependent acquisition (DDA), dependence on alignment and normalization, and relative-only intensities unless matched standards are added (Cox et al. 2014). Within label-free work, MS1 peak-area methods such as MaxLFQ, spectral counting, and unlabeled data-independent acquisition (DIA) trade precision and completeness differently (Gillet et al. 2012). Choose label-free methods for relative discovery with enforced QC; keep tandem mass tag (TMT) or targeted assays when multiplex labeling or a closed peptide list fits better.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service and Deep DIA Proteomics Service for project-specific feasibility and analysis planning.
Advantages and Limitations at a Glance
Topic |
Advantage when controls hold |
Matching limitation |
|---|---|---|
Chemistry |
No isotopic or isobaric labeling step |
No same-run multiplex damper on injection drift |
Cohort design |
Flexible independent enrollment |
Every added run carries chromatography risk |
Throughput planning |
Not capped by a fixed TMT channel count |
Instrument time scales with sample number |
Quantitative claim |
Relative same-protein discovery at scale |
Not absolute concentration without standards |
Acquisition choice |
DDA-LFQ or unlabeled DIA available |
Missing values or window interference remain |
Analysis |
Mature MaxQuant, DIA-NN, and related pipelines |
Normalization, FDR, and QC decide usable peaks |
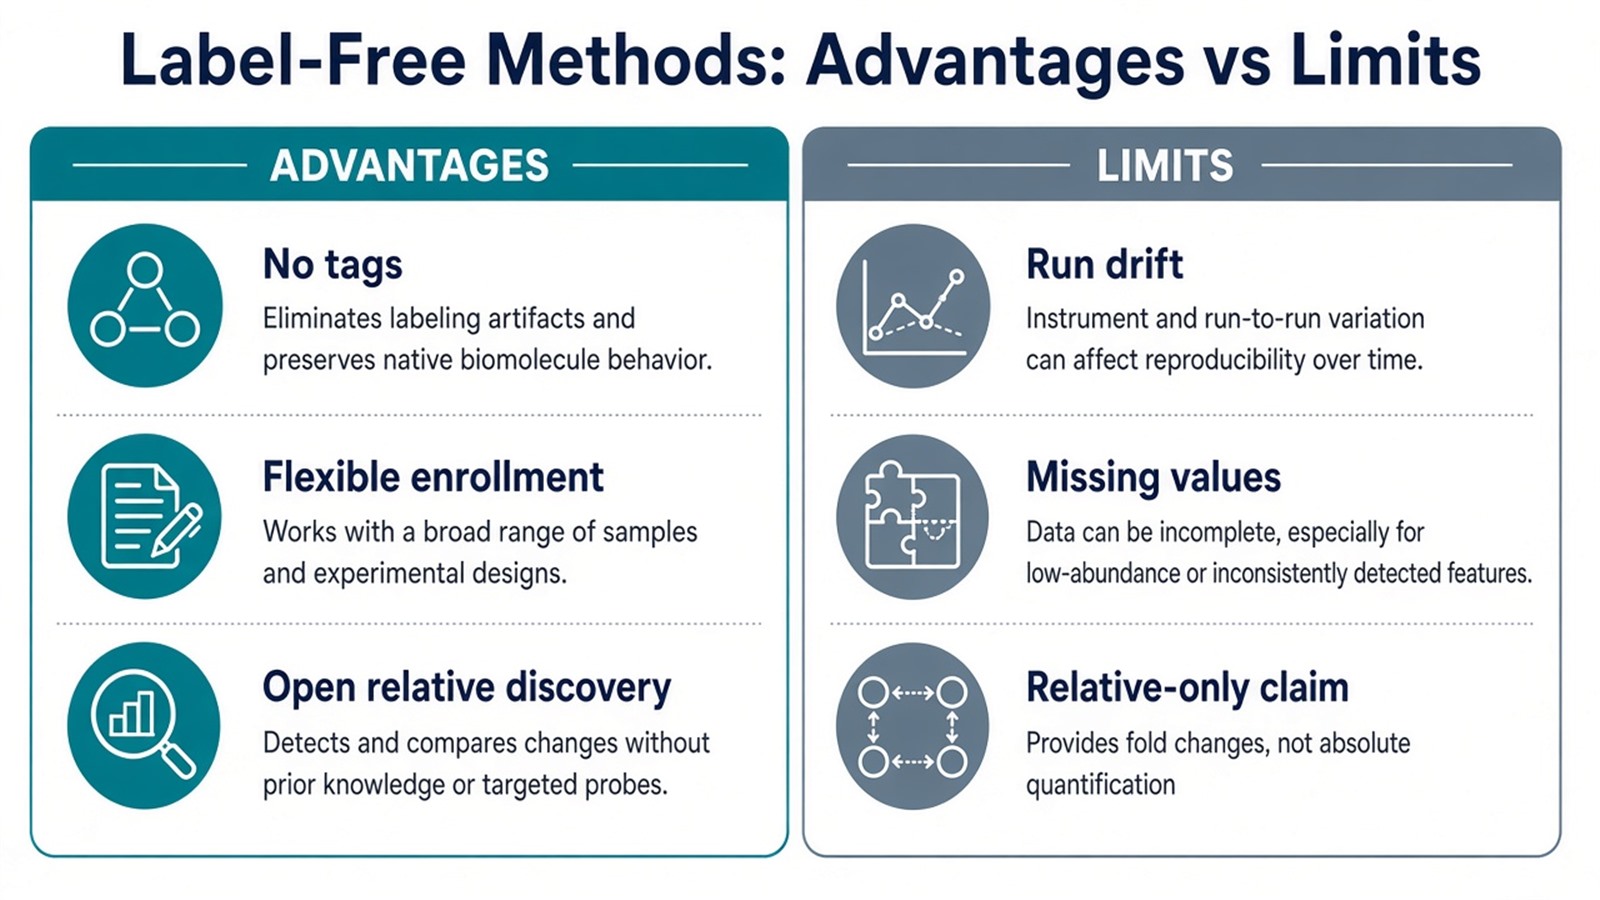
Figure 1. Label-free advantages and limitations arise together: independent unlabeled runs enable flexible relative discovery while raising batch and missing-value risk.
Calling label-free methods high precision without stating acquisition mode, run order, and the relative claim overstates method class alone.
Method Variants Inside Label-Free Quantification
Label-free is a chemistry choice. The quantitative feature still depends on acquisition and analysis.
Method variant |
Main advantage |
Matching limitation |
|---|---|---|
MS1 peak-area DDA-LFQ (e.g., MaxLFQ) |
Mature relative statistics after peptide identification |
Stochastic missingness across runs |
Spectral counting |
Simple ranking from identification frequency |
Weaker for subtle fold changes than peak-area LFQ |
Unlabeled DIA fragment chromatograms |
Often more complete matrices via scheduled windows |
Chimeric spectra and library or library-free FDR burden |
DDA-LFQ fits identification-centric discovery and MaxLFQ-centered plans when run order is controlled. Spectral counting can support coarse abundance ranking but should not be treated as equivalent to intensity-based LFQ for small effects. Unlabeled DIA fits larger cohorts when completeness matters more than single-precursor spectral simplicity.
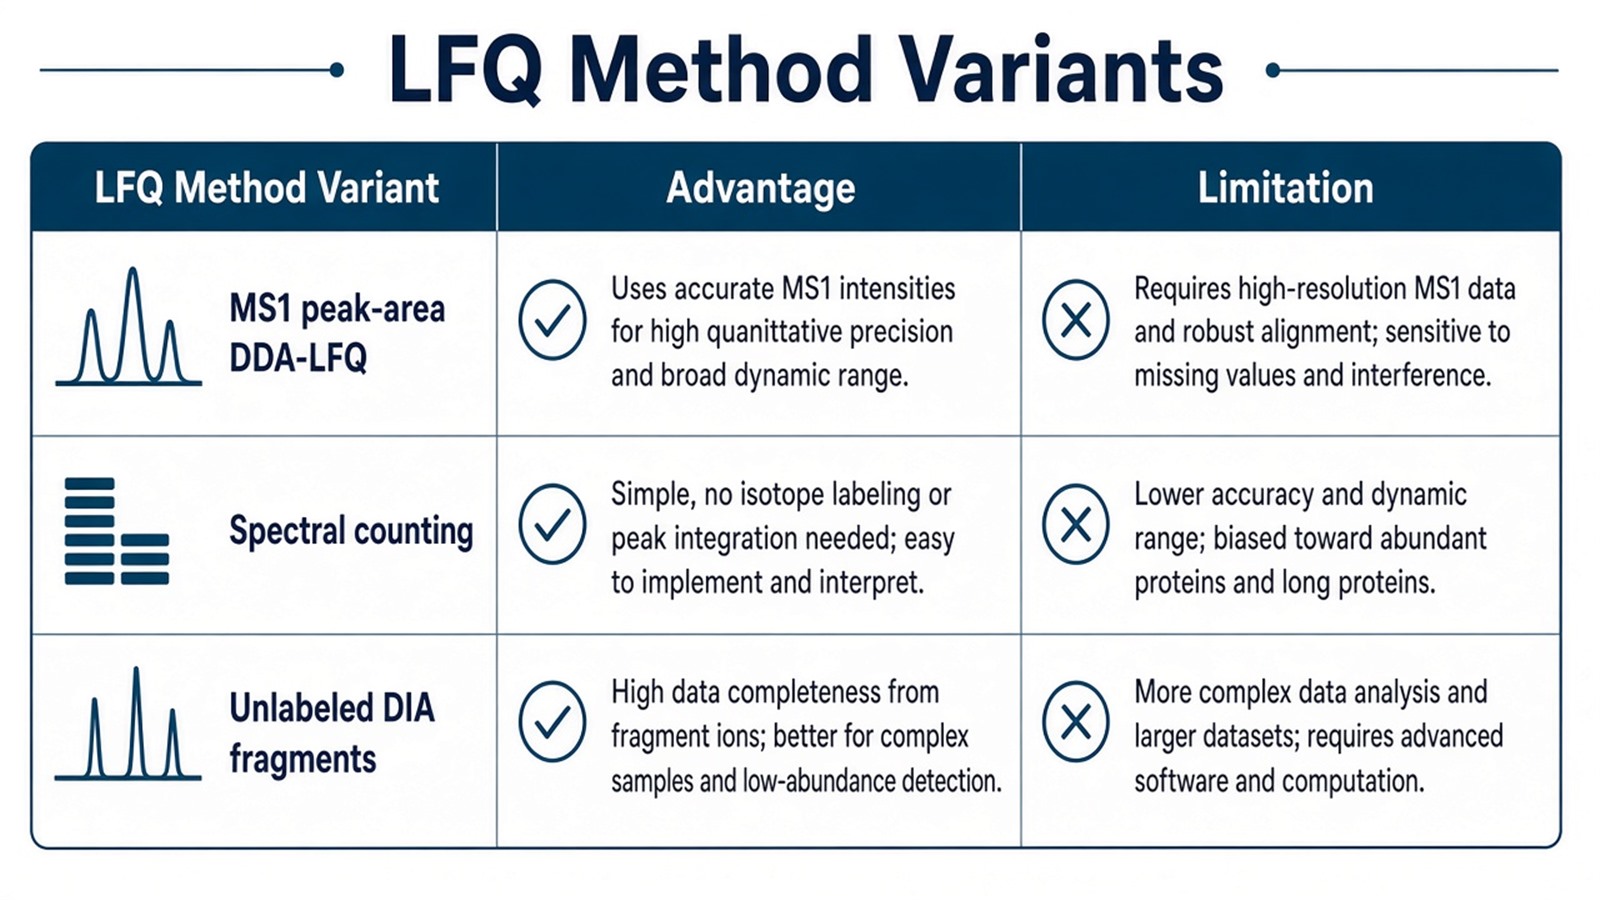
Figure 2. Label-free methods share unlabeled chemistry but differ in which spectral features carry relative quantification.
For operational LFQ workflow detail, see What Is Label-Free Analysis? LFQ Principles, Workflow, Advantages, and Limitations. For a closely related design-level advantage list, see Advantages and Disadvantages of Label-Free Quantitative Proteomics. For DDA versus DIA inside LFQ, see DIA vs. DDA in Label-Free Quantitative Proteomics: A Comparative Analysis. For DIA technique trade-offs, see Advantages and Disadvantages of DIA in Protein Quantification.
Judgment Criteria: When Label-Free Methods Fit
Study need |
Label-free methods often fit |
Reassess before committing |
|---|---|---|
Claim |
Relative same-protein discovery |
Absolute concentration or diagnostic cutoff |
Sample plan |
Independent injections; enrollment may continue |
All contrasts must share one TMT plex |
Chemistry |
Labeling impractical, costly, or too wasteful |
Clean amine labeling and closed plex preferred |
Completeness priority |
Unlabeled DIA when tooling and QC are ready |
Simple matrix where DDA depth already suffices |
Panel status |
Open discovery inventory still needed |
Closed shortlist ready for PRM or MRM |
Prefer label-free peak-area or DIA methods when samples must stay unlabeled and relative discovery is the claim. Prefer spectral counting only for coarse ranking when intensity pipelines are unavailable. Prefer TMT when same-run multiplex ratios fit a frozen kit. Prefer PRM, MRM, or AQUA when targets are closed or amount units are required.
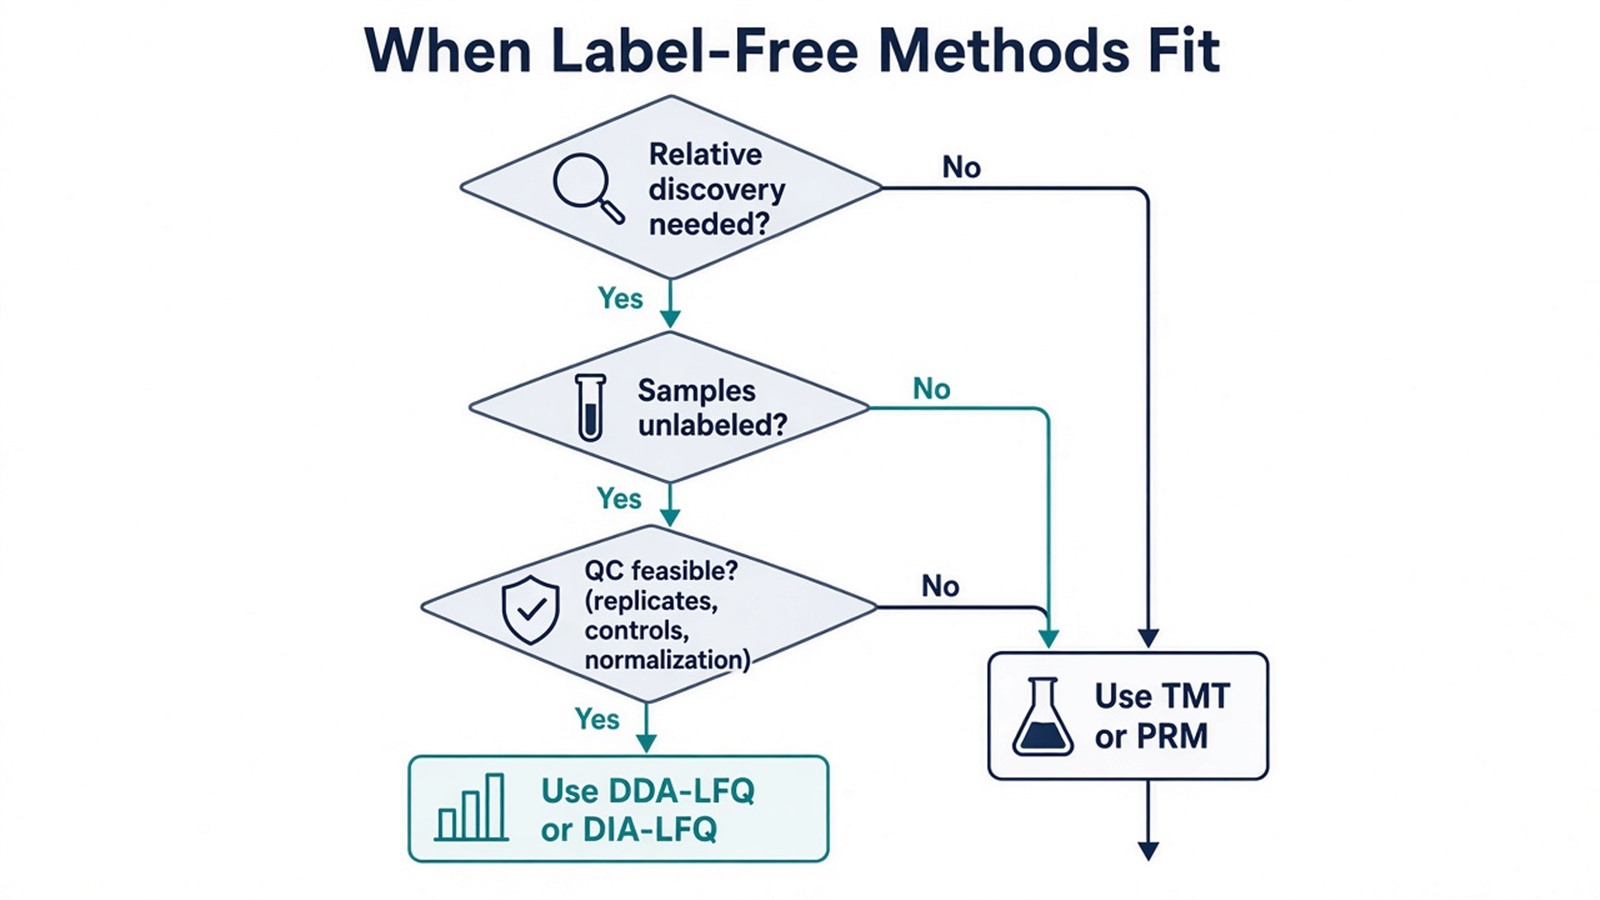
Figure 3. Select label-free methods from the relative claim and enrollment rules; change route when multiplex labeling or closed-panel amount dominates.
For labeling versus unlabeled selection, see TMT vs Label Free Quantitative Proteomics and Comparing LFQ and Isobaric Labeling Strategies in Proteomics Quantification. For normalization that affects label-free limits, see How to Normalize Data in Label-Free Quantitative Proteomics?. For analysis software, see Essential Analysis Tools for Label-Free Proteomics: A Comprehensive Review of MaxQuant and DIA-NN.
Limits and Application Boundaries
Label-free methods do not remove batch effects without design. Completeness in DIA is not accuracy. Ordinary intensities remain relative unless stable isotope-labeled standards (SIS) and calibration are added. Pathway enrichment from a differential list shows overrepresentation relative to the quantified background; it does not prove pathway activity.
Typical applications:
- Mechanism and treatment screens that need relative protein change across independent samples.
- Clinical or preclinical biofluid discovery with flexible enrollment.
- Matrices where labeling chemistry is risky or sample input is scarce.
- Discovery followed by PRM or MRM confirmation of a closed shortlist.
Diagnostic cutoffs and absolute stoichiometry sit outside ordinary research label-free reporting unless a separately validated assay framework is in place.
Once the label-free method variant, acquisition mode, and QC rules are defined, the project can be scoped as an LFQ or unlabeled DIA study. Researchers can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for sample evaluation and workflow planning. For application maps, see Applications of LC-MS/MS in Label-Free Quantitative Proteomics and A Complete Guide to Label-Free Quantitative Proteomics (LFQ) in Biomedical Research.
Frequently Asked Questions
1. Are all label-free methods the same?
No. They share unlabeled chemistry but differ in quantitative features: MS1 peak areas, spectral counts, or DIA fragment chromatograms.
2. Is label-free always cheaper and more accurate than TMT?
Reagent cost often favors label-free at scale, but accuracy follows QC, not the label-free name. TMT can help when a closed plex and same-run comparison fit better.
3. Does DIA remove label-free limitations?
DIA can reduce stochastic missingness. It does not remove window interference, batch drift, or the relative-only claim.
4. Can spectral counting replace MaxLFQ-style peak-area LFQ?
Usually not for subtle fold changes. Spectral counting is coarser and better treated as a ranking aid.
5. Do label-free methods provide absolute protein concentration?
Not by default. Absolute amount needs matched standards and calibration, typically on a closed panel after discovery.
Reference
- J. Cox, M.Y. Hein, C.A. Luber, et al. (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031591
- L.C. Gillet, P. Navarro, S. Tate, et al. (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.M111.016717
