



Precise label-free protein analysis depends on matched sample prep before any LC-MS/MS run: declare matrix type, use a shared lysis buffer and extraction rule across contrast arms, quantify total protein and load peptides by amount rather than volume alone, then reduce, alkylate, digest, and clean up so detergents and salts do not carry into chromatography (Wisniewski et al. 2009). Label-free quantification (LFQ) omits isotopic or isobaric tags, so independent injections carry full chromatographic and batch risk; prep drift becomes ratio error that software cannot fully remove (Cox et al. 2014). Reserve aliquots for QC pools and optional PRM or AQUA follow-up before scarce material is consumed. Pilot digests in the authentic matrix when input is low or prep is new.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service and Deep DIA Proteomics Service for project-specific feasibility and sample planning.
Sample Types and Prep Judgments for Label-Free Analysis
Label-free analysis still bottom-up digests proteins to peptides. Prep must match the biological question and the acquisition class (DDA peak-area LFQ or unlabeled DIA).
Sample context |
Prep judgment that often gates LFQ quality |
Common failure mode |
|---|---|---|
Cultured cells or organoids |
Matched harvest, lysis, and confluence state |
Growth state confounds treatment ratios |
Fresh tissue or biopsy |
Minimal freeze-thaw; consistent homogenization |
Unequal recovery looks like biology |
FFPE or archived tissue |
Declared extraction compatible with digestion |
Recovery bias across blocks |
Plasma or serum |
Depletion or fractionation declared up front |
High-abundance masking and batch drift |
Low-input or scarce aliquots |
Protein assay and load QC before full cohort |
Volume loading hides low yield |
Hard-to-label matrices |
Unlabeled chemistry avoids tag failures |
Prep still must match across arms |
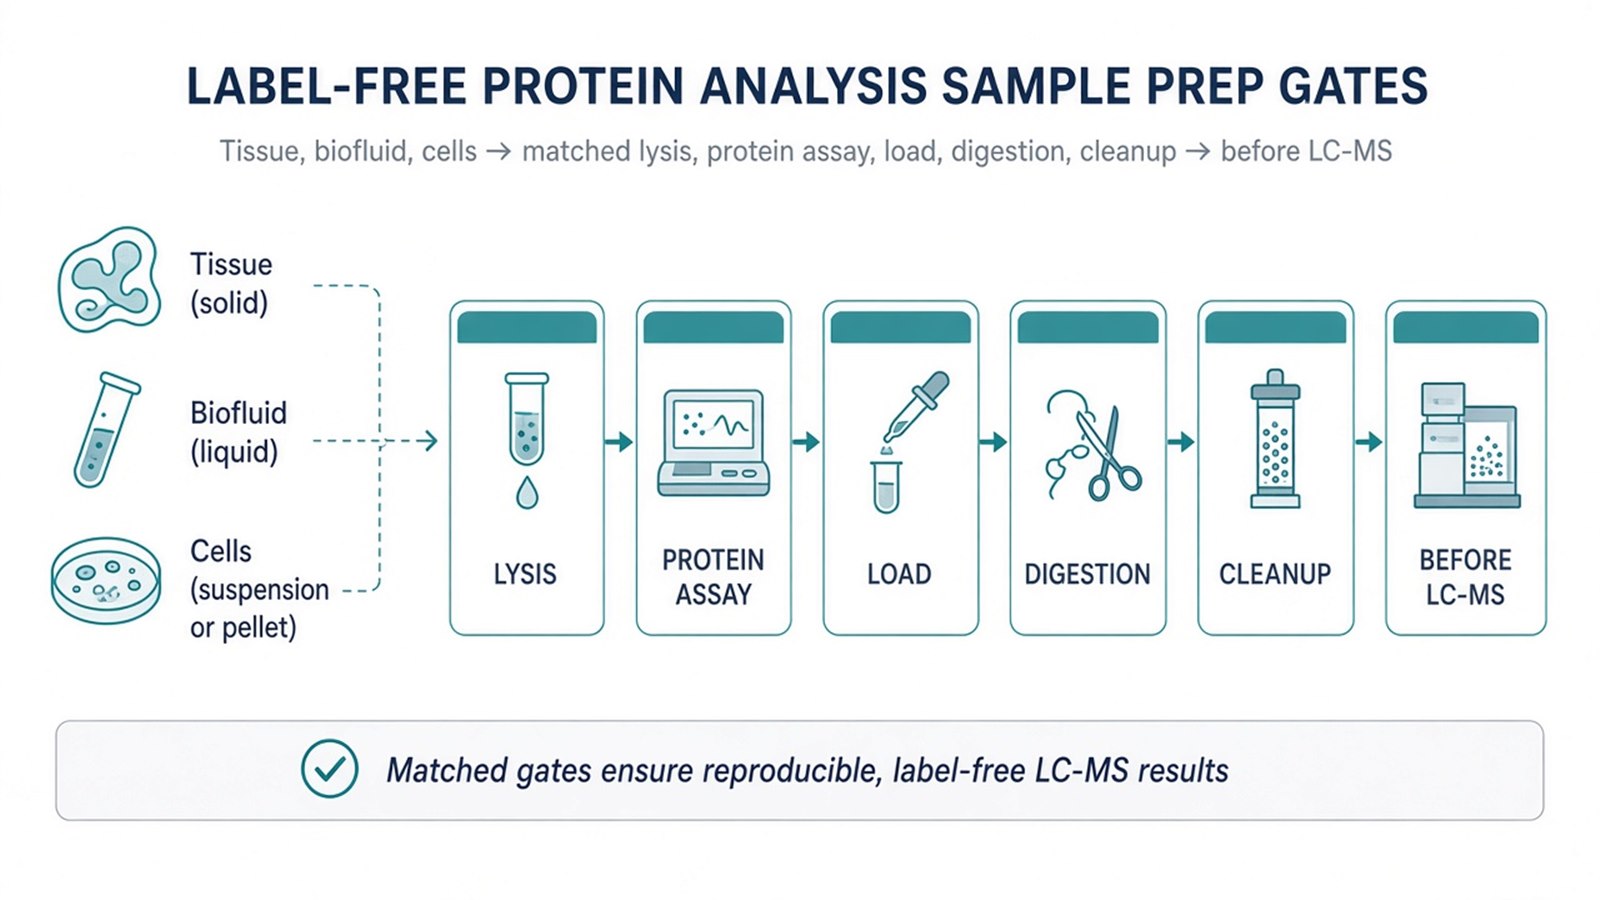
Figure 1. Label-free precision starts in prep: matched chemistry across groups sets the ceiling for later LFQ or unlabeled DIA.
Calling label-free analysis marker-free accuracy without matched load, digestion, and the relative claim overstates what omitting tags alone provides.
For prep troubleshooting, see The Impact of Sample Preparation on Quantitative Results in Quantitative Proteomics. For relative versus absolute prep gates, see Absolute and Relative Quantitative Proteomics Analysis.
Shared Prep Workflow Before LFQ or Unlabeled DIA
- Freeze contrast arms, replicates, and the relative claim before scaling prep.
- Extract proteins under one declared lysis recipe per study arm comparison.
- Assay total protein; normalize load into digestion; avoid volume-only loading.
- Reduce, alkylate, and digest (usually trypsin); record enzyme-to-protein ratio and time.
- Clean peptides (solid-phase extraction or equivalent); control detergent and salt carryover.
- Optional depletion or fractionation when complexity demands it; apply consistently across groups.
- Store QC pools and reserve aliquots for targeted follow-up when discovery is planned.
- Branch acquisition: DDA for MS1 peak-area LFQ, or windowed DIA for fragment peak groups (Demichev et al. 2020).
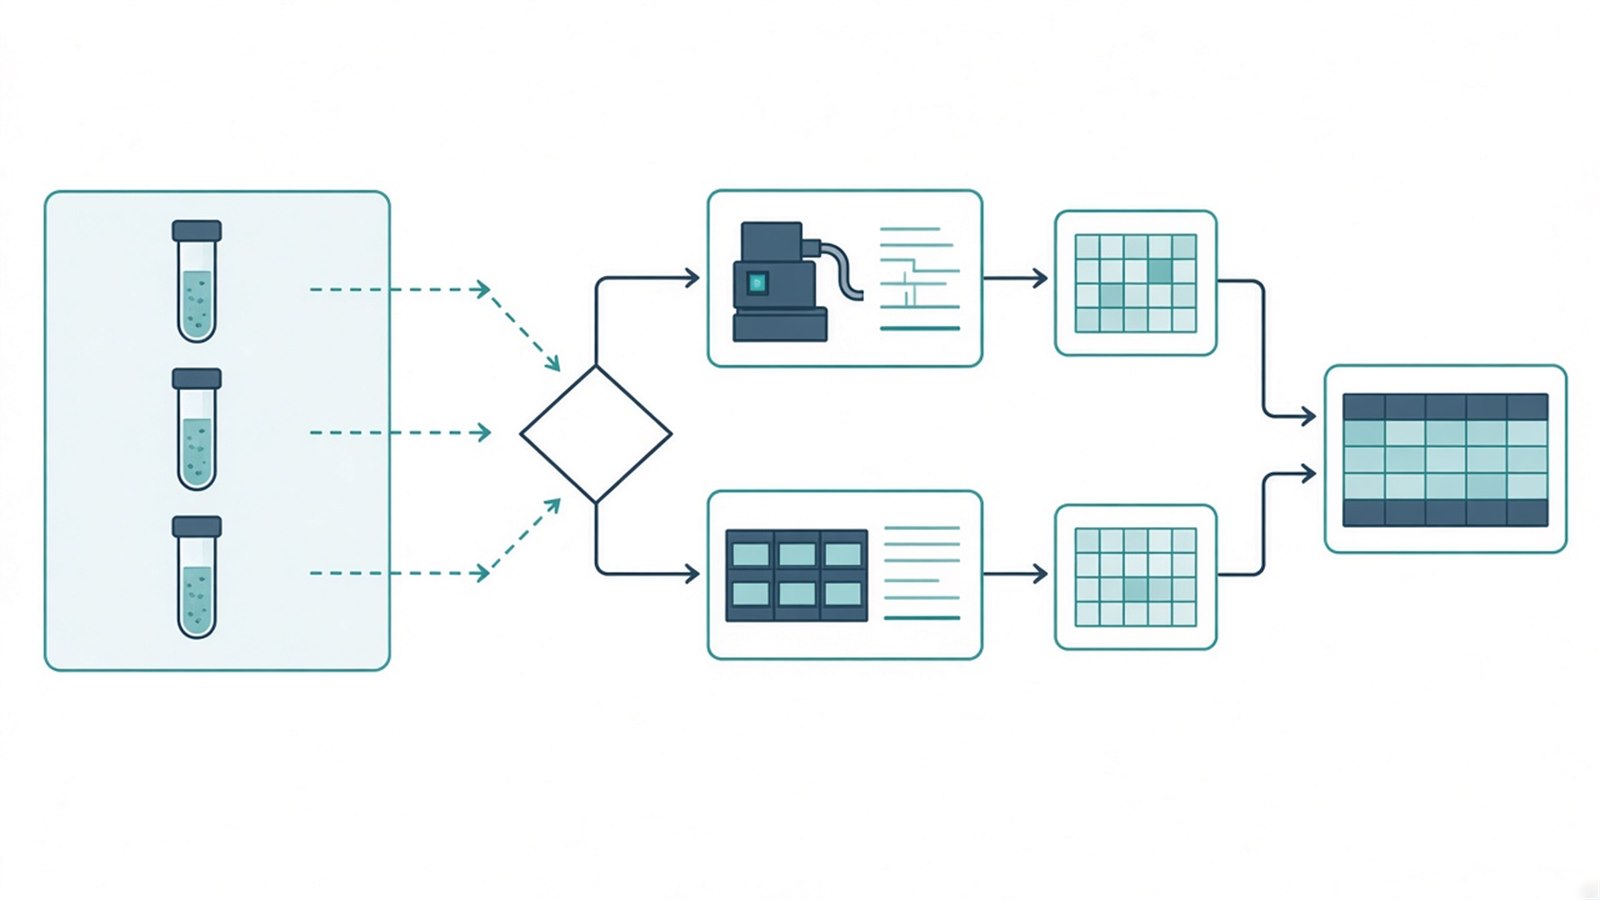
Figure 2. Shared prep feeds both DDA-LFQ and unlabeled DIA; acquisition choice comes after chemistry is stable.
For LFQ principles and workflow detail, see What Is Label-Free Analysis? LFQ Principles, Workflow, Advantages, and Limitations. For strategy mapping, see Label-Free Quantification Methods: Mass Spectrometry-Based Protein Quantification Strategies. For normalization after prep is sound, see How to Normalize Data in Label-Free Quantitative Proteomics?.
Judgment Criteria: When Label-Free LFQ Fits
Study need |
Label-free route often fits |
Reassess |
|---|---|---|
Claim |
Relative same-protein discovery |
Absolute concentration or diagnostic cutoff |
Chemistry |
Labeling impractical or risky |
Clean amine labeling and frozen TMT plex preferred |
Enrollment |
Independent injections; samples may arrive later |
All contrasts must share one TMT mix |
Acquisition |
DDA-LFQ when MS1 areas fit; DIA when completeness priority |
Acquisition undecided while prep batches drift |
Follow-up |
Open inventory for later PRM or AQUA |
Closed shortlist already needs amount units now |
Prefer DDA-LFQ when identification-centric MS1 peak areas and flexible enrollment fit after matched prep. Prefer unlabeled DIA when windowed acquisition and extraction QC better match cohort completeness needs. Prefer TMT when same-run multiplex ratios fit a frozen kit. Prefer PRM, MRM, or AQUA when targets are closed or amount units are required.
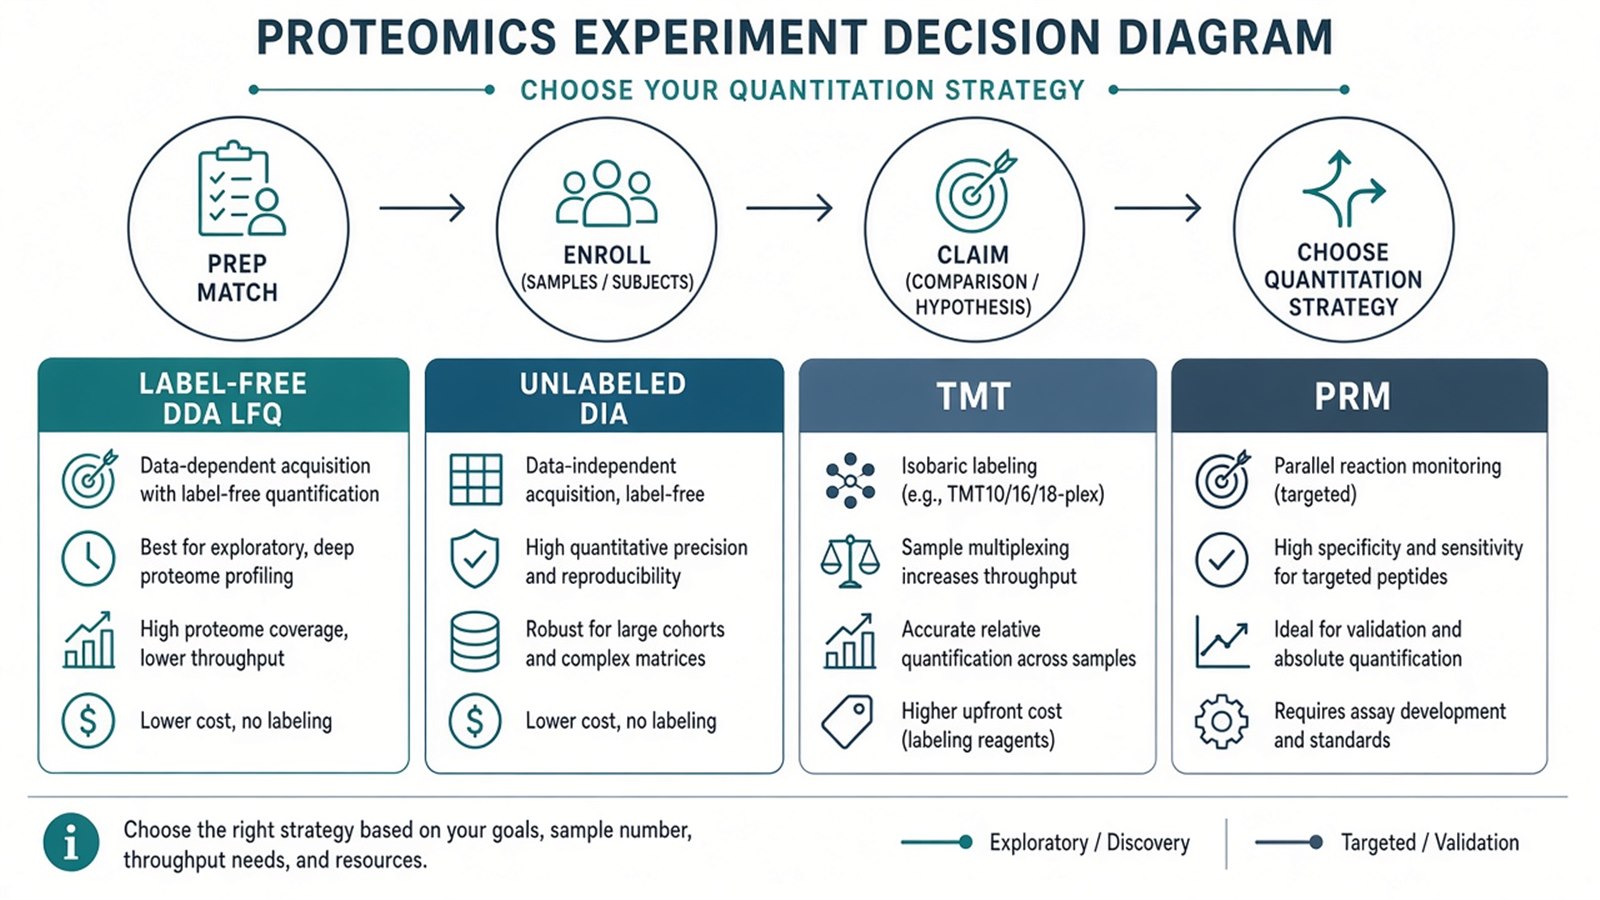
Figure 3. Choose label-free LFQ or DIA when unlabeled relative discovery fits matched prep; change family when multiplex labeling or absolute panels dominate.
For advantage and tool trade-offs, see Label-Free Quantification: Advantages, Applications, and Tools and Label-Free Protein Quantification Methods: Advantages and Limitations. For labeling comparison, see TMT vs Label Free Quantitative Proteomics and Comparing LFQ and Isobaric Labeling Strategies in Proteomics Quantification. For DDA versus DIA inside label-free work, see DIA vs. DDA in Label-Free Quantitative Proteomics: A Comparative Analysis.
Limits and Application Boundaries
Matched prep does not convert relative intensities into molar concentration. Label-free flexibility does not remove run-order confounding or chromatographic drift. DDA-LFQ can show stochastic missing values; DIA completeness is not accuracy. Software normalization cannot repair unequal digestion or detergent carryover. Pathway enrichment shows overrepresentation relative to the quantified background; it does not prove pathway activity. Diagnostic cutoffs sit outside ordinary research label-free reporting unless a separately validated assay framework is in place.
Typical applications when prep and claim are defended:
- Disease or treatment screens with relative protein change across matched digests.
- Drug-response proteomes with flexible unlabeled enrollment.
- Biofluid discovery cohorts where labeling chemistry is impractical.
- Non-model or hard-to-label matrices after consistent extraction rules.
- Discovery lists nominated for later PRM, MRM, or AQUA confirmation.
Once matrix, prep recipe, load rules, and acquisition branch are defined, the project can be scoped as label-free quantitative proteomics. Researchers can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for sample evaluation and workflow planning.
Frequently Asked Questions
1. Does label-free analysis eliminate sample prep requirements?
No. Without tags, every run inherits prep and chromatography variability. Matched lysis, digestion, and load are required.
2. What loading rule best supports precise label-free ratios?
Assay total protein and load by mass into digestion. Volume-only loading often hides yield differences between groups.
3. Is label-free the same as LFQ?
LFQ usually means relative quantification from unlabeled LC-MS/MS, often MS1 peak-area methods or unlabeled DIA extraction. Prep rules apply to both.
4. Can label-free MS report absolute protein amount?
Not by default. Absolute amount needs matched stable isotope standards and calibration, typically on a targeted panel.
5. When should prep problems stop an LFQ cohort?
When pilot digests show drifting yield, persistent detergent carryover, or load failures that track group labels. Fix prep before scaling acquisition.
Reference
- J.R. Wisniewski, A. Zougman, N. Nagaraj, M. Mann (2009). Universal sample preparation method for proteome analysis. Nat. Methods, 6, 359-362. https://doi.org/10.1038/nmeth.1322
- J. Cox, M.Y. Hein, C.A. Luber, et al. (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031591
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
