



Data-independent acquisition (DIA) protein quantification is applied when unlabeled digests on separate liquid chromatography-tandem mass spectrometry (LC-MS/MS) injections need a windowed MS/MS matrix for a predefined relative contrast after false discovery rate (FDR) controlled extraction (Gillet et al. 2012). DIA names the acquisition class. Sequential window acquisition of all theoretical fragment ion spectra (SWATH-MS) is one common window plan inside that class. Application value sits in cohort design, matched pretreatment, locked methods, and contrast-tested statistics, not in a disease or omics keyword alone. The guide below maps DIA quantification application patterns and ties each to workflow, parameters, limits, and route choice. It is not a diagnostic promise, not a multi-omics software manual, and not a repeat of DDA versus DIA theory.
Discovery outputs remain candidate lists until targeted confirmation or stable isotope-labeled internal standard (SIS) designs support remeasurement or amount claims (Gerber et al. 2003).
In MtoZ Biolabs offerings, label-free DIA discovery is commonly evaluated when open contrasts, separate injections, and documented extraction fit the matrix and enrollment plan.
Operational stages appear in Workflow of DIA in Protein Quantification. SWATH-focused domain examples appear in Application of SWATH-Based Protein Quantification.
Application Patterns That Commonly Use DIA Quantification
Five patterns appear when teams describe DIA protein quantification applications. Each maps to list status and follow-up expectations.
Biomarker-oriented discovery compares predefined groups such as case versus control, stage, or risk stratum after matched prep. DIA fits open lists on many files when enrollment spans batches (High-throughput SWATH-MS Quantitative Proteomics for Biomarker Discovery, Typical Applications of DIA-Based Quantitative Proteomics in Clinical Research).
Pharmacology and target-mechanism studies compare abundance before and after compound exposure, dose steps, or time courses. DIA supplies wide relative matrices when contrasts are frozen to vehicle or baseline arms (Quantitative Proteomics in Disease and Drug Discovery).
Validation staging narrows discovery candidates through parallel reaction monitoring (PRM) or multiple reaction monitoring (MRM) on a closed peptide panel. DIA supplies the open stage; targeted acquisition supplies remeasurement (Application of DIA-PRM Proteomics).
Large cohort and multi-batch enrollment needs interleaved acquisition and one extractor version across files. DIA window plans including SWATH-style schedules support open contrasts when prep stays matched (Rosenberger et al. 2017).
Multi-omic integration overlays transcriptomic or metabolomic context on a contrast-tested protein list. Omics layers interpret biology after QC. They do not replace contrast design or missing-value policy.
DIA application value is a defensible relative matrix plus a declared contrast, not clinical validation or precision medicine by default.
Oncology candidate framing appears in DIA Proteomics Services for Cancer Biomarker Discovery.
Study Designs That Make DIA Applications Defensible
Application quality follows staging and contrast discipline.
Contrast frozen before threshold exploration. Arms should not be merged or relabeled after acquisition.
Matched pretreatment across groups. Lysis, digestion, cleanup, and load rules align within the application pattern. Plasma depletion or fractionation applies equally to all arms when used.
Interleaved run order when cohort size grows. Batch structure that tracks group labels confounds biomarker and pharmacology interpretations.
Library or library-free extraction declared with matrix provenance. Unified FDR and interference filters precede candidate or mechanism language (Demichev et al. 2020).
Separate interpretation layers for discovery, validation, and omics overlay. Validation wording requires PRM, SIS, or independent cohort design, not discovery p-values alone.
Shared Workflow From Application Question to Interpretable Matrix
A practical DIA application spine usually runs as follows.
- Confirm application pattern, matrix, contrast, and relative claim.
- Prepare matched digests to injection-ready loads on separate injections for label-free work.
- Pilot DIA windows on the matrix; lock LC, window table, and cycle time.
- Acquire cohort files with QC inserts and interleaved order as agreed.
- Extract peptides under FDR control; normalize; handle missing values (Lazar et al. 2016).
- Test the predefined contrast only; document batch and dropout flags.
- Rank proteins for pattern-specific interpretation or optional PRM, MRM, or SIS follow-up.
- Optional omics overlay on the tested list when multi-layer context is in scope.
Steps 1 through 2 gate every pattern. Step 6 is where biomarker, drug-mechanism, or validation language must match list status.
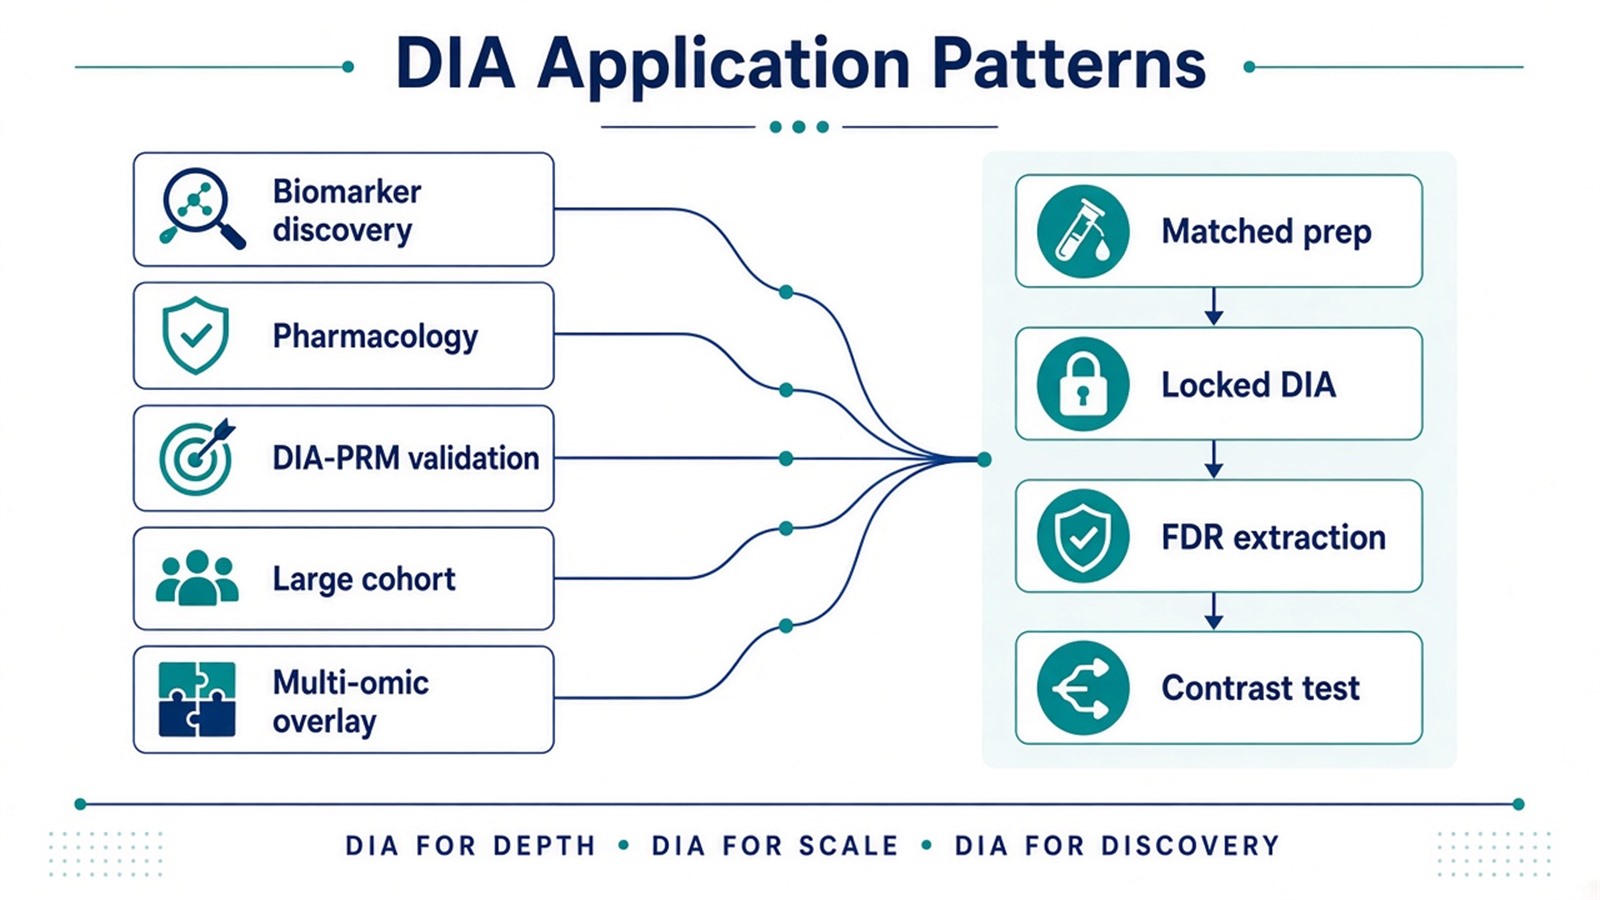
Figure 1. DIA applications share matched prep, locked acquisition, and contrast-tested extraction before pattern-specific follow-up.
Prep and acquisition handoff appears in SWATH MS Analysis. Extraction conventions appear in DIA Data Analysis Methods in Proteomics.
Parameters and Limits by Application Pattern
Application pattern |
Parameter that must be declared |
Limit if mis-set |
|---|---|---|
Biomarker discovery |
Candidate versus validated status |
Discovery peaks called diagnostic |
Pharmacology |
Vehicle or time-zero reference |
Unequal compound handling prep |
DIA-PRM staging |
Panel size versus duty cycle |
Panel longer than cycle allows |
Large cohort |
Window plan locked, one extractor |
Mid-cohort method change |
Multi-omic overlay |
Protein contrast tested first |
Omics rescue of undefined contrast |
All patterns |
Missing-value policy |
Imputed gaps without rules |
Follow-up |
SIS only when amount is claim |
Open DIA intensities as concentration |
Limits follow the same table. DIA applications do not certify clinical tests, drug labels, or regulatory biomarkers. High throughput does not remove abundance-dependent missingness. Multi-omics integration does not fix post hoc relabeling or unequal prep.
Window plan specifics for SWATH schedules compare with Principle of SWATH-Based Protein Quantification. Mobility-enhanced cohorts compare with Workflow of 4D-DIA Quantitative Proteomics.
How to Choose DIA for the Application Goal
Use pattern, list status, enrollment, and follow-up unit together.
Application need |
DIA plan that often fits |
Recheck before committing |
|---|---|---|
Open discovery, many files |
Label-free DIA with locked windows |
Run order tracks group |
High-file biomarker screen |
DIA or SWATH-style after pilot |
Biomarker wording without validation design |
Mechanism after treatment |
Matched prep, frozen time points |
Relabel time bins after acquisition |
Candidates need remeasurement |
DIA discovery then PRM panel |
PRM without aliquot reserve |
Locked monitoring panel |
PRM or MRM without rediscovery |
Full DIA when list already closed |
Complex digest, mobility gain |
4D-DIA after pilot |
Mobility-free DIA when pilot is clean |
Amount on named peptides |
SIS targeted assay |
Discovery intensities as concentration |
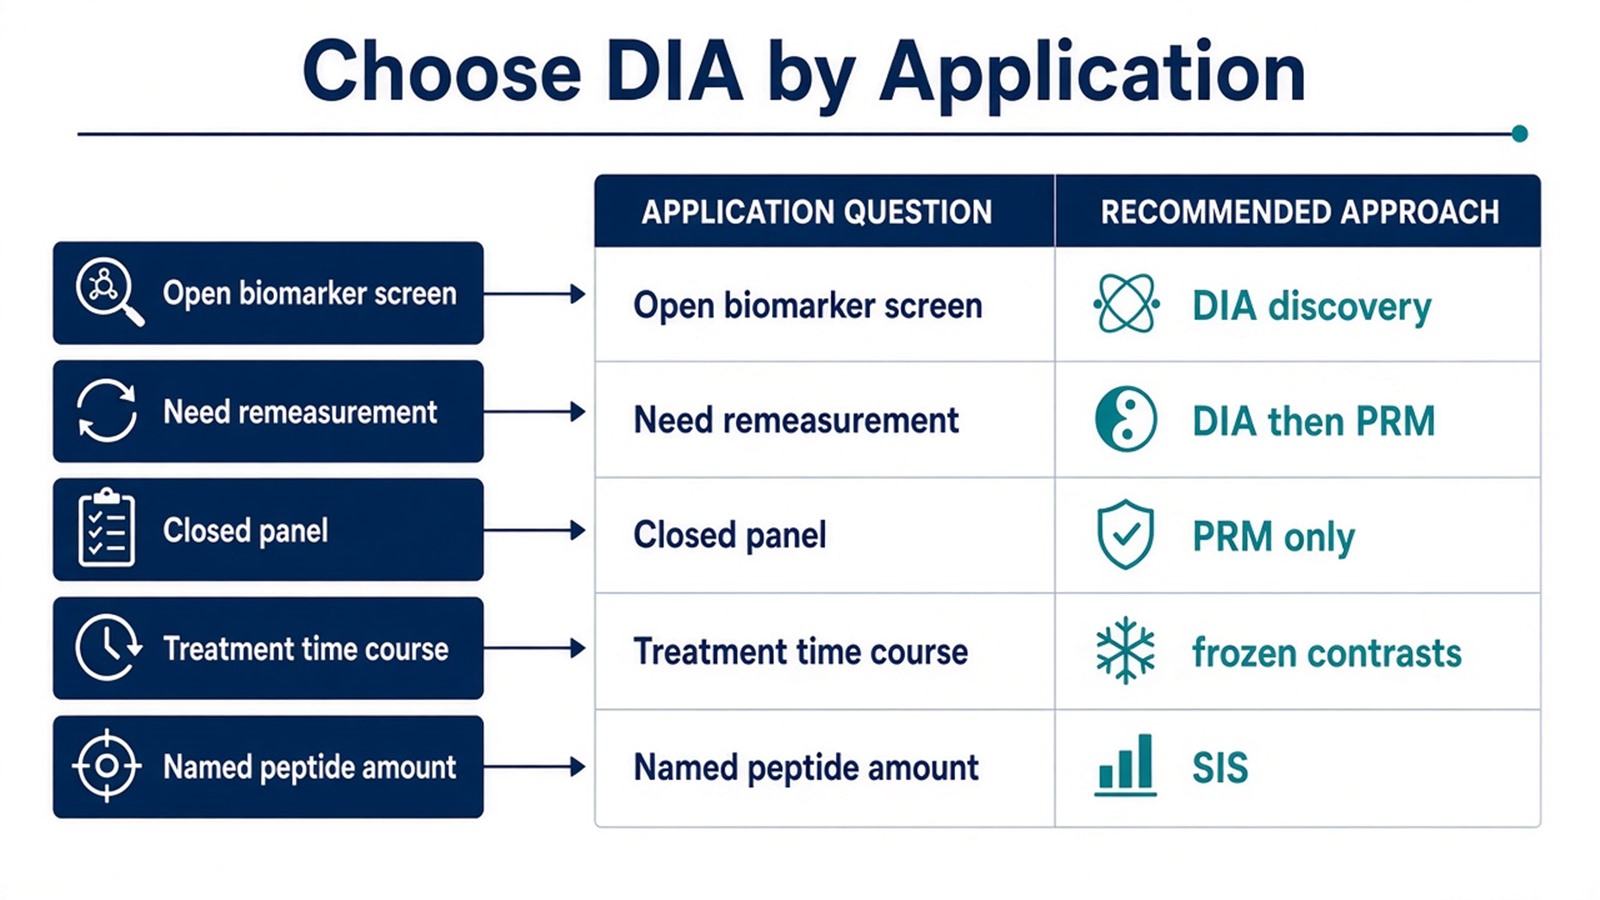
Figure 2. Choose DIA when the application needs an open relative matrix on matched prep; validation and amount claims need targeted or SIS designs.
Three-axis route selection appears in Protein Quantification Method. Sample readiness checks appear in Exploring Quantitative Analysis in Proteomics.
Teams with application pattern, contrast design, and follow-up intent can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for DIA application alignment.
Frequently Asked Questions
1. Is DIA biomarker validation the same as DIA discovery?
No. Discovery is an open list for a predefined contrast. Validation needs PRM, SIS, or independent cohort design on narrowed targets.
2. Does DIA alone identify drug targets?
No. DIA supplies relative abundance contrasts for declared arms. Target claims need orthogonal evidence and study-specific validation.
3. Is multi-omics integration a DIA acquisition step?
No. Omics overlay interprets a tested protein list after extraction QC. It is not part of windowed MS/MS acquisition.
4. Must applications use SWATH windows?
No. SWATH is one DIA window plan. Other tiled window layouts may fit after matrix pilot lock.
5. When should large cohorts avoid DIA?
When the peptide list is already closed and small, targeted monitoring without rediscovery may fit better than a full DIA campaign.
MtoZ Biolabs can discuss DIA application planning when contrast design, matrix pilots, and follow-up goals are documented.
If further evaluation of pattern fit, DIA-PRM staging, or discovery-to-targeted handoff is needed, project details can be submitted for a feasibility review.
Reference
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, H. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- V. Demichev, C. Messner, S. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- G. Rosenberger, S. Liu, J. Röst, H.L. Ludwig, C. Buil, B. Borchers, R. Aebersold, L. Collins (2017). Statistical control of peptide and protein error rates in large-scale targeted data-independent acquisition analyses. Nat. Commun., 8, 14224. https://doi.org/10.1038/ncomms14224
