



Data-independent acquisition (DIA) advantages in protein quantification are scheduled-window fragment coverage, often fewer stochastic missing values than data-dependent acquisition (DDA), and later re-extraction of stored fragment chromatograms. Disadvantages are chimeric MS2 interference, dependence on a spectral library or library-free search settings, heavier software and compute load, and relative-only intensities unless matched standards are added. SWATH-MS is one sequential-window DIA implementation, usually library-based, not a third method class that removes those limits (Gillet et al. 2012). Choose DIA when unlabeled relative discovery needs cohort completeness and window QC can be enforced. Keep DDA, tandem mass tag (TMT) multiplex, or parallel reaction monitoring (PRM) when identification, closed labeling, or a locked peptide panel is the claim.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Deep DIA Proteomics Service and Label-Free Quantitative Proteomics Service for project-specific feasibility and analysis planning.
Advantages and Disadvantages at a Glance
Topic |
DIA advantage when controls hold |
Matching disadvantage |
|---|---|---|
Coverage |
Scheduled windows can recover peptides missed by stochastic top-N DDA picks |
Window multiplexing mixes fragments and can hide low-quality peaks |
Missing values |
Often more complete relative matrices across a cohort |
Completeness is not the same as accuracy |
Reproducibility |
Fixed acquisition logic supports run-to-run consistency |
Chromatography, run order, and batch drift still move intensities |
Data reuse |
Stored fragment evidence can be re-extracted under updated libraries or searches |
Re-analysis inherits library gaps and FDR assumptions |
Quantitative claim |
Relative same-protein discovery at scale |
Absolute concentration needs SIS and calibration |
Analysis |
Library-based SWATH-style or library-free DIA is available |
Specialized software, compute, and interference filters are required |
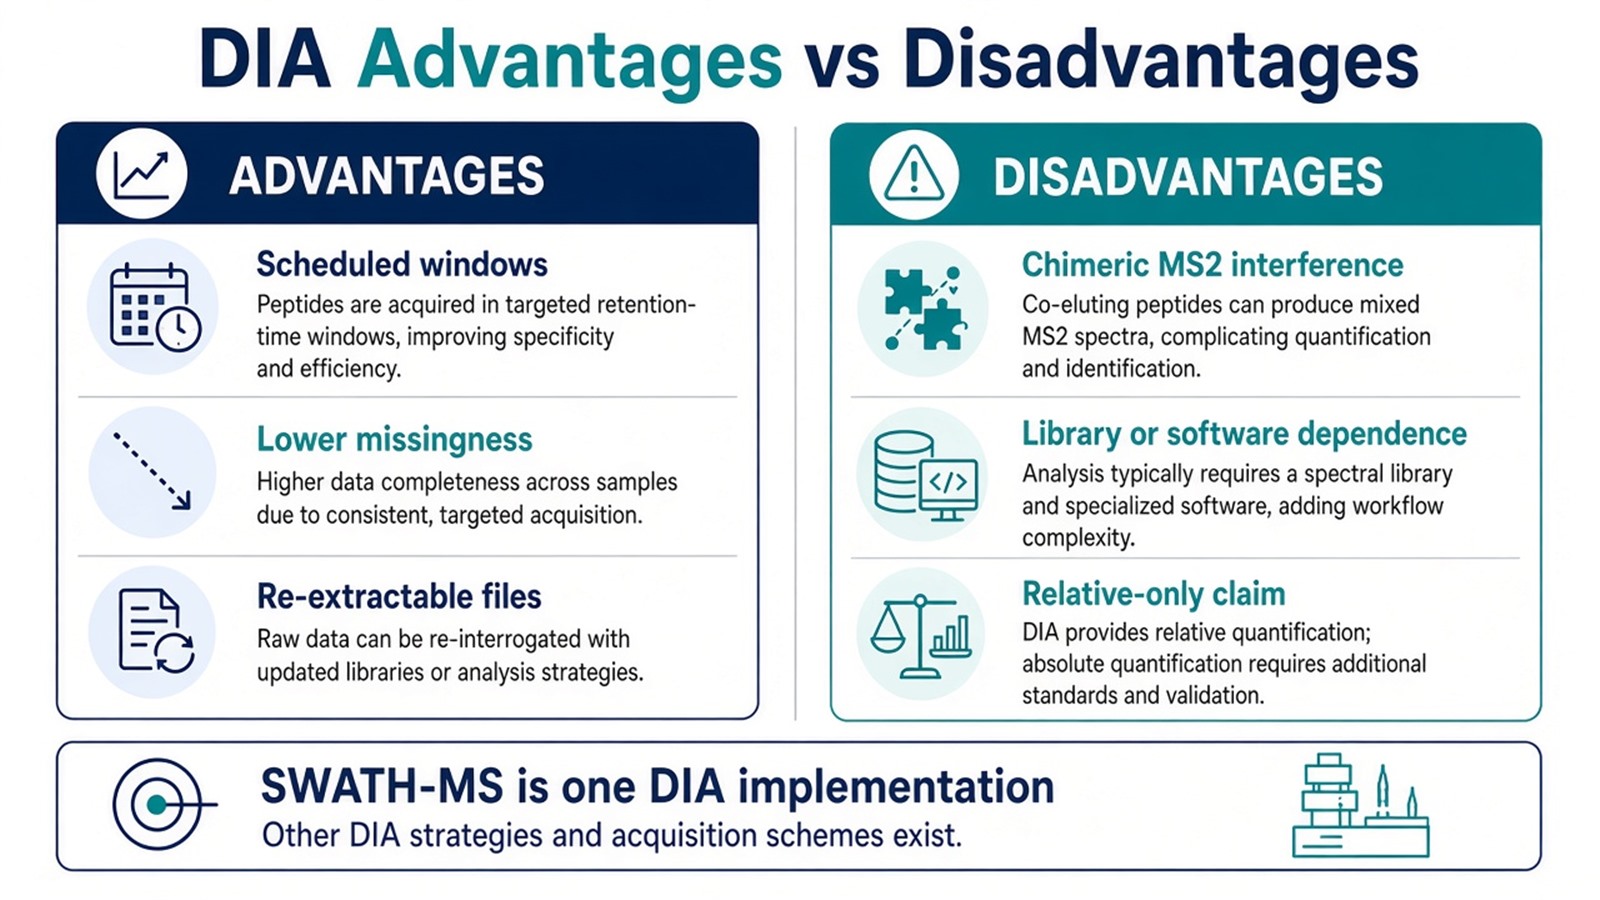
Figure 1. DIA advantages and disadvantages arise from the same design: scheduled windows improve relative completeness while raising interference and analysis cost.
A more complete DIA matrix is still a relative matrix. It is not proof of interference-free peaks or absolute amount.
How DIA and SWATH Create Those Trade-Offs
DIA divides the precursor m/z range into isolation windows and fragments ions in each window on a fixed schedule. Peptide quantities usually come from extracted fragment-ion chromatograms rather than only from precursors that happened to be chosen as top peaks. That is why missing-value control can improve in unlabeled liquid chromatography-tandem mass spectrometry (LC-MS/MS) cohorts.
SWATH-MS applies the same class as consecutive windows and typically extracts transitions against a spectral library that stores peptide identity, fragments, and retention-time information (Gillet et al. 2012). Library-free or Direct DIA routes still use scheduled-window acquisition; they change extraction strategy, not the definition of DIA (Demichev et al. 2020). Naming SWATH does not specify vendor, window width, gradient, or labeling chemistry.
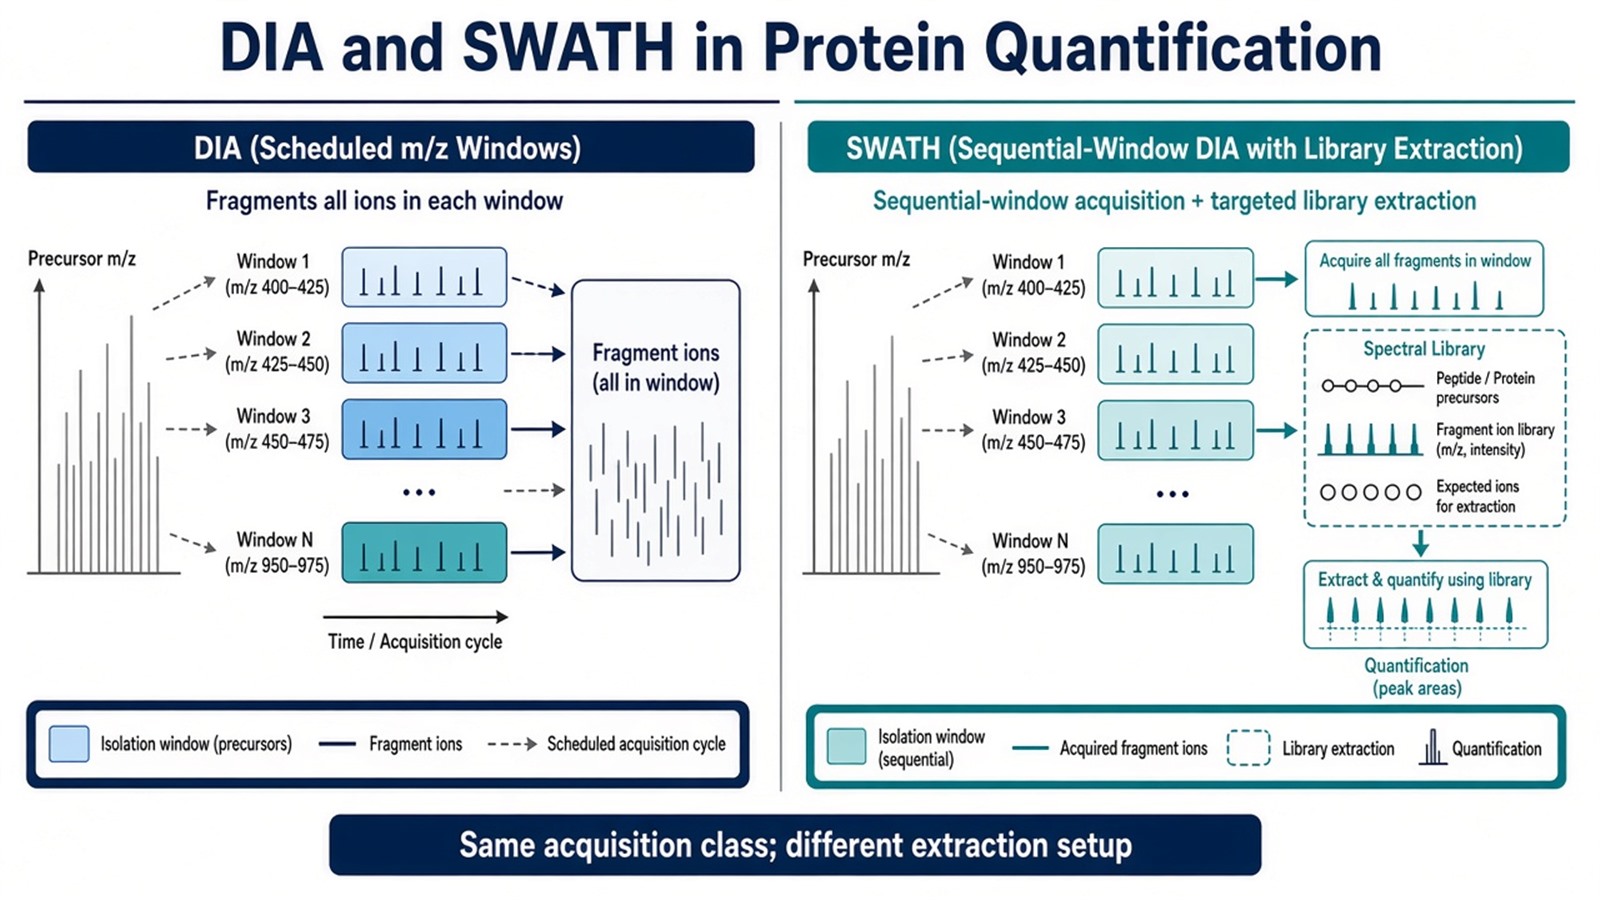
Figure 2. DIA is the acquisition class; SWATH-MS is one sequential-window implementation, commonly paired with library extraction.
For definitions of DIA versus SWATH beyond this advantages page, researchers can refer to What Is DIA and SWATH? Understanding Data-Independent Acquisition in Proteomics?. For a paired strengths-and-limits treatment, see Strengths and Limitations of DIA in Protein Quantification. For acquisition choice against DDA, see DIA vs DDA Proteomics: Key Differences and Applications Explained.
Judgment Criteria: When Advantages Outweigh Disadvantages
Study need |
DIA / SWATH-style often worth the trade-off |
Reassess before committing |
|---|---|---|
Claim |
Relative unlabeled discovery across many runs |
Absolute units or diagnostic cutoff |
Missing-value risk |
Stochastic DDA gaps would dominate statistics |
Simple matrix where DDA depth already suffices |
Library logistics |
Matched library available, or library-free DIA planned |
Unmatched library with no library-free path |
Interference tolerance |
Window design, chromatography, and peak-group QC can be enforced |
Severe chimeric interference expected without mitigation |
Panel status |
Open discovery inventory still needed |
Closed shortlist ready for PRM or MRM |
Analysis capacity |
DIA software, FDR rules, and compute are in place |
No declared extraction pipeline or QC |
Prefer DIA when scheduled-window completeness is the scarce resource for relative discovery. Prefer a SWATH-style library workflow when a matched spectral library is part of the plan. Prefer Direct DIA when empirical library construction is the bottleneck. Prefer DDA when cleaner single-precursor MS2 or library building comes first. Prefer PRM or MRM when targets are already closed.
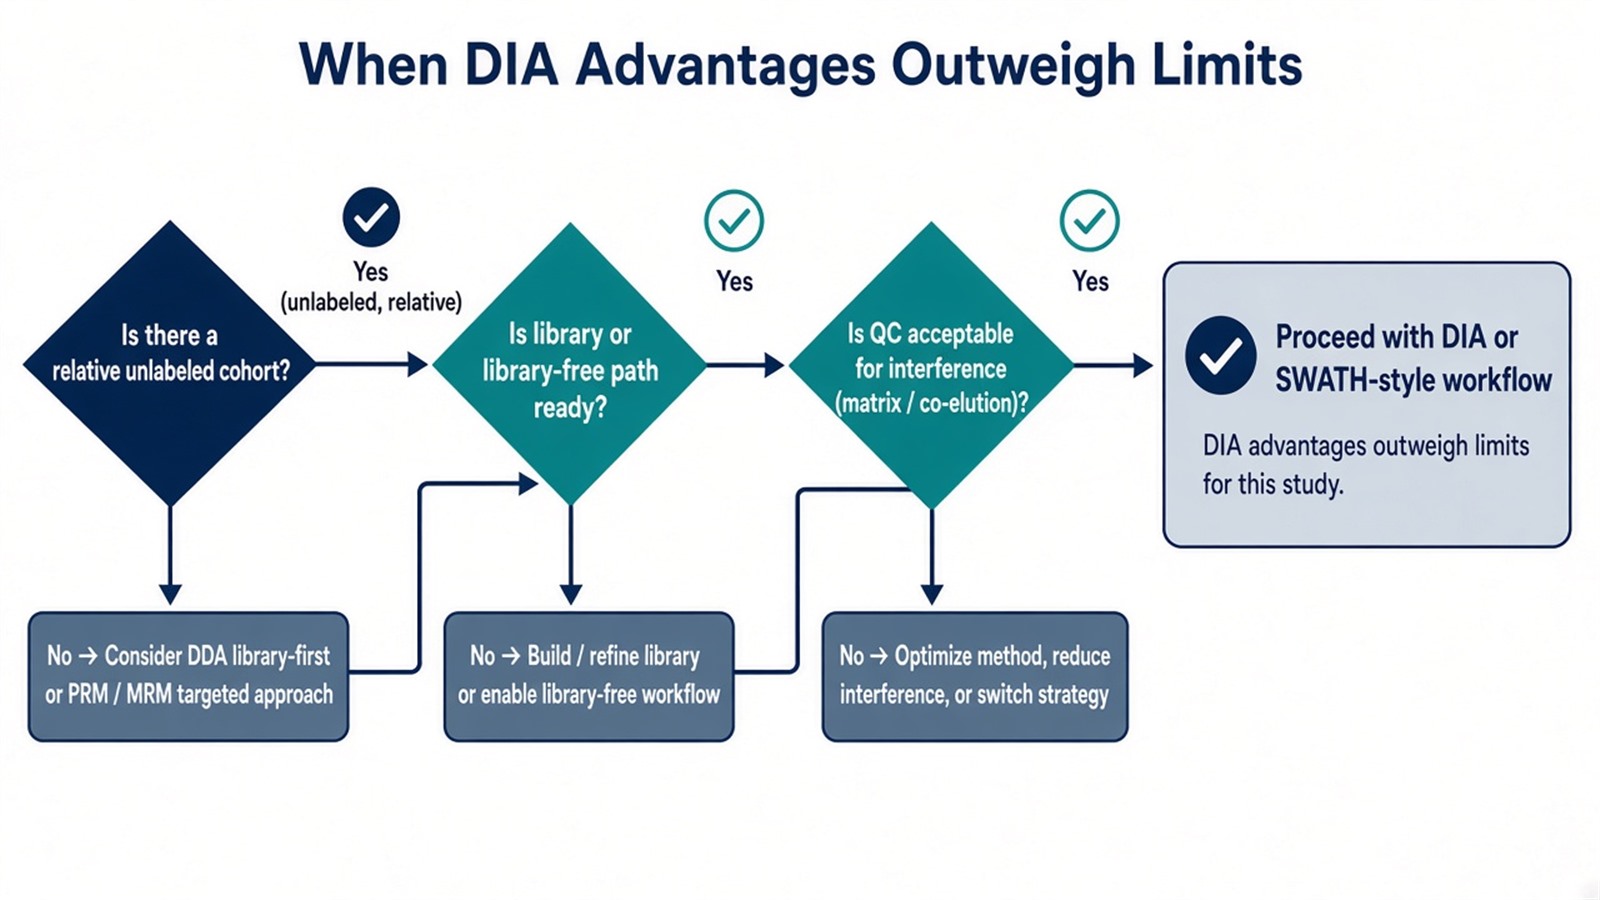
Figure 3. Accept DIA disadvantages only when the relative cohort claim and library or library-free path can absorb window interference and analysis cost.
For DDA versus DIA inside label-free stacks, see DIA vs. DDA in Label-Free Quantitative Proteomics: A Comparative Analysis. For library-free extraction, see Direct DIA: High-Efficiency Proteomics without a Spectral Library. For analysis tooling, see Essential Analysis Tools for Label-Free Proteomics: A Comprehensive Review of MaxQuant and DIA-NN.
Limits, SWATH Notes, and Applications
DIA does not fragment every possible peptide without interference. Wide windows, poor chromatography, and undeclared FDR filters convert the completeness advantage into noisy ratios. SWATH-style library extraction cannot recover peptides absent from the library. Unmatched libraries transfer tissue or batch bias into the matrix. Ordinary DIA intensities remain relative unless stable isotope-labeled standards (SIS) and a calibration model are added.
Typical applications:
- Unlabeled treatment, genotype, or time-course screens that need consistent fragment coverage across many independent injections.
- Complex-matrix relative discovery where DDA missingness would dominate later statistics.
- Projects that may reprocess stored DIA files under updated libraries or search settings.
- Discovery followed by PRM or MRM confirmation of a closed shortlist.
Diagnostic cutoffs, companion-diagnostic claims, and absolute stoichiometry sit outside ordinary research DIA reporting unless a separately validated assay framework is in place. Fixed protein-count or CV promises without matrix, window scheme, and filter details overstate method class alone.
Once the relative claim, SWATH-style library or library-free route, and interference controls are defined, the project can be evaluated as a DIA quantification study. Researchers can review the MtoZ Biolabs Deep DIA Proteomics Service for sample evaluation, feasibility assessment, and workflow planning. For analysis pitfalls after acquisition, see Common Pitfalls in DIA Proteomics Data Analysis and How to Avoid Them. For closed-panel follow-up, see PRM and MRM in Targeted Proteomics: Advantages and Limitations.
Frequently Asked Questions
1. Does DIA quantify all peptides in a sample?
No. Scheduled windows record mixed fragment evidence. Peptides can still be missed, interfered, or filtered by FDR.
2. Is SWATH better than DIA for quantification?
SWATH-MS is a DIA implementation, not a higher class. Advantages and disadvantages follow window design, library quality, and QC, not the SWATH name alone.
3. Is lower missingness the same as higher accuracy?
No. DIA can fill matrices more consistently and still quantify interfered transitions incorrectly. Accuracy needs peak-group QC.
4. Can DIA replace TMT or AQUA?
Not as a drop-in. TMT answers closed multiplex labeling. AQUA answers calibrated amount for named peptides. DIA answers relative unlabeled discovery when the plan fits.
5. When should a project keep DDA instead of DIA?
Keep DDA when identification-first spectra, MaxLFQ-centered files, or a matched DDA library for later DIA are the priority.
Reference
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
