



The workflow of pull-down coupled with mass spectrometry (MS) for protein identification is six laboratory steps that turn a ligand bead into a judged peptide table: design and sample preparation, pull-down, elution or on-bead collection, digestion, LC-MS/MS, and enrichment against an empty-handle arm. The ligand can be a tagged fusion, a biotinylated compound, or a nucleic acid. Antibody capture is immunoprecipitation and follows a different control. This workflow identifies proteins present in the eluate. It does not, by itself, report a protein–protein interaction, a binding constant, or a biological process. The useful first decision is whether the empty-handle, linker-only, or bead-only arm will be processed with the same prey and the same wash. Adding that arm after a single bait digest cannot reconstruct the background.
Mascot, MaxQuant, or another search engine names accessions. They do not decide which accessions are partners. For what those names mean before this sequence is run, Identification of Protein Interactions Using Pull-Down and Mass Spectrometry provides a complementary identification discussion.
Researchers who already have a ligand, an empty-handle plan, and an identification question can also review the MtoZ Biolabs Pull Down based Protein Analysis Service with Mass Spectrometry for project-specific feasibility and analysis planning.
Why These Six Steps Are Kept
The original page names design, pull-down, elution, digestion, MS, and interpretation. That order is the identification workflow. It is not the four-step GST bench procedure, and it is not the fusion-only coupling argument. For GST wet capture without the MS steps, What Is the General Procedure for GST Pull-Down Analysis of Protein–Protein Interactions? provides a complementary GST procedure. For when this workflow is the right identification method, Advantages and Disadvantages of Pull-Down Coupled with MS for Protein Identification provides a complementary decision.
Experimental Design and Sample Preparation
Write the ligand class, the empty-handle arm, the prey source, and the claim that will be allowed, before the first lysis. A glutathione S-transferase (GST) tag is one handle, not the default. His, Strep, biotin, and nucleic-acid ligands need their own resins and their own empty arms.
The bait fusion, if used, is expressed and immobilized. The prey is a purified protein or a lysate that may come from a different host. A lysate “containing the target protein” is not automatically the bait feed. Input protein is matched across arms. For ligand classes, Affinity Pull-Down Assay provides a complementary ligand-class discussion.
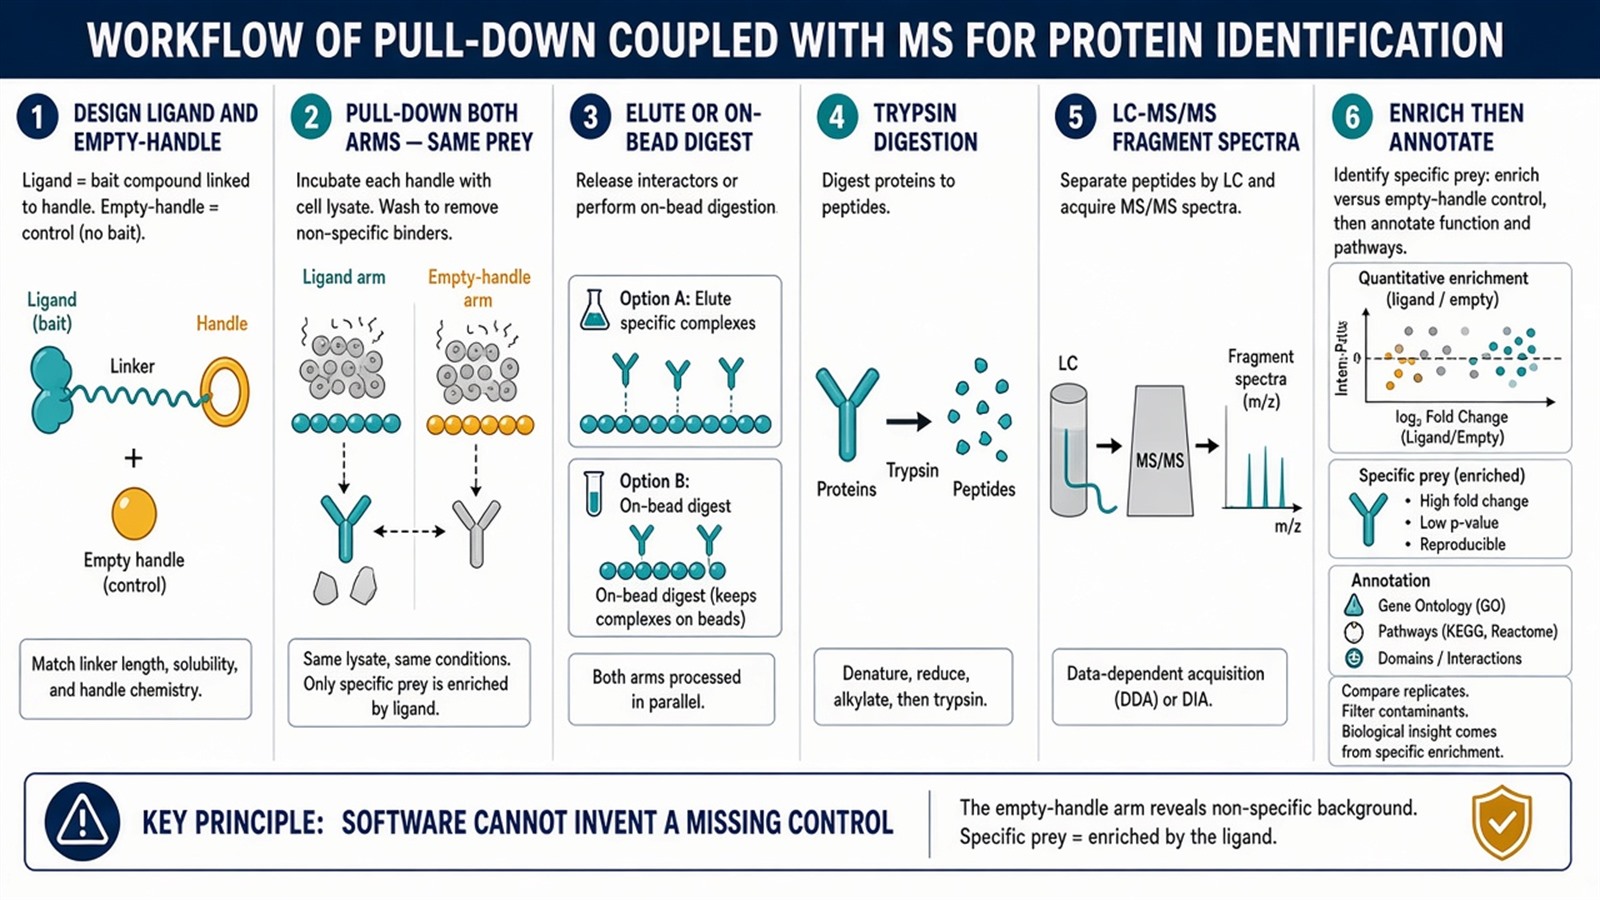
Figure 1. Design, capture, elution or on-bead digest, LC-MS/MS, then enrichment. The empty-handle arm travels through every step. Software cannot invent it later.
Name the empty-handle arm in the design paragraph. A later MaxQuant search cannot reconstruct a digest that was never run.
Pull-Down Reaction
Both bead arms receive the same prey. Incubation time and temperature are written once. Washing is a kinetic filter. Rigorous washing does not ensure that only specific partners remain. It reduces some resin binders and also strips weak true contacts. Fine-tuning the wash is a trade-off, not a specificity guarantee.
Elution and Collection
Competitive ligand, acid, or detergent reverses the handle or denatures the assembly. Both exits release a mixture. On-bead digestion is an alternative when elution is incomplete. Ligand and empty-handle must use the same exit. The collected material is not yet an interacting complex. It is the input to digestion.
Protein Digestion
The eluate, or the washed beads, is concentrated if needed, then reduced, alkylated, and cut, commonly with trypsin. Cleanup improves peptide recovery when trap capacity matches the load. It does not rescue an unmatched pull-down.
Mass Spectrometry Analysis
Peptides are separated by liquid chromatography and measured by tandem MS. Sequence assignment comes from fragment spectra. Parent mass-to-charge peaks are not identifications. Quantification, if acquired, is occupancy after wash. The instrument name does not decide which rows are ligand-dependent. For the GST-specific five-step coupling after this general order, GST Pull-Down Assay Combined with Mass Spectrometry for Protein-Protein Interaction Analysis provides a complementary GST–MS page.
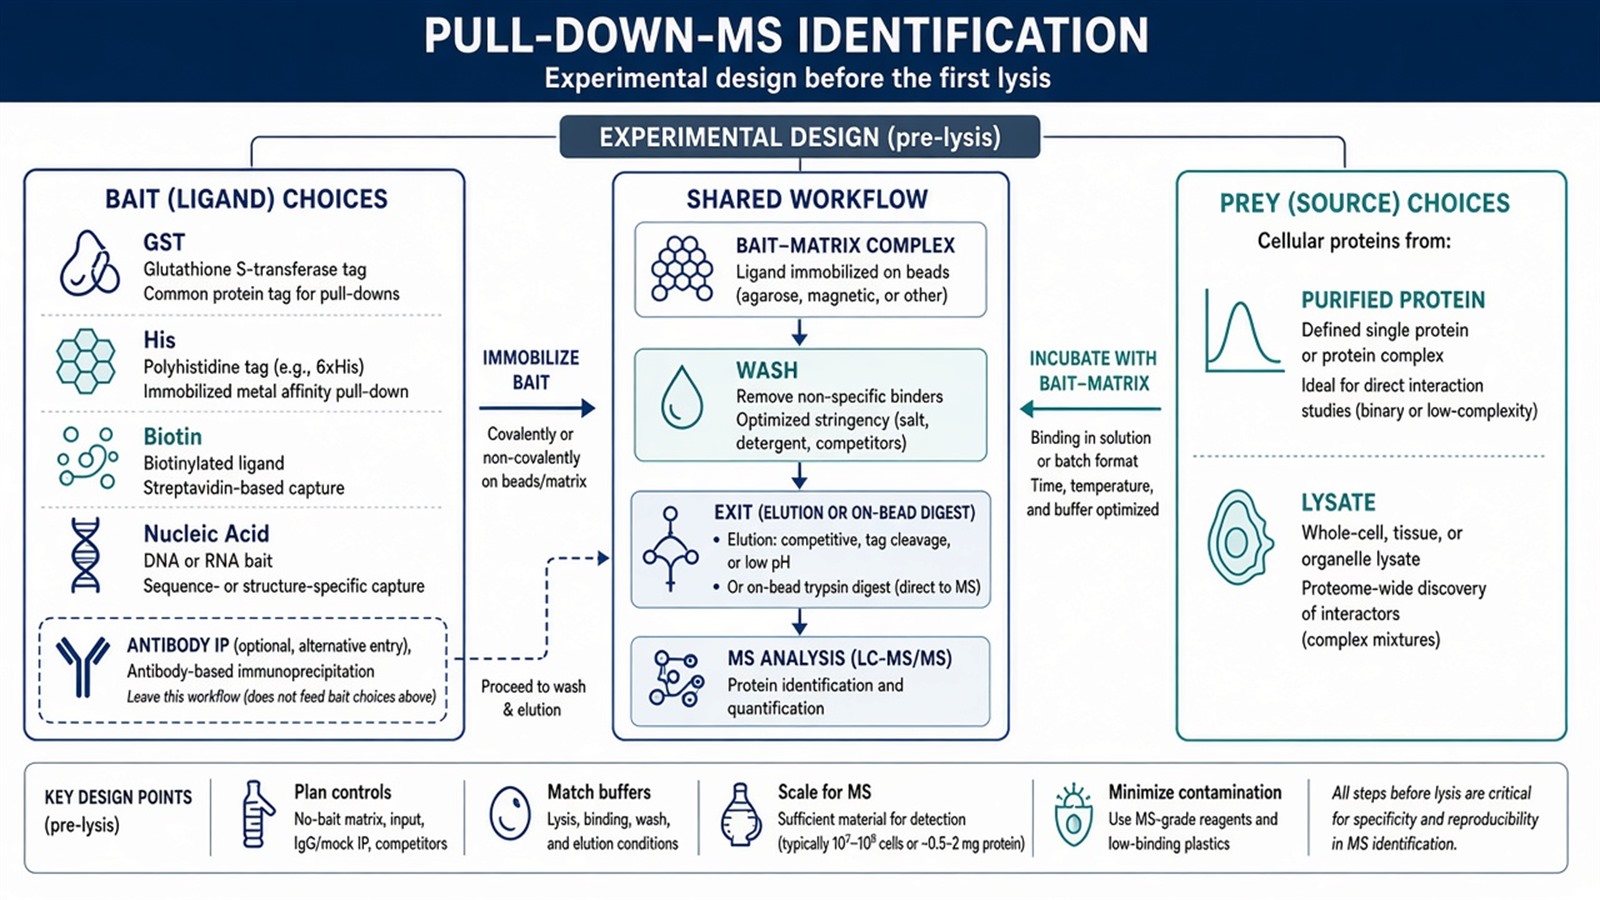
Figure 2. GST, His, biotin, or nucleic acid can be the ligand. Prey can be a purified protein or a lysate. Antibody resins leave this workflow and become IP.
Data Analysis and Result Interpretation
Search software matches spectra to a protein database. That step produces potential names, not interacting proteins.
Each row is first asked whether the ligand or bait was recovered and whether the candidate is enriched against the empty-handle arm. Subtracting every empty-handle identification deletes real partners that leak into the handle arm. Annotation of biological roles comes last. For how to read the blot or the table after these steps, How to Interpret the Results of a Pull-Down Experiment provides a complementary interpretation order.
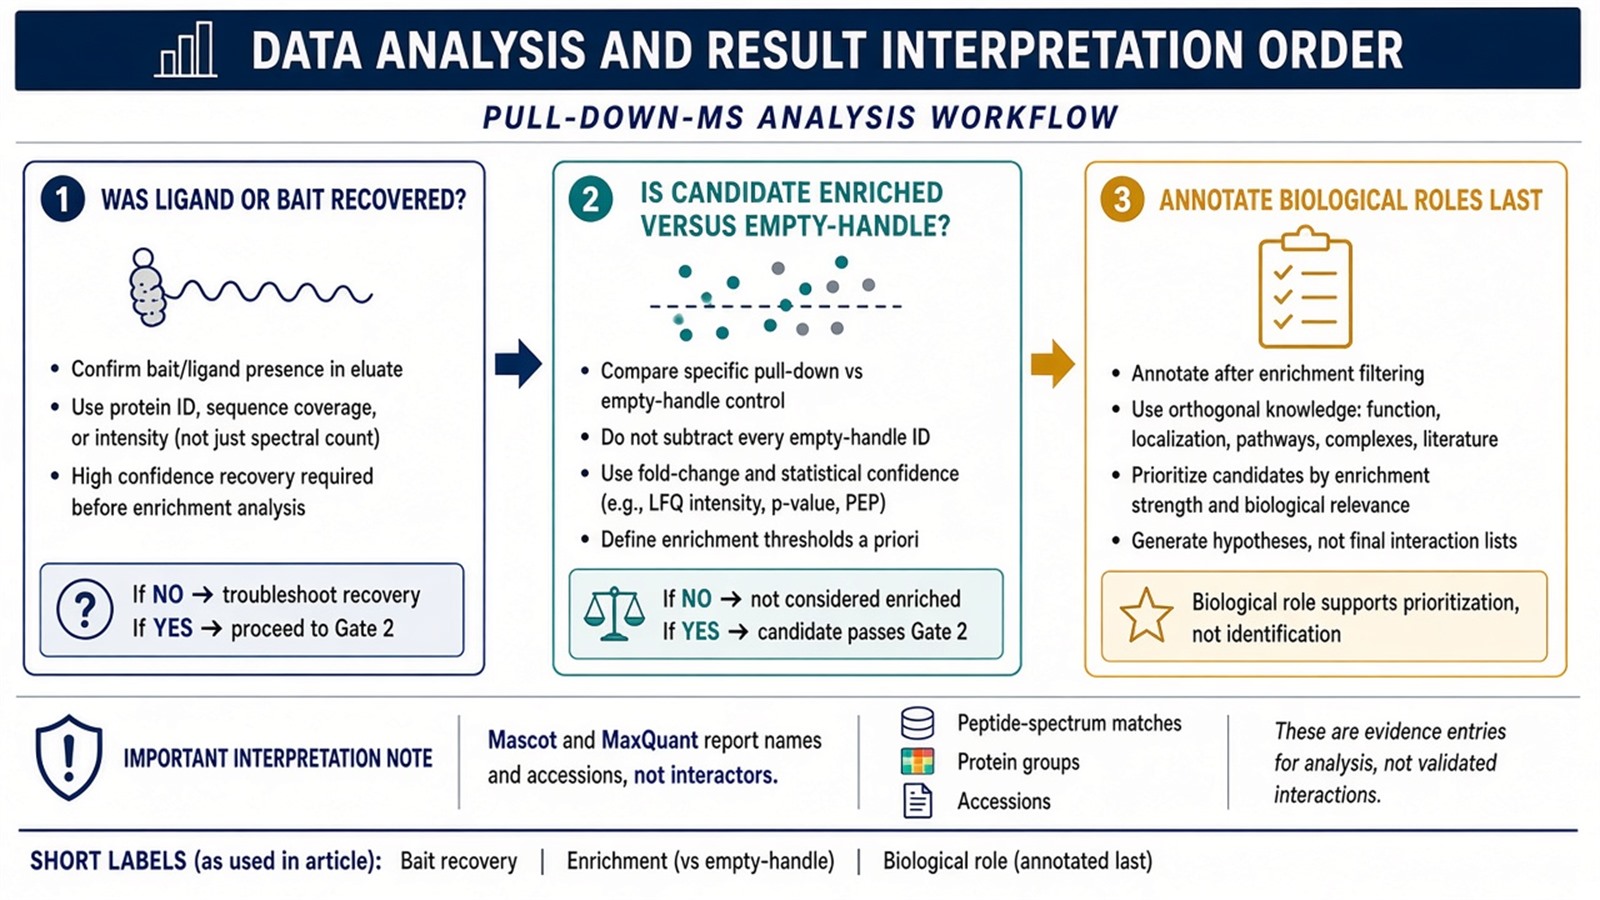
Figure 3. Mascot or MaxQuant names accessions. Interaction language waits for enrichment. Pathway sentences are not a sixth wet-lab step.
Experimental Limits
The workflow reduces a mixture to what the ligand, the wash, and the search engine can report. A comprehensive understanding of protein–protein interactions is a later overlay. Diagnostic language sits outside ordinary research reporting unless a separately validated assay framework is in place.
Project Planning and Service Scope
A usable workflow plan names the six steps, the empty-handle arm, the elution or on-bead route, and the claim that will be allowed, before the first induction. MtoZ Biolabs scopes pull-down with Western or Orbitrap-class LC-MS/MS. Interpretability still follows those steps, not the software brand.
Once the ligand is specified as GST, the wet capture can be scoped as GST pull-down. Researchers who need a GST-bait plan before identification can review the MtoZ Biolabs GST Pull Down Assay Service for project-specific sample evaluation, feasibility assessment, and workflow planning.
Frequently Asked Questions
1. What is the workflow of pull-down plus MS for identification?
Design both arms, capture and wash, elute or digest on-bead, run LC-MS/MS, then enrich against the empty-handle before annotation.
2. Must the bait be a GST fusion?
No. GST is one handle. His, Strep, biotin, and nucleic-acid ligands follow the same six steps with their own resins.
3. Does a rigorous wash leave only specific partners?
No. Washing is a kinetic filter. Specificity is the empty-handle comparison.
4. Can Mascot or MaxQuant determine who interacts with the target?
They identify peptides. Interaction language requires enrichment against the empty-handle arm.
5. How does this page differ from the GST procedure and GST–MS pages?
This page is the identification sequence across ligand classes. The GST procedure page stops at the wet capture. The GST–MS page is the five-step GST coupling.
Reference
- Gingras A.C., Gstaiger M., Raught B., Aebersold R. (2007). Analysis of protein complexes using mass spectrometry. Nat. Rev. Mol. Cell Biol., 8, 645-654. https://doi.org/10.1038/nrm2208
- Dunham W.H., Mullin M., Gingras A.C. (2012). Affinity-purification coupled to mass spectrometry: basic principles and strategies. Proteomics, 12, 1576-1590. https://doi.org/10.1002/pmic.201100523
- Mellacheruvu D., Wright Z., Couzens A.L., et al. (2013). The CRAPome: a contaminant repository for affinity purification-mass spectrometry data. Nat. Methods, 10, 730-736. https://doi.org/10.1038/nmeth.2557
- Cox J., Mann M. (2008). MaxQuant enables high peptide identification rates, individualized p.p.b.-range mass accuracies and proteome-wide protein quantification. Nat. Biotechnol., 26, 1367-1372. https://doi.org/10.1038/nbt.1511
- Perkins D.N., Pappin D.J., Creasy D.M., Cottrell J.S. (1999). Probability-based protein identification by searching sequence databases using mass spectrometry data. Electrophoresis, 20, 3551-3567. https://doi.org/10.1002/(SICI)1522-2683(19991201)20:18<3551::AID-ELPS3551>3.0.CO;2-2
