Quantitative Analysis of Proteins by Liquid Chromatography
Quantitative analysis of proteins by liquid chromatography in proteomics practice means peptides from a matched digest are separated on a reversed-phase column and quantified by liquid chromatography-tandem mass spectrometry (LC-MS/MS), not by a standalone high-performance liquid chromatography (HPLC) trace alone (Bantscheff et al. 2012). Chromatography stability and injection-ready peptide loads decide whether later label-free, isobaric, or targeted signals stay comparable across runs. The guide below focuses on sample pretreatment through the LC injection point. It is not a disease-application catalog, not a column catalog, and not a detector marketing page.
Pretreatment still has to match the planned labeling and acquisition route. Unlabeled digests can be acquired as data-dependent acquisition (DDA) or data-independent acquisition (DIA). Isobaric tandem mass tag (TMT) work needs amine-compatible peptides before channel mixing. Named proteins followed by parallel reaction monitoring (PRM) or multiple reaction monitoring (MRM) need clean digests that schedule reliably. In MtoZ Biolabs offerings, unlabeled discovery is commonly run as DDA label-free or DIA, multiplexed isobaric work is typically evaluated as TMT, and closed lists are typically followed by PRM, with MRM when a scheduled triple-quadrupole panel already exists.
Sample Inputs That Must Be LC-Ready Before Quantification
Common quantitative inputs include cultured cells, tissues, plasma or serum, and purified fractions. Each matrix changes how much material is extracted, how aggressively detergents must be removed, and how much peptide can be loaded without suppressing the column or the mass spectrometer.
Cells and tissues usually move through lysis, reduction, alkylation, and trypsin digestion under one declared chemistry. Plasma and serum often need depletion or fractionation before deep discovery, and cleanup must stay equal across groups. Purified fractions can reach LC faster but still need desalting and solvent exchange before injection.
LC-based protein quantification starts when digests are clean, desalted, and loaded in a matched solvent, not when raw lysate reaches the autosampler.
Bulk Bradford, bicinchoninic acid (BCA), Lowry, and 280 nm assays help match total protein before digestion. They do not replace peptide-level quantification after chromatography and extraction.
Pretreatment That Protects Chromatography and Cross-Run Comparability
Quantitative LC-MS depends on matched pretreatment more than on a single aggressive extraction recipe.
Detergent and salt removal. Chaotropes, detergents, and high salt left in the digest suppress peptide ionization and distort retention. Filter-aided or solid-phase cleanup helps produce LC-compatible peptides (Wisniewski et al. 2009; Rappsilber et al. 2007).
Digestion completeness. Missed cleavages that track groups look like treatment effects after alignment. Shared enzyme-to-substrate rules and time windows keep peptide stoichiometry stable before the first injection.
Desalting and resuspension. Peptides are often loaded in aqueous acid with a small fraction of organic solvent compatible with the first gradient step. Unequal dry-down recovery between groups creates intensity offsets that normalization cannot always fix.
Optional labeling and stable isotope-labeled internal standard (SIS) timing. TMT labels free amines after digestion, so amine carryover in buffers competes with tagging. SIS amount claims need a declared spike point relative to cleanup (Gerber et al. 2003).
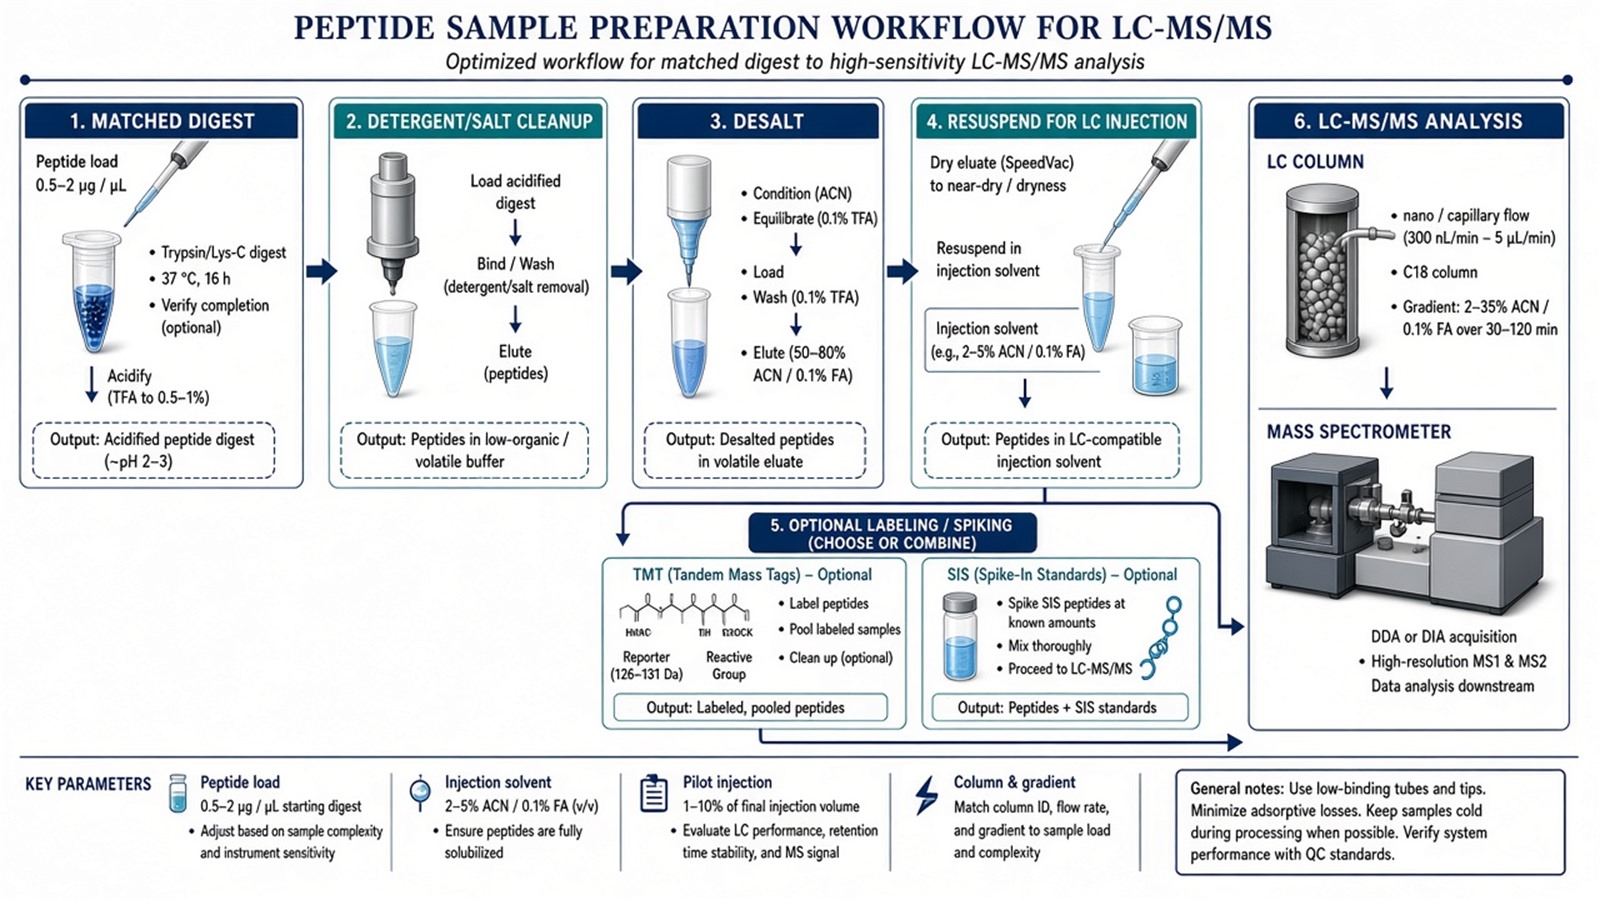
Figure 1. Quantitative LC-MS pretreatment ends at a matched peptide injection; column stability carries comparability into acquisition.
Researchers who need the full lysis-to-digest chemistry spine can refer to Quantitative Protein Analysis.
Shared Workflow From Sample Receipt to LC Injection
A practical spine for LC-quantitative work usually runs as follows.
- Confirm matrix, group map, and relative versus SIS amount claim.
- Aliquot matched input after a load assay, then lyse and digest under shared rules.
- Clean peptides to remove detergents, salts, and lipids that harm LC.
- Desalt and resuspend in injection-compatible solvent at a declared peptide load.
- Add TMT channels or SIS only when the design requires them.
- Run a pilot injection to check retention and signal before the full cohort block.
Where cohorts diverge still matters. Unlabeled designs keep each digest on its own injection path after pretreatment. TMT mixes labeled digests after labeling. Targeted designs freeze peptides before scheduling, but cleanup quality must match discovery digests.
Order errors show up on the column first. Overloaded injections broaden peaks and saturate the detector. Under-loaded pilot failures tempt unequal re-injection. Treatment-confounded prep batches create retention-aligned artifacts in label-free matrices (Cox et al. 2014).
Acquisition mode and data extraction sit after LC. Researchers can refer to A Guide to Label-Free Quantitative Proteomics: From Experiment to Data Analysis when the remaining question is alignment after unlabeled LC-MS runs.
Parameters and Limits at the LC Handoff
Parameter |
Why it matters before LC |
Failure mode if ignored |
|---|---|---|
Matched peptide load per injection |
Keeps peak areas comparable |
Saturation or weak signals by group |
Cleanup recovery across groups |
Limits prep-specific losses |
Systematic missingness by treatment |
Solvent composition at injection |
Anchors retention time |
Fronting peaks and unstable alignment |
Column age and batch plan |
Stabilizes retention across runs |
Apparent shifts that mimic biology |
Digestion and labeling completeness |
Stabilizes peptide stoichiometry |
Missed cleavages or soft TMT reporters |
SIS spike timing |
Supports amount claims |
Relative peaks read as concentration |
Limits follow the same table. Standalone HPLC with ultraviolet detection can size or purity-check some protein preparations. It does not by itself return a defensible proteome-wide quantitative matrix. Ultra-high-performance liquid chromatography (UHPLC) narrow peaks help throughput when gradients and loads stay matched. They do not replace explicit normalization and missing-value rules after acquisition.
Missing values often begin as prep or LC dropout at low abundance, not only as identification chance (Lazar et al. 2016). Pathway enrichment cannot repair unequal cleanup recovery or injections that were not matched.
Researchers who need signal-type definitions after pretreatment is fixed can refer to What Are the Quantitative Methods for Proteomics?.
Choosing Pretreatment for LC-Based Quantitative Projects
Use matrix, mixability, and claim unit to choose the pretreatment and LC plan.
Project need |
Pretreatment and LC plan that often fits |
Recheck before committing |
|---|---|---|
Open cohort, cells or tissue |
Matched cleanup, desalt, unlabeled injections |
Run order identical to treatment |
Freezable multi-group set |
Matched digest, TMT labeling, mixed LC path |
Amine carryover; late unlabeled files |
Plasma or serum discovery |
Equal depletion plus matched cleanup before LC |
Depletion on only one group |
Named peptides to remeasure |
Clean digest, targeted schedule, stable load |
Panel longer than one duty cycle |
Mass or molar unit required |
Matched digest, SIS, calibration before cohort LC |
Spike after incomplete cleanup |
Only intact protein purity check |
HPLC-UV or size route |
Not peptide-level LC-MS quantification |
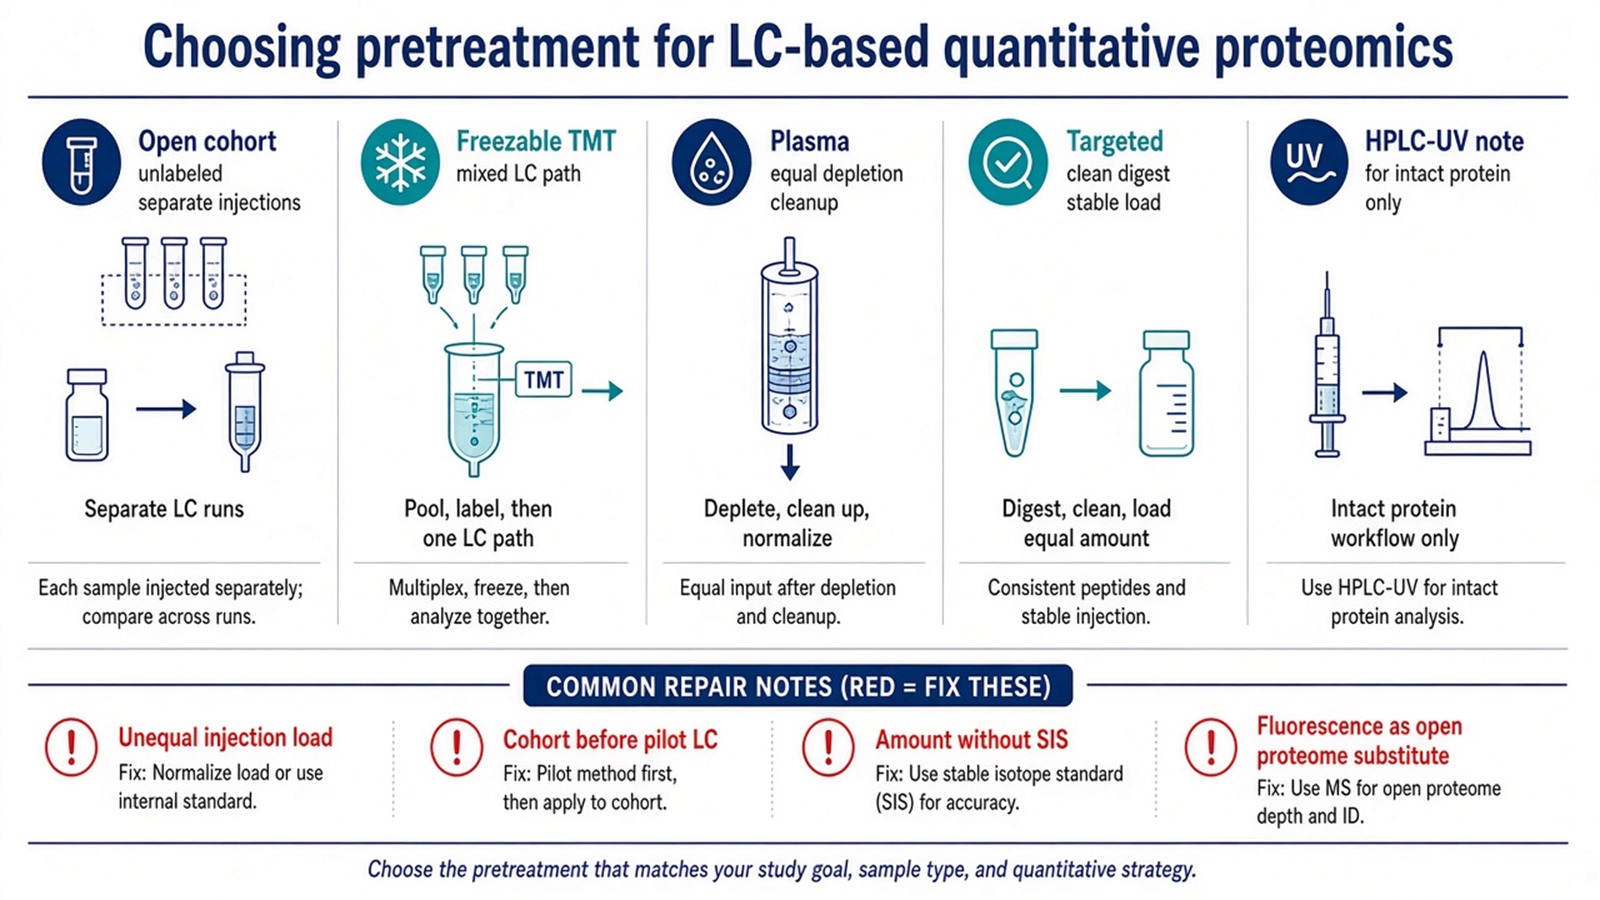
Figure 2. Choose cleanup and injection plans from matrix and claim unit; unequal loads, amine interference, and amount-without-SIS requests need repair before LC batches.
Unlabeled pretreatment more often fits open enrollment with separate injections. TMT pretreatment more often fits a freezable set after amine cleanup. Targeted confirmation more often fits after names freeze. Exceptions exist when a short closed cohort must share one LC method to limit run-order drift.
Researchers who need labeling-versus-acquisition selection after the LC handoff plan is clear can refer to Protein Quantification Method. Teams that already have matrix, group design, and a requested claim can also review the MtoZ Biolabs Quantitative Proteomics Service for project-specific pretreatment and LC planning.
Frequently Asked Questions
1. Is HPLC-UV alone enough for quantitative proteomics?
No. HPLC-UV can support some intact protein or purity workflows. Proteome-wide quantitative claims need peptide-level LC-MS/MS with declared extraction and contrast rules.
2. Does a better column replace matched peptide loads?
No. Column quality helps separation when loads and gradients stay matched. Unequal injection amounts still break cross-run comparability.
3. When should a pilot LC injection run before the cohort?
When the matrix, cleanup recipe, or load is new. Full-batch injection before a pilot often forces repeat digestion or unequal re-injection.
4. Do unlabeled and TMT projects share the same LC pretreatment spine?
They share cleanup, desalting, and load-matching principles. TMT adds amine-compatible labeling and mixing before the shared LC path. Unlabeled designs keep digests on separate injections.
5. Can fluorescence detection replace LC-MS for many proteins?
No. Fluorescence routes fit configured assays. Open or multi-protein quantitative analysis in digests more often needs LC-MS/MS discovery or a targeted panel.
MtoZ Biolabs can support LC-quantitative pretreatment across unlabeled DDA or DIA discovery, TMT relative plexes, and targeted PRM or MRM follow-up when sample type, study design, and the intended claim are available.
If further evaluation of cleanup recovery, injection loads, TMT compatibility, or SIS spike planning before LC batches is needed, project details can be submitted for a feasibility review.
Reference
- M. Bantscheff, S. Lemeer, M.M. Savitski, B. Kuster (2012). Quantitative mass spectrometry in proteomics: critical review update from 2007 to the present. Anal. Bioanal. Chem., 404, 939-965. https://doi.org/10.1007/s00216-012-6203-4
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- J. Rappsilber, M. Mann, Y. Ishihama (2007). Protocol for micro-purification, enrichment, pre-fractionation and storage of peptides for proteomics using StageTips. Nat. Protoc., 2, 1896-1906. https://doi.org/10.1038/nprot.2007.261
- J.R. Wisniewski, A. Zougman, N. Nagaraj, M. Mann (2009). Universal sample preparation method for proteome analysis. Nat. Methods, 6, 359-362. https://doi.org/10.1038/nmeth.1322
Support Documents
Protein Quantification for Deeper Discovery
Gain a clearer understanding of protein quantification approaches and their applications in studying protein abundance changes by downloading our detailed brochure.