



Label-free quantitative proteomics (LFQ) estimates relative protein abundance from mass spectrometry signals without isotopic or chemical labeling. The usable advantages are simpler sample chemistry, independent sample enrollment, flexible cohort size, and compatibility with sample types that cannot be labeled cleanly. The matching disadvantages are run-to-run chromatographic and instrument variability, missing values in unlabeled data-dependent acquisition (DDA), heavier dependence on alignment and normalization, and the fact that ordinary LFQ intensities are relative values rather than protein amounts or cross-protein molar ranks. Claims of high throughput or high precision only hold after acquisition mode, chromatography stability, and the relative-comparison claim are specified.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for project-specific feasibility and analysis planning.
How LFQ Advantages and Disadvantages Arise Together
LFQ keeps each digest as its own liquid chromatography-tandem mass spectrometry (LC-MS/MS) run. Peptide identities come from fragment evidence. Quantitative values usually come from MS1 peak areas in DDA workflows, or from fragment chromatograms when the unlabeled digest is acquired as data-independent acquisition (DIA) (Cox et al. 2014; Gillet et al. 2012). Comparability is reconstructed after acquisition by alignment and normalization. That design is why later samples can still be added when the analytical regime remains compatible, and why injection order, column aging, and batch structure become part of the quantitative risk.
Labeling, acquisition, and assay scope remain separate decisions. LFQ means labels were not used. DDA and DIA name how fragmentation is scheduled. Targeted assays such as parallel reaction monitoring (PRM) can also be unlabeled, but they quantify a closed peptide list rather than an open discovery matrix.
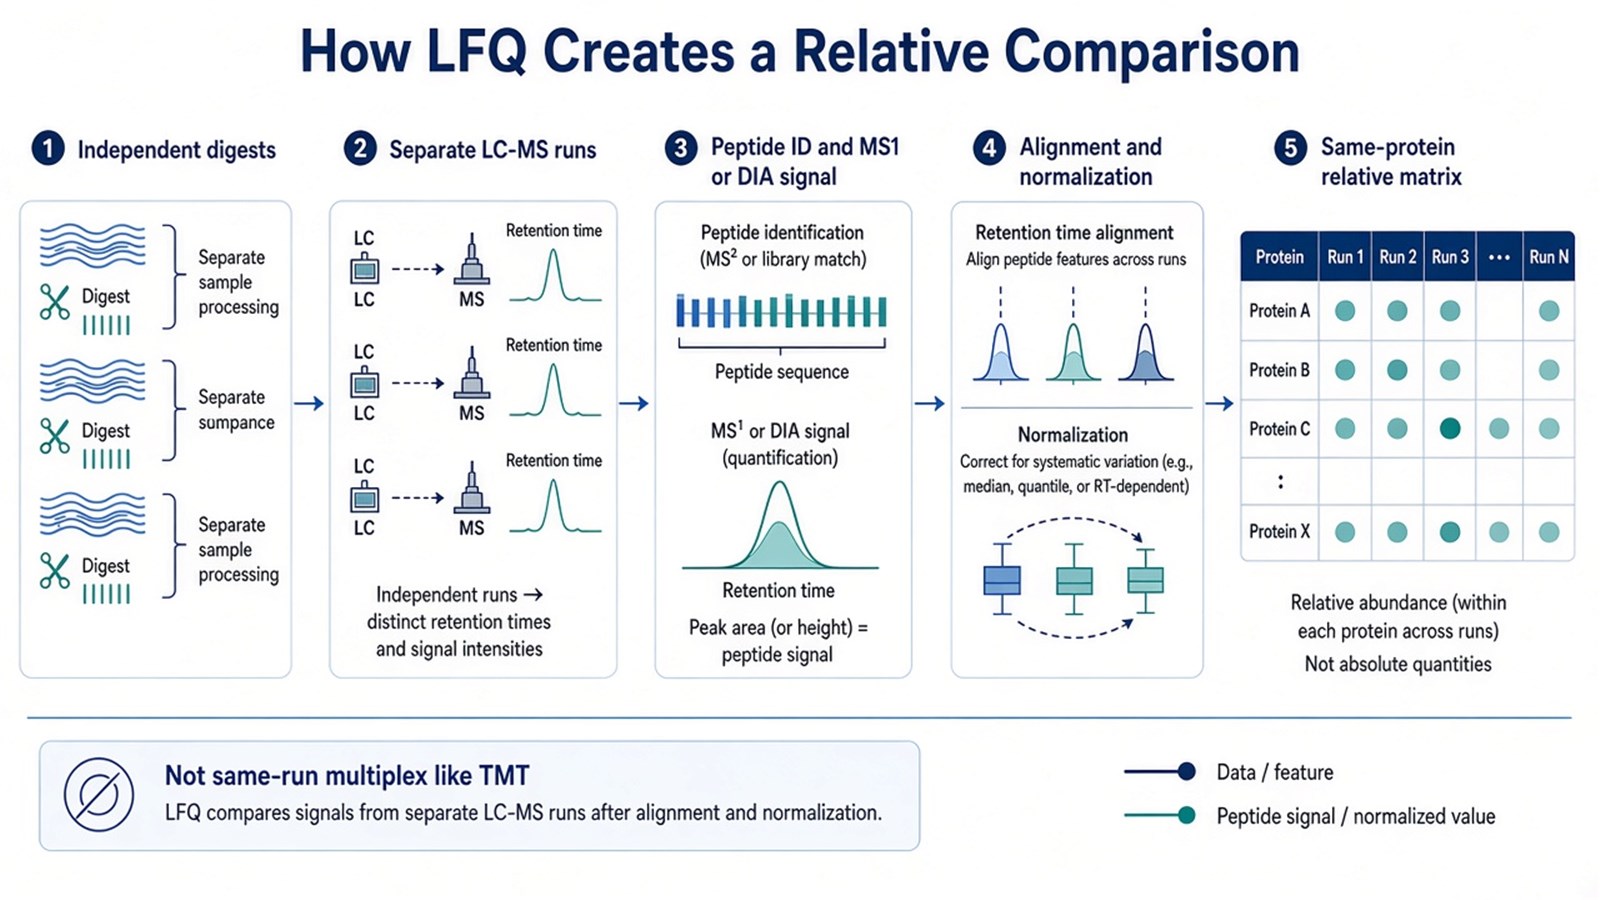
Figure 1. LFQ compares the same protein across independently acquired runs after alignment and normalization; it is not a same-run multiplex comparison like TMT.
An LFQ intensity supports relative change of one protein inside one coherent study plan, not a calibrated copy-number ranking across proteins.
Advantages That Hold for Unlabeled Independent Injections
No labeling chemistry and broader sample compatibility
LFQ omits isotopic or chemical tags, so amine-buffer conflicts, incomplete labeling, and leftover reagent are not part of the quantitative path. That matters for clinical tissues, biofluids, archival material, and other matrices where labeling chemistry is unreliable or sample amount is limited. The advantage is chemical simplicity. It is not proof that digestion and cleanup are trivial.
Flexible enrollment and experimental design
Because samples are not frozen into one multiplex kit, groups can be acquired over a planned window, and additional compatible injections can sometimes be added later. Designs with uneven group sizes or evolving cohorts often fit unlabeled discovery better than a closed tandem mass tag (TMT) plex. Flexibility still requires one coherent chromatographic and processing plan. A new column, instrument, or long interruption can create a block that ordinary normalization cannot merge.
Relative discovery without plex-size ceilings
Unlabeled discovery is not capped by a fixed channel count. Large treatment panels, genotype collections, and multi-site cohorts can be compared as relative matrices when acquisition and analysis stay controlled. Instrument time scales with sample number because each digest is injected separately. That is a planning cost, not automatically higher biological throughput than a multiplexed same-run design.
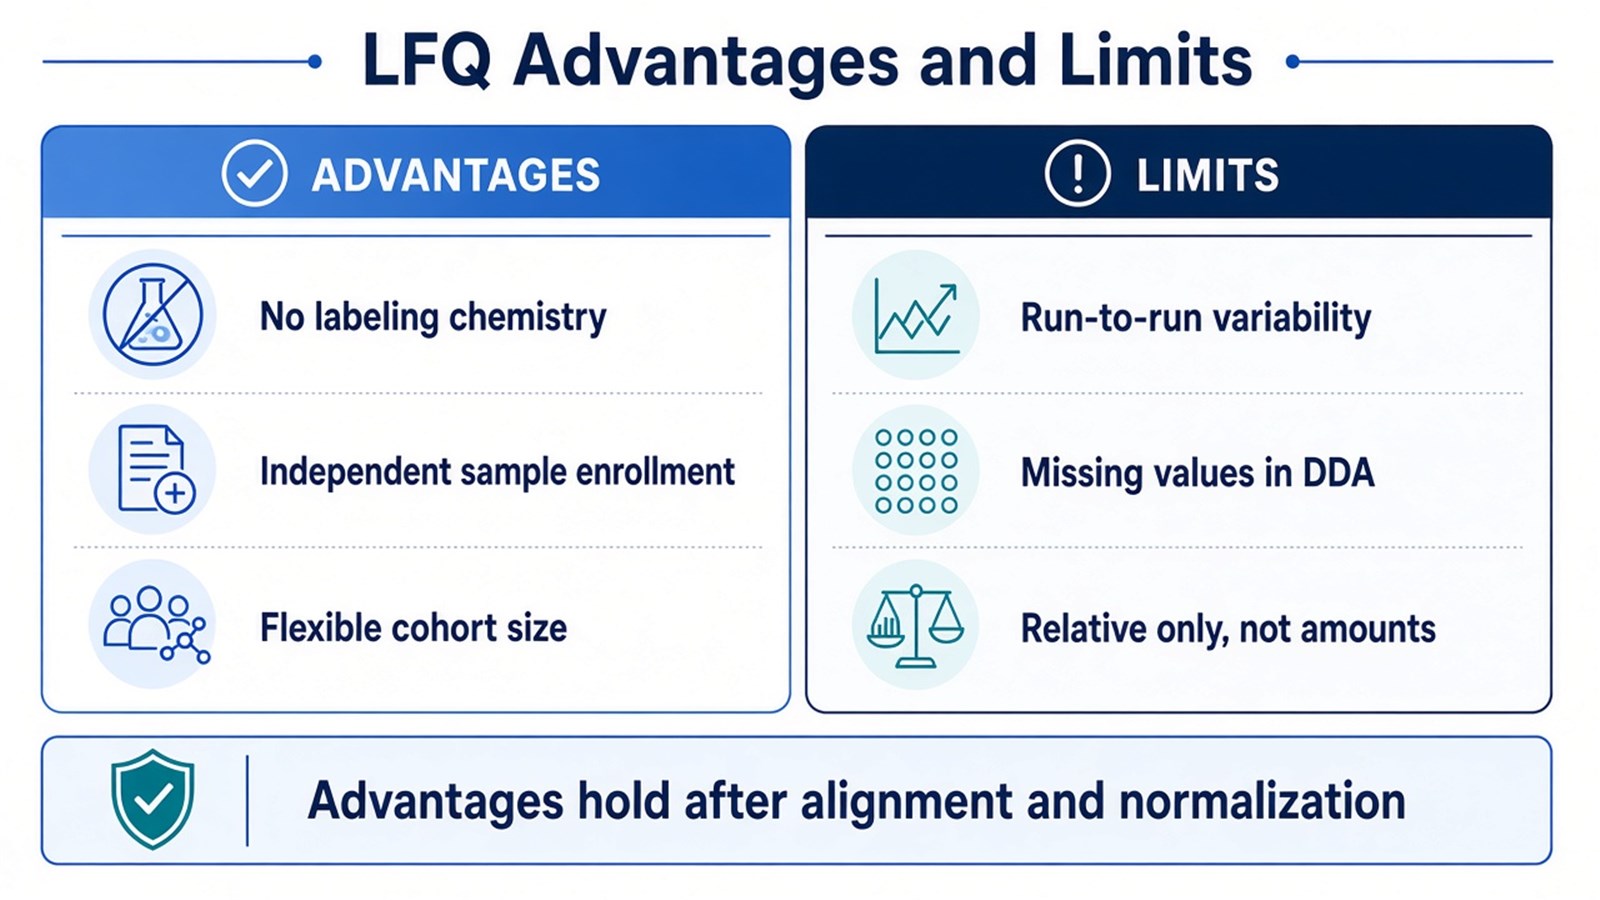
Figure 2. LFQ advantages apply when independent injections can be aligned and normalized; run-to-run variability and relative-only claims remain the main planning limits.
Disadvantages That Change the Experimental Plan
Run-to-run variability and design sensitivity
Each injection carries its own loading, spray, and retention-time history. Without randomized run order, quality-control monitoring, and declared normalization, technical scale can masquerade as biology. Reproducibility is therefore a property of the whole acquisition and analysis plan, not an intrinsic weakness of every unlabeled peptide.
Missing values and completeness trade-offs
In unlabeled DDA, a peptide may be identified in one file and missed in another. Match-between-runs can reduce some gaps and can also transfer incorrect assignments if tolerances are too open. DIA can improve matrix completeness by scheduled-window fragmentation, but it does not remove window interference or create absolute amounts (Gillet et al. 2012). Completeness and accuracy remain separate claims.
Relative ratios only, with heavier analysis burden
Ordinary LFQ intensities do not report tissue concentration or rank protein A against protein B by molar amount. Intensity-based absolute proxies such as iBAQ answer a different within-sample question and should not be substituted for cross-sample LFQ contrasts without stating the change in claim. Researchers comparing those readouts can refer to What Is the Difference between LFQ and iBAQ?.
Alignment, normalization, missing-value handling, and batch review are mandatory analysis steps. For how normalization assumptions should be chosen and checked, see How to Normalize Data in Label-Free Quantitative Proteomics?.
How to Judge Whether LFQ Fits the Current Cohort
Study condition |
LFQ is often useful |
Reassess before unlabeled discovery |
|---|---|---|
Comparison structure |
Relative same-protein change across independent runs |
Closed multi-group set that benefits from one pooled plex |
Sample chemistry |
Digests should stay unlabeled or cannot be labeled cleanly |
Labeling is feasible and same-run comparison is the priority |
Cohort timing |
Enrollment continues or group sizes are uneven |
All samples can be frozen in one TMT kit now |
Completeness need |
DIA can be added when DDA missingness is limiting |
True fold-change magnitude in a dense digest needs MS3-style control inside a plex |
Quantitative claim |
Relative discovery inside one study plan |
Absolute amount or cross-protein molar ranking without standards |
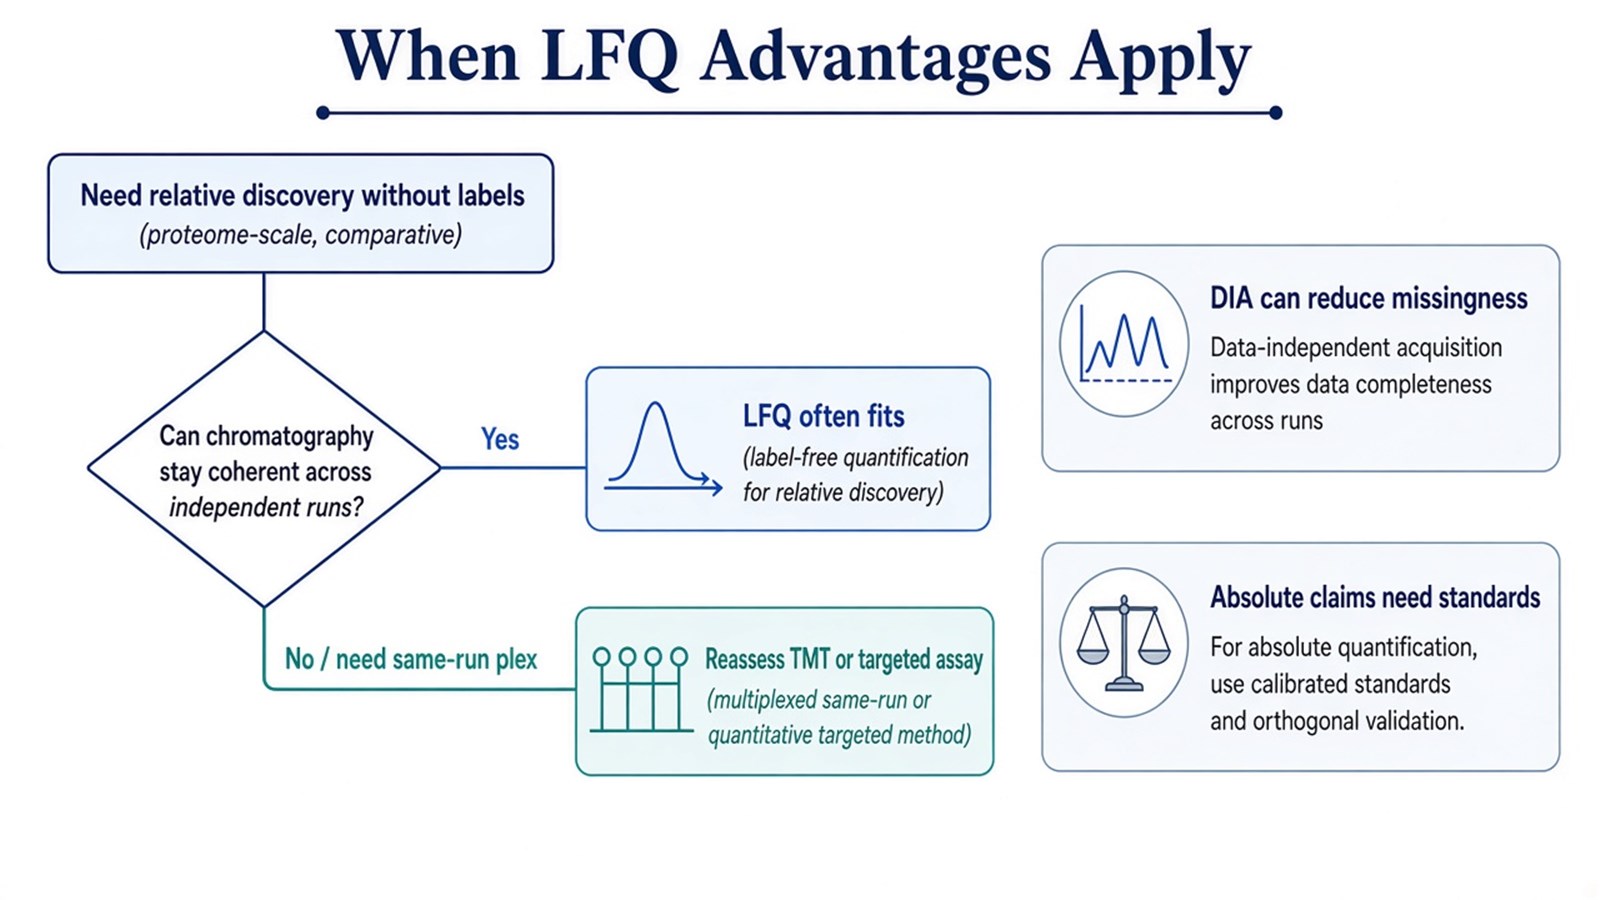
Figure 3. LFQ advantages apply when relative discovery can be maintained across independent runs; a closed plex or absolute claim points to a different method.
When sample number, multiplexing, or later enrollment makes the choice less straightforward, researchers can refer to Comparing LFQ and Isobaric Labeling Strategies in Proteomics Quantification. For a fuller unlabeled definition beyond the advantage list, see What Is Label-Free Quantification in Proteomics?.
Application Boundaries After the Trade-off Is Accepted
LFQ is commonly used for treatment screens, tissue-state comparisons, clinical cohort discovery, and projects where labeling would constrain chemistry or enrollment. In those settings, design controls and normalization decide whether relative changes are trustworthy. Pathway enrichment on an LFQ candidate list reflects overrepresentation relative to a quantified background. It does not prove pathway activity. Diagnostic cutoffs sit outside ordinary discovery LFQ claims.
Once the unlabeled constraint, acquisition mode, and expected protein-level readout are defined, the project can be evaluated as an LFQ study. Researchers can review the MtoZ Biolabs Label-Free Quantitative Proteomics Service for sample evaluation, feasibility assessment, and workflow planning.
Frequently Asked Questions
1. Is label-free quantification the same as DIA?
No. LFQ means isotopic or isobaric labels were not used. DIA means precursors are fragmented in scheduled windows. An unlabeled digest can be run as DDA or DIA.
2. Does LFQ always have lower precision than TMT?
Not as a blanket rule. TMT reduces some injection-to-injection drift inside one plex but can compress ratios. LFQ precision depends on chromatography stability, normalization, and missingness. The better method is the one that matches the claim and cohort.
3. Can LFQ report absolute protein concentration?
Not from ordinary LFQ intensities. Absolute or copy-number claims need matched standards and a calibration model.
4. Is LFQ automatically cheaper and faster for every large study?
Reagent cost is usually lower without labels, but instrument time scales with independent injections. Total cost and calendar time are project outcomes, not fixed properties of the method name.
5. When is TMT the better next experiment than LFQ?
TMT is often better when the contrast can be frozen in one kit, labeling is feasible, and same-run relative comparison is the main need. LFQ is often better when samples must stay independent or cannot be labeled cleanly.
Reference
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, N. Nagaraj, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031591
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
