



Absolute QUAntification (AQUA) uses stable isotope-labeled synthetic peptides to convert targeted MS signals into amount or concentration for named peptides (Gerber et al. 2003). Advantages include sequence-specific standards, isotope dilution control of preparation drift, and use with MRM or PRM on a closed panel. Disadvantages include synthesis cost, calibration design, and skilled targeted method work. AQUA reports peptide amount under stated spike timing, not open discovery, and does not replace relative LFQ, DIA, or TMT when fold change alone suffices.
Researchers who already have a closed target list and required reporting units can also review the MtoZ Biolabs Absolute Quantitative Analysis (AQUA) Service and Targeted Proteomics Service for project-specific feasibility and assay planning.
AQUA Advantages and Disadvantages at a Glance
Topic |
Advantages |
Disadvantages |
|---|---|---|
Specificity |
Heavy-light peptide pairs target defined sequences |
Only scheduled peptides are measured |
Quantitative claim |
Supports concentration or amount with calibration |
Not a relative discovery matrix by itself |
Experimental control |
Isotope dilution reduces some preparation drift |
Spike timing defines what is corrected |
Platform |
Works with MRM or PRM targeted acquisition |
Needs transition or scheduling optimization |
Scale |
Efficient for a closed shortlist |
Cost and design burden rise with panel size |
Matrix |
Can be robust when calibrators match sample background |
Ion suppression and recovery can break naive curves |
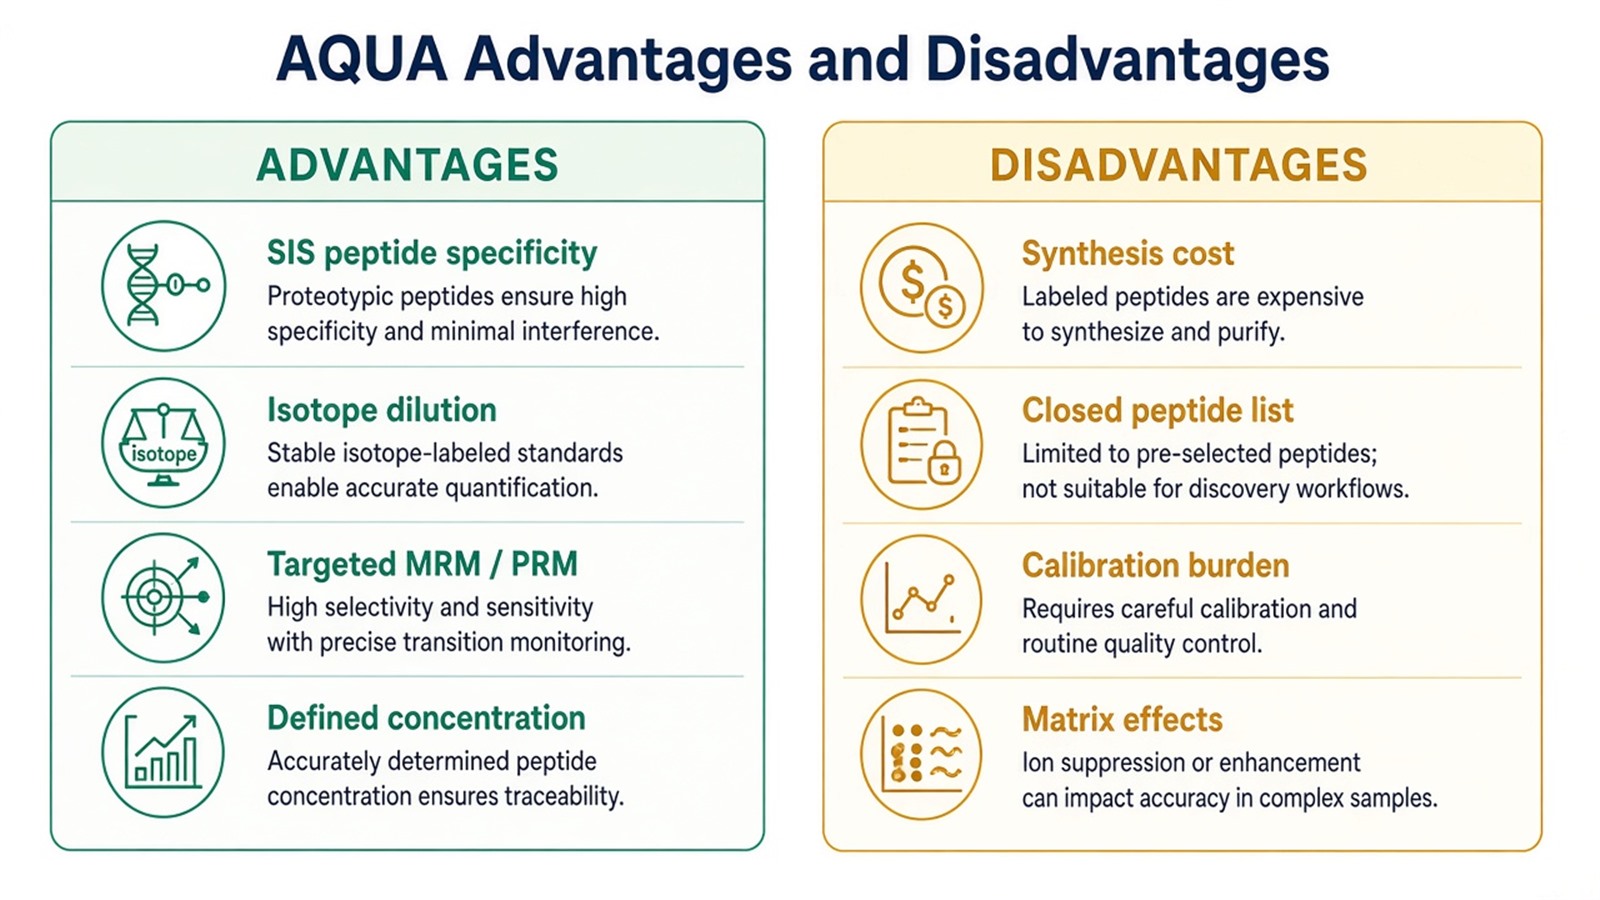
Figure 1. AQUA trades open discovery coverage for calibrated amount on a closed peptide list.
AQUA strengths appear when the scientific question needs defined units for named peptides, not when the question is still an open protein inventory.
How AQUA Absolute Quantification Works
AQUA is implemented as isotope dilution on proteotypic peptides. A heavy synthetic peptide matching the target sequence is spiked at a known amount into the sample or digest. Endogenous light peptide and heavy standard are acquired together by targeted LC-MS/MS. A calibration curve built in matrix-matched material converts the light-to-heavy response into amount or concentration for that peptide.
The defended result is peptide-level amount under the chosen spike point. Protein-level concentration is inferred only when digestion, enrichment, and calibration support that inference. Post-digestion spiking does not automatically correct protein losses that occurred before the standard entered the sample.
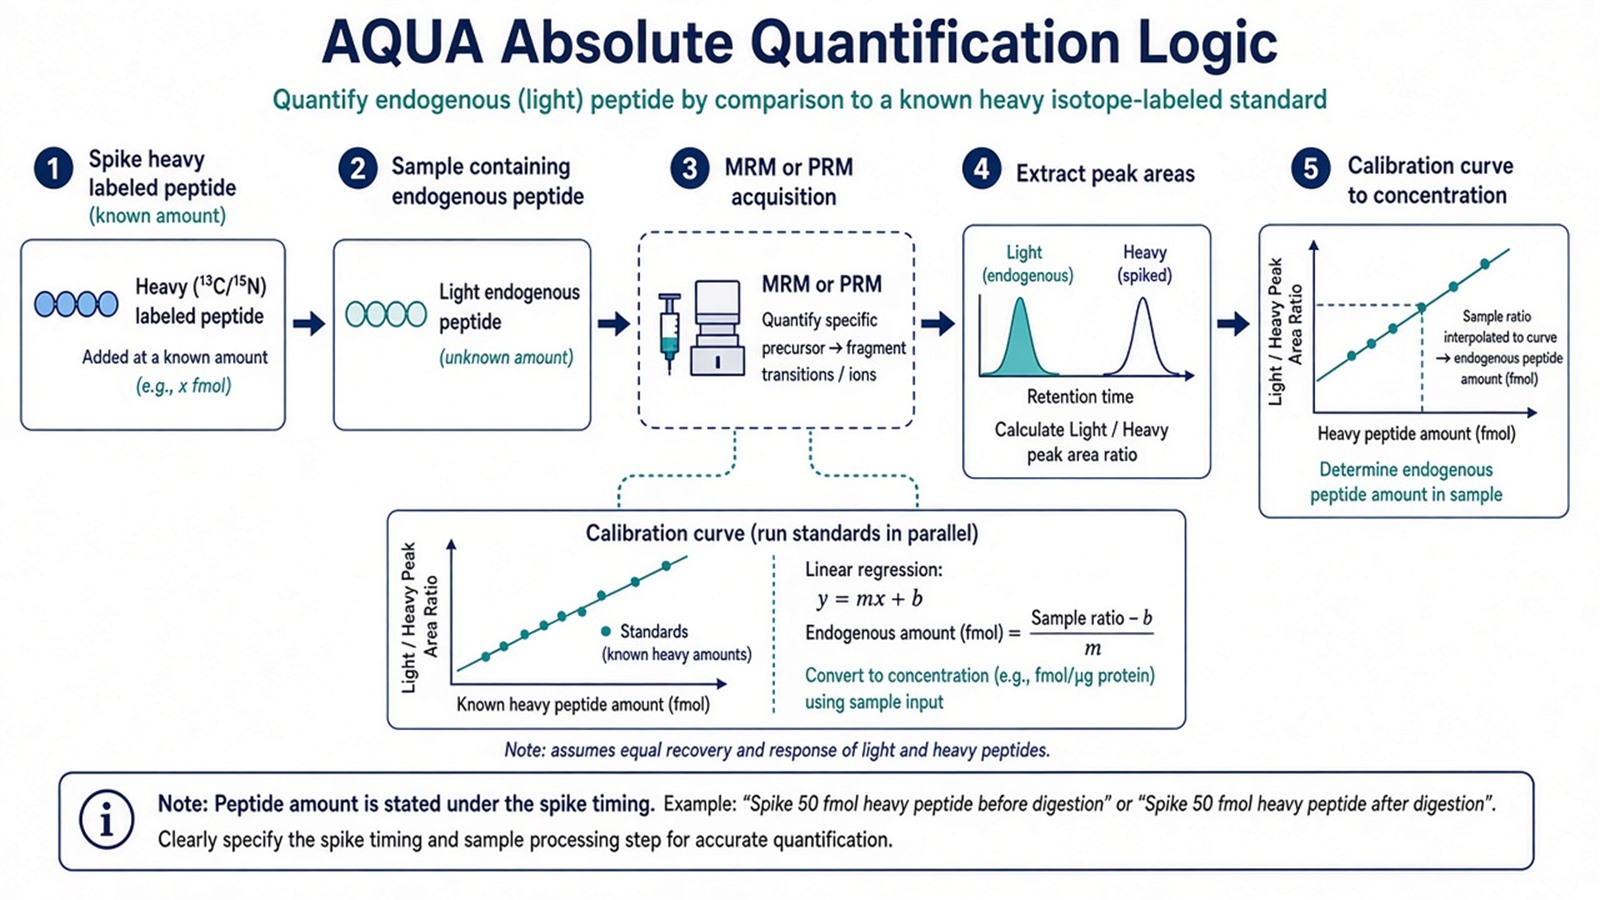
Figure 2. AQUA converts targeted light and heavy peptide signals into amount only after standards, spike timing, and calibration are defined.
For broader absolute method families, see Absolute Protein Quantification: Methods and Uses. For targeted absolute framing, see Absolute Quantification in Targeted Proteomics. For the shared targeted path, see Targeted Proteomics Workflow: How Does Targeted Proteomics Work?.
Judgment Criteria: When AQUA Fits
Study need |
AQUA often fits |
Reassess before ordering standards |
|---|---|---|
Claim |
Concentration, stoichiometry, or specification units |
Relative fold change alone |
Targets |
Closed, mature proteotypic peptides |
Open discovery list still changing |
Range |
Expected amounts bracketed by calibrators |
Abundance unknown across many orders of magnitude |
Matrix |
Study-like calibrators and QC feasible |
No peptide survives digestion in that matrix |
Platform |
MRM or PRM method can be built for the panel |
Only unlabeled discovery runs are planned |
Validation stage |
Research assay for named amount |
Regulatory diagnostic cutoff without full validation |
Prefer AQUA when the decision sentence requires amount or concentration for specific peptides and the panel is closed. Prefer relative PRM or MRM without full calibration when confirmation trends are enough. Prefer label-free quantification (LFQ), DIA, or TMT while the inventory is still open. Prefer immunoassay transfer only after the peptide-level MS claim is defined, not as a substitute for MS design.
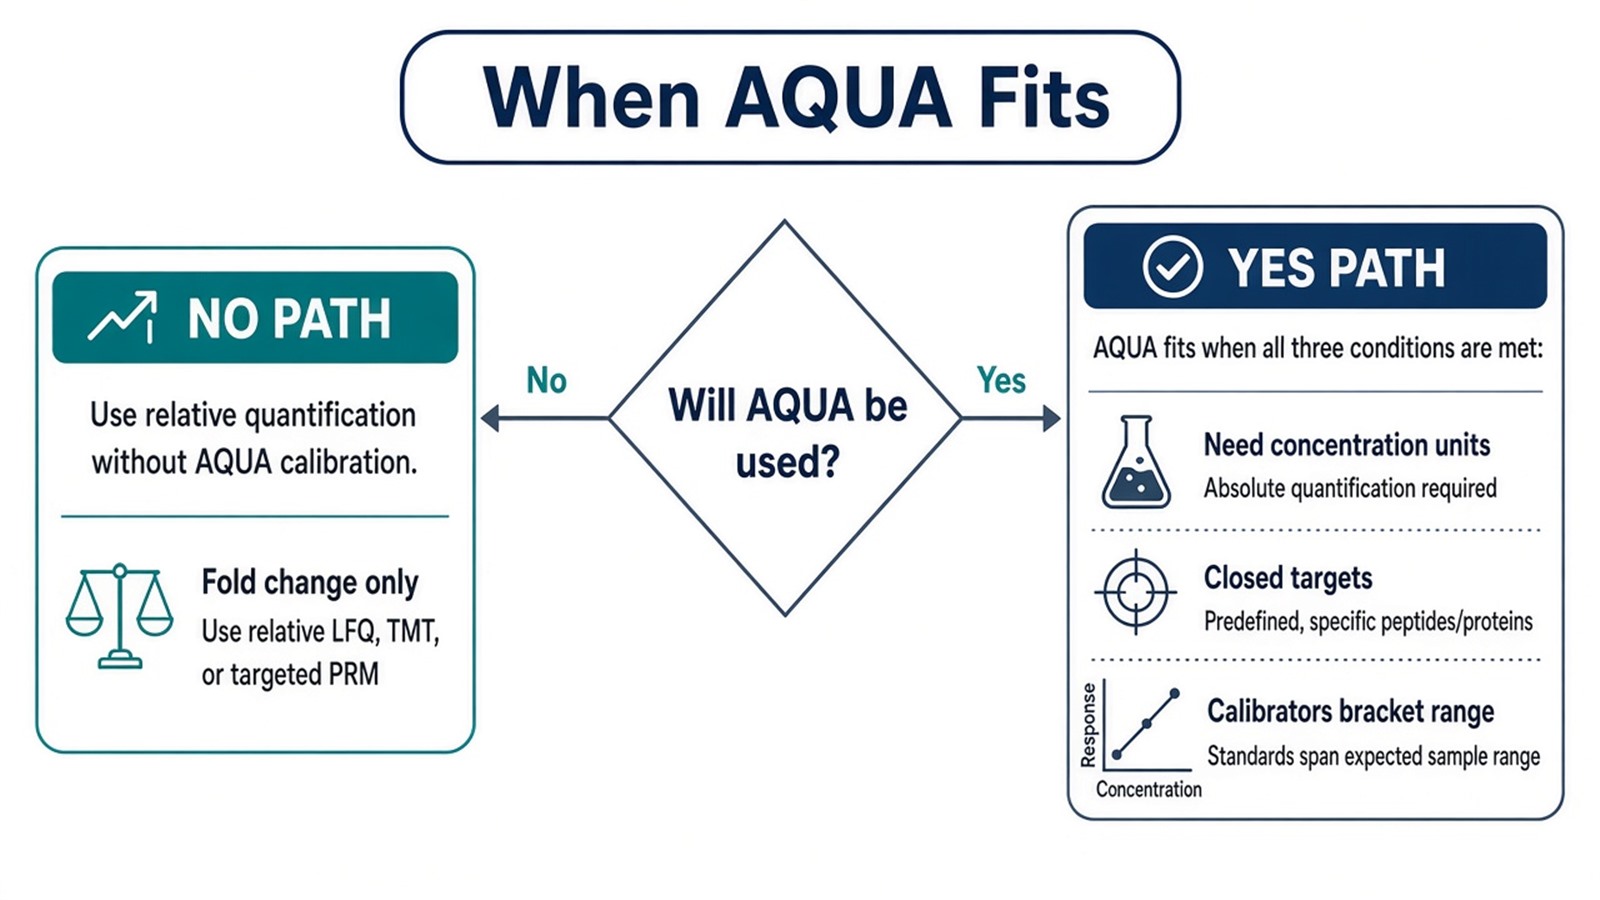
Figure 3. Choose AQUA when amount is part of the claim and the peptide list is closed; keep relative routes when it is not.
For PRM versus MRM as acquisition layers under AQUA, see PRM and MRM in Targeted Proteomics: Advantages and Limitations. For experimental design breadth, see Targeted Proteomics Experimental Design.
Limits and Application Boundaries
AQUA does not quantify proteins that lack a suitable proteotypic peptide or that fall outside the validated calibration range without dilution or enrichment redesign. Multiplexing many AQUA peptides increases synthesis cost and chromatographic scheduling load. Modified forms need standards that carry the same modification chemistry. Extremely low abundance in complex biofluids may still fail even with standards if the light peptide is not recovered.
Typical applications include reference amount for a biomarker peptide in research validation, stoichiometry or impurity monitoring for a defined target in biopharma matrices, and bridging MS amount to later assay development for a short closed list. Ordinary discovery biomarker lists, pathway screens, and diagnostic decision rules sit outside default AQUA reporting unless a separate validated framework is in place.
Once targets, spike timing, calibration range, and acquisition class are defined, the project can be evaluated as an AQUA absolute assay. Researchers can review the MtoZ Biolabs Absolute Quantitative Analysis (AQUA) Service for standard design, feasibility assessment, and workflow planning.
Frequently Asked Questions
1. Is AQUA the same as label-free or TMT quantification?
No. LFQ, DIA, and TMT are usually relative discovery or ratio strategies. AQUA adds labeled standards and calibration for amount on named peptides.
2. Does AQUA always reach femtomolar sensitivity?
Sensitivity follows peptide recovery, matrix background, and instrument performance for that method. AQUA improves specificity for the scheduled peptide but does not guarantee detection of every low-abundance analyte.
3. Can one AQUA peptide quantify the whole protein automatically?
The readout is the monitored peptide under the stated digestion and spike design. Protein inference needs explicit assumptions about proteotypic representation and processing.
4. Is AQUA only compatible with MRM?
No. AQUA logic is independent of acquisition class. Many modern panels use PRM with the same isotope dilution principle.
5. When should a project skip AQUA?
When the claim is relative fold change across groups, when targets are not closed, or when budget and time cannot support standards and calibration.
Reference
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
