



Quantitative proteomics is powerful when it turns matched peptide digests into defensible abundance comparisons across conditions, not when it only lengthens an identification list (Bantscheff et al. 2012). The breakdown below explains what that power actually is in laboratory practice: comparable signals, scalable cohort designs, and confirmation routes that can remeasure named peptides. It is not a disease-application catalog, not a future-technology forecast, and not a second definition encyclopedia.
Power still depends on three declared choices: labeling chemistry, acquisition mode, and whether the claim is a relative ratio or a stable isotope-labeled internal standard (SIS) amount. Unlabeled digests can be acquired as data-dependent acquisition (DDA) or data-independent acquisition (DIA). Isobaric tandem mass tag (TMT) work typically mixes channels before one LC path. Named proteins are typically followed by parallel reaction monitoring (PRM) or multiple reaction monitoring (MRM) / selected reaction monitoring (SRM). In MtoZ Biolabs offerings, unlabeled discovery is commonly run as DDA label-free or DIA, multiplexed isobaric work is typically evaluated as TMT, and closed lists are typically followed by PRM, with MRM when a scheduled triple-quadrupole panel already exists.
What Quantitative Proteomics Adds Beyond Identification
Identification answers which peptides scored. Quantification answers how their extracted signals change between groups after extraction, digestion, and acquisition stay matched. That shift is what makes quantitative proteomics useful for treatment contrasts, time courses, and confirmation of short candidate lists.
The gain is not automatic. A deep protein inventory without quantitative filters, unique-peptide rules, and a declared contrast still cannot support a fold-change claim. Bulk dye assays and A280 readings only match total load. They do not replace peptide-level quantification.
The practical power of quantitative proteomics is a controlled comparison of peptide signals under a stated claim, not a longer protein name list alone.
Researchers who need the signal-type definitions behind that claim can refer to What Are the Quantitative Methods for Proteomics?.
Sources of Analytical Power in Practice
Four laboratory sources usually explain why a quantitative design works.
Comparable signals across conditions. Unlabeled DDA label-free quantification (LFQ) extracts MS1 peak areas after identification (Cox et al. 2014). Unlabeled DIA extracts fragment chromatograms from scheduled windows (Gillet et al. 2012). TMT reads relative channel abundance from reporter ions after mixing (Thompson et al. 2003). Each route supports relative comparison only when samples share extraction chemistry and a declared normalization or channel map.
Throughput without losing the contrast. Multiplexed TMT freezes several groups into one LC path, which often reduces run-order drift inside a plex. Unlabeled designs keep enrollment open by injecting digests separately, which often fits cohorts that still grow. Throughput is a design property, not a reason to skip QC.
Confirmation after names freeze. PRM and MRM remeasure scheduled peptides from extracted fragment signals (Lange et al. 2008; Peterson et al. 2012). SIS-supported targeted assays convert light-to-heavy ratios into peptide amounts (Gerber et al. 2003). Confirmation power rises when the list is short enough for one duty cycle.
Optional multi-omic or pathway context. Pathway enrichment or transcriptomics overlay can help interpret a cleaned matrix. It does not repair missingness, confounded run order, or amount claims made without SIS.
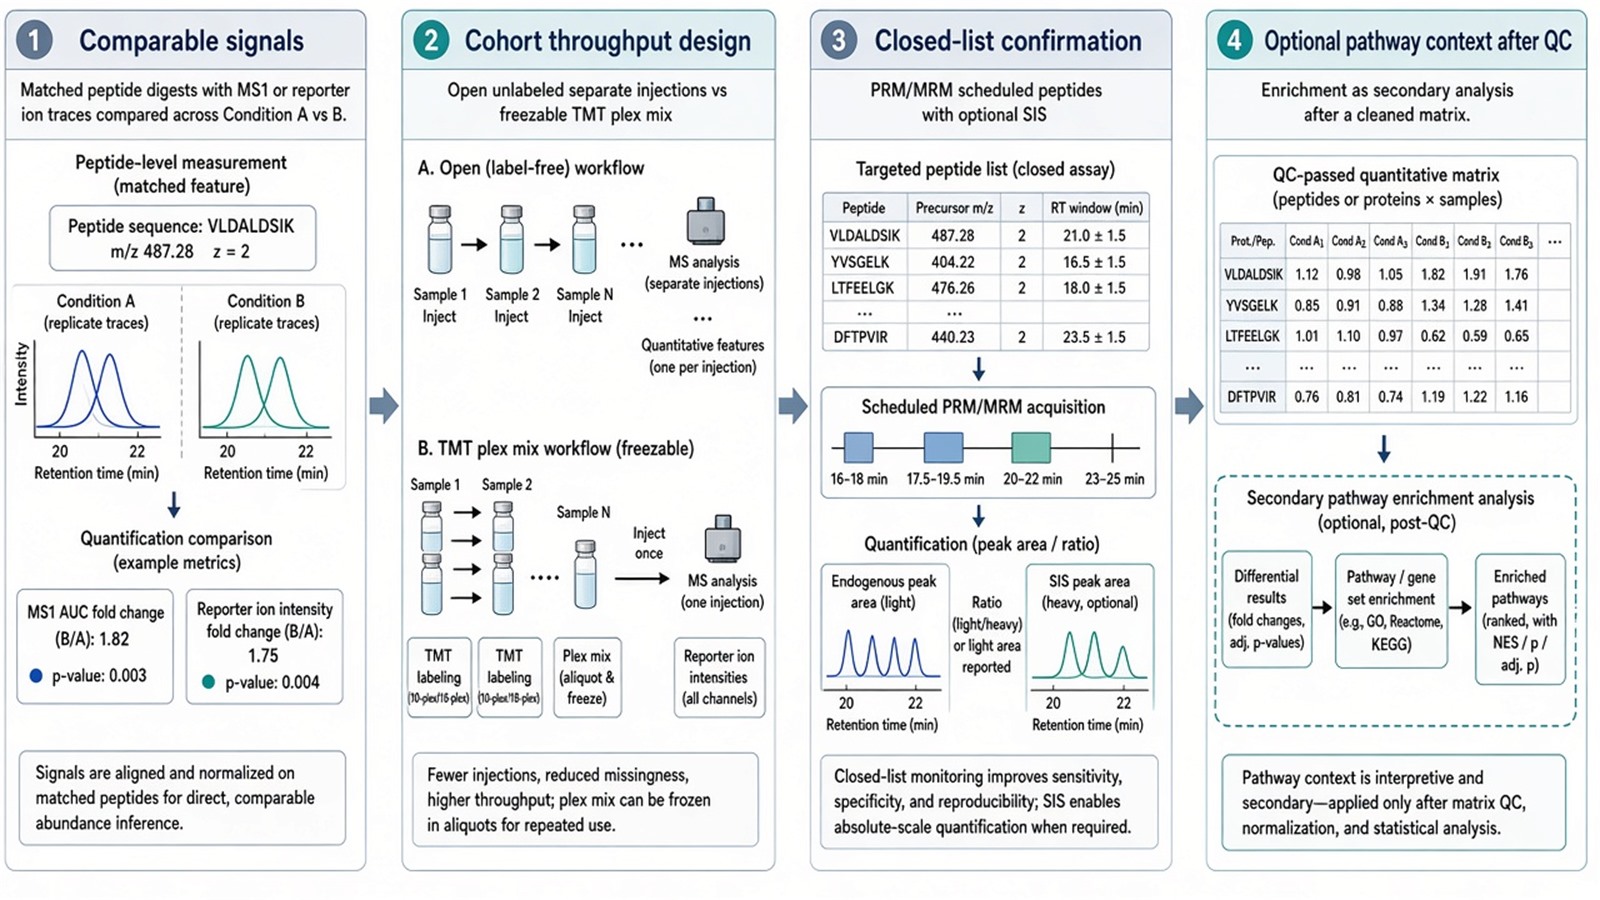
Figure 1. Analytical power comes from matched signals, a freezable or open cohort design, and optional confirmation; pathway context is secondary after QC.
A technique map of unlabeled, isobaric, and targeted routes is covered in Quantitative Proteomics Techniques. This page stays on what those routes deliver when the design holds.
Shared Workflow That Turns Comparisons into Defensible Matrices
Every powerful quantitative project still follows the same spine: matched extraction and digestion, LC-MS/MS under a declared acquisition mode, identification or targeted extraction, protein rollup, and a contrast that matches the sample map.
What changes by route is where samples diverge. Unlabeled work keeps each digest on its own injection, so alignment and normalization carry the cross-run burden. TMT adds labeling completeness and pooling before acquisition. Targeted work inserts peptide selection and method scheduling before the cohort is acquired. SIS, when used, adds spike timing and calibration before amount reporting.
Order matters more than a biomarker keyword. Unequal input, treatment-confounded run order, incomplete labeling, or an oversized targeted panel can erase the comparison after the instrument run looks complete.
Parameters and Limits That Bound That Power
Key parameters usually decide whether the claimed power survives review.
Parameter |
Why it matters |
Failure mode if ignored |
|---|---|---|
Matched input and digestion |
Keeps peptide yield comparable |
Apparent fold changes from load bias |
Run-order or channel map |
Separates biology from batch |
Group effects that track injection order |
Acquisition and FDR rules |
Define which features enter the matrix |
Inflated IDs with weak quantitative traces |
Unique-peptide and missing-value rules |
Control protein rollup and dropout |
Soft contrasts that vanish after QC |
SIS assignment (amount assays) |
Ties ratio to a concentration unit |
Relative peaks read as ng per mL |
Limits follow the same table. Unlabeled matrices do not invent unidentified proteins. TMT ratios are relative inside a plex and do not accept late unlabeled files as extra channels. Targeted schedules do not survey an open proteome. Ordinary discovery intensities are not absolute concentration. Instrument brand names and future single-cell or spatial platforms are implementation layers. They are not required to explain why a standard cohort comparison works.
Missing values need a rule matched to abundance-dependent dropout before imputation (Lazar et al. 2016). Pathway stories cannot replace that triage.
Project Fit: When the Power Claim Holds
Use the intended claim and enrollment flexibility to decide whether quantitative proteomics is the right next step.
Project need |
Design that often holds the claim |
Recheck before committing |
|---|---|---|
Open list, samples may still be added |
Unlabeled DDA LFQ or unlabeled DIA |
Run order identical to treatment |
Open list, full set can be mixed now |
TMT relative plex |
Later harvests without a bridge |
Named peptides to remeasure |
PRM or MRM |
Panel longer than one duty cycle |
Mass or molar unit for named peptides |
Targeted assay plus matched SIS |
Relative peaks read as concentration |
Only total protein load matching |
Bulk dye or A280 assay |
Not a proteome comparison |
Disease keyword without matched groups |
Redesign groups first |
Power claim fails before acquisition |
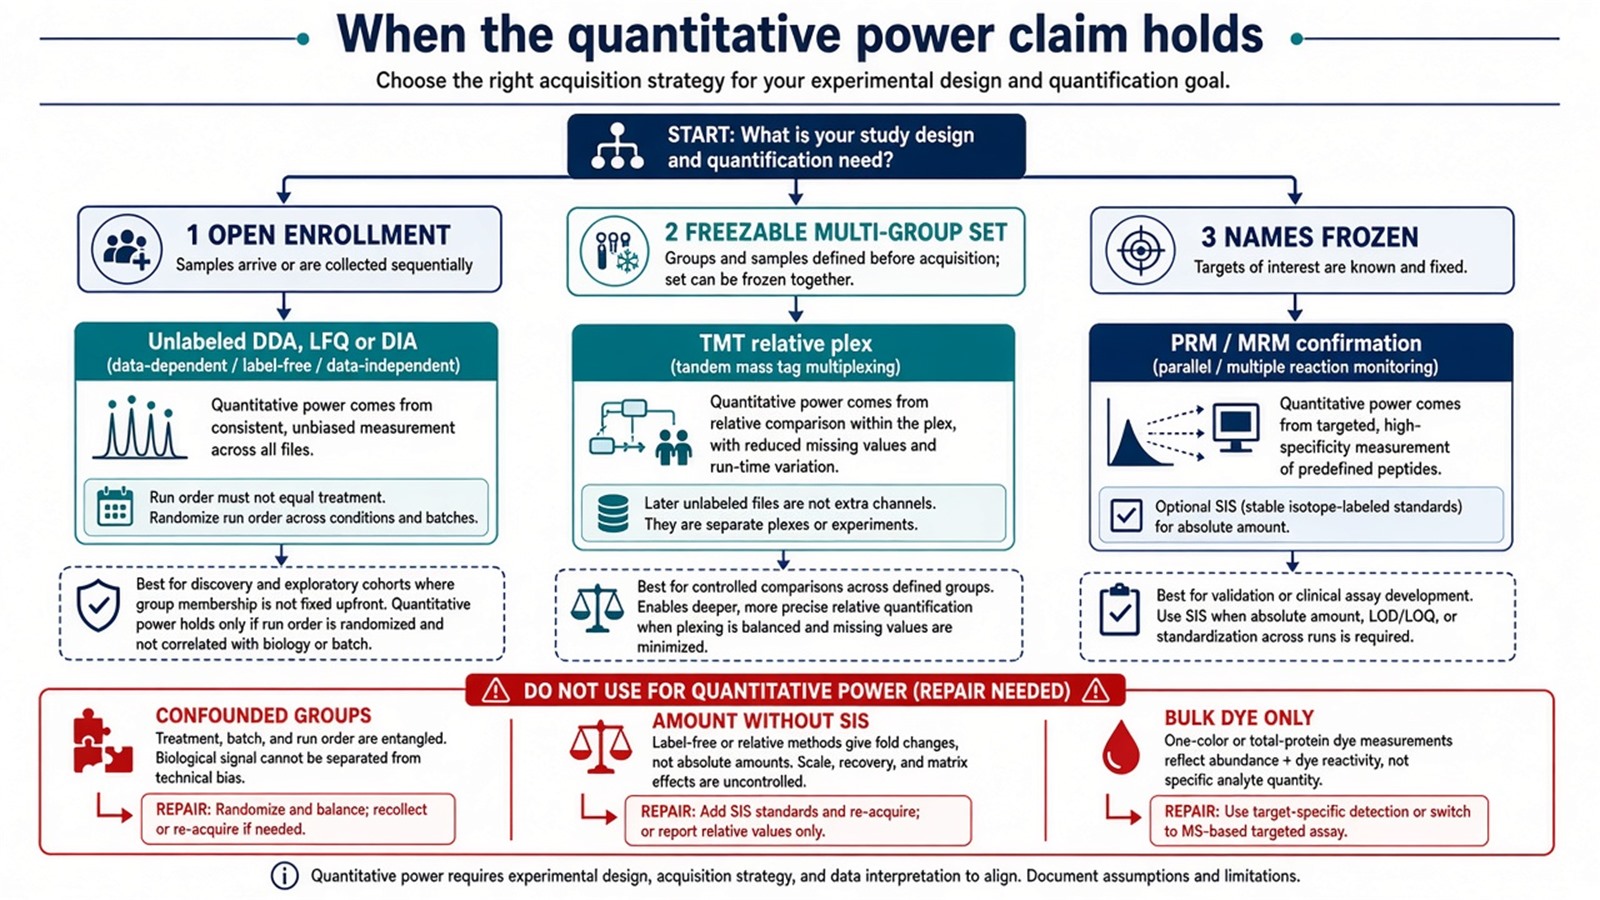
Figure 2. The power claim holds when list status, mixability, and unit match the assay; confounded groups and amount-without-SIS requests need repair first.
Unlabeled discovery more often fits open enrollment. TMT more often fits a freezable multi-group set. Targeted confirmation more often fits after names freeze. Exceptions exist when a tiny validated panel never needed discovery, or when a short closed cohort must share one injection to limit run-order drift.
Researchers who need the three-axis selection logic after this breakdown can refer to Protein Quantification Method. Teams that already have sample type, group design, and a requested claim can also review the MtoZ Biolabs Quantitative Proteomics Service for project-specific feasibility.
Frequently Asked Questions
1. Does high identification depth prove that a quantitative project is powerful?
No. Power requires usable quantitative traces, matched design, and a declared contrast. A long protein list can still fail quantitative filters.
2. Is multiplexing the same as higher biological power?
No. Multiplexing improves within-plex comparability when the channel map is valid. It does not replace biological replication or fix confounded groups.
3. Can pathway enrichment replace quantitative QC?
No. Enrichment interprets a cleaned matrix. It cannot repair missingness, batch effects, or amount claims made without SIS.
4. When should confirmation follow discovery?
When names freeze and the next claim needs scheduled remeasurement or an SIS amount. Open discovery remains the first step when the protein list is still unknown.
5. Does absolute quantification make every study more powerful?
No. Absolute reporting helps only when a concentration unit is required and a matched SIS plus calibration are available. Many contrasts are answered by relative ratios alone.
MtoZ Biolabs can support quantitative proteomics designs across unlabeled DDA or DIA discovery, TMT relative plexes, and targeted PRM or MRM follow-up when sample type, study design, and the intended claim are available.
If further evaluation of labeling versus acquisition, relative versus SIS-supported amount, or whether a bulk load assay is sufficient is needed, project details can be submitted for a feasibility review.
Reference
- M. Bantscheff, S. Lemeer, M.M. Savitski, B. Kuster (2012). Quantitative mass spectrometry in proteomics: critical review update from 2007 to the present. Anal. Bioanal. Chem., 404, 939-965. https://doi.org/10.1007/s00216-012-6203-4
- J. Cox, M.Y. Hein, C.A. Luber, I. Paron, M. Mann (2014). Accurate proteome-wide label-free quantification by delayed normalization and maximal peptide ratio extraction, termed MaxLFQ. Mol. Cell. Proteomics, 13, 2513-2526. https://doi.org/10.1074/mcp.M113.031031
- S.A. Gerber, J. Rush, O. Stemman, M.W. Kirschner, S.P. Gygi (2003). Absolute quantification of proteins and phosphoproteins from cell lysates by tandem MS. Proc. Natl. Acad. Sci. U.S.A., 100, 6940-6945. https://doi.org/10.1073/pnas.0832254100
- L.C. Gillet, P. Navarro, S. Tate, H. Rost, N. Selevsek, L. Reiter, R. Bonner, R. Aebersold (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.O111.016717
- V. Lange, P. Picotti, B. Domon, R. Aebersold (2008). Selected reaction monitoring for quantitative proteomics: a tutorial. Mol. Syst. Biol., 4, 222. https://doi.org/10.1038/msb.2008.61
- C. Lazar, L. Gatto, M. Ferro, C. Bruley, T. Burger (2016). Accounting for the multiple natures of missing values in label-free quantitative proteomics data sets to compare imputation strategies. J. Proteome Res., 15, 1116-1125. https://doi.org/10.1021/acs.jproteome.5b00981
- A.C. Peterson, J.D. Russell, D.J. Bailey, M.S. Westphall, J.J. Coon (2012). Parallel reaction monitoring for high resolution and high mass accuracy quantitative, targeted proteomics. Mol. Cell. Proteomics, 11, 1475-1488. https://doi.org/10.1074/mcp.O111.013698
- A. Thompson, J. Schafer, K. Kuhn, S. Kienle, J. Schwarz, G. Schmidt, T. Neumann, R. Johnstone, A.K. Mohammed, C. Hamon (2003). Tandem mass tags: a novel quantification strategy for comparative analysis of complex protein mixtures by MS/MS. Anal. Chem., 75, 1895-1904. https://doi.org/10.1021/ac0262560
