Protein Modification Prediction Software
Protein modification prediction software evaluates a protein sequence to prioritize candidate residues for phosphorylation, acetylation, ubiquitination, or other specified modifications. The software answers a sequence question. It does not answer a sample question. NetPhos, PAIL, UbPred, and related tools score amino acids against motifs or trained models and return a ranked list of candidate sites (Blom et al. 1999). Bottom-up liquid chromatography-tandem mass spectrometry (LC-MS/MS) reports whether a covalent mass shift is present on an accepted peptide in the lysate or purified protein that was actually measured. Choosing a predictor by interface polish or update frequency does not close that gap.
Researchers who already have a candidate list and need residue-level evidence in a real sample can review the MtoZ Biolabs PTM Sites Identification Service for how enrichment, LC-MS/MS, and localization scoring are matched to a named modification class.
What Prediction Software Can Report
Protein modification prediction software reports a score, probability, or kinase-group label for residues in a submitted sequence (Blom et al. 1999; Xue et al. 2008). The input is typically a FASTA. The output is a table of positions that resemble known phosphorylation, acetylation, or ubiquitination patterns. False positives and false negatives are expected. Cellular occupancy, kinase access, peptide detectability after trypsin, and the treatment sitting on the bench are not sequence features.
A high NetPhos score does not mean the serine was phosphorylated in this cell type. A PAIL hit does not mean the lysine was acetylated in the immunoprecipitate. An UbPred rank does not mean a ubiquitin remnant will be recovered after digestion. Function after modification is outside the software object entirely. Predictors do not model catalytic activity, localization of the protein, or pathway output.
Predictors, Annotated Databases, and Spectrum Search Tools
1. Sequence predictors versus reported-site databases
Sequence predictors and experimental databases are often filed together as “PTM software.” They are not interchangeable. NetPhos, GPS, PAIL, UbPred, and ModPred infer sites from sequence or from models trained on earlier data. PhosphoSitePlus and UniProt record sites that were reported in literature or in deposited experiments (Hornbeck et al. 2015). A database residue is still a prior for this sample, but it is a different prior: someone measured a protein, not only a motif. Conservation across homologs can shrink a candidate panel. It cannot replace a spectrum from the condition under study.
Use a predictor when the protein is poorly annotated and a shortlist is needed before mutagenesis or targeted MS. Use a database when the question is what has already been seen on that accession. Use both as a panel, not as two independent identifications.
2. Prediction software is not a search engine
MaxQuant, Proteome Discoverer, Spectronaut, and related platforms score peptide-spectrum matches and localization on recorded LC-MS/MS data (Cox and Mann 2008; Olsen and Mann 2013). They are not protein modification prediction software. A localization probability or Ascore tests whether fragments distinguish one residue from nearby candidates on an accepted peptide (Beausoleil et al. 2006). That test requires ions that entered the instrument. Pasting a NetPhos residue into a search as if it were a localized site inverts the evidence chain.
Kinase-specific predictors such as GPS add a hypothesized enzyme class to the residue. The label is a motif hypothesis. It is not kinase activity in the lysate and it is not evidence that the enzyme acted on that protein in the experiment.
Phosphorylation-focused experimental assignment after metal-affinity capture is covered in the MtoZ Biolabs Phosphorylation Site Identification Service when the study focuses on phosphate and the next analytical goal is a localized site, not a predicted one.
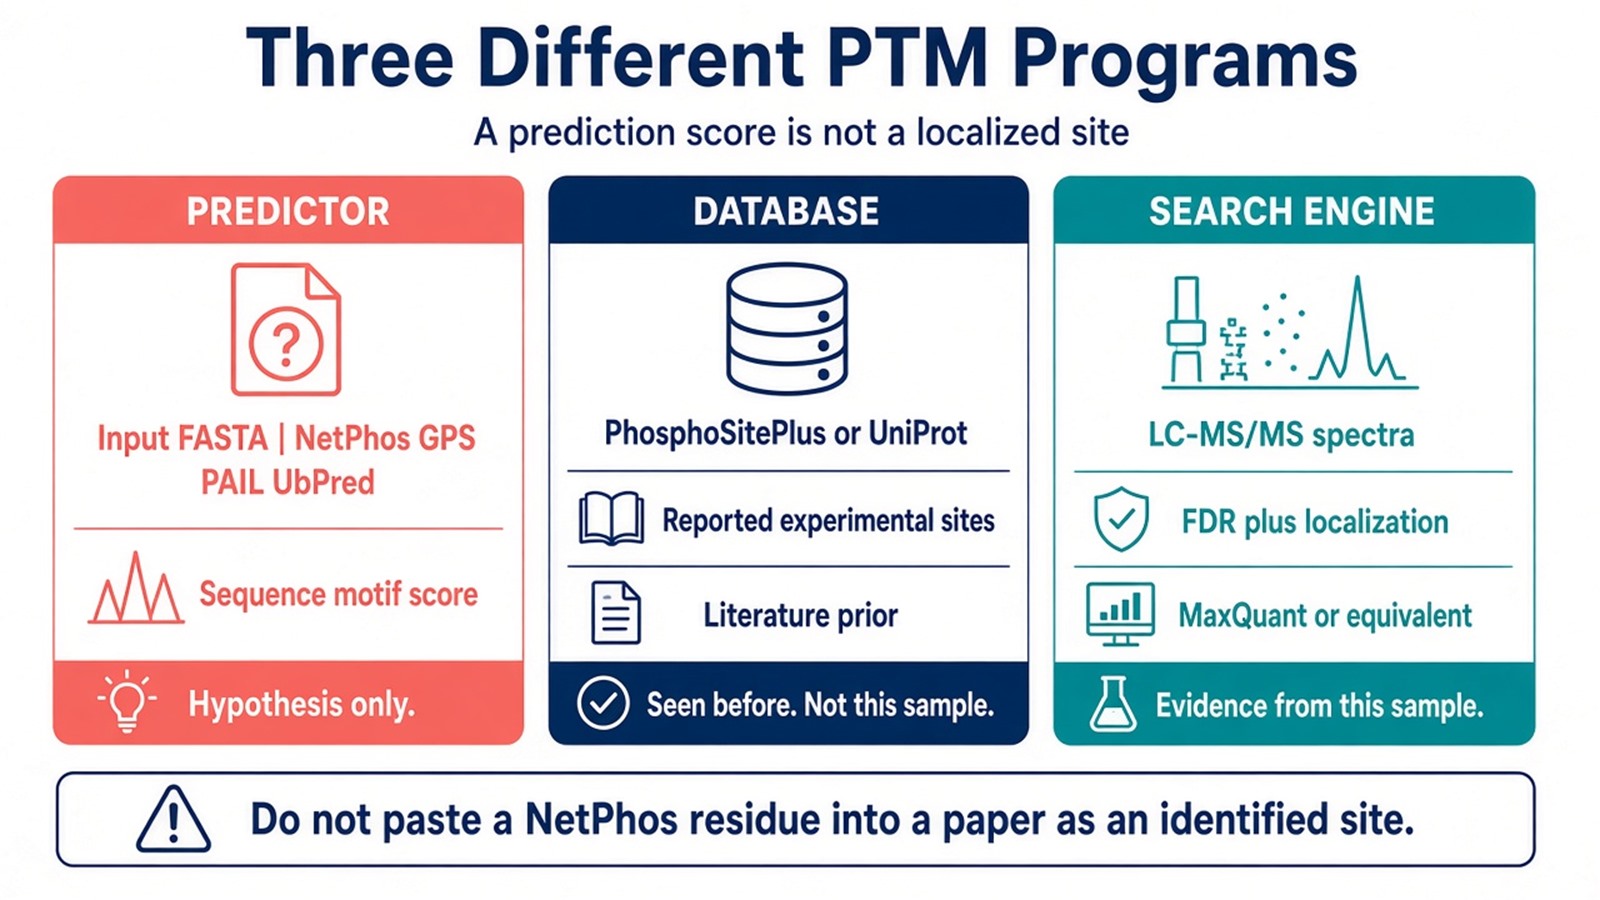
Figure 1. Predictors score a FASTA; databases list reported sites; search engines localize mass shifts on spectra from this sample.
How to Use a Prediction List in an Experimental Design
1. As a candidate panel
The legitimate use of prediction software is to shorten the residue set that will be measured or mutated. Ranked serines, threonines, tyrosines, or lysines can define peptides for targeted PRM or MRM, choose which protein to immunoprecipitate, or decide which alleles to make after a localized site is in hand. Keep the list class-specific. A phosphorylation predictor does not generate an acetylation panel. Capture chemistry for LC-MS/MS remains class-specific: titanium dioxide (TiO2) or immobilized metal affinity chromatography (IMAC) for phosphopeptides, antibody enrichment for acetyl-lysine or ubiquitin remnants.
When the protein is already named and the predictor only supplied a panel, residue-level chemistry on that target is addressed by the MtoZ Biolabs Targeted Post-Translational Modification (PTM) Detection Service.
2. Interpreting and prioritizing prediction scores
Prediction scores are best reported as candidate-site evidence rather than experimental identifications. In follow-up LC-MS/MS experiments, the search space should match the modification class and sample preparation; peptide identification and site-localization confidence must be assessed from the measured spectra. Choose a prediction tool according to the required output, such as kinase-specific predictions or general residue-level phosphorylation scores. These tools use different models and should be selected based on their scientific purpose rather than interface design.
Update frequency matters only insofar as training sets change. Check whether the predictor supports the relevant species and protein isoform. Combining results from different models may help prioritize candidates, while experimental site identification depends on the measured peptide spectra.
Class-enriched mapping used to test a prediction panel across many proteins is described in the Post-translational Modifications (PTMs) Service when the modification class is named and the protein set is still broad.
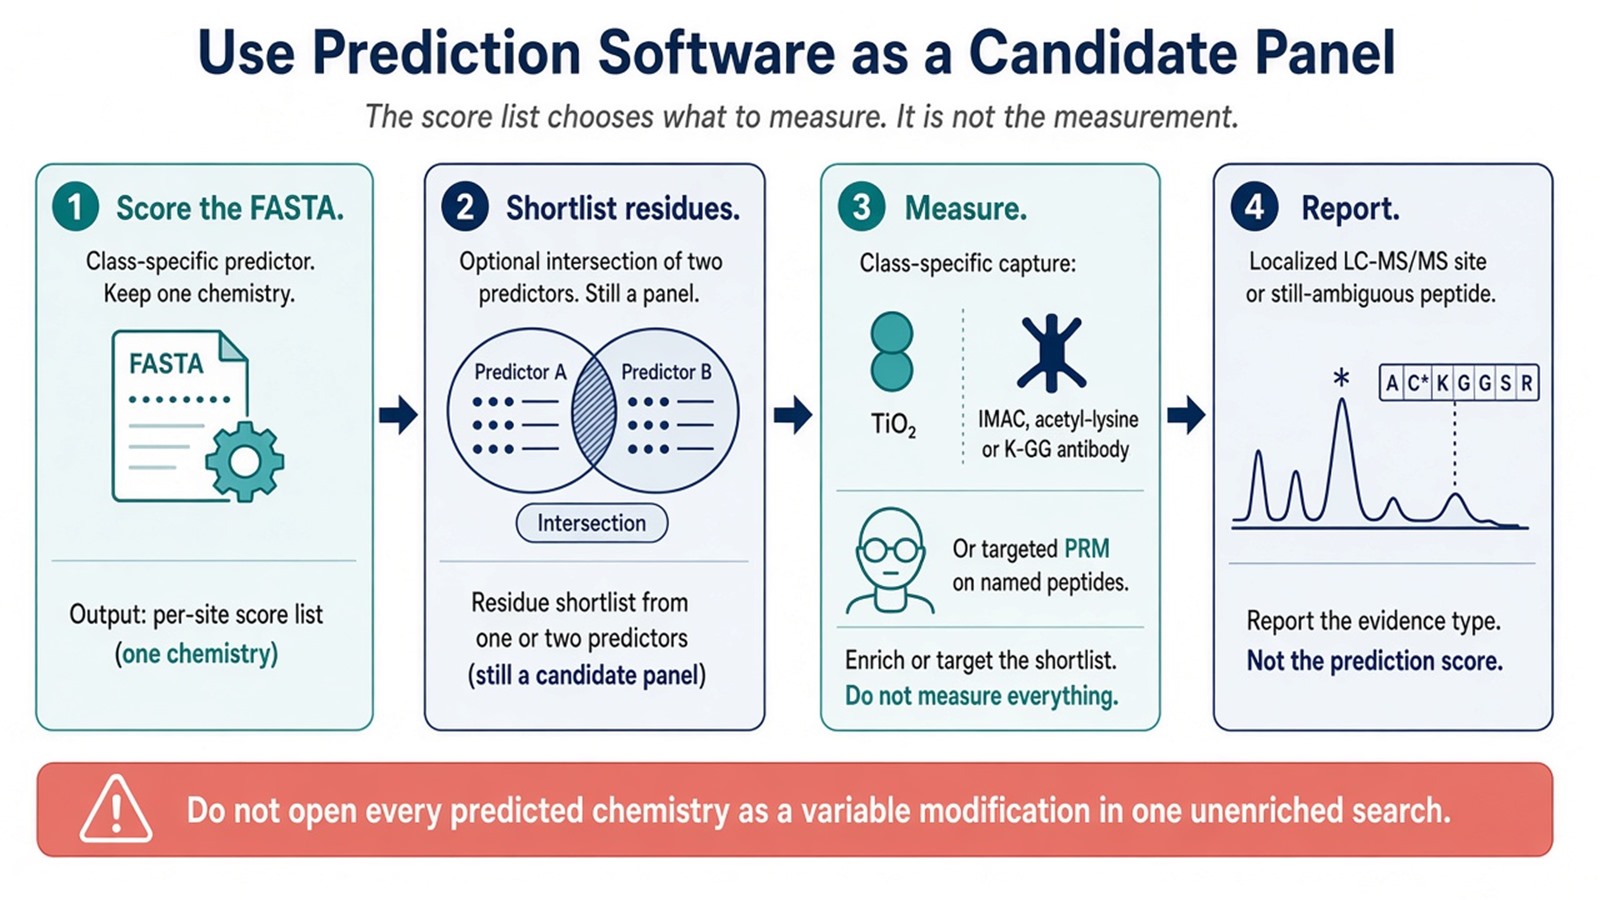
Figure 2. A scored residue list can choose peptides or alleles; identification still requires class-specific capture and fragment-supported localization.
Factors That Decide Whether Software Output Can Be Used
Scientific sentence |
Tool that can support it |
Do not conclude |
|---|---|---|
This residue looks like a known motif |
Sequence predictor (e.g., NetPhos, GPS, PAIL, UbPred) |
The site is occupied in the sample |
This residue has been reported before |
PhosphoSitePlus, UniProt, or a similar record |
It is present in this treatment |
A modified peptide was accepted and localized |
LC-MS/MS search with a localization rule |
The predictor was therefore correct as a method |
A kinase class is hypothesized |
Kinase-specific predictor |
Enzyme activity or substrate proof |
Which tool is easiest to click |
Usability, not a scientific factor |
Higher biological accuracy |
Species and isoform still matter. A model trained on mammalian phosphosites can over-call residues in a distant organism or on a splice form that was not in the training set. Trypsin detectability is independent of the prediction score: a high-scoring lysine that becomes a missed cleavage after acetylation may never appear as a tryptic peptide. Input to the predictor should be the sequence that will be searched, including known variants, not a canonical isoform chosen for convenience.
Experimental Design When a Predictor Is Run First
Before submitting a FASTA sequence, define the modification class and the planned experimental test of the candidate list. The first names the class the predictor is allowed to propose. The second names the experiment that will test the shortlist: class-enriched LC-MS/MS on a lysate, targeted detection on a purified protein, or mutagenesis after a localized site exists. If the second sentence is missing, the software run has no experimental use.
Avoid combining three predictors as a substitute for enrichment. Do not enlarge the variable-mod list to every chemistry a multi-PTM predictor can emit. Phosphorylation and acetylation still need separate capture if both shortlists will be tested. Biological replicates belong in any comparison that will be read as a change at a predicted-then-measured site. The predictor cannot supply those replicates.
When the protein is unmapped and abundant enough, a class-enriched discovery map can be run without a prediction step. The software is optional. It becomes useful when the protein is named, the sample is limited, or the next assay is a closed peptide list. Record the predictor name, version, and score threshold with the candidate panel so that the panel is not later rewritten as a result.
Interpreting Prediction-Software Tables
A score is evidence that a residue resembles the model the software was trained on. Calling that row a protein modification, a functional change, or a condition-dependent site restates a software category and overstates the output. Absence of a prediction is not proof of an unmodified residue. Training-set bias, isoform mismatch, and conservative thresholds hide sites that LC-MS/MS can still find.
Accuracy, usability, and update frequency are product attributes. They are not substitutes for peptide FDR, localization scoring, or occupancy denominators. Two predictors that agree have reduced the panel. They have not determined the site. Clinical diagnostic cutoffs sit outside ordinary research use of prediction software unless a separately validated assay framework is in place.
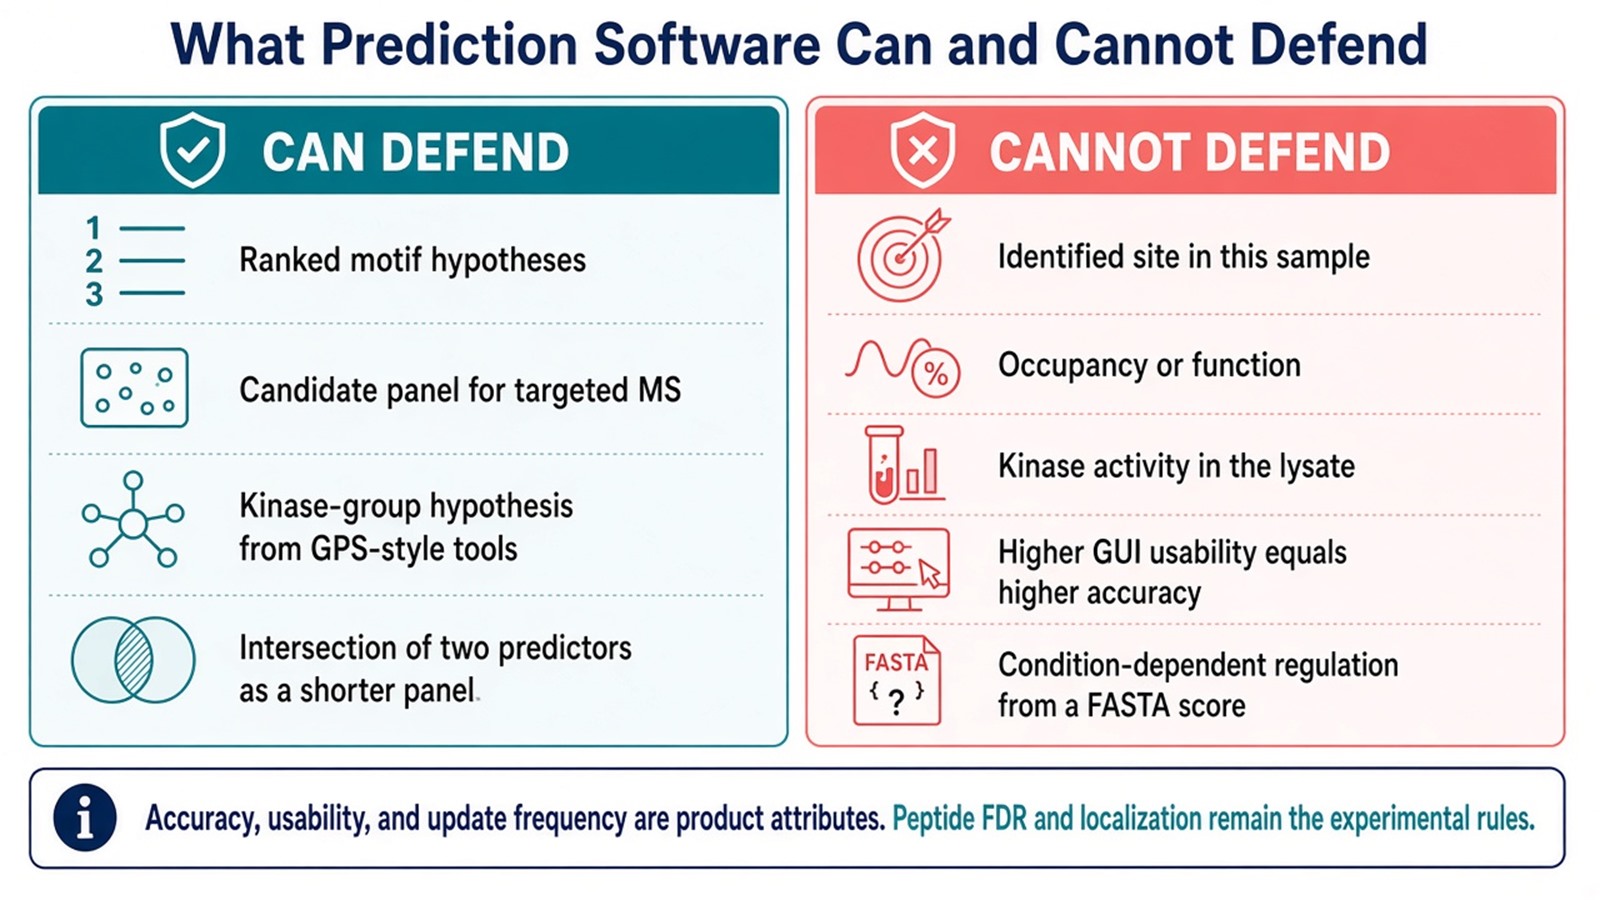
Figure 3. Candidate panels can be defended; identified sites, occupancy, function, and enzyme activity cannot be read from a prediction table.
Frequently Asked Questions
1. Can NetPhos or GPS replace LC-MS/MS for phosphorylation sites?
No. Predictors rank sequence hypotheses. Localization of a mass shift in the sample still needs class-specific LC-MS/MS or an equivalently specific experimental assay.
2. Is PhosphoSitePlus prediction software?
No. It is primarily a repository of reported sites. It can inform a panel the same way a predictor can, and it still does not identify the modification in this experiment.
3. Does a higher advertised accuracy mean the site is present?
No. Published accuracy is estimated on a benchmark set. Occupancy and detectability in this matrix are not part of that score.
4. Should I search every chemistry a multi-PTM predictor suggests?
No. Keep the variable-mod list matched to the capture that will be performed. Extra masses increase chimeric assignments.
5. When is prediction software unnecessary?
When the class is already named and the sample can support a class-enriched discovery or targeted map. The FASTA does not have to be scored first.
MtoZ Biolabs can provide experimental testing of prediction-software shortlists from class-specific enrichment through LC-MS/MS site localization, including guidance on whether a purified protein or a proteome-wide class map is the better next step when project sequences and samples are available.
If further evaluation of a candidate panel, modification class, or how predictor output should sit next to fragment-supported sites is needed, project details can be submitted for a feasibility review.
References
- N. Blom, S. Gammeltoft, S. Brunak (1999). Sequence and structure-based prediction of eukaryotic protein phosphorylation sites. J. Mol. Biol., 294, 1351-1362. https://doi.org/10.1006/jmbi.1999.3310
- Y. Xue, J. Ren, X. Gao, C. Jin, L. Wen, X. Yao (2008). GPS 2.0, a tool to predict kinase-specific phosphorylation sites in hierarchy. Mol. Cell. Proteomics, 7, 1598-1608. https://doi.org/10.1074/mcp.M700574-MCP200
- P.V. Hornbeck, B. Zhang, B. Murray, J.M. Kornhauser, V. Latham, E. Skrzypek (2015). PhosphoSitePlus, 2014: mutations, PTMs and recalibrations. Nucleic Acids Res., 43, D512-D520. https://doi.org/10.1093/nar/gku1267
- J. Cox, M. Mann (2008). MaxQuant enables high peptide identification rates, individualized p.p.b.-range mass accuracies and proteome-wide protein quantification. Nat. Biotechnol., 26, 1367-1372. https://doi.org/10.1038/nbt.1511
- J.V. Olsen, M. Mann (2013). Status of large-scale analysis of post-translational modifications by mass spectrometry. Mol. Cell. Proteomics, 12, 3444-3452. https://doi.org/10.1074/mcp.O113.034181
- S.A. Beausoleil, J. Villen, S.A. Gerber, J. Rush, S.P. Gygi (2006). A probability-based approach for high-throughput protein phosphorylation analysis and site localization. Nat. Biotechnol., 24, 1285-1292. https://doi.org/10.1038/nbt1240